Hacker News, September 21
 Hacker News
Monday, September 21, 2026
Xiaomi open-sourced its strongest model and the training run that made it — Hacker News, September 21
Xiaomi has open sourced its strongest model yet, and published the six day training run that produced it. That was the top of the Hacker News front page on Monday, September twenty first, two thousand twenty six.
Two open models, old prices
Hacker News
Monday, September 21, 2026
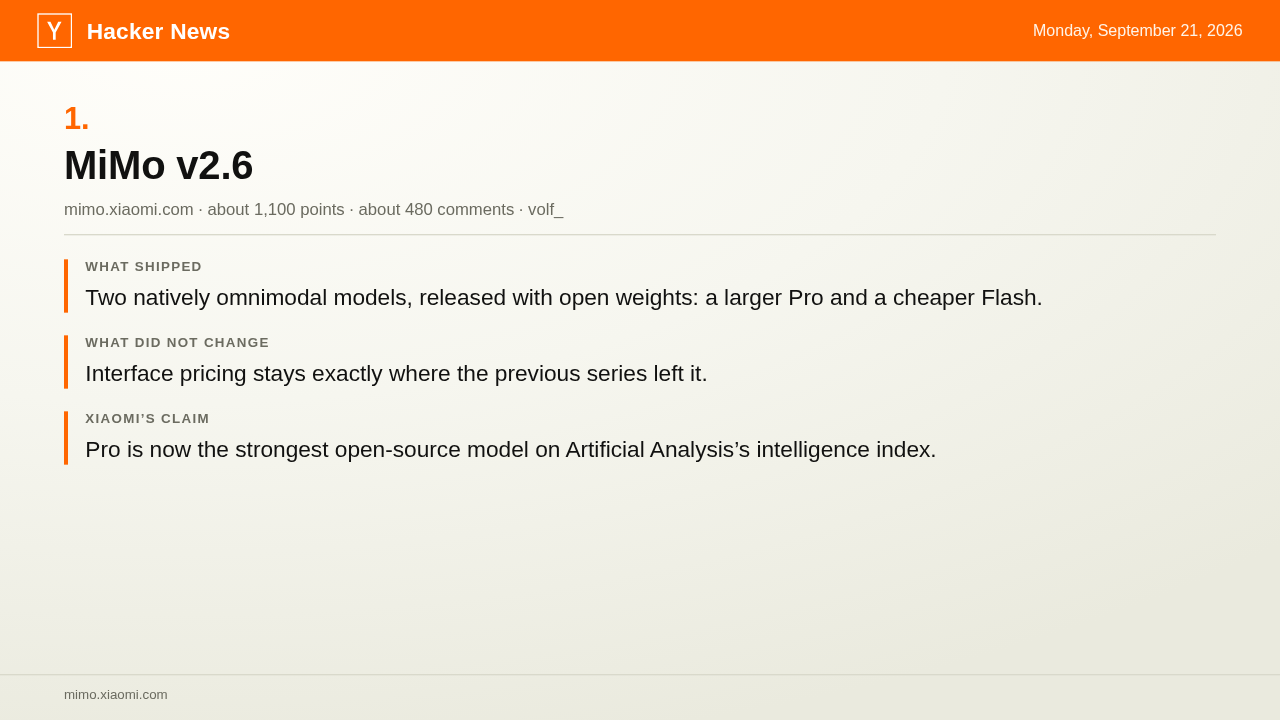
MiMo v2.6
Xiaomi released two open weight models, a larger Pro and a cheaper Flash, both handling text, images and audio natively. Pricing did not move. Their claim: Pro is the strongest open source model on the Artificial Analysis index.
Six days of reinforcement learning
Hacker News
Monday, September 21, 2026
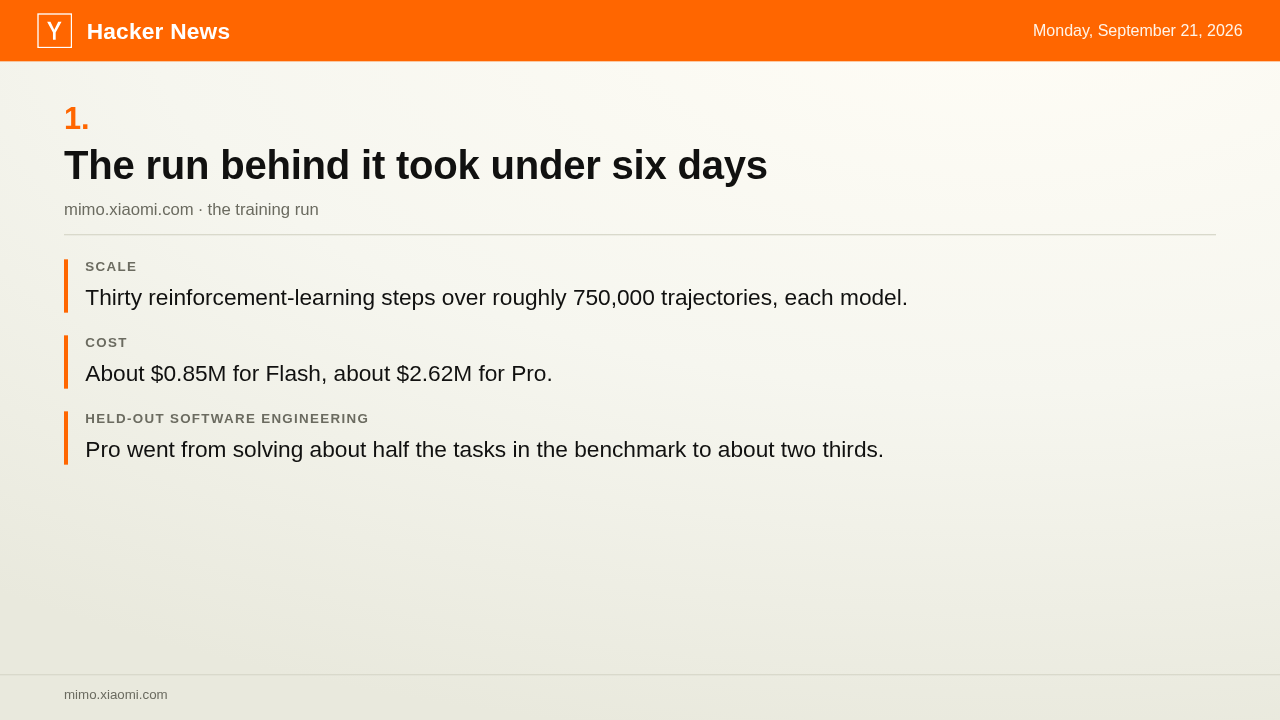
The run behind it took under six days
Each model took thirty reinforcement learning steps over roughly seven hundred and fifty thousand trajectories. About two point six million dollars of compute for Pro. On a held out software engineering benchmark it went from solving about half the tasks to two thirds.
What ships alongside the weights
Hacker News
Monday, September 21, 2026
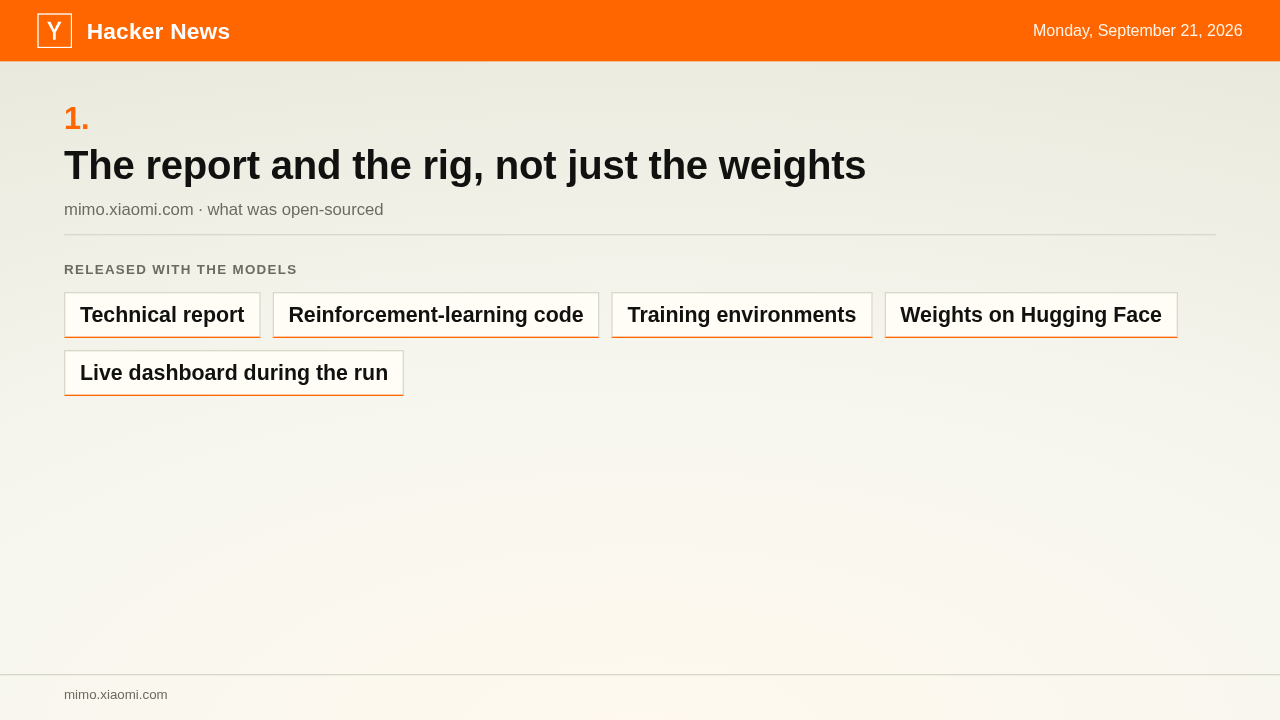
The report and the rig, not just the weights
The weights came with the technical report, the reinforcement learning code and the training environments, so the result can be reproduced and checked rather than taken on trust.
Transparency over scores
Hacker News
Monday, September 21, 2026
In the thread
“The realtime dashboard they shared during training was an incredible learning and teaching tool for me.”
Commenter rao-v picks out the openness rather than the scores. The dashboard ran while the training did, and the report covers the benchmarks they came out badly on too.
Whatever you look at shapes you
Hacker News
Monday, September 21, 2026
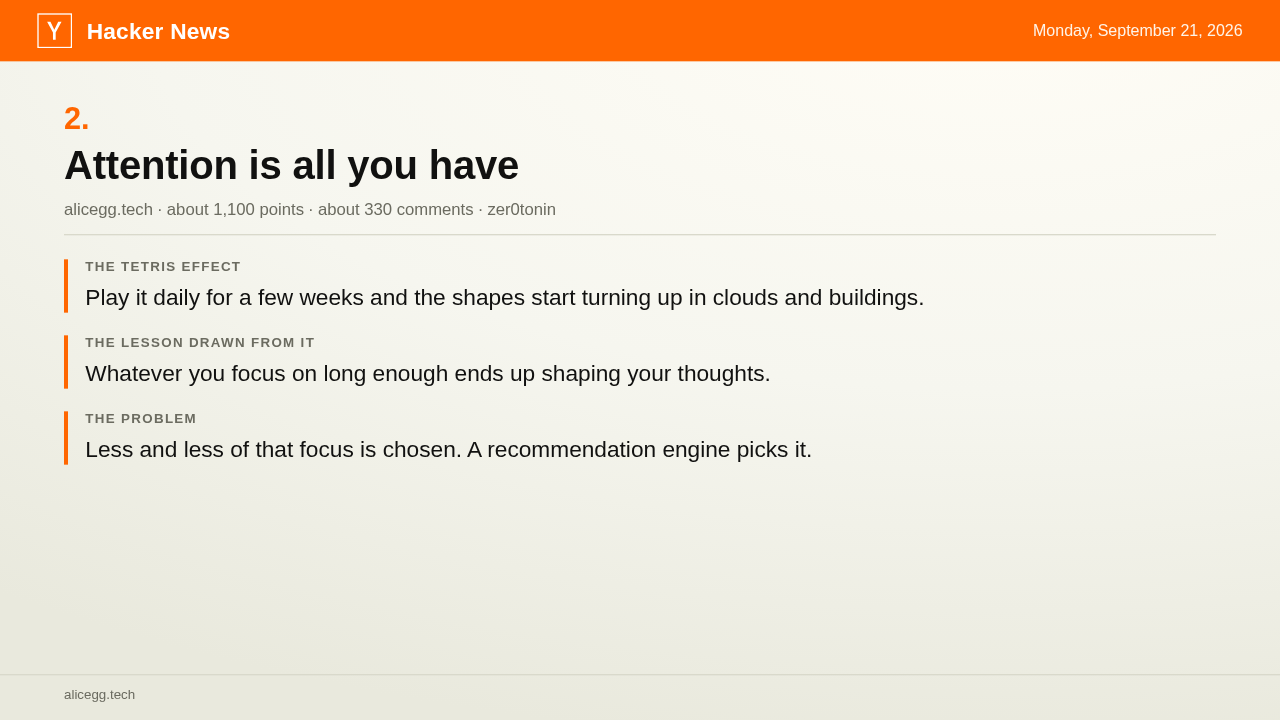
Attention is all you have
An essay that opens with the Tetris effect: play it daily for a few weeks and the shapes start appearing in clouds and buildings. Whatever you focus on shapes how you think. And a recommendation engine picks that focus for you.
When the web was better
Hacker News
Monday, September 21, 2026
In the thread
“Peak internet was the brief period of time when it was available but we weren’t permanently connected.”
Commenter tripleee offers a blunter version, and this is their view rather than anything the essay argues. Peak internet, they reckon, was the short window when it was there but you were not permanently attached to it.
Bored with the mechanics
Hacker News
Monday, September 21, 2026
What Sun got wrong
Bryan Cantrill distills it to one line: Sun had become bored with the mechanics of running a business. A startup on OpenSolaris wanted to buy Sun hardware and could not get Sun to answer the phone. Dell answered an overnight web form by morning.
The buying experience
Hacker News
Monday, September 21, 2026
In the thread
“The server rails and power cords for a new Alpha server were going to cost more than a shipped, delivered Dell server that I could get the next day.”
Commenter coreyh14444 remembers it from the customer's side, which is the same complaint the post makes. Buying from the old workstation vendors meant live sales meetings and endless quote revisions.
A live model in a browser tab
Hacker News
Monday, September 21, 2026
Transformers Explained Visually
An explainer out of Georgia Tech runs a small GPT-2 inside your browser tab. Type a prompt and watch the tokens, attention weights and next token probabilities move. An old model, chosen because it has the same parts as the current ones.
What it made click
Hacker News
Monday, September 21, 2026
In the thread
“I always struggled to see how transformers get away with compressing all context in a flat vector between attention and the MLP.”
Commenter mhl47 says what it unstuck, and the page bears it out. Attention and the feed forward layer alternate through twelve stacked blocks, so other tokens mix back in at every one.
Small models for boring decisions
Hacker News
Monday, September 21, 2026
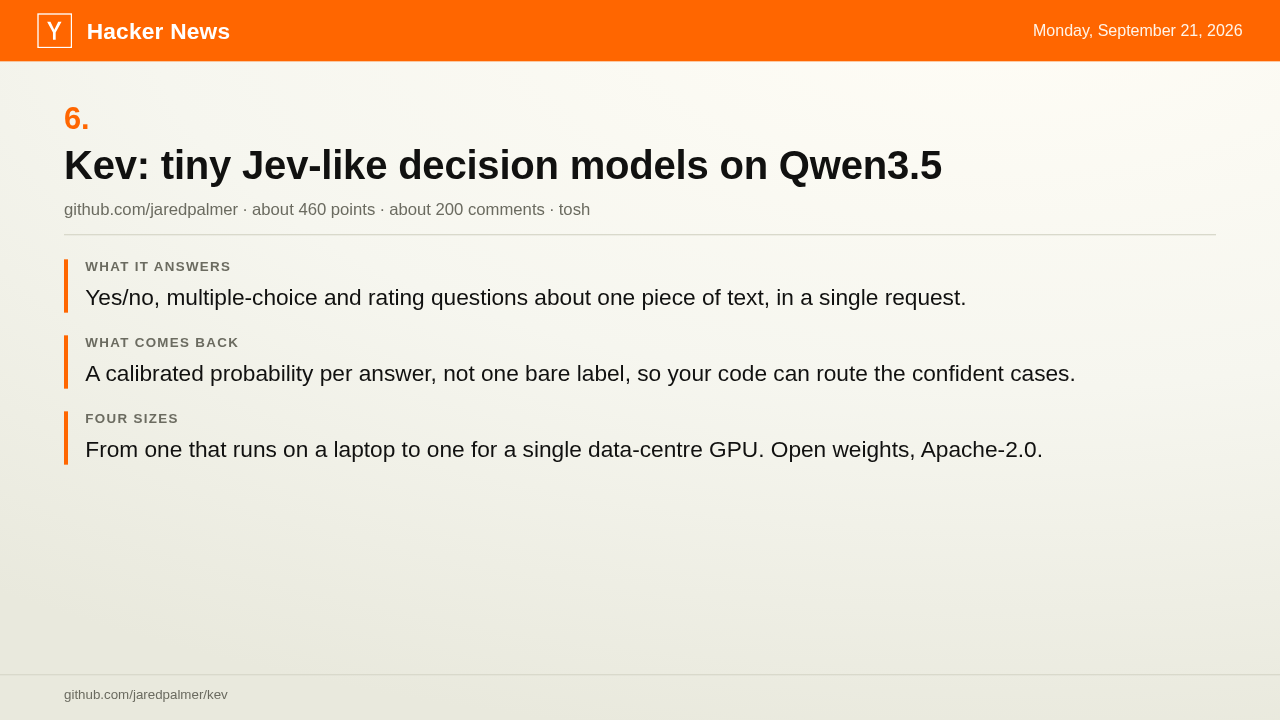
Kev: tiny Jev-like decision models on Qwen3.5
An open weights family for the dull decisions: which team owns this ticket, does it need a human, how annoyed is the customer. Each answer is a probability, so your code routes the confident ones and sends the rest to a person. The smallest runs on a laptop.
A smaller alternative
Hacker News
Monday, September 21, 2026
In the thread
“If you only need classification, and you can provide some training data, you can ask Codex or Claude to build an embeddings plus logistic classifier model for you.”
Commenter nico pushes a smaller option, from their own experience rather than anything the project measured. For plain classification, a hundred labelled examples and a classifier over embeddings trains on a laptop in minutes.
Sources
Hacker News
Monday, September 21, 2026
Every story on these slides
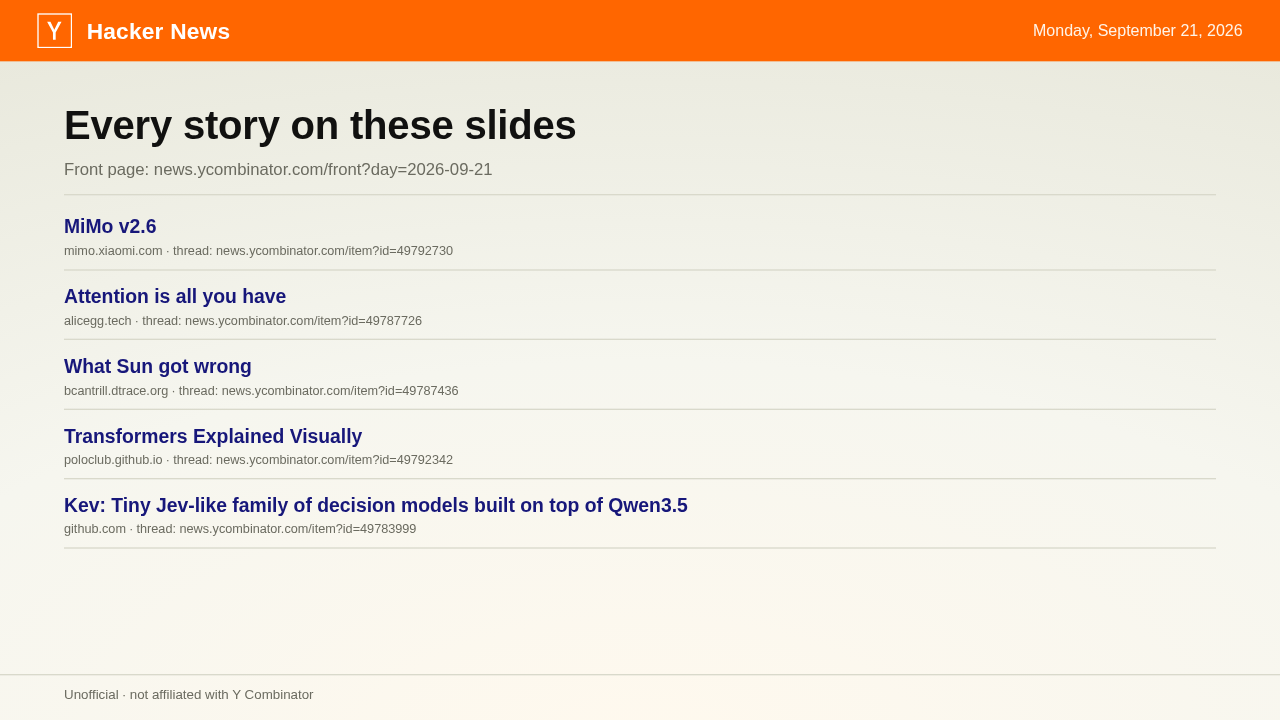
- MiMo v2.6mimo.xiaomi.com · thread: news.ycombinator.com/item?id=49792730
- Attention is all you havealicegg.tech · thread: news.ycombinator.com/item?id=49787726
- What Sun got wrongbcantrill.dtrace.org · thread: news.ycombinator.com/item?id=49787436
- Transformers Explained Visuallypoloclub.github.io · thread: news.ycombinator.com/item?id=49792342
- Kev: Tiny Jev-like family of decision models built on top of Qwen3.5github.com · thread: news.ycombinator.com/item?id=49783999
Xiaomi's MiMo release, the essay on attention, Bryan Cantrill on Sun, the transformer explainer, and Kev. Each one is linked here beside its thread, with the front page they all came from.