Pi replaces Claude Code, Goldman cuts its traders off, and DeepSeek fits in 64 GB
15 hours ago
Caleb retires Claude Code for Pi, an open-source coding harness, over constant prompt changes. Also from Sunday's Hacker News front page: Goldman Sachs limits Claude Code to its engineers, GitHub's new pull request Overview page, and Llama-modchip running the 284B DeepSeek-V4-Flash in 64 GB of RAM with no GPU. Goodbye Claude, hello Pi, by Caleb https://caleb.software/posts/claude-to-pi.html Discussion: https://news.ycombinator.com/item?id=50410107 siraben on a Pi extension for long bash commands: https://news.ycombinator.com/item?id=50410725 leobuskin on keeping Claude in Claude Code: https://news.ycombinator.com/item?id=50410950 Goldman Sachs is pulling Claude Code from its bankers and traders, State of AI https://www.thestateofai.com/news/goldman-sachs-claude-code-traders-bankers Discussion: https://news.ycombinator.com/item?id=50415628 lukebuehler on the lethal trifecta: https://news.ycombinator.com/item?id=50416595 New pull request overview page in public preview, GitHub Changelog https://github.blog/changelog/2026-11-05-new-pull-request-overview-page-in-public-preview/ Discussion: https://news.ycombinator.com/item?id=50408931 jmux on the page's speed: https://news.ycombinator.com/item?id=50416521 Llama-modchip: 284B DeepSeek on 64GB RAM, no GPU https://github.com/synchopate/llama-modchip Discussion: https://news.ycombinator.com/item?id=50411961 aappleby's test against plain llama.cpp: https://news.ycombinator.com/item?id=50416358 armcat on quantisation below 4 bits: https://news.ycombinator.com/item?id=50413074 The front page that day: https://news.ycombinator.com/front?day=2026-11-08
Ask about this presentation
Chapters
Show transcriptHide transcript
On Sunday's HN front page, Caleb, a developer who has used Claude Code since it came to the Pro plan, retires it as a main coding harness and moves to Pi, an open-source one. Anthropic announced that Claude Code would read AGENTS.md files a day after that decision, too late to change it. Until then, anyone using Claude Code beside other agents had been copying or symlinking CLAUDE.md into AGENTS.md in every repo.
Slide text

Pi replaces Claude Code, Goldman cuts its traders off, and DeepSeek fits in 64 GB
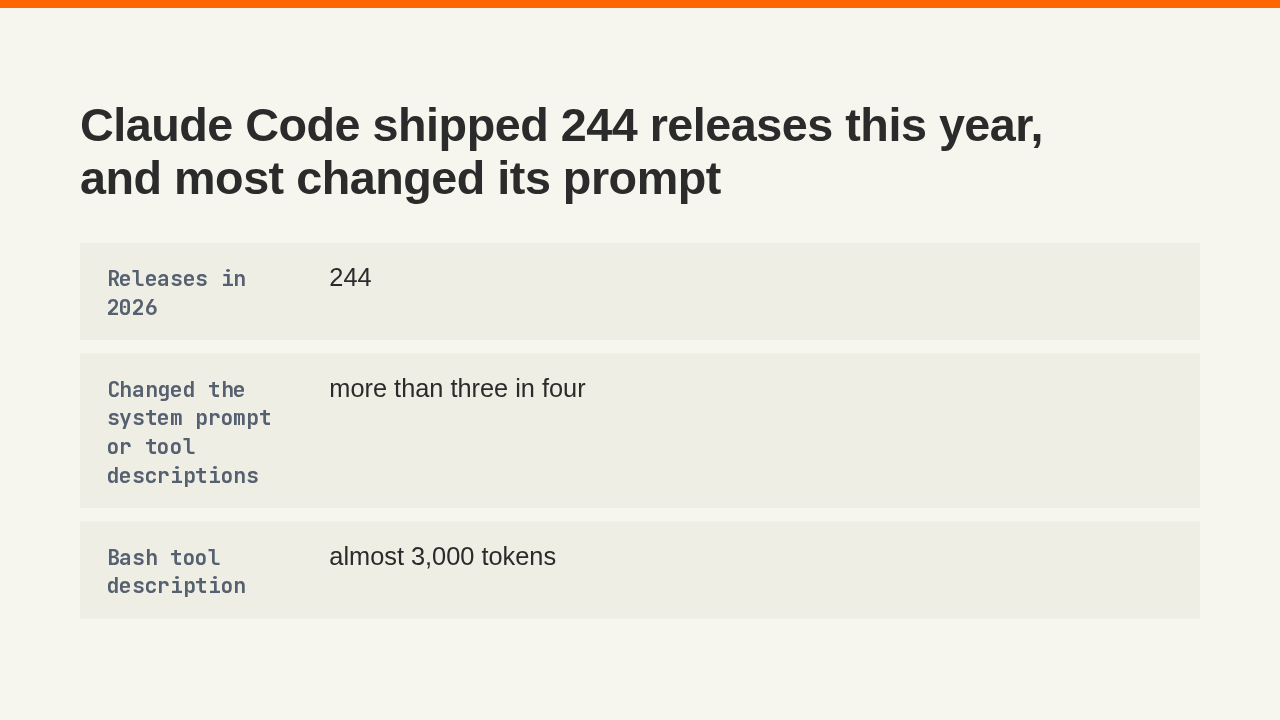
The complaint is churn. Claude Code has shipped more than 240 releases this year, and more than three in four changed the system prompt or the tool descriptions, which shifts how the model behaves in a repo with its own conventions. The Bash tool's description alone runs to almost 3,000 tokens, mostly about git and pull requests. Pi's own prompt is far smaller. A Claude Code bug that drops IDE text selections in a second tab was first reported in December 2025. In Pi, Caleb fixed it with an extension written in about twenty minutes.
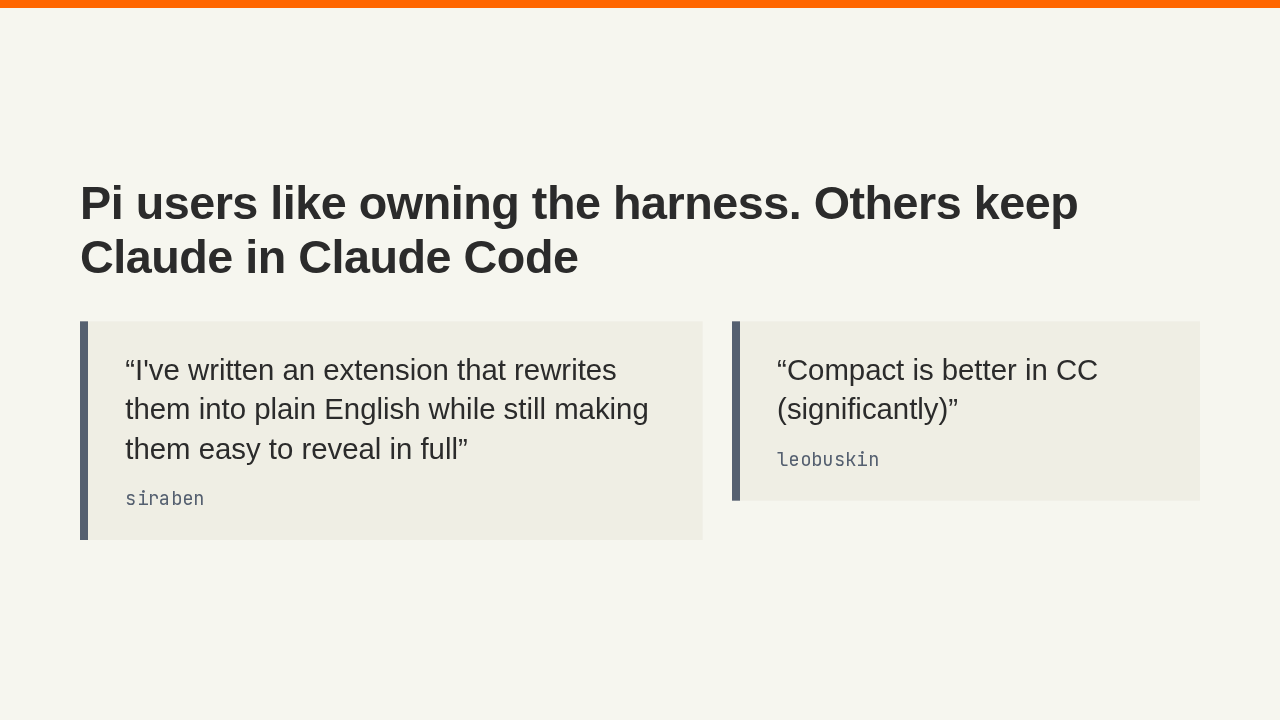
Under the post, siraben has used Pi daily for over a month, and wrote an extension that turns the long bash commands new models write into plain English, with the full command a click away. leobuskin argues the other side: Claude models do better inside Claude Code, where compaction and prompt caching are tuned for them, and running another harness on an Anthropic subscription risks a ban under its terms.
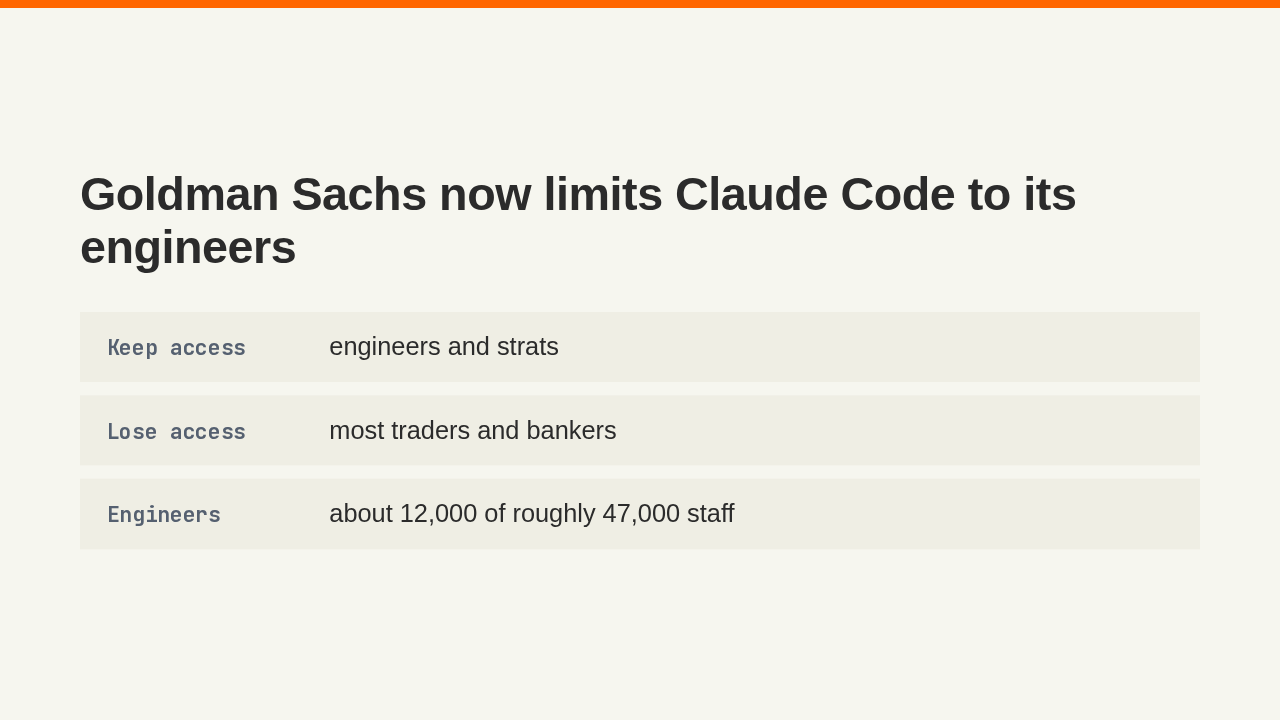
Goldman Sachs has limited Claude Code and GitHub's coding tools to its engineers, about twelve thousand of its roughly forty-seven thousand staff. Strats, who work across trading, research and engineering, keep access. Most traders and bankers lose it. They had been using the agents to watch client trading flows and model positions. In July, the bank's chief information officer was praising tools that traders built this way. Goldman is also a lead underwriter on Anthropic's IPO.
The rule targets third-party agents that write and run code on their own, with the same access as the person using them. Goldman's in-house assistant, which doesn't run code, stays open to everyone. lukebuehler calls it the lethal trifecta: private data, untrusted input, and a way to send things out, all on one workstation that also holds client and trade information.
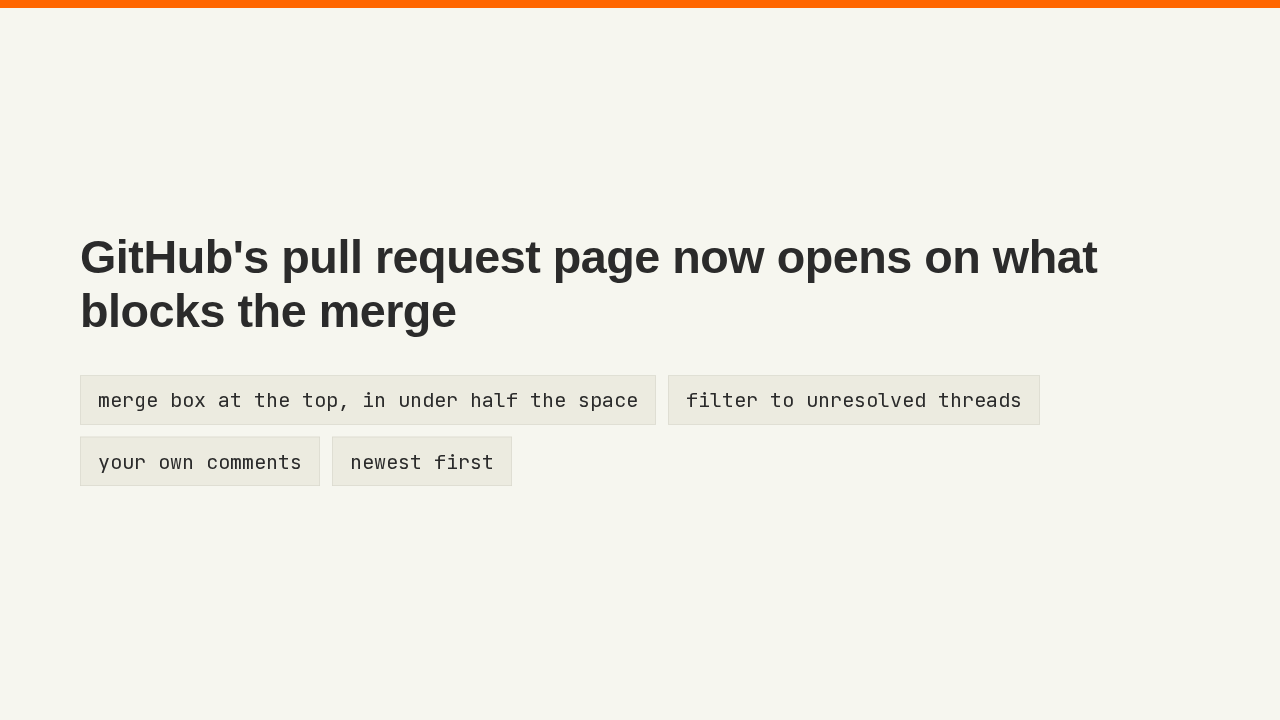
GitHub has a new pull request Overview page in public preview, and you opt in from a button in the header. The merge box moves to the top, redesigned to fit in less than half the space: checks, comments, approvals, and the next action, such as updating your branch. You can filter the conversation to unresolved threads or to your own comments, and sort it newest first. The same menu switches back to the classic page. In the comments, jmux would trade all of it for the speed the page had three years ago.
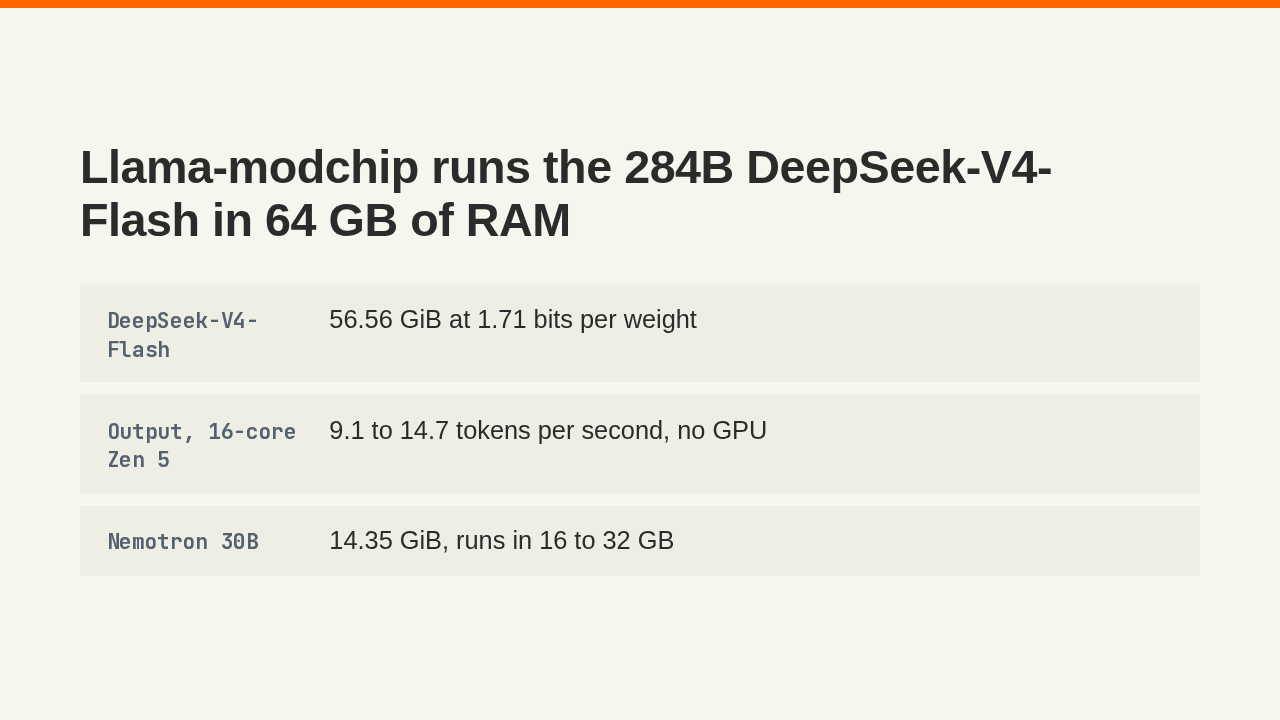
Llama-modchip is a set of patches to llama.cpp that runs DeepSeek-V4-Flash, all 284 billion parameters, on a 64 gigabyte Linux machine with no GPU. It squeezes the model under 2 bits per weight, about 57 gigabytes, so the model and a long context stay in RAM without swapping. A 16-core Zen 5 writes about 9 to 15 tokens a second. The files use a new tensor type, so stock llama.cpp, Ollama and LM Studio refuse to load them.
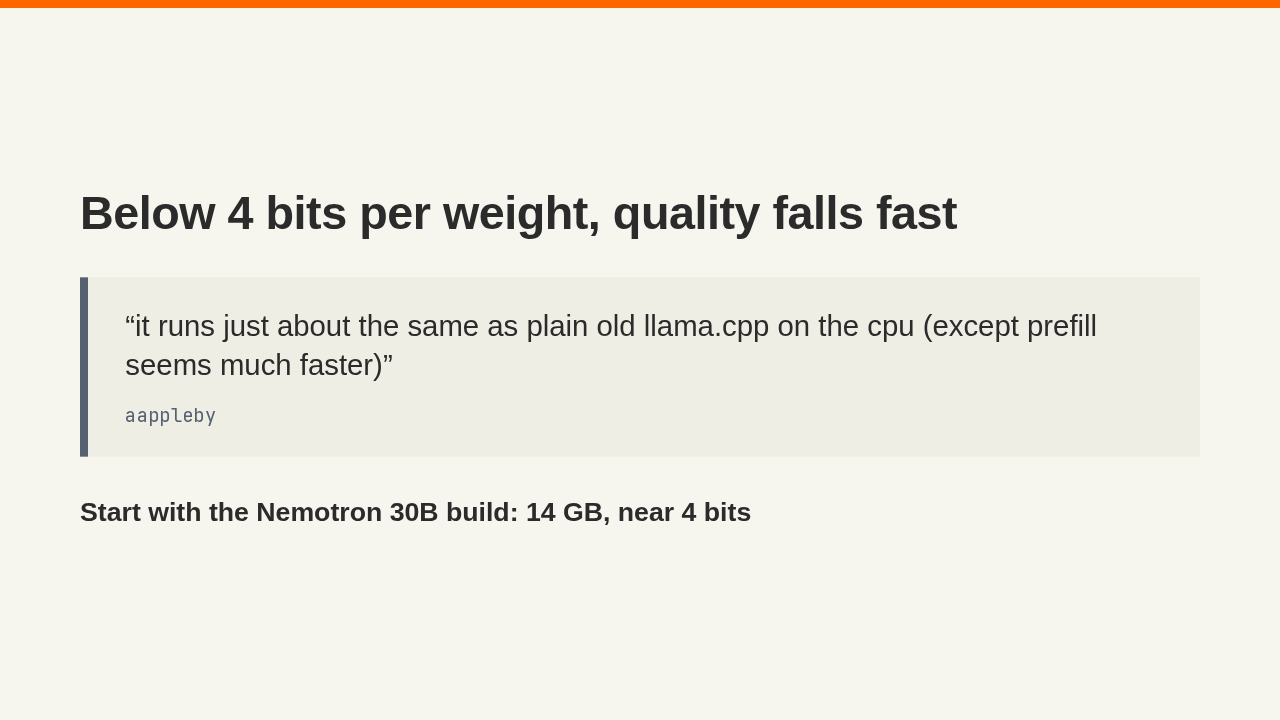
aappleby tried the Nemotron build on a 16-core Zen 4 and found it ran about the same as plain llama.cpp, apart from much faster prompt processing. armcat points to research where quality drops sharply below 4 bits per weight, and the DeepSeek build sits under 2. With a 32 gigabyte machine, I'd start with the Nemotron build. It is 14 gigabytes, close to 4 bits, and quick to test before a 57 gigabyte download.
Up next
 4:12
Libghostty 1.0 is stable, your Mac maps your family, and Discord drops Electron
@hacker-news
1 day ago
 3:49
BUI puts Blender’s UI in your app, Firenook speeds up Firebase emulators, and ASN blocks GrapheneOS
@hacker-news
2 days ago
 4:24
Alpine’s OpenSSH lets a 300-character password in, GPT-6 Astra slacks on safety research, and Discord drops Electron
@hacker-news
3 days ago
 3:59
Nvidia RTX Spark runs local AI five times slower on Linux, and a fake interview cost Binance $6.3B
@hacker-news
4 days ago
 3:15
GPT-6 Astra reads raw weights only on tiny networks, and Postman installs itself into Codex
@hacker-news
5 days ago
 3:13
Postgres 19 slips because AI finds its bugs, Astra fixes Qwen by editing its weights, and Ubuntu waits on a 9.8
@hacker-news
6 days ago
 3:49
Hono+htmx and Astro cost Claude least to build, Brazil fines a hidden prompt, and Zamzar turns 20
@hacker-news
1 week ago
 3:49
Linux’s TCP bug can root Go servers, one ChatGPT link took your account, and HackerTube
@hacker-news
1 week ago
 3:13
Anthropic files its S-1, coding agents cost up to 75% less to run, and Microsoft offers 60,000 buyouts
@hacker-news
1 week ago
 3:50
Goose outruns safe Rust with no heap, and a 2015 CNN beats GPT-6 Astra at skin cancer
@hacker-news
2 weeks ago
 4:10
Brotli needs patching in Node, Python and curl, Roc nears C, and uv check runs ty
@hacker-news
2 weeks ago
 3:59
Claude proves 123 libraries' fuzz tests can't crash, Kimi K3.1 Pro, and Docker is weird
@hacker-news
2 weeks ago