Agent-Reflex trains an 8B agent to recover when its MCP tools fail, and it gets derailed half as often
1 month ago
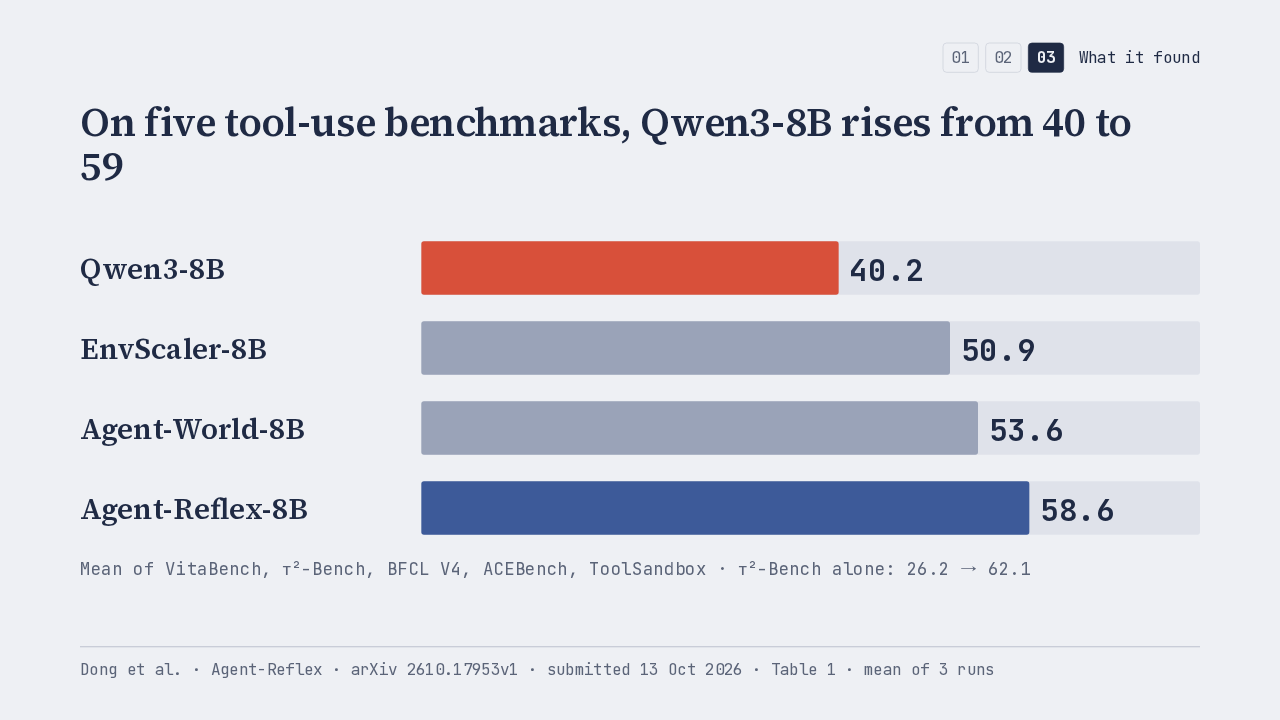
Agent-Reflex trains Qwen3-8B to notice and recover when MCP tools fail or a user corrects it. On AgentNoiseBench it is thrown off course in 28.5% of runs against 56.1% for the base model, and its mean across five tool-use benchmarks rises from 40.2 to 58.6. It still trails GPT-5.2 and Claude 4.5 Sonnet. From Renmin University of China and the National University of Singapore (arXiv 2610.17953v1, submitted 13 Oct 2026). Paper: https://arxiv.org/abs/2610.17953 Code: https://github.com/RUC-NLPIR/Agent-Reflex Model: https://huggingface.co/dongguanting/Agent-Reflex-8B Data: https://huggingface.co/datasets/dongguanting/Agent-Reflex-SFT-54K
Ask about this presentation
Chapters
Show transcriptHide transcript
Agent-Reflex teaches a small open model to notice when an MCP tool fails or a user corrects it, and to recover. It comes from Renmin University of China and the National University of Singapore.
Slide text

Agent-Reflex trains an 8B agent to recover when its MCP tools fail, and it gets derailed half as often
Guanting Dong, Xinyu Yang, Jiajie Jin and colleagues, with Zhicheng Dou · Renmin University of China, National University of Singapore
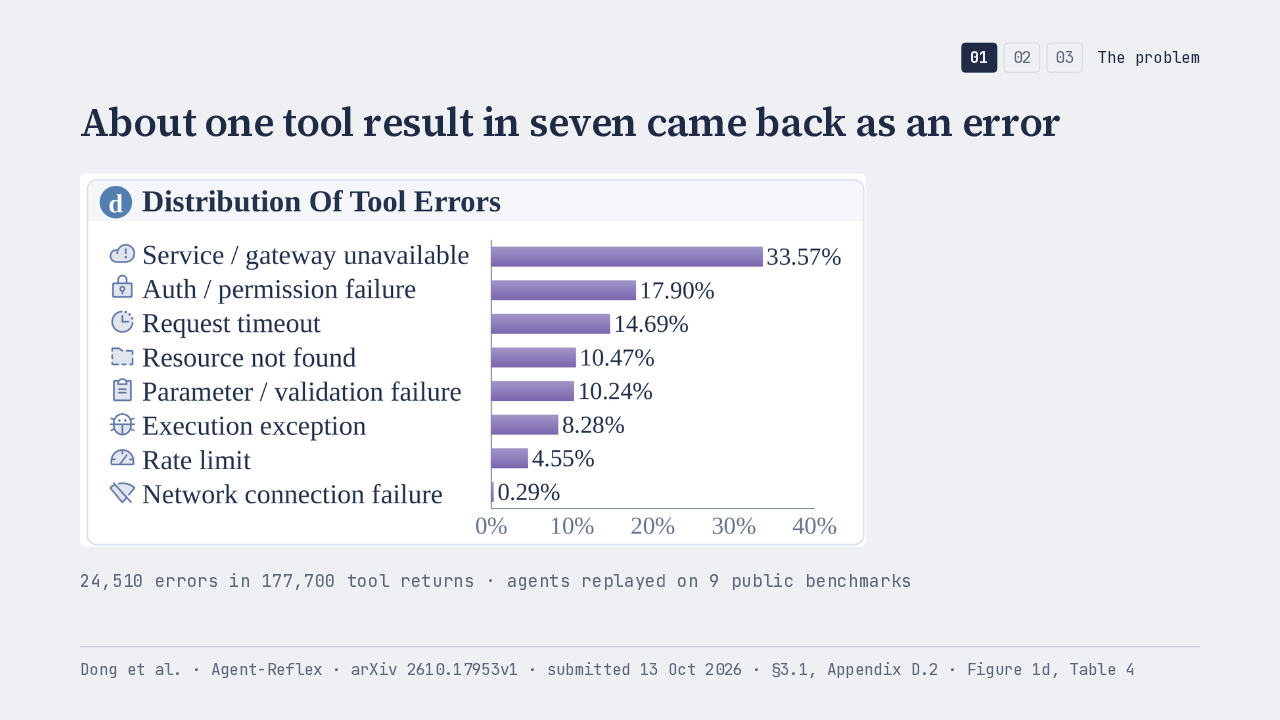
Dong et al. · Agent-Reflex · arXiv 2610.17953v1 · submitted 13 Oct 2026 · Appendix E.1Real tools fail all the time. Replaying agents on nine public benchmarks, about one tool result in seven was an error. A third were services that were down, followed by permission failures and timeouts.
Slide text
01 02 03 The problemAbout one tool result in seven came back as an error

24,510 errors in 177,700 tool returns · agents replayed on 9 public benchmarks
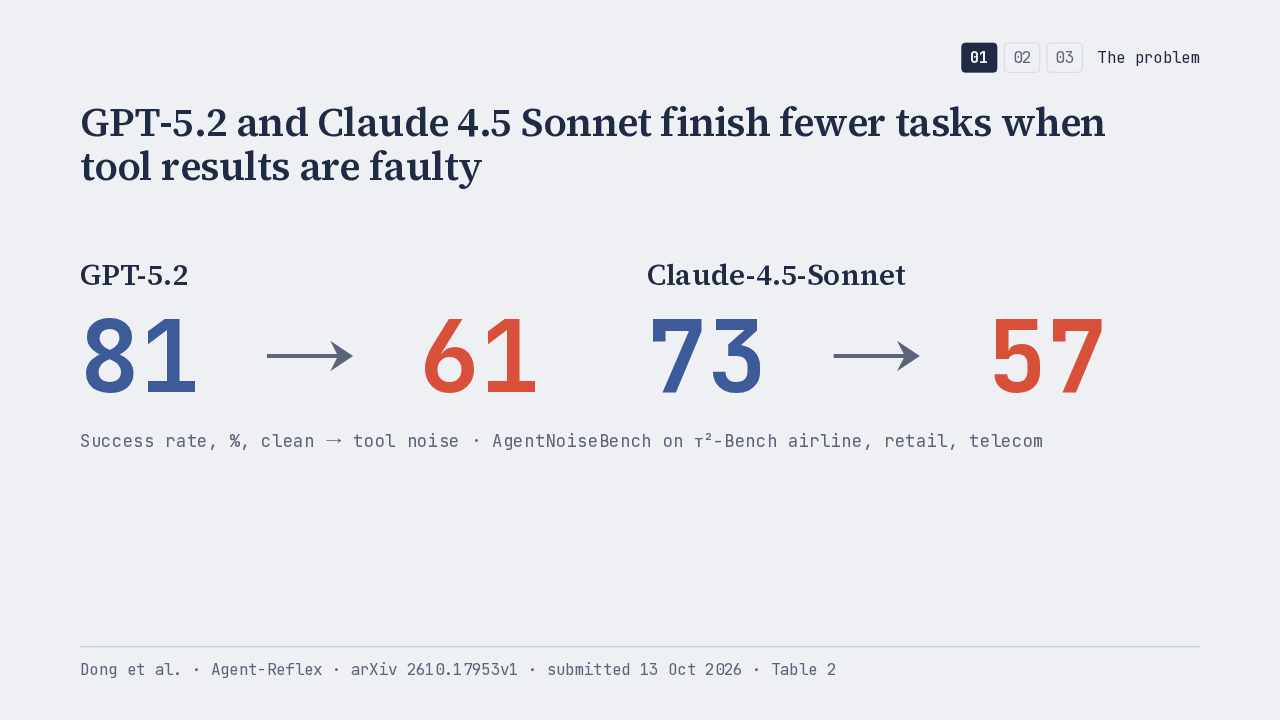
Dong et al. · Agent-Reflex · arXiv 2610.17953v1 · submitted 13 Oct 2026 · §3.1, Appendix D.2 · Figure 1d, Table 4Frontier models stumble too. On the airline, retail and telecom tasks of τ²-Bench, GPT-5.2 drops from about 80 to about 60 percent success once tool results turn faulty. Claude 4.5 Sonnet loses about 16 points.
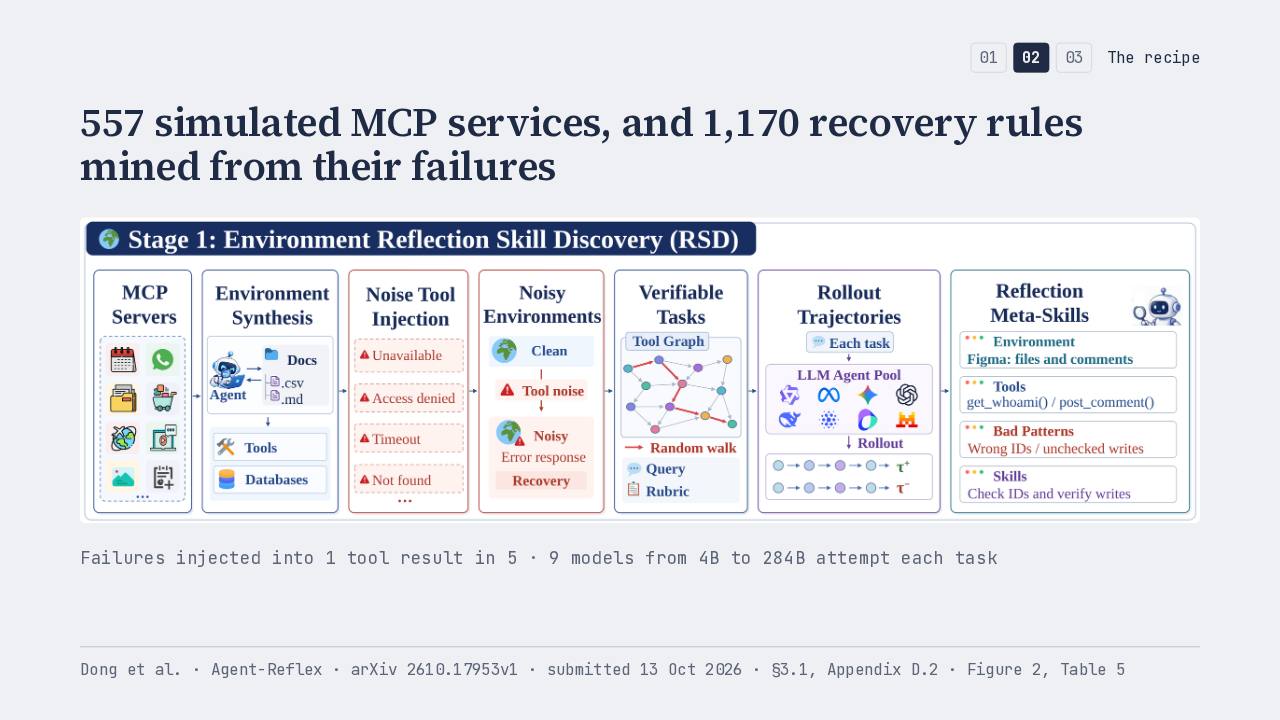
The recipe builds 557 simulated services from popular MCP servers and injects real error types into one tool result in five. Nine models attempt each task, and the difference between runs that recovered and runs that failed becomes a written rule.
Slide text
01 02 03 The recipe557 simulated MCP services, and 1,170 recovery rules mined from their failures

Failures injected into 1 tool result in 5 · 9 models from 4B to 284B attempt each task
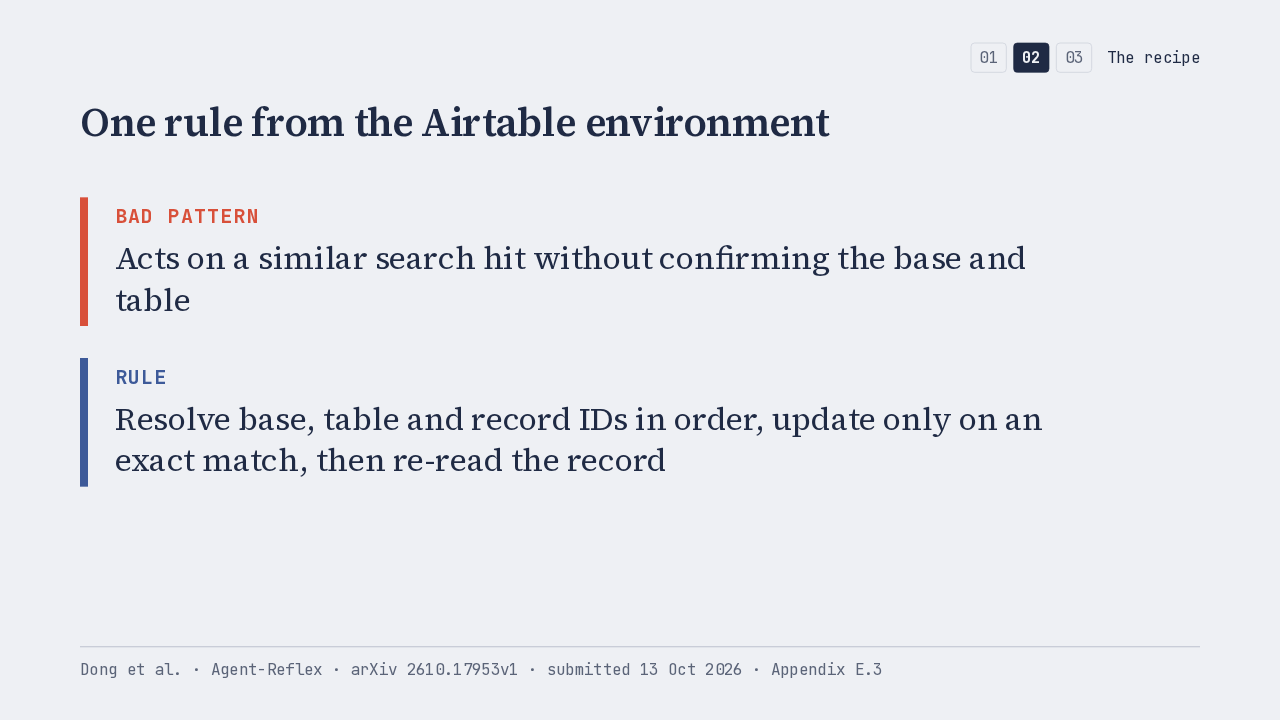
Dong et al. · Agent-Reflex · arXiv 2610.17953v1 · submitted 13 Oct 2026 · §3.1, Appendix D.2 · Figure 2, Table 5Here is one rule, for a service modeled on Airtable. Failing agents acted on a search result that only looked right. The rule says to confirm every identifier, write only on an exact match, then read the record back.
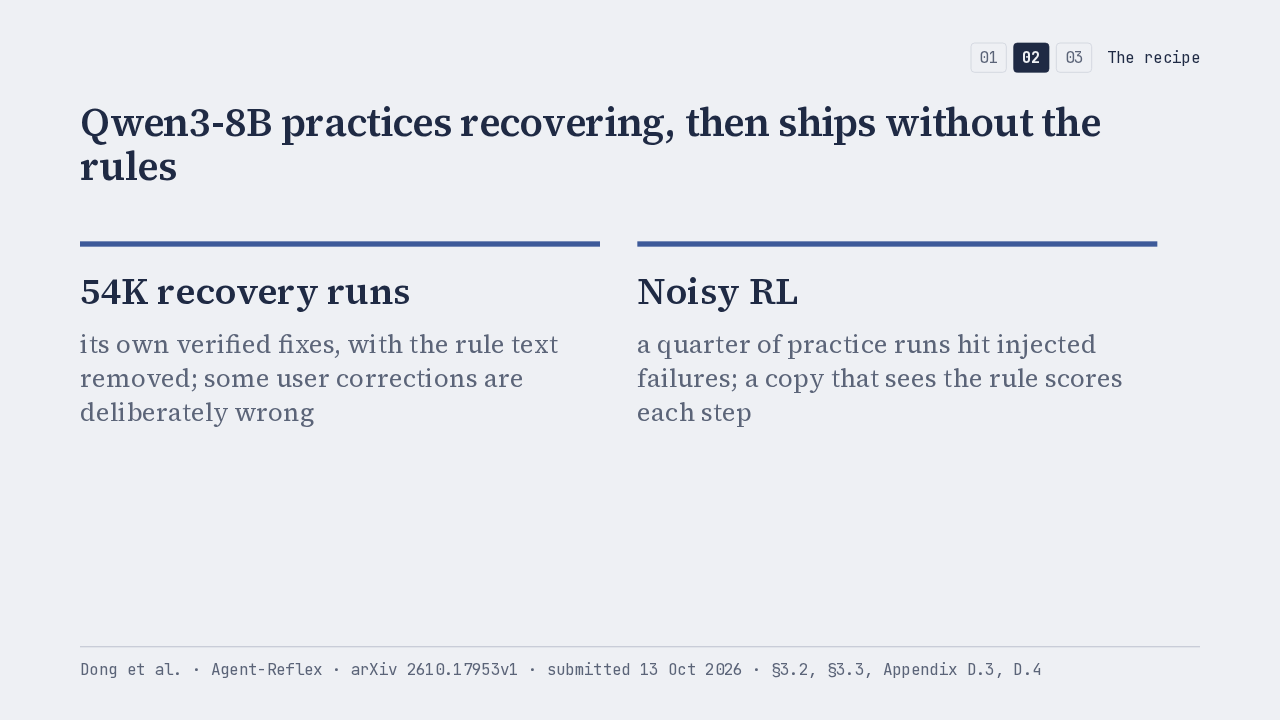
Qwen3-8B fine-tunes on about 54,000 runs where it fixed its own mistakes, with the rule text stripped out and some user corrections wrong on purpose. Reinforcement learning follows, with a quarter of runs hitting failures. The finished model carries no rule library.
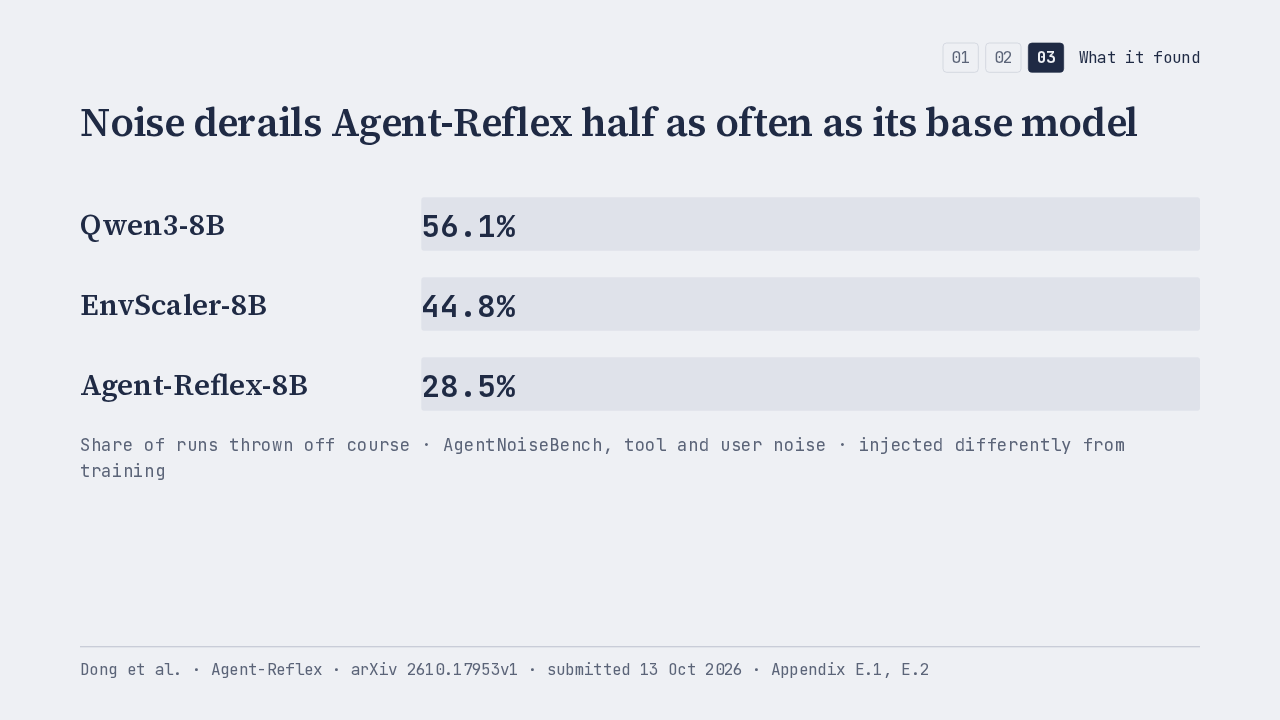
AgentNoiseBench injects its faults differently from the training setup. There, noise throws the base Qwen model off course in more than half its runs. Agent-Reflex goes off course in just over a quarter.
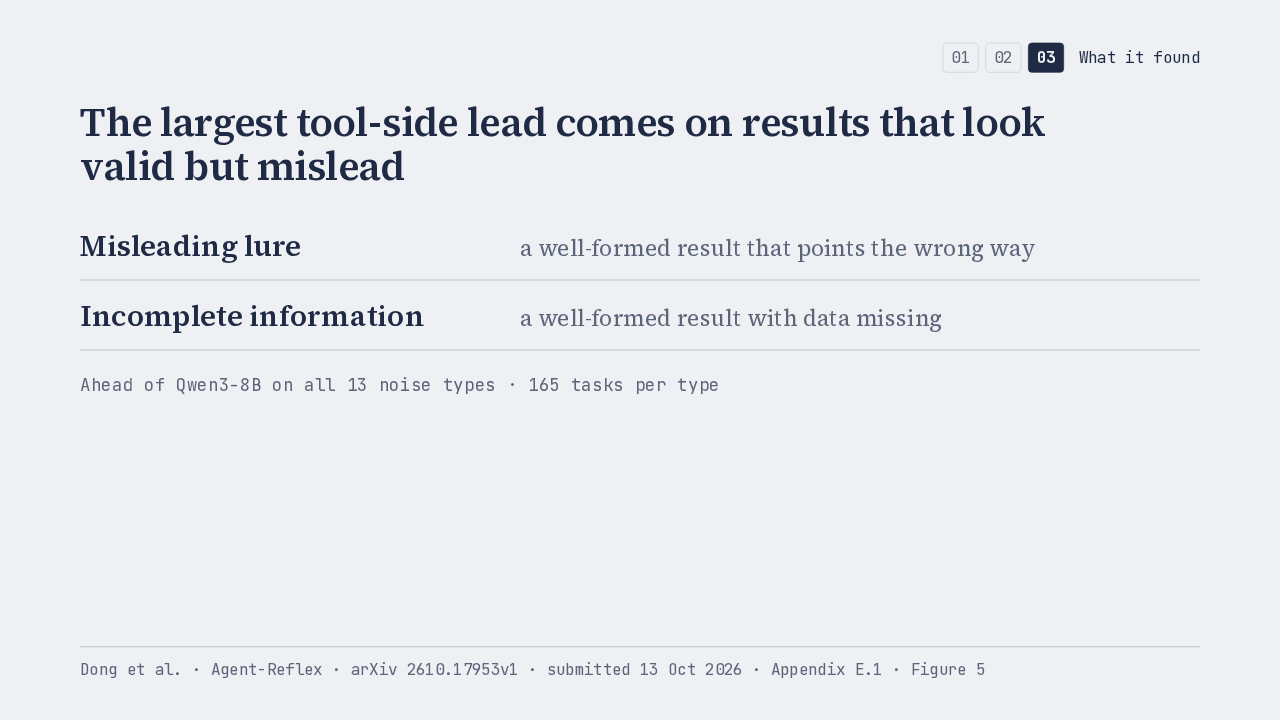
The biggest tool-side gain is on results that pass every format check but point the wrong way or leave data out. The agent only catches those by reading the content. It beats the base model on all thirteen kinds of noise.
The recipe also helps when tools behave. Averaged over five tool-use benchmarks, Qwen3-8B goes from about 40 to almost 60, ahead of the other 8B training recipes. On τ²-Bench its score more than doubles.
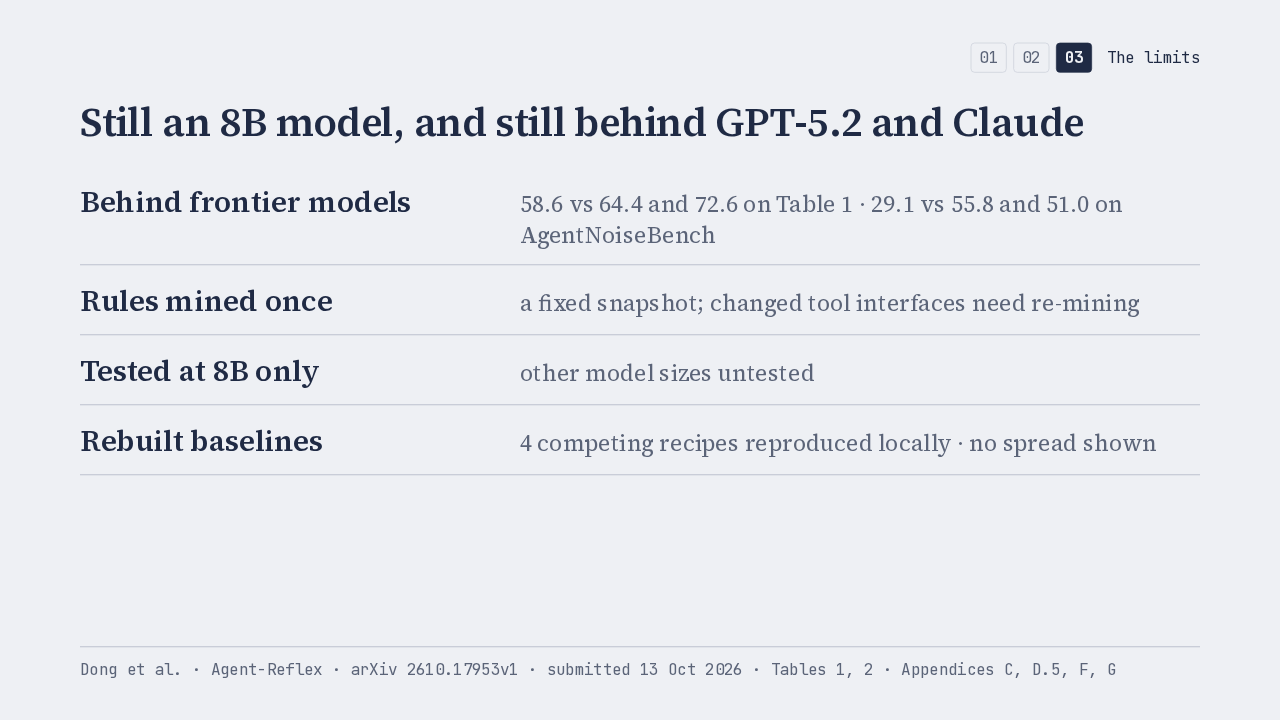
It is still an 8B model. GPT-5.2 and Claude 4.5 Sonnet score higher on every test here. The rules come from one fixed snapshot of services, so changed tools need new mining, and the recipe has only been tried at 8B.
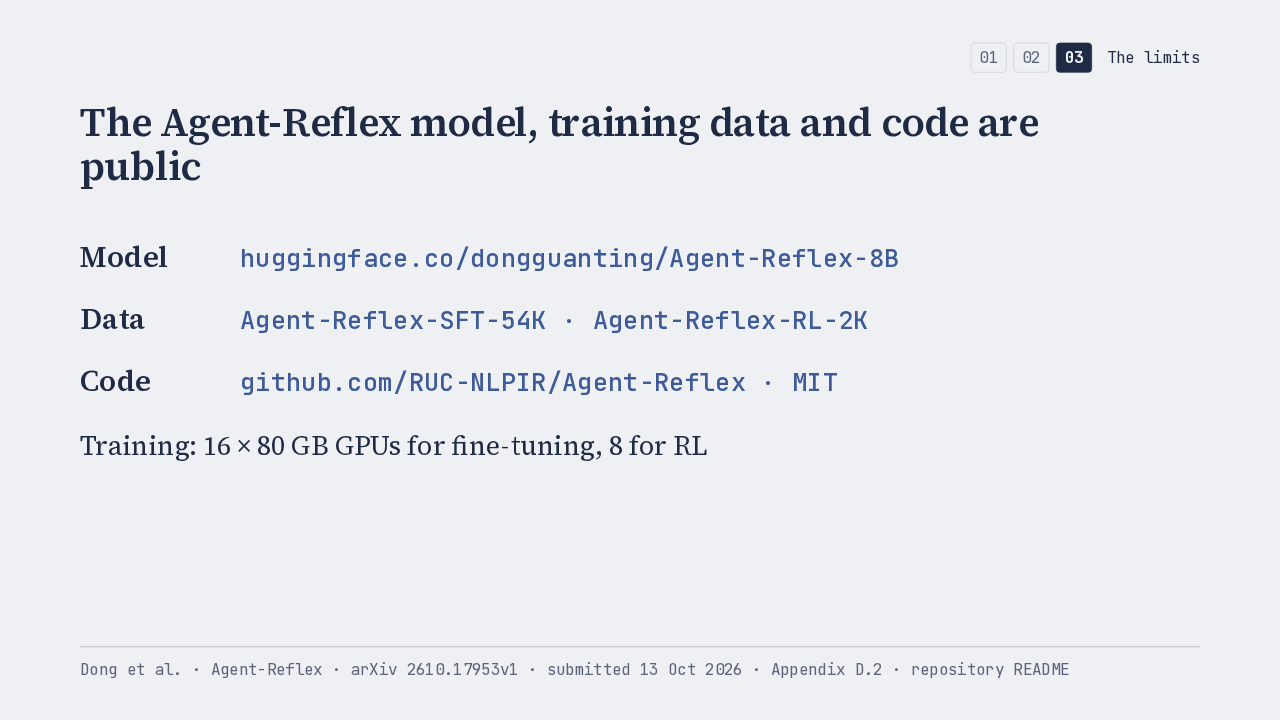
The checkpoint, both training sets, the rule library and the code are public under the MIT license. Retraining it takes sixteen 80-gigabyte GPUs for fine-tuning and eight for reinforcement learning.
Up next
 2:49
NestOne cuts a Qwen3.5 decision model to 24 layers at nearly full accuracy
@ai-papers
1 day ago
 2:33
MME-VLA robot memory counts a pause as work done and stops early
@ai-papers
3 days ago
 2:16
GPT-6 Astra fixed a small Qwen’s math by editing 1,023 of its weights
@ai-papers
5 days ago
 2:42
LoopVQ cuts looped models’ KV cache to half a bit and lifts Ouro’s throughput up to 6×
@ai-papers
1 week ago
 2:35
CUA-Master-27B is an open computer-use agent that trails only Claude Opus 5 and GPT-5.6-Sol on Agents' Last Exam
@ai-papers
1 week ago
 2:37
CaPtain trains Qwen3.5-4B to control a robot in code and beats several frontier-model agents
@ai-papers
1 week ago
 2:45
Trajectory2Gym data lifts a 4B Qwen3 agent past the stock 30B model on Tau2
@ai-papers
2 weeks ago
 2:46
“Wait” in reasoning models comes from training data, and RL almost never invents it
@ai-papers
3 weeks ago
 2:08
Looking Ahead makes Wan video models more physically plausible, with generation unchanged
@ai-papers
3 weeks ago
 2:30
OpenVLHarness gives vision models tools and a memory, and seven models each gain about 10 points
@ai-papers
3 weeks ago
 2:41
3DCodeVerse makes the same model write better 3D code than Claude Code, Codex or Gemini CLI
@ai-papers
4 weeks ago
 2:45
EmbodiedCLBench: one practice task gives AI agents most of their gain, and more practice doesn’t add to it
@ai-papers
1 month ago