LoopVQ cuts looped models’ KV cache to half a bit and lifts Ouro’s throughput up to 6×
23 hours ago
LoopVQ, a KV cache quantizer for looped language models, stores Ouro's cache at half a bit per value with about a point of accuracy lost, and raises peak SGLang serving throughput up to 6× on one GPU. Minsoo Cheong and Sungjoo Yoo, Seoul National University, arXiv 2611.05304v1 (3 Nov 2026). Paper: https://arxiv.org/abs/2611.05304 Code: https://github.com/mscheong01/LoopVQ
Ask about this presentation
Chapters
Show transcriptHide transcript
LoopVQ shrinks the context memory of looped language models to half a bit per value. On Ouro, that raises peak serving throughput up to six times. It comes from Minsoo Cheong and Sungjoo Yoo at Seoul National University.
Slide text

LoopVQ cuts looped models’ KV cache to half a bit and lifts Ouro’s throughput up to 6×
Minsoo Cheong, Sungjoo Yoo · Seoul National University
Cheong and Yoo · LoopVQ · arXiv 2611.05304v1 · 3 Nov 2026Looped models like Ouro run the same layers four times, so a small model performs like a much larger one. But every pass stores its own keys and values, six times the cache of Llama 3.1 8B.
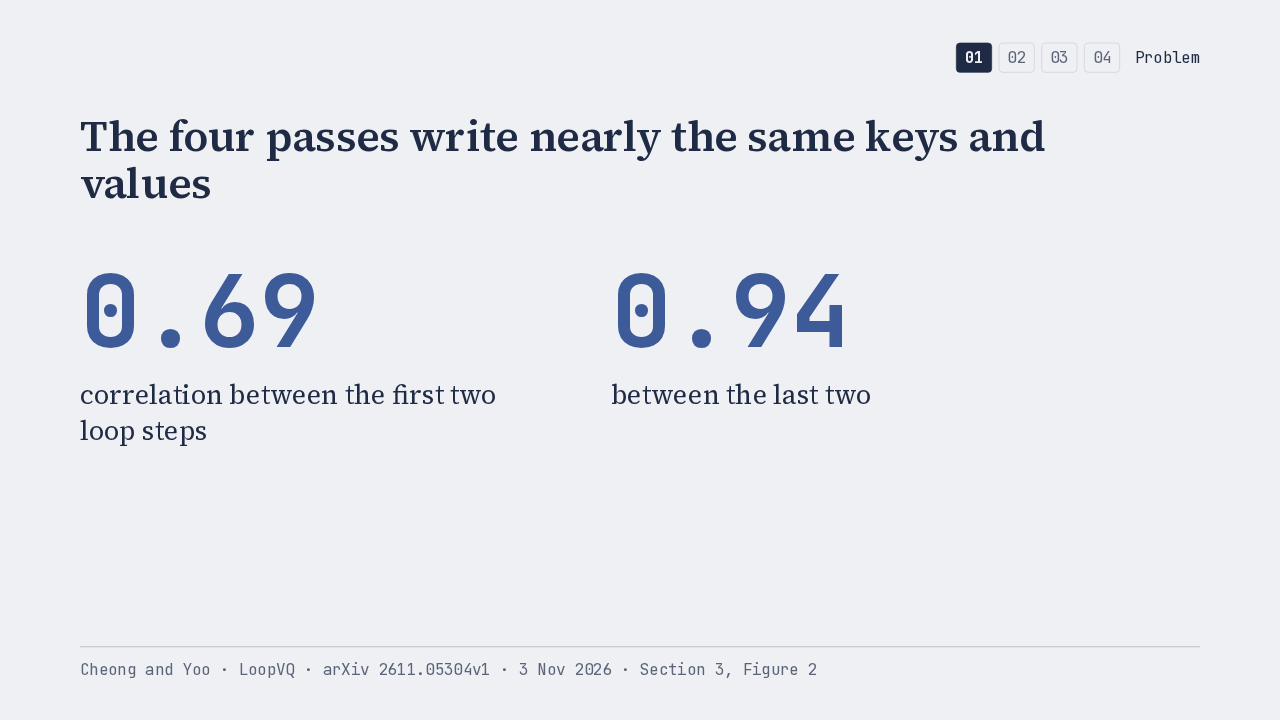
Those four copies are nearly identical, because the same weights compute them from the same token. Neighbouring passes correlate at about 0.7 early in the loop and above 0.9 by the end.
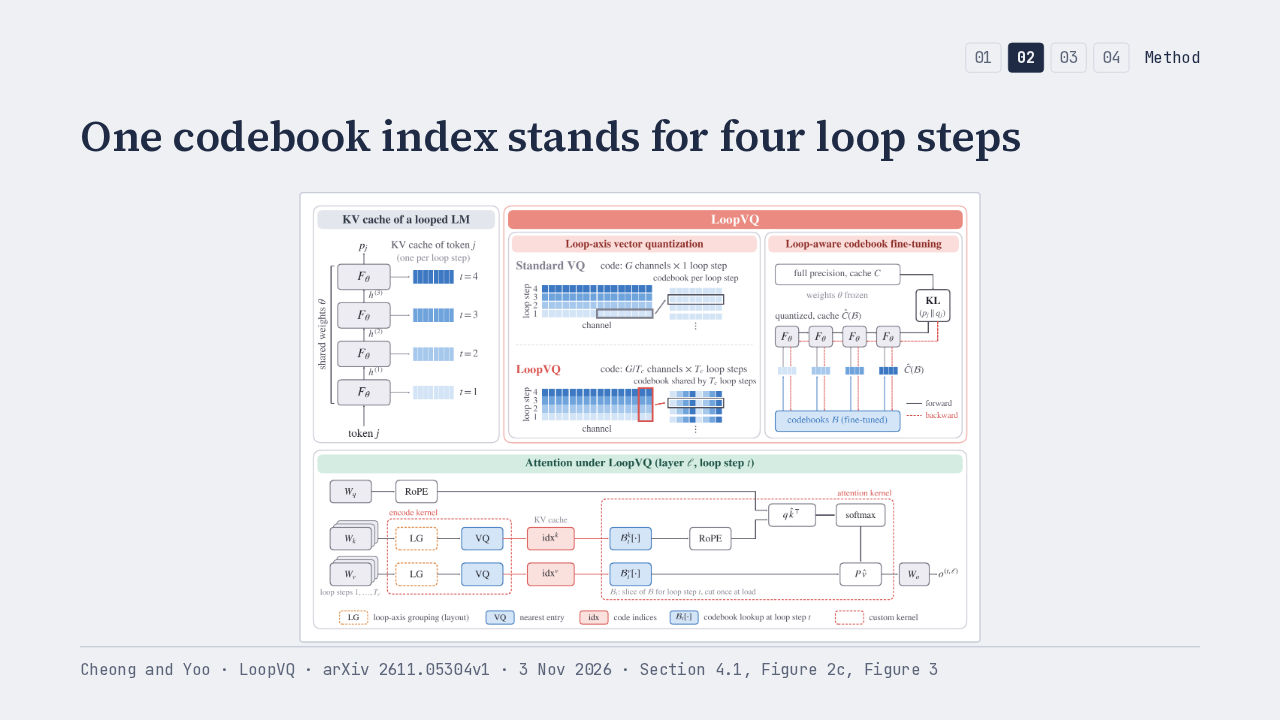
Standard vector quantization stores a separate code for each pass. LoopVQ groups channels across four passes, so one index covers all four at the same bit cost. At half a bit, that roughly halves the error.
Slide text
01 02 03 04 MethodOne codebook index stands for four loop steps
 Cheong and Yoo · LoopVQ · arXiv 2611.05304v1 · 3 Nov 2026 · Section 4.1, Figure 2c, Figure 3
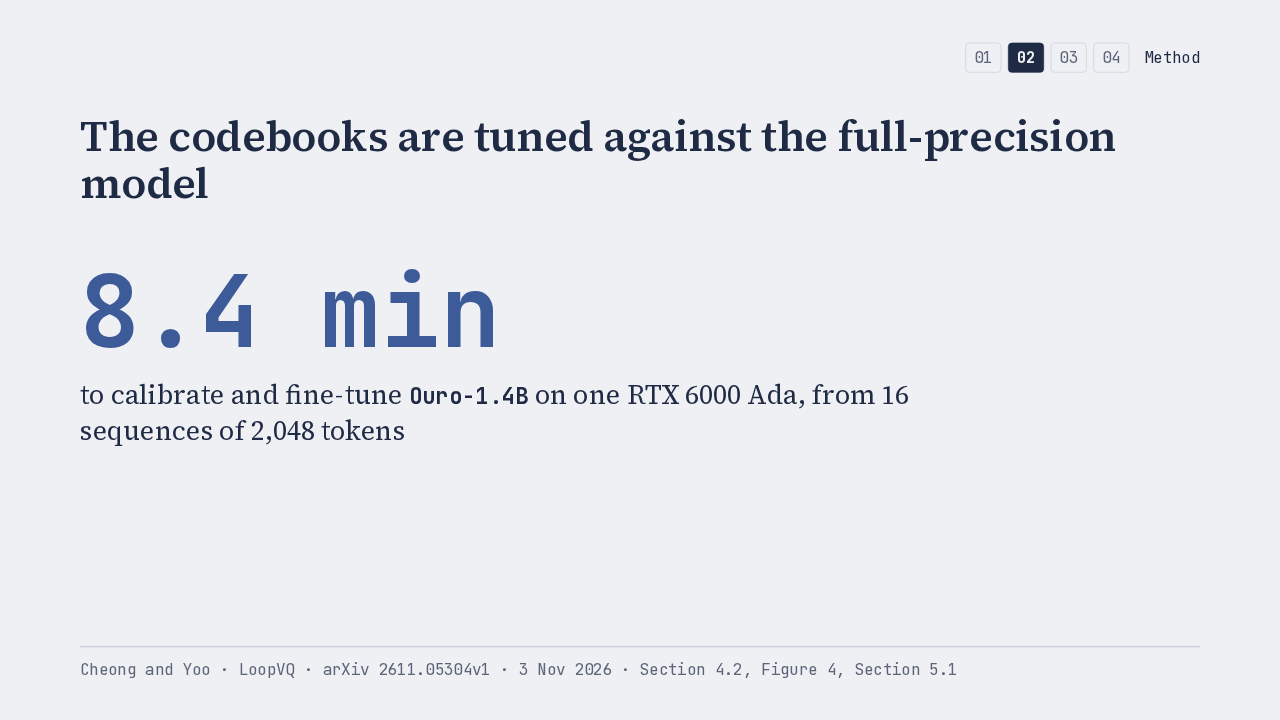
The codebooks are then fine-tuned until the quantized model's output matches the original's. For the 1.4 billion parameter Ouro, all of it takes about eight minutes on one RTX 6000 Ada card.
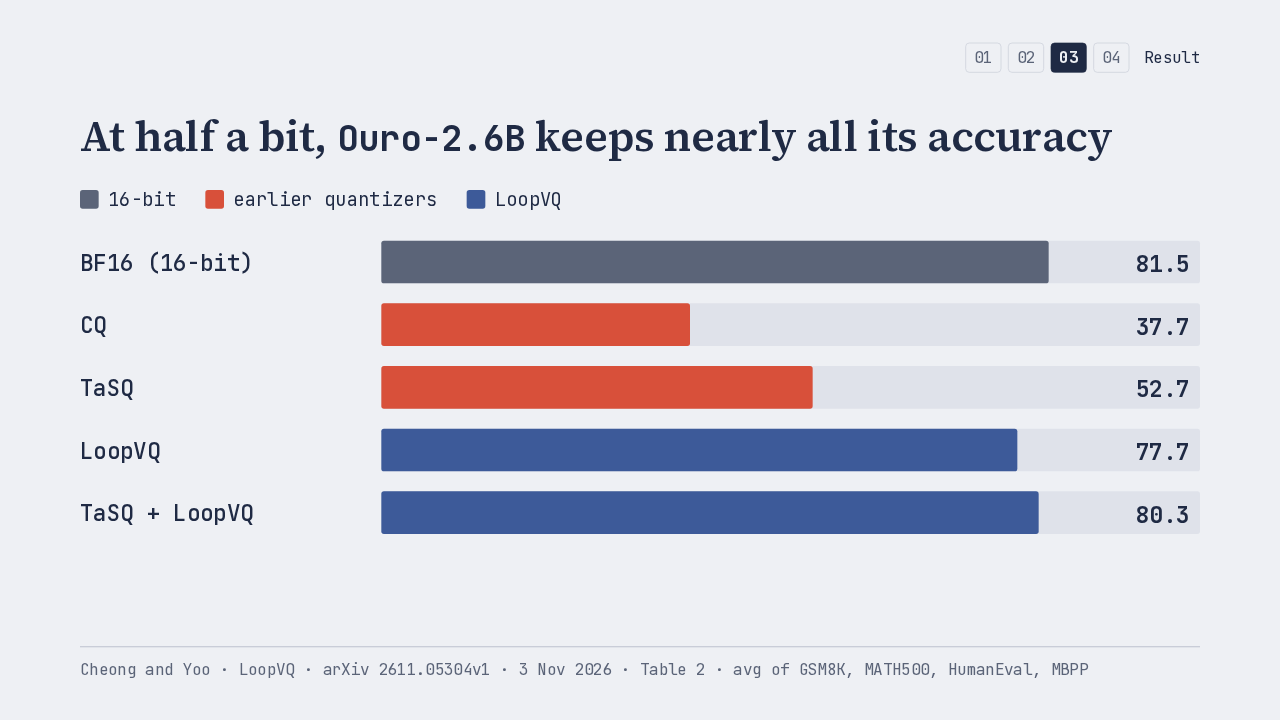
Half a bit is a 32-fold cut from 16-bit. At that size, earlier quantizers keep at most two thirds of Ouro's math and coding score. LoopVQ with TaSQ lands within about a point of full precision.
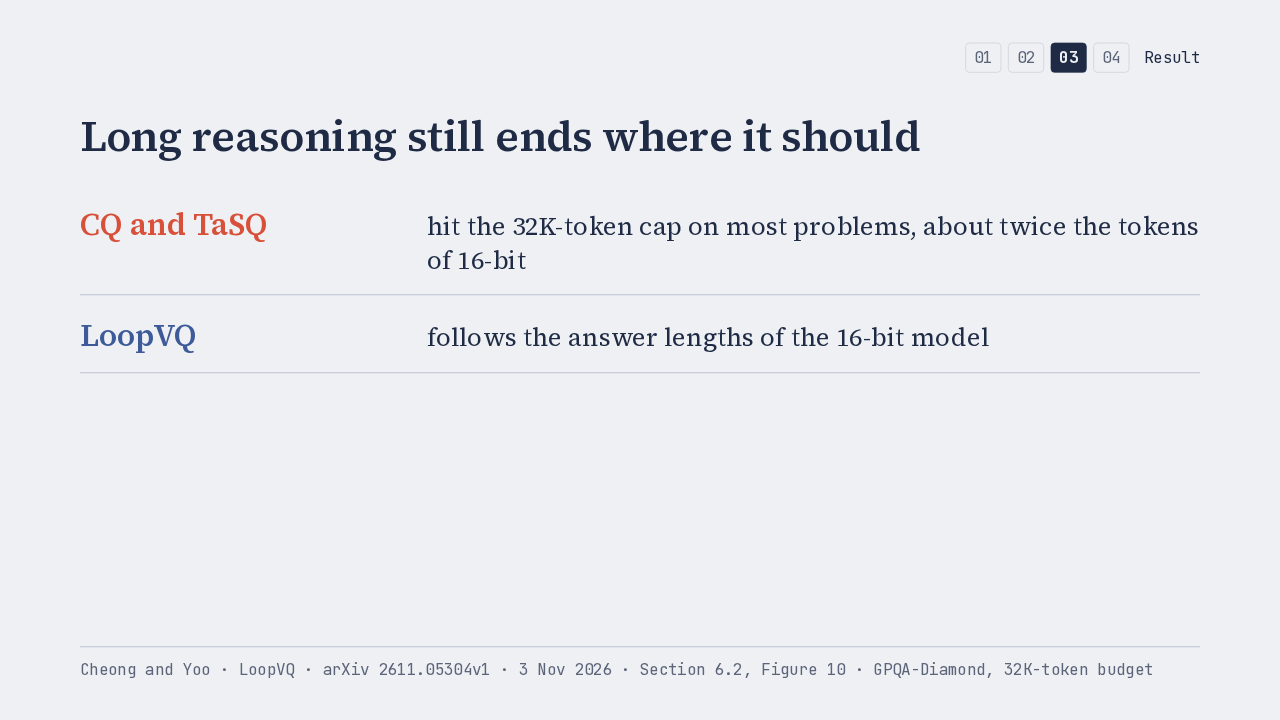
With earlier quantizers, Ouro's thinking model runs to the 32,000 token limit on most GPQA Diamond problems. With LoopVQ, answers stay as long as at full precision, so the speedup is real time saved.
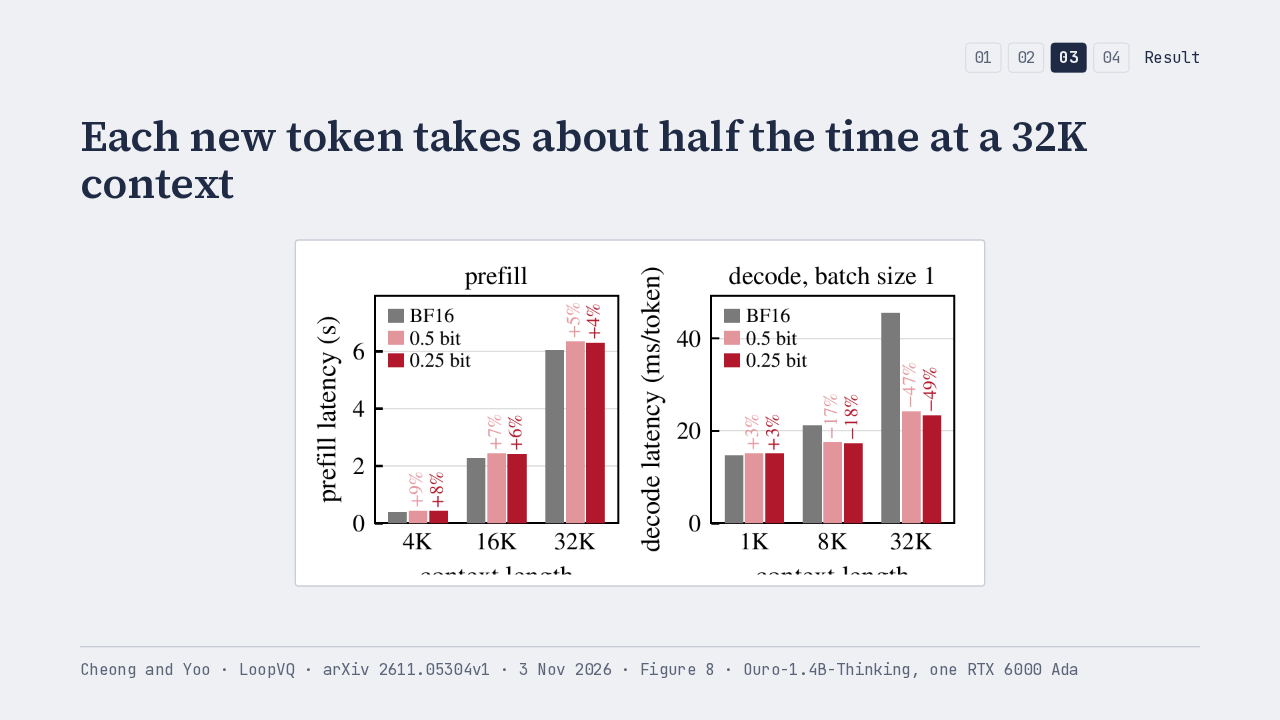
Decoding looks up small indices instead of 16-bit keys, so the saving grows with context. At 32,000 tokens, each new token takes about half as long. Prefill costs a few percent more.
Slide text
01 02 03 04 ResultEach new token takes about half the time at a 32K context
 Cheong and Yoo · LoopVQ · arXiv 2611.05304v1 · 3 Nov 2026 · Figure 8 · Ouro-1.4B-Thinking, one RTX 6000 Ada
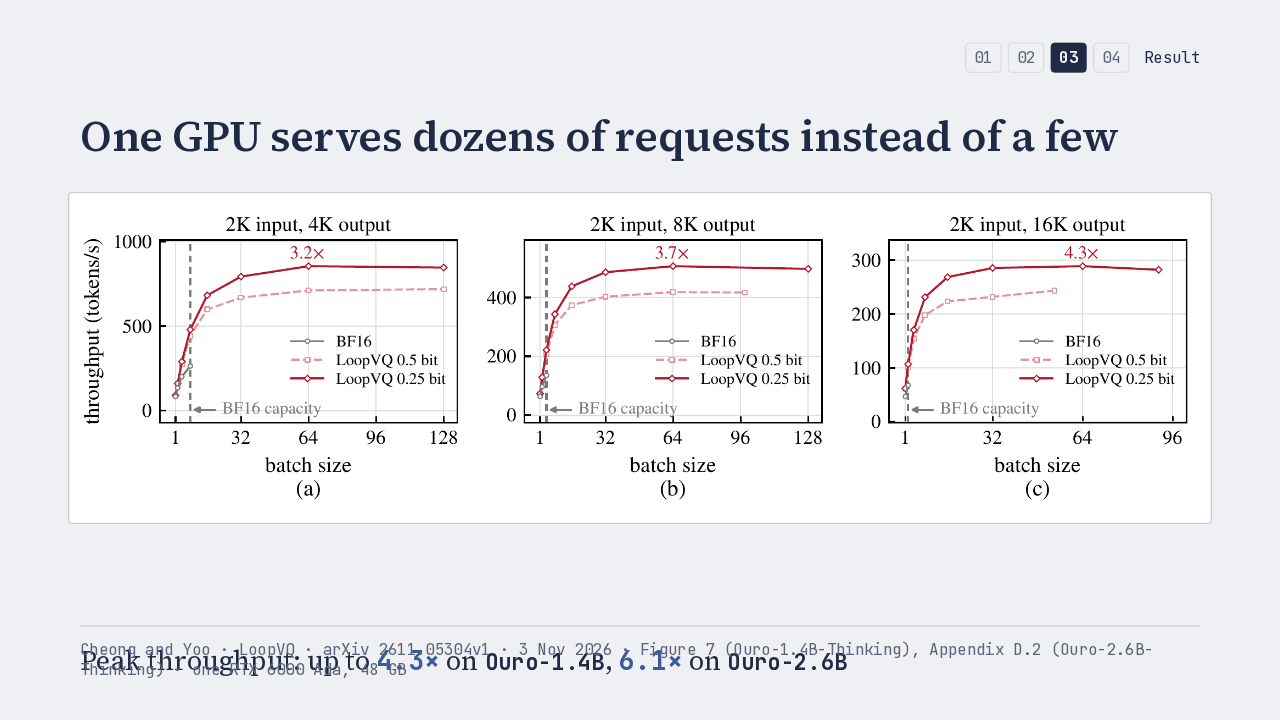
On one 48 gigabyte card, full precision fits only a few long requests, while LoopVQ serves dozens to over a hundred. Peak throughput rises up to four times on the smaller Ouro, and six on the larger.
Slide text
01 02 03 04 ResultOne GPU serves dozens of requests instead of a few

Peak throughput: up to 4.3× on
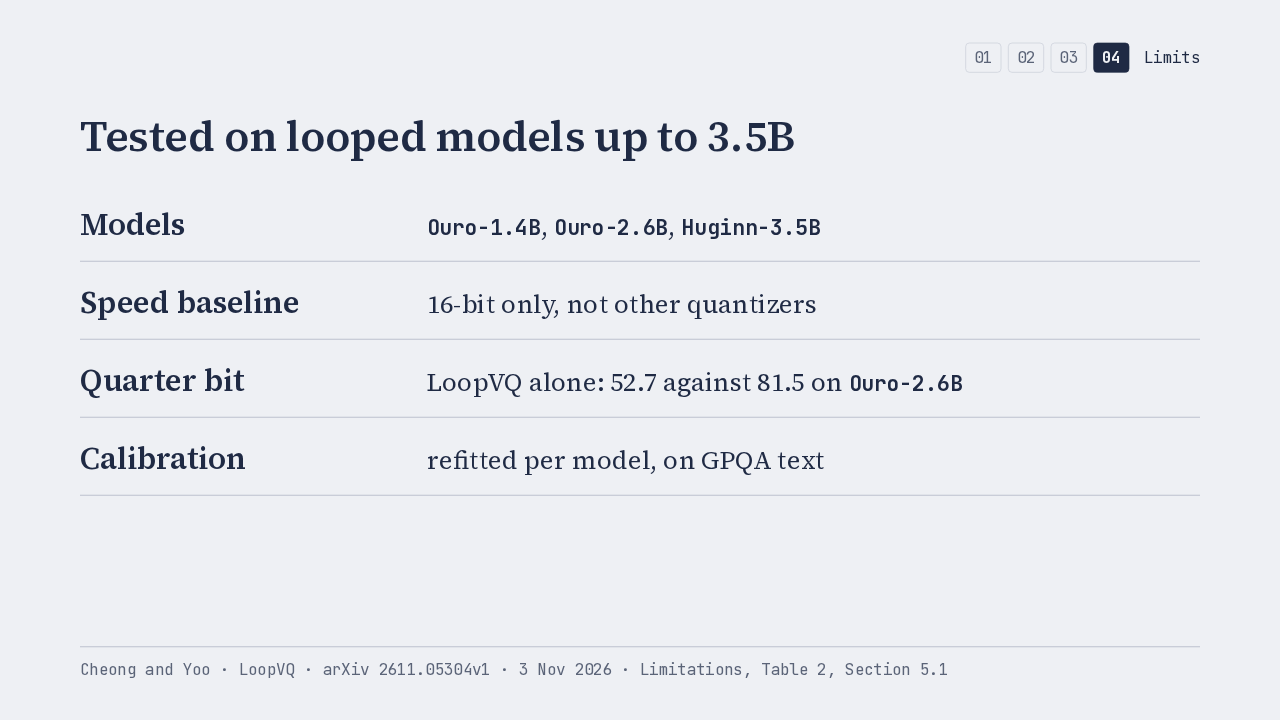
Ouro-1.4B, 6.1× onOuro-2.6BCheong and Yoo · LoopVQ · arXiv 2611.05304v1 · 3 Nov 2026 · Figure 7 (Ouro-1.4B-Thinking), Appendix D.2 (Ouro-2.6B-Thinking) · one RTX 6000 Ada, 48 GBLoopVQ is tested only on looped models of 3.5 billion parameters or fewer, and its speed only against full precision. At a quarter bit, it loses about a third of Ouro's score, and every model needs its own calibration.
Serving Ouro on one card, I would run TaSQ with LoopVQ at half a bit: about a point of accuracy for several times the throughput. The code and its SGLang server are on GitHub under the Apache license.
Up next
 2:35
CUA-Master-27B is an open computer-use agent that trails only Claude Opus 5 and GPT-5.6-Sol on Agents' Last Exam
@ai-papers · 3 days ago
 2:37
CaPtain trains Qwen3.5-4B to control a robot in code and beats several frontier-model agents
@ai-papers · 4 days ago
 2:45
Trajectory2Gym data lifts a 4B Qwen3 agent past the stock 30B model on Tau2
@ai-papers · 1 week ago
 2:46
“Wait” in reasoning models comes from training data, and RL almost never invents it
@ai-papers · 2 weeks ago
 2:08
Looking Ahead makes Wan video models more physically plausible, with generation unchanged
@ai-papers · 2 weeks ago
 2:30
OpenVLHarness gives vision models tools and a memory, and seven models each gain about 10 points
@ai-papers · 2 weeks ago
 2:41
3DCodeVerse makes the same model write better 3D code than Claude Code, Codex or Gemini CLI
@ai-papers · 3 weeks ago
 2:53
Agent-Reflex trains an 8B agent to recover when its MCP tools fail, and it gets derailed half as often
@ai-papers · 3 weeks ago
 2:45
EmbodiedCLBench: one practice task gives AI agents most of their gain, and more practice doesn’t add to it
@ai-papers · 3 weeks ago
 3:11
Tool-using agents often act before checking the evidence the action needs
@ai-papers · 4 weeks ago
 3:19
Given enough tries, base models solve more agent tasks than their post-trained versions
@ai-papers · 1 month ago
 4:57
Coding agents solve fewer SWE-bench issues once a repository's names are changed
@ai-papers · 1 month ago