Ollama runs Perplexity's pplx-decider, a local 27B model that routes, checks and grades

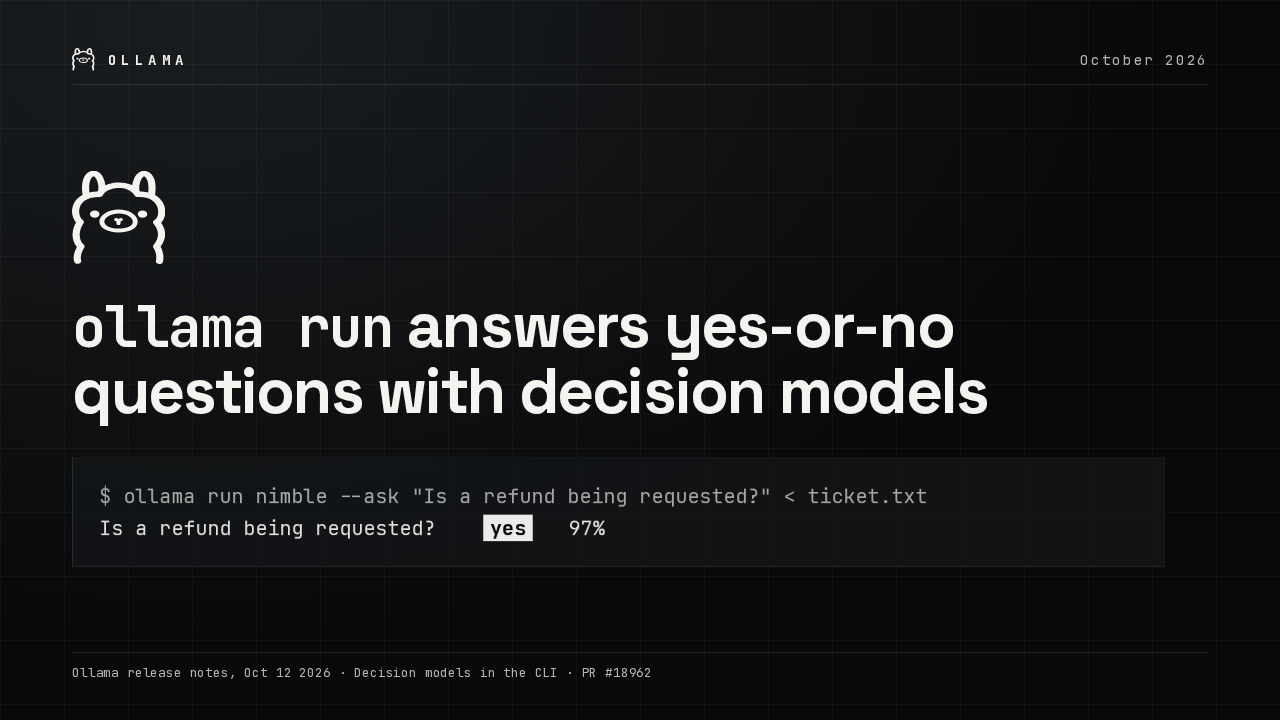
$ ollama run pplx-decider --ask "Is a refund being requested?" < ticket.txt
Ollama now runs pplx-decider, a 27 billion parameter decision model from Perplexity, fine-tuned from Qwen 3.8. Hand it a support ticket, a screenshot or a form, ask a question in plain words, and it decides.
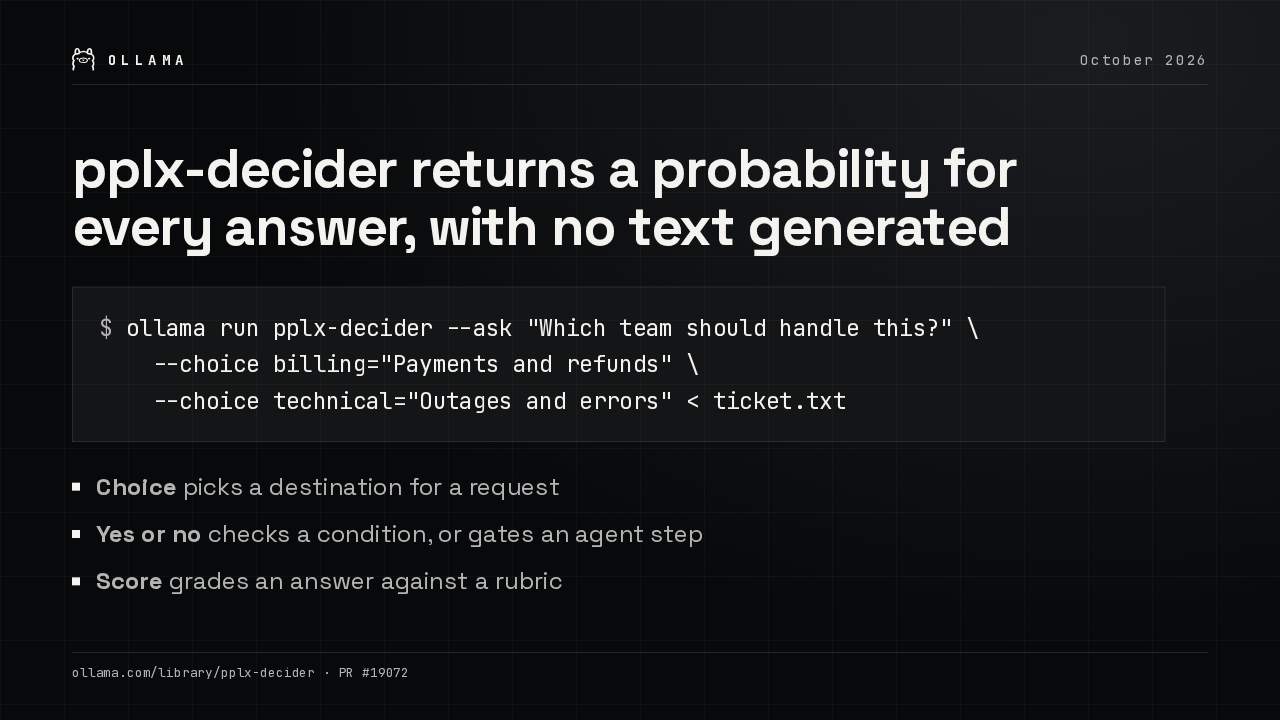
pplx-decider returns a probability for every answer, with no text generated
$ ollama run pplx-decider --ask "Which team should handle this?" \
    --choice billing="Payments and refunds" \
    --choice technical="Outages and errors" < ticket.txt
- Choice picks a destination for a request
- Yes or no checks a condition, or gates an agent step
- Score grades an answer against a rubric
pplx-decider never writes a reply. It scores every option of every question in one pass. So it can route a ticket to billing, check a yes or no condition, or grade an answer.
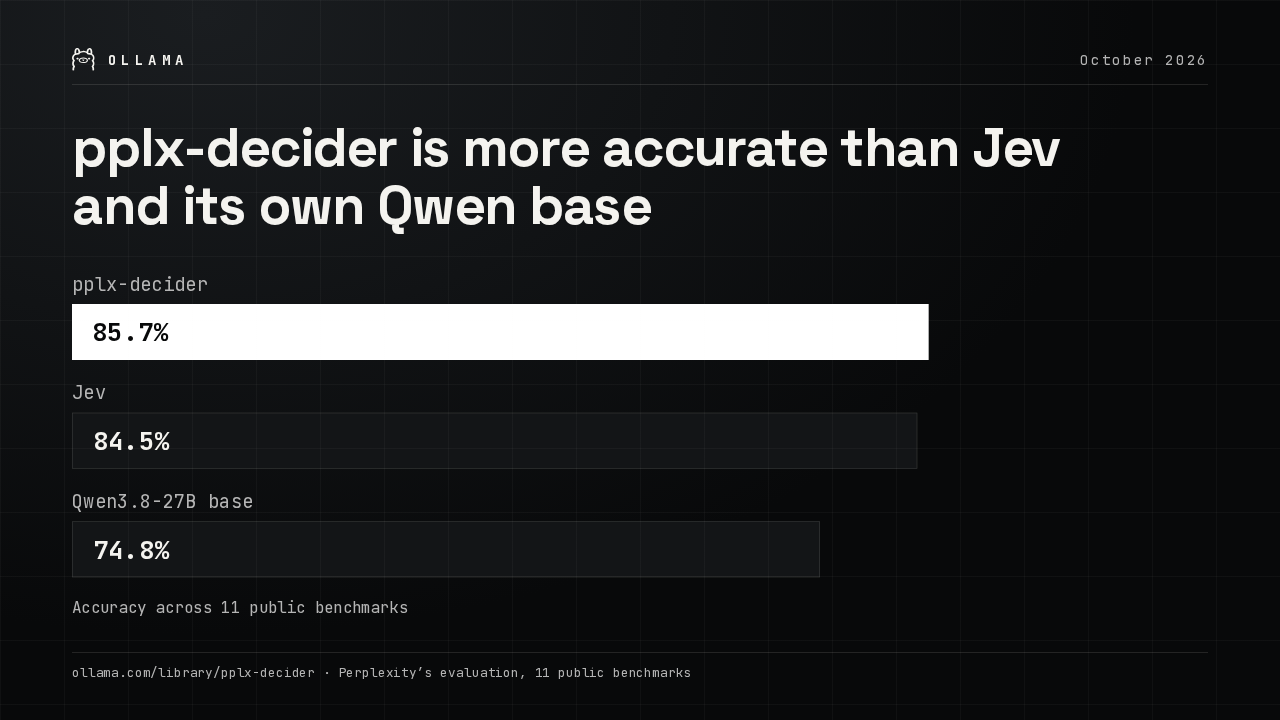
pplx-decider is more accurate than Jev and its own Qwen base
Across eleven public benchmarks, pplx-decider edges out the Jev decision model, and gets about one more answer in ten right than the Qwen model it was trained from.
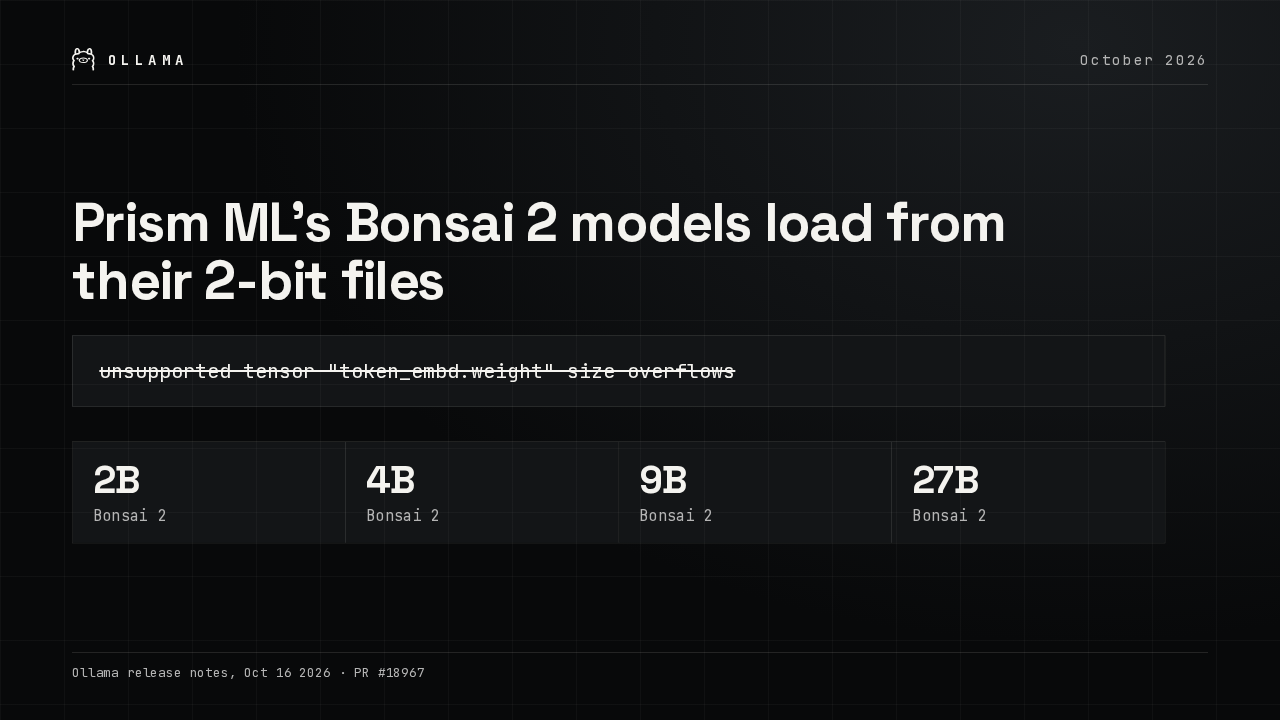
Prism ML's Bonsai 2 models load from their 2-bit files
Prism ML’s Bonsai 2 models load from their 2-bit files
unsupported tensor "token_embd.weight" size overflows
Ollama now reads the two-bit Q2_0 format. Those files used to stop with a size overflow error, at create time and at load. That unblocks Prism ML's Bonsai 2 models, from 2 billion to 27 billion parameters.
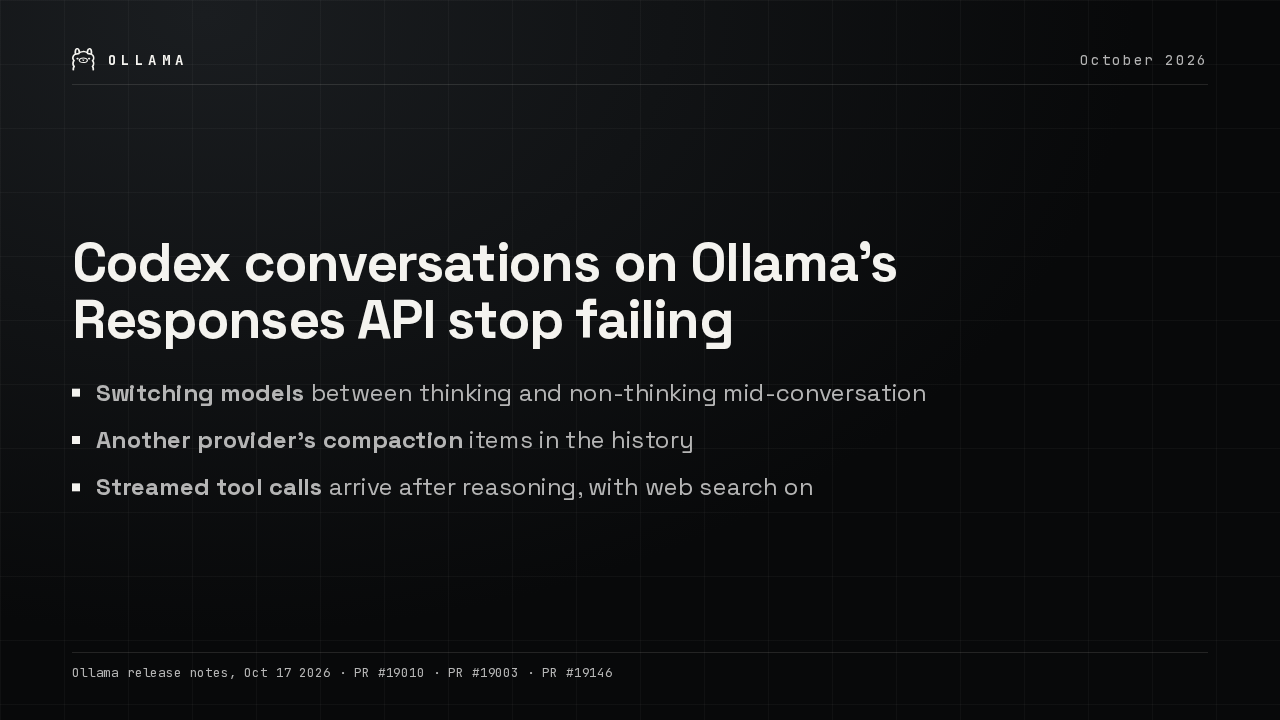
Codex conversations on Ollama's Responses API stop failing
Codex conversations on Ollama’s Responses API stop failing
- Switching models between thinking and non-thinking mid-conversation
- Another provider’s compaction items in the history
- Streamed tool calls arrive after reasoning, with web search on
Codex and other OpenAI Responses clients get three fixes. A conversation can switch between thinking and non-thinking models, carry another provider's compacted history, and stream tool calls without duplicates.
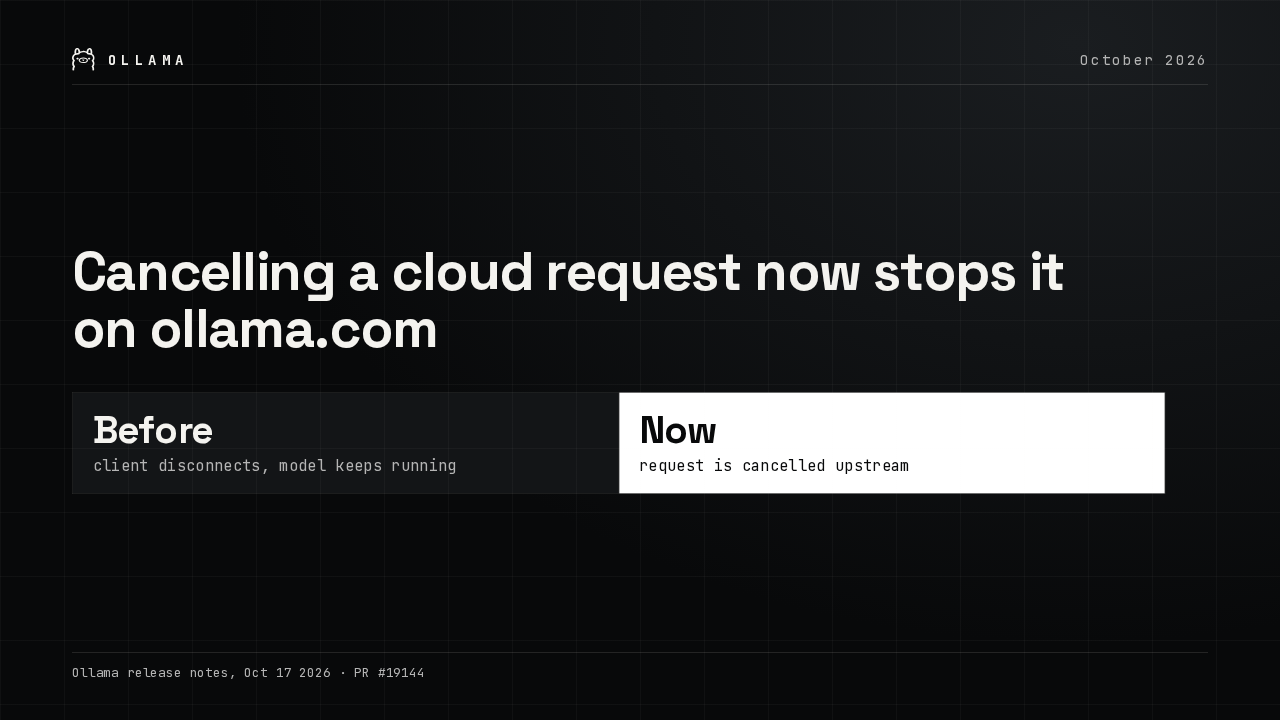
Cancelling a cloud request now stops it on ollama.com
When your client disconnects from a request to a cloud model, Ollama now cancels it on ollama.com. Before, the remote model kept generating after you had walked away.
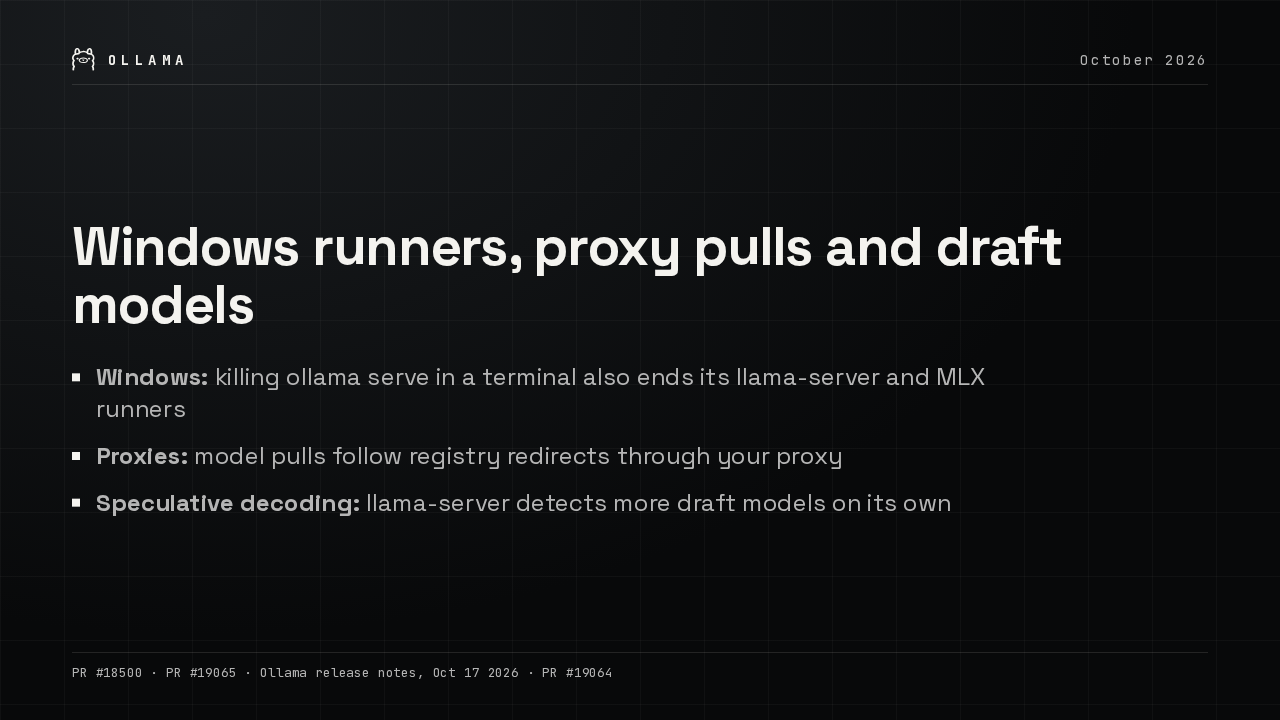
Windows runners, proxy pulls and draft models
- Windows: killing ollama serve in a terminal also ends its llama-server and MLX runners
- Proxies: model pulls follow registry redirects through your proxy
- Speculative decoding: llama-server detects more draft models on its own
On Windows, killing ollama serve now takes its llama server and MLX runners with it, instead of leaving them running. Pulls work behind a proxy, and more draft models work for speculative decoding.
Which question would you hand pplx-decider first?
The full list is in Ollama's release notes on GitHub. Which question would you hand pplx-decider first?