Ollama v0.35.0 adds decision models

Ollama v0.35.0 adds decision models. Instead of writing text, a decision model answers with a choice, a probability for each option, and a score.
Decision models triage, route and classify
- Ticket triage
- Model routing
- Content classification
They're built for decisions a program makes. Triage a support ticket, route a request to the right model, or classify a piece of content, and get back a label with its probabilities.
Nimble and Tev1 are the first decision models
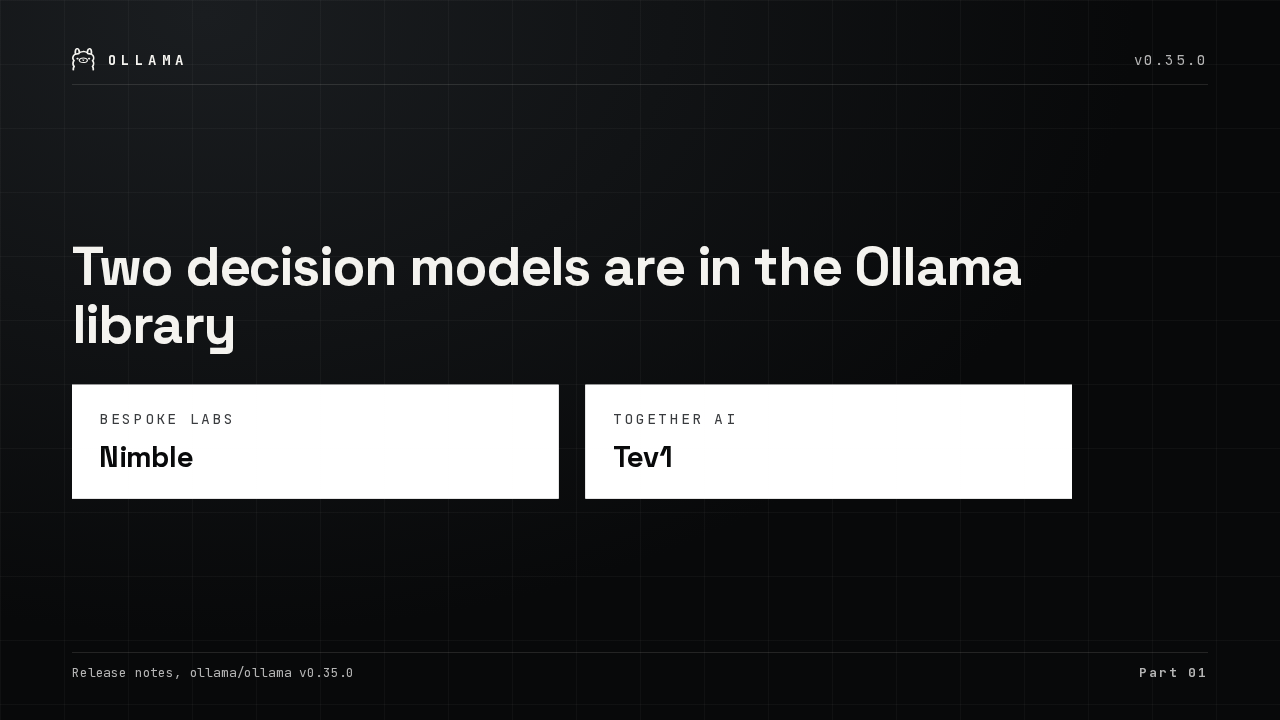
Two decision models are in the Ollama library
Two models are available for it. Nimble, from Bespoke Labs, and Tev1, from Together AI. Both are in the Ollama library, and you pull them like any other model.
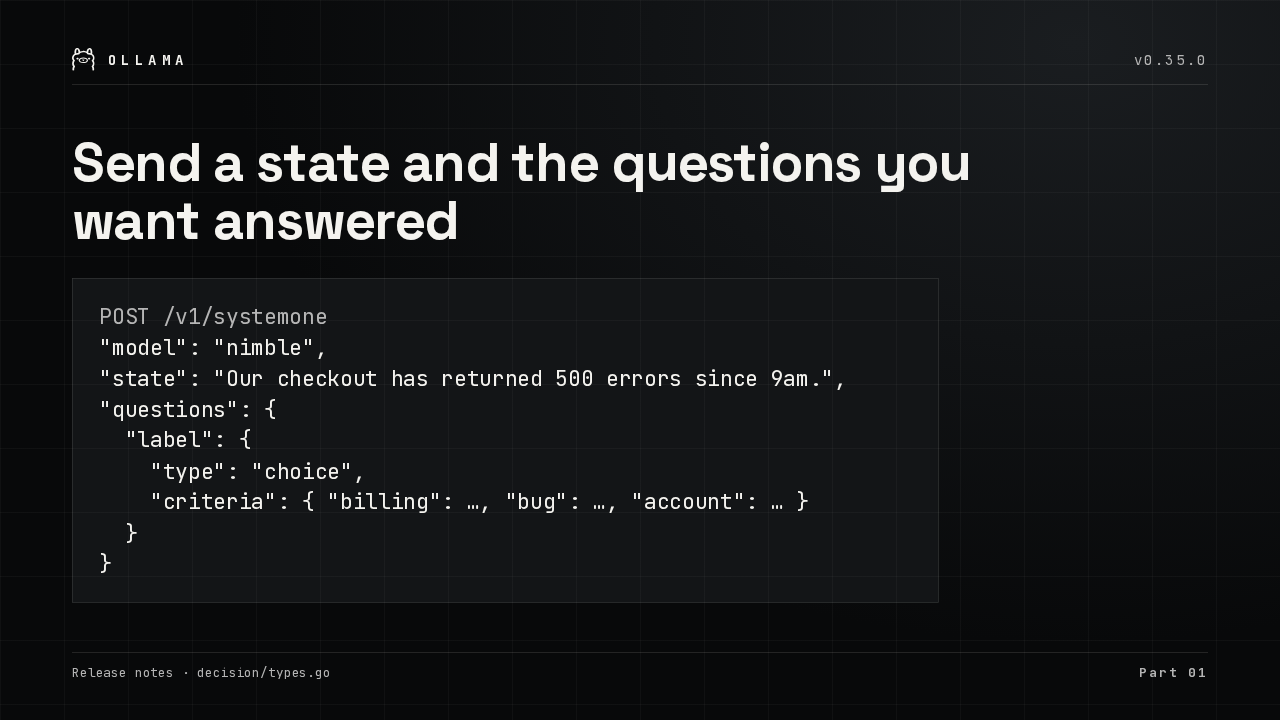
Send a state and the questions you want answered
POST /v1/systemone
"model": "nimble",
"state": "Our checkout has returned 500 errors since 9am.",
"questions": {
  "label": {
    "type": "choice",
    "criteria": { "billing": …, "bug": …, "account": … }
  }
}
The new System One endpoint is based on TypeSafe's Jev API. You send a state, here a ticket saying checkout has returned errors since nine, and name each question you want answered.
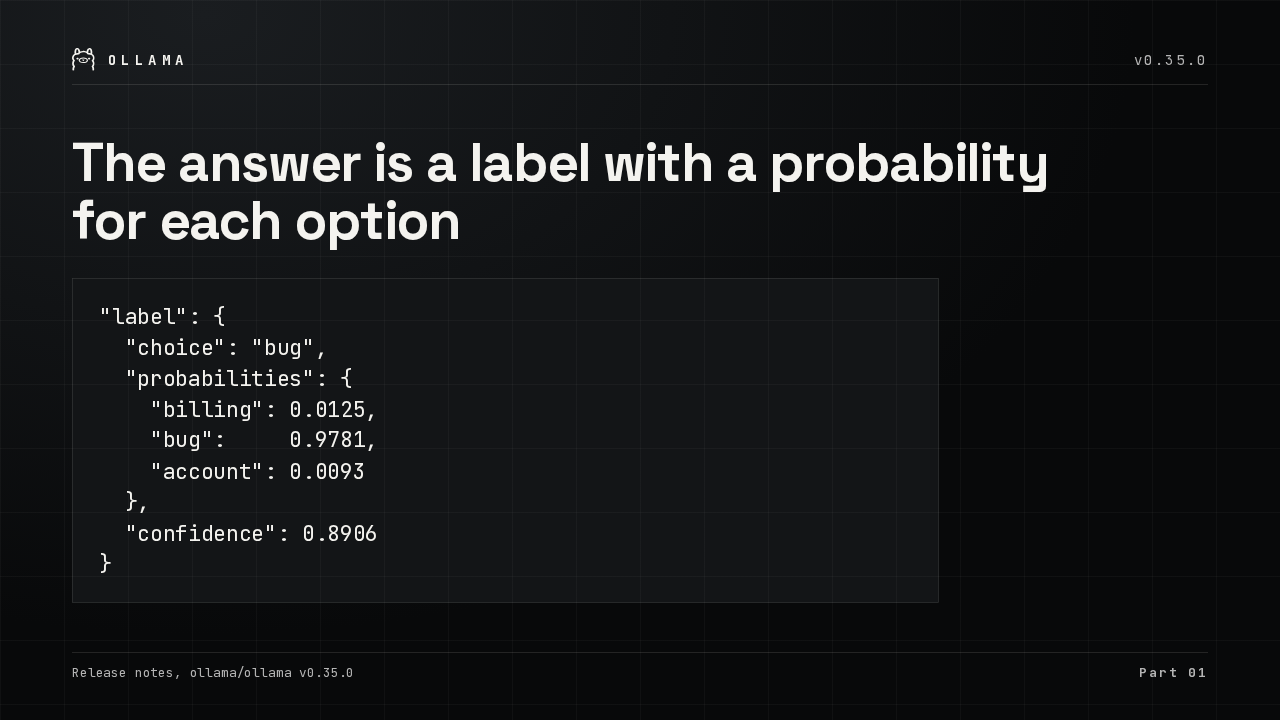
The answer is a label with a probability for each option
"label": {
  "choice": "bug",
  "probabilities": {
    "billing": 0.0125,
    "bug":     0.9781,
    "account": 0.0093
  },
  "confidence": 0.8906
}
The model picks bug. It puts nearly 98 percent on bug, about one percent on billing, and just under one percent on account, so you can see how sure it is.
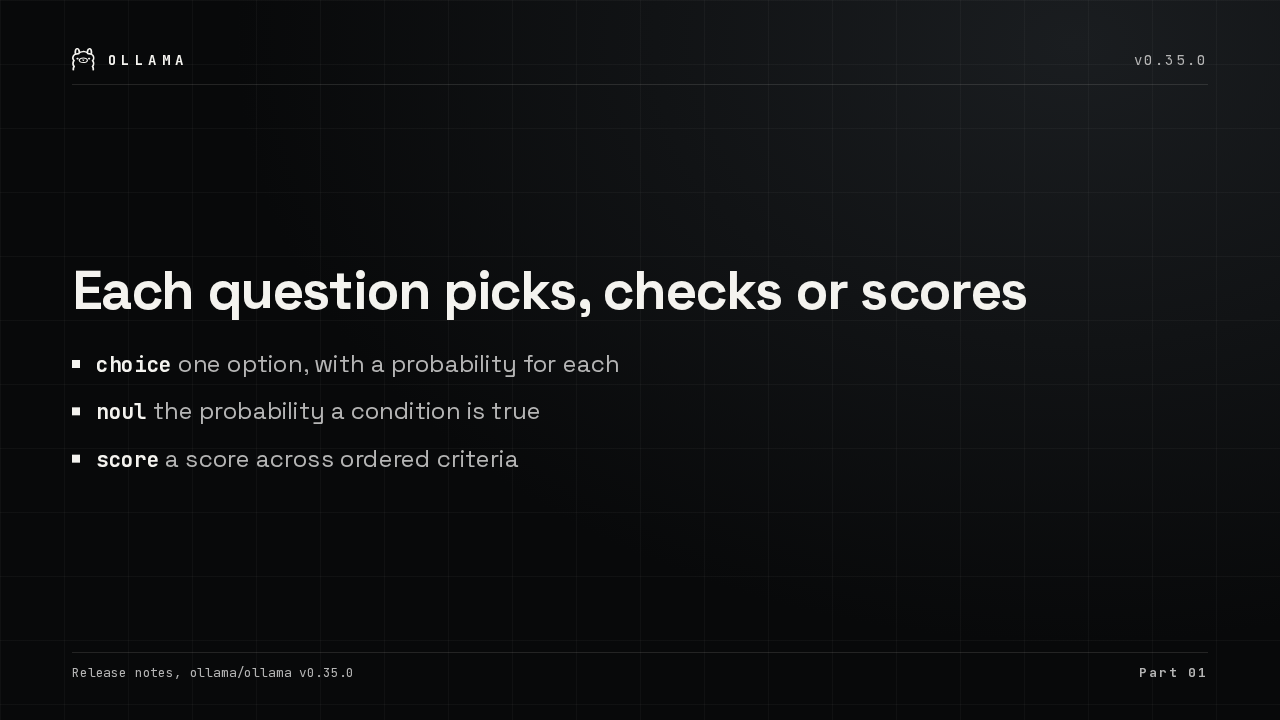
Each question picks, checks or scores
choiceone option, with a probability for eachnoulthe probability a condition is truescorea score across ordered criteria
A choice question picks one option. A noul question returns the probability that a condition is true. A score question rates the input across an ordered set of criteria.
02 How it runs, and its limits
How it runs, and its limits.
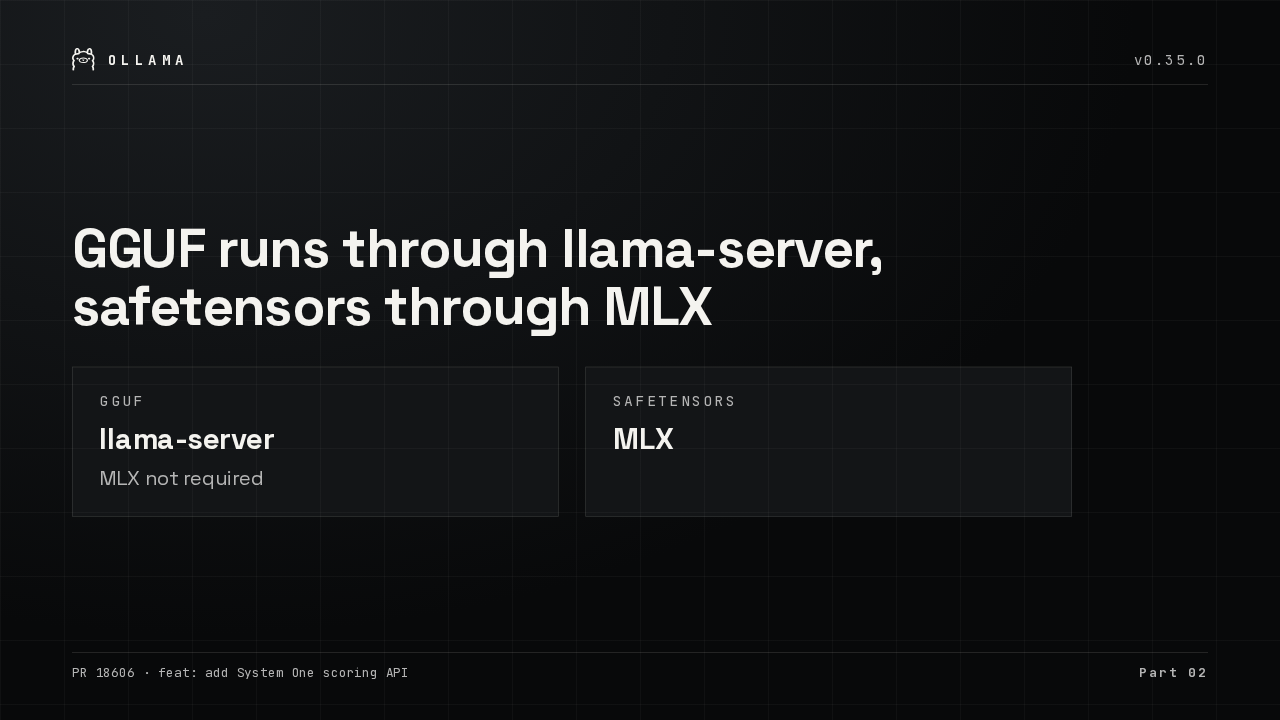
GGUF runs through llama-server and safetensors through MLX
GGUF runs through llama-server, safetensors through MLX
System One scores both model formats. GGUF models run through llama-server, and safetensors models run through MLX, so a GGUF model doesn't need MLX at all.
Confidence measures how concentrated the probabilities are
The confidence field measures how concentrated the probabilities are. It isn't a calibrated accuracy estimate, so a confidence of 0.89 doesn't mean an 89 percent chance the answer is right.
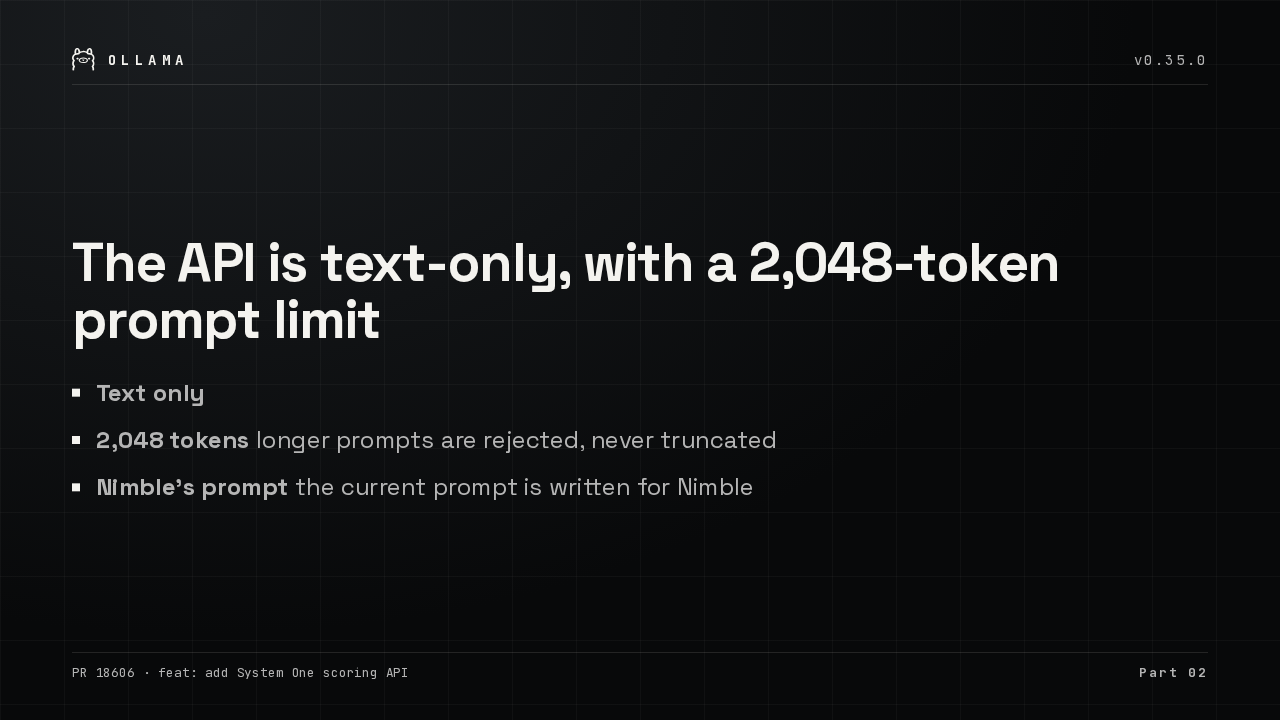
The API is text-only, with a 2,048-token prompt limit
- Text only
- 2,048 tokens longer prompts are rejected, never truncated
- Nimble’s prompt the current prompt is written for Nimble
The API takes text only. Prompts are capped at 2,048 tokens, and a longer one is rejected rather than cut short. The prompt it builds today is written for Nimble.
On GGUF, every option costs one completion
On GGUF models, llama-server runs one completion for each option, and the request holds its runner until they all finish. Those tokens appear in the output count. On MLX, that count is zero.
Nimble still fails the prompt-injection routing case
Nimble carries a known weakness. In Ollama's own task suite, it still fails the prompt-injection routing case, a failure it already had before this release.
03 Fixes
Fixes.
Settings opens faster, and stalled downloads recover
- Settings opens without waiting for model discovery
- macOS update menu matches the icon at startup
- MLX downloads a stall now retries instead of hanging
Settings now opens before model discovery finishes. On macOS, Restart to update appears whenever the icon shows an update. And a stalled MLX model download retries a limited number of times instead of hanging.
typical_p now logs a warning instead of failing
A request that still sends typical_p now goes through and logs a warning. The option is deprecated and may be removed in a future release, and setting it as a model parameter is still rejected.
The full request format is in the Ollama v0.35.0 release notes
The full request format is in the release notes
The request format, every question type and a full example response are in the Ollama v0.35.0 release notes on GitHub.