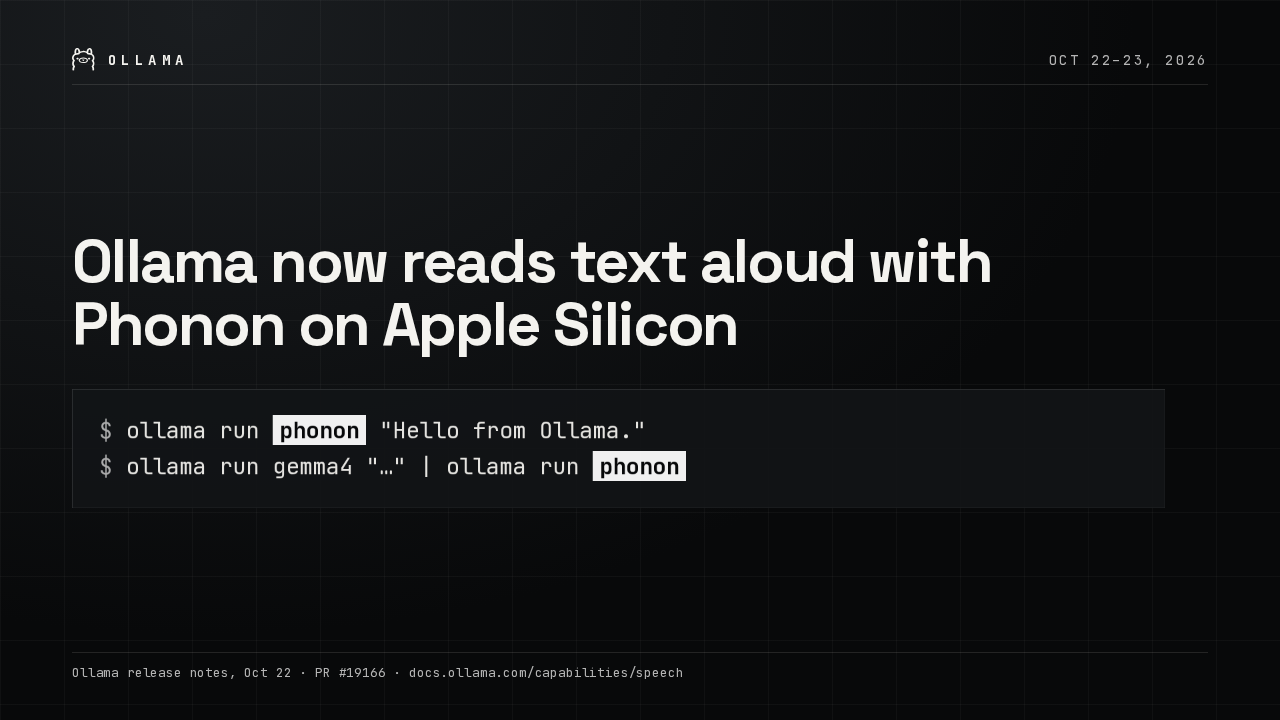
Ollama now reads text aloud with Phonon on Apple Silicon

$ ollama run phonon "Hello from Ollama."
$ ollama run gemma4 "…" | ollama run phonon
Ollama can talk now. Phonon is a text-to-speech model that runs on Apple Silicon. Give it text, or pipe a chat model's answer into it, and the audio starts playing while the rest is still being generated.
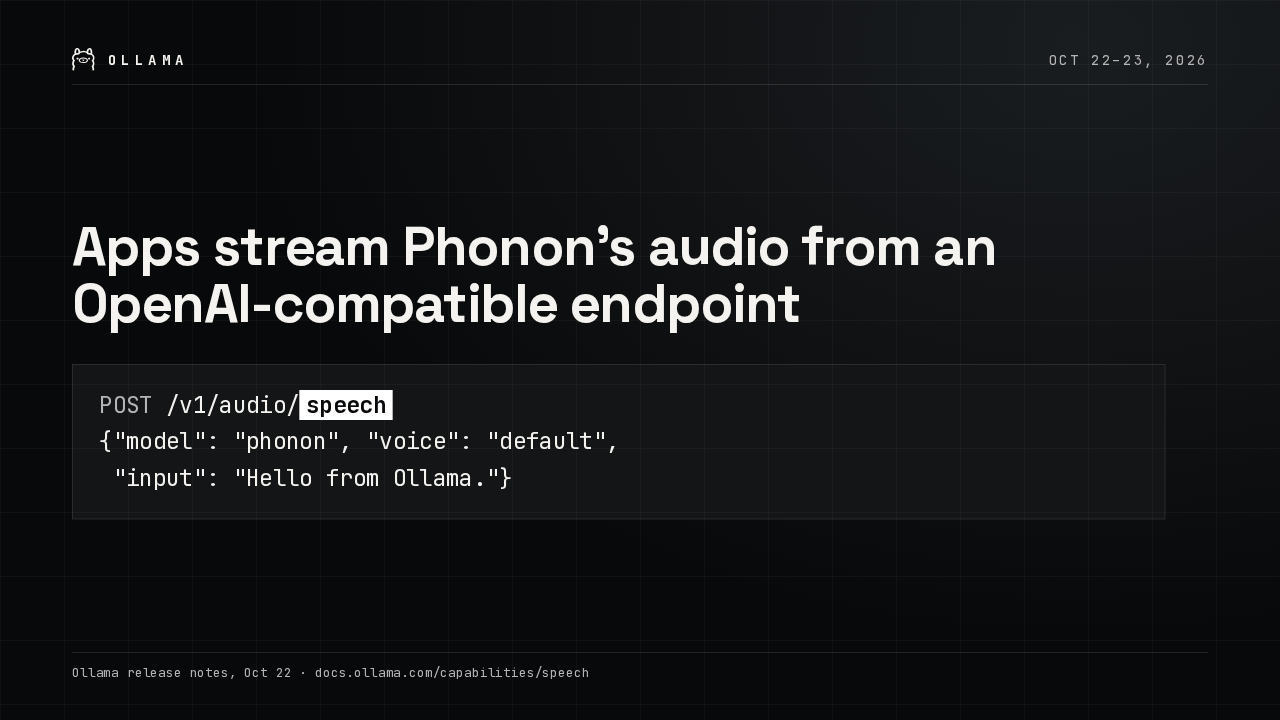
Apps stream Phonon's audio from an OpenAI-compatible endpoint
Apps stream Phonon’s audio from an OpenAI-compatible endpoint
POST /v1/audio/speech
{"model": "phonon", "voice": "default",
 "input": "Hello from Ollama."}
Apps get the same voice through Ollama's OpenAI-compatible speech endpoint, so code written for OpenAI's speech API can point at your own machine. Phonon speaks English, and it needs numbers written out as words.
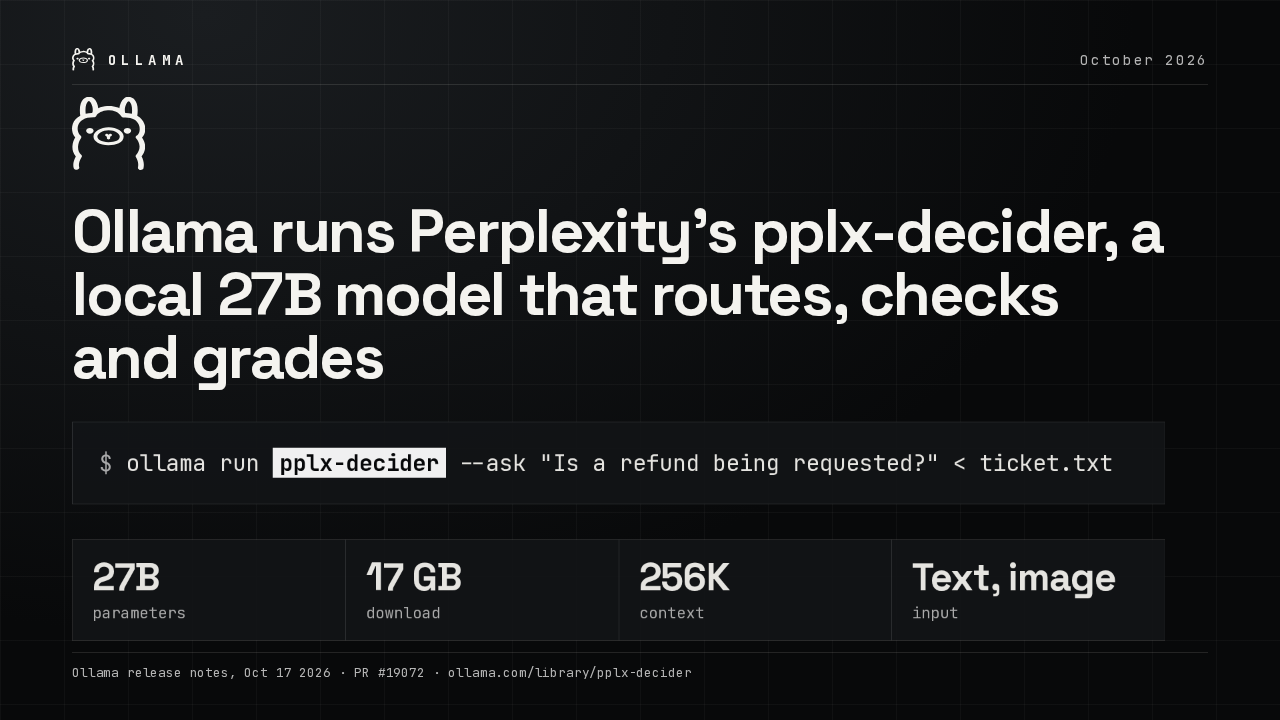
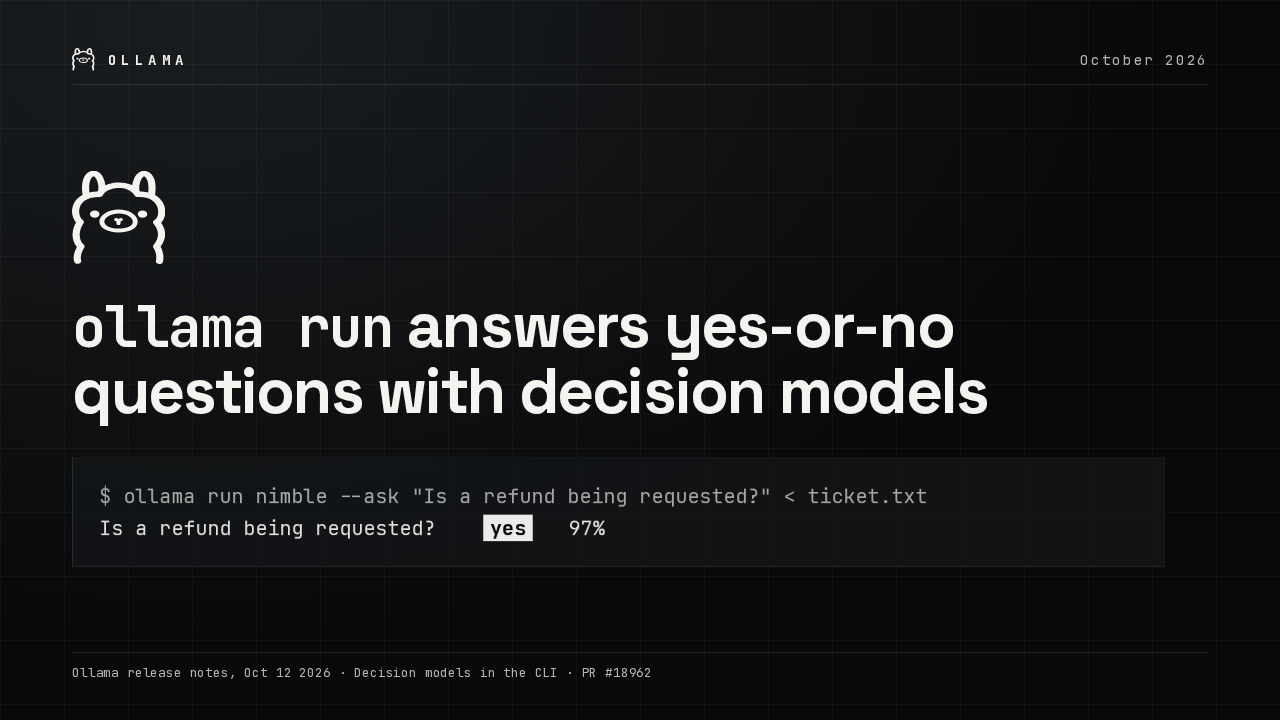
d3 models sort, answer yes or no, and score options with probabilities
$ ollama run d3 "A customer says their card
  was charged twice." --ask "Is this a billing issue?"
d3 brings vLLM Semantic Router's decision models to Ollama. Give one text, structured data or an image, then ask it to sort, answer yes or no, or put a probability on each option. Sizes run from 2 billion to 27 billion parameters.
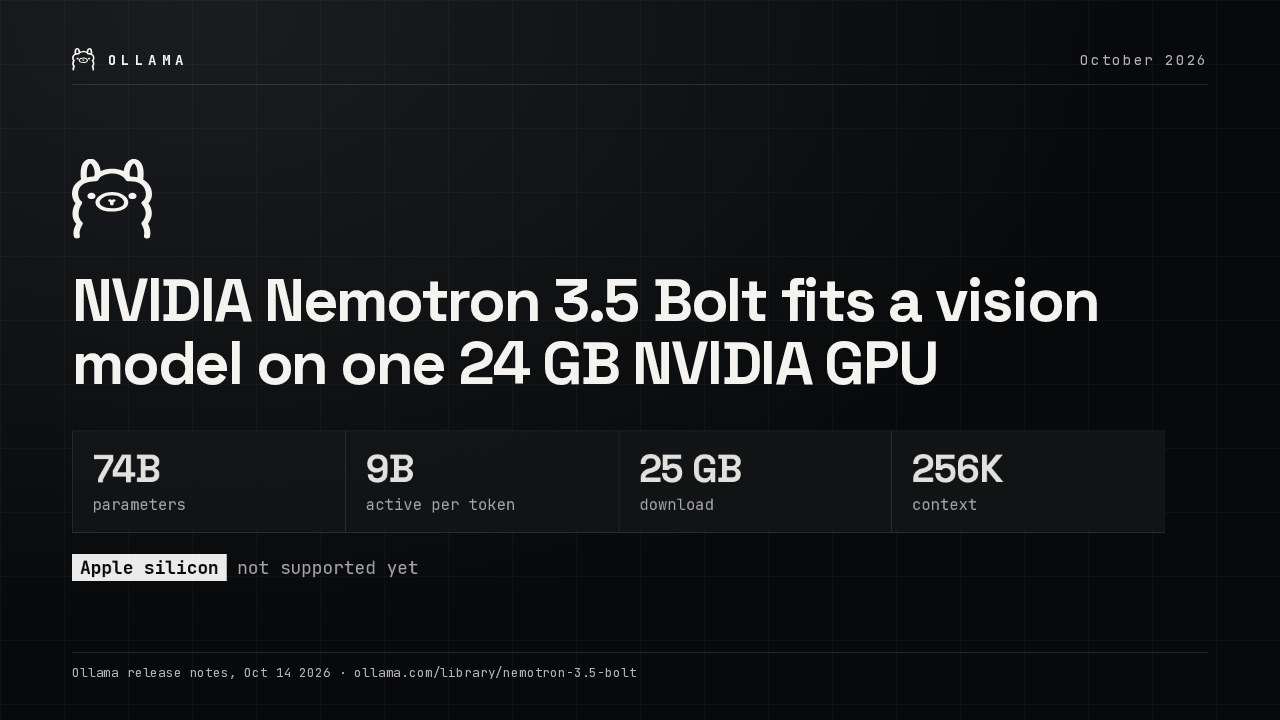
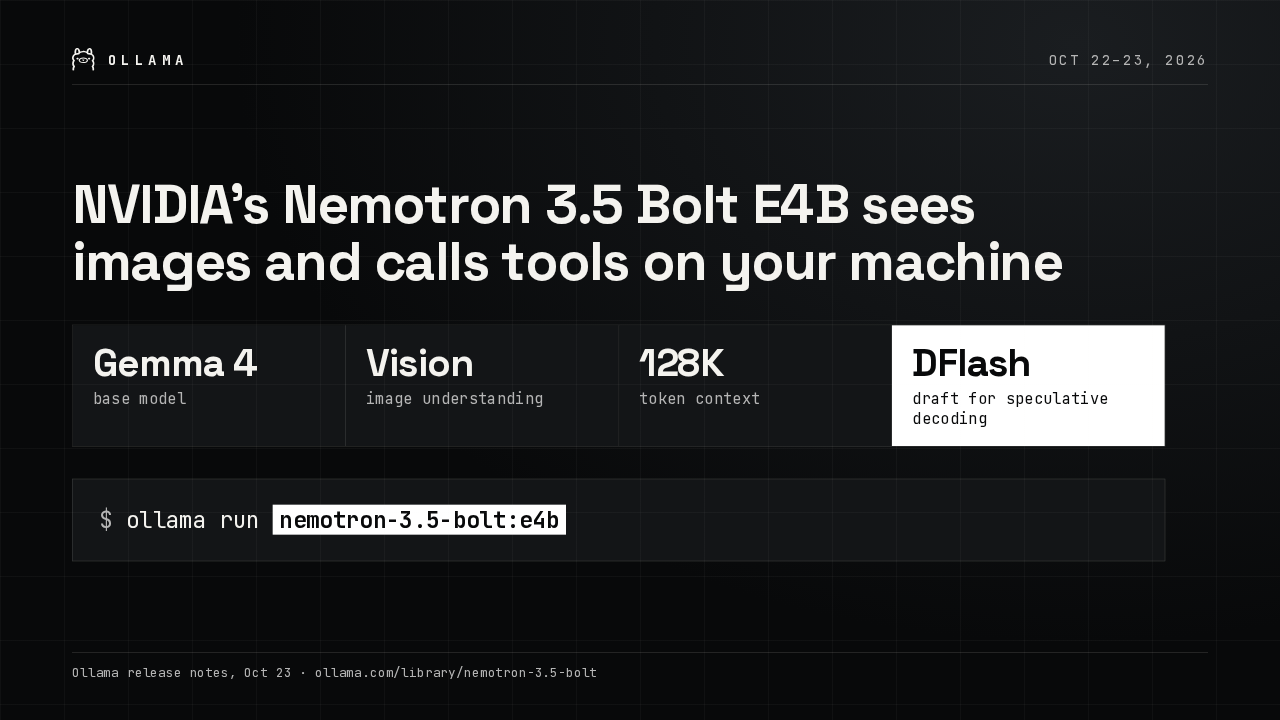
NVIDIA's Nemotron 3.5 Bolt E4B sees images and calls tools on your machine
NVIDIA’s Nemotron 3.5 Bolt E4B sees images and calls tools on your machine
$ ollama run nemotron-3.5-bolt:e4b
NVIDIA's Nemotron 3.5 Bolt E4B is a smaller vision-language model built on Gemma 4, for fast chat, images and tools. It holds 128,000 tokens, and it ships with a DFlash draft model for speculative decoding, which speeds up replies.
Flint now runs on Linux and Windows too
Flint, the coding model from Recursive, ran only on Macs until now. It now runs on Linux and Windows too. And when you turn its thinking off, Flint gives you the answer directly.
Broken streams now say why, and coding tools get the right context
- Streaming replies through the OpenAI Responses and Anthropic Messages APIs report a failure
ollama launchgives Claude Code, Codex and OpenCode each cloud model’s context length- Anthropic-compatible web search keeps a thinking setting the model supports
A streamed reply that fails halfway now ends with an error. Ollama launch gives Claude Code, Codex and OpenCode each cloud model's real context length, so compaction starts on time. And web search handles thinking settings the model lacks.
Which model's answers would you pipe into Phonon?
Which model’s answers would you pipe into Phonon?
On a Mac with Apple Silicon, Phonon is one pull away, and Ollama's speech guide covers the setup. Which model's answers would you pipe into it?