Ollama v0.40.5 runs NVIDIA Nemotron 3.5 Bolt, a 74B vision model sized for one 24 GB GPU

2 hours ago

Ollama v0.40.5 (October 14, 2026) adds NVIDIA Nemotron 3.5 Bolt, a 74B vision model (9B active) tuned for one 24 GB NVIDIA GPU, and Nemotron 3.5 Super, a 120B vision-language model with up to a million tokens of context. On NVIDIA, the MLX runner processes Nemotron prompts about twice as fast. Clef and Clef Flash decision models run on Ollama's cloud, and Responses tool calls and cloud errors are fixed. https://github.com/ollama/ollama/releases/tag/v0.40.5 https://github.com/ollama/ollama/compare/v0.40.4...v0.40.5 https://ollama.com/library/nemotron-3.5-bolt https://ollama.com/library/nemotron-3.5-super

Ask

Ask about this presentation

Answers are generated from this presentation.

Chapters

  1. 0:00Ollama v0.40.5 runs NVIDIA Nemotron 3.5 Bolt, a 74B vision model sized for one 24 GB GPU
  2. 0:14Nemotron 3.5 Super reads images and up to a million tokens
  3. 0:30On NVIDIA, the MLX runner processes Nemotron prompts about twice as fast
  4. 0:48Clef and Clef Flash decision models run on Ollama's cloud
  5. 0:59Fixes for Responses tool calls and cloud errors
Show transcript

Ollama v0.40.5 runs NVIDIA Nemotron 3.5 Bolt, a 74B vision model sized for one 24 GB GPU

Ollama
Ollama
October 2026
Ollama
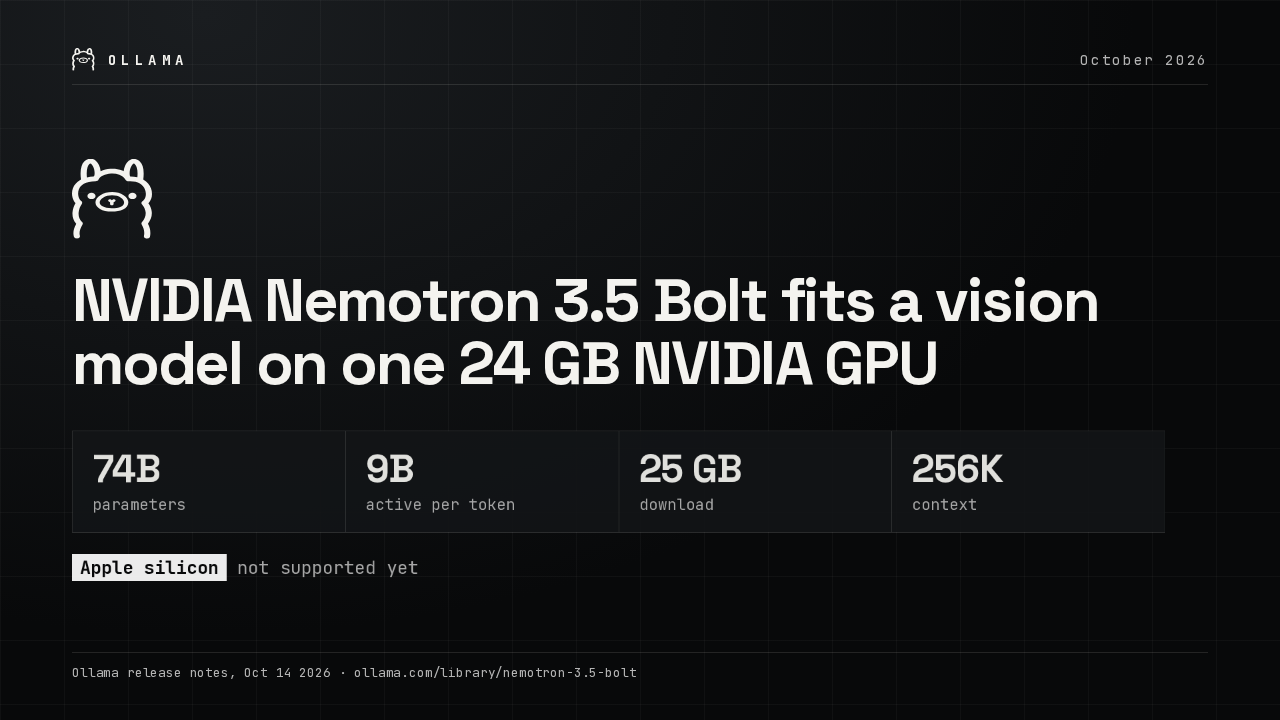
NVIDIA Nemotron 3.5 Bolt fits a vision model on one 24 GB NVIDIA GPU
74Bparameters
9Bactive per token
25 GBdownload
256Kcontext
Apple silicon not supported yet
Ollama release notes, Oct 14 2026 · ollama.com/library/nemotron-3.5-bolt

Ollama now runs NVIDIA Nemotron 3.5 Bolt, a 74 billion parameter vision model tuned to fit one 24 gigabyte NVIDIA card. Mac owners have to wait, because Apple silicon isn't supported yet.

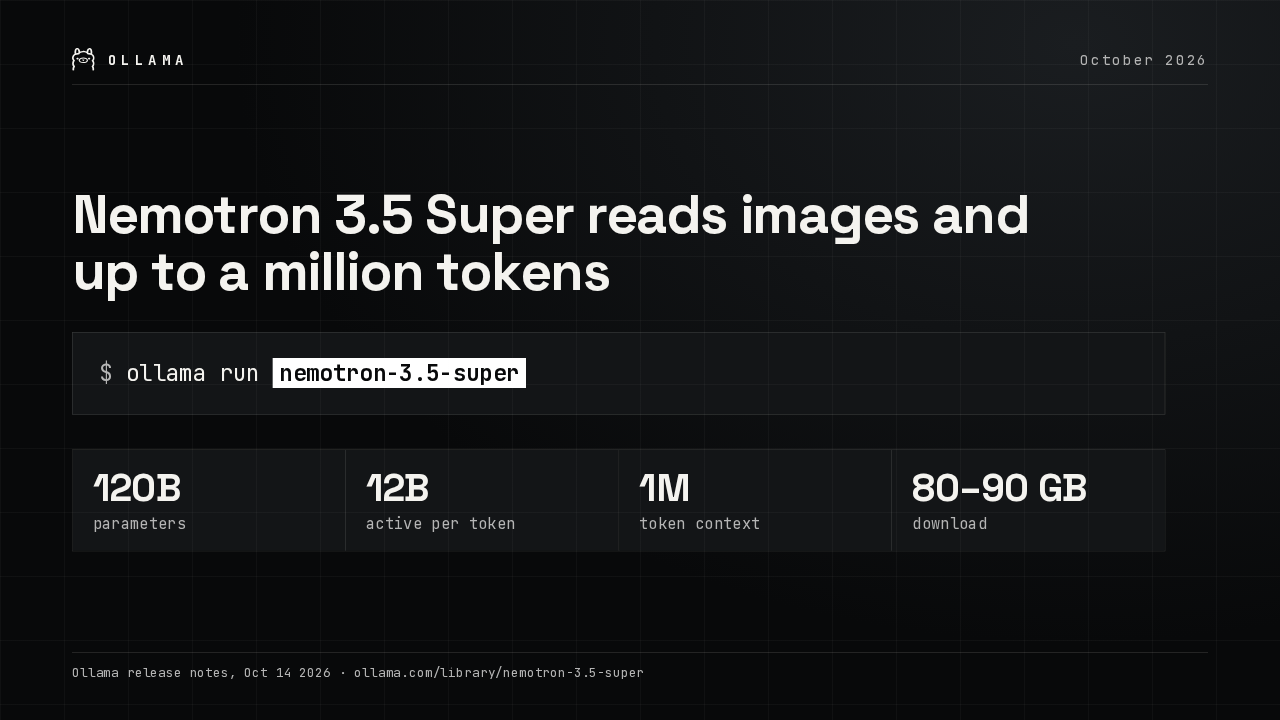
Nemotron 3.5 Super reads images and up to a million tokens

Ollama
Ollama
October 2026
$ ollama run nemotron-3.5-super
120Bparameters
12Bactive per token
1Mtoken context
80–90 GBdownload
Ollama release notes, Oct 14 2026 · ollama.com/library/nemotron-3.5-super

Bolt is distilled from Nemotron 3.5 Super, which has 120 billion parameters. Super reads documents and images, calls tools, and takes up to a million tokens of context, but the download is 80 to 90 gigabytes.

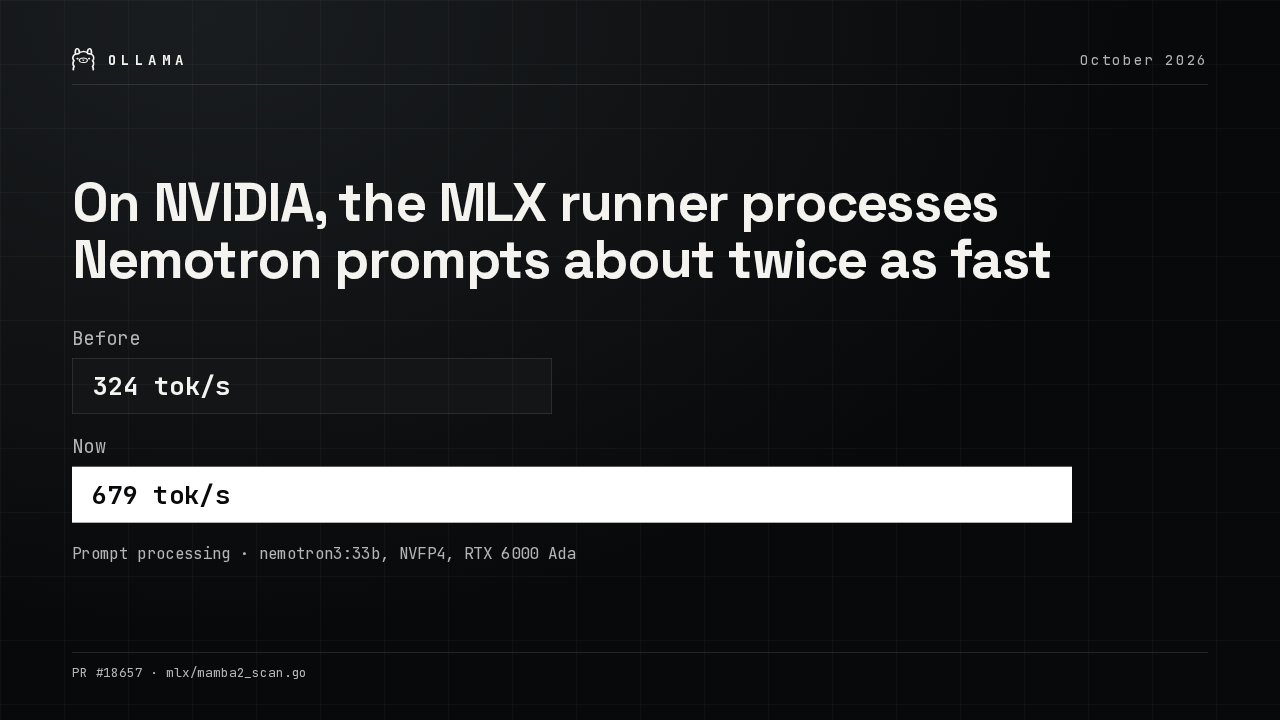
On NVIDIA, the MLX runner processes Nemotron prompts about twice as fast

Ollama
Ollama
October 2026
Before
324 tok/s
Now
679 tok/s
Prompt processing · nemotron3:33b, NVFP4, RTX 6000 Ada
PR #18657 · mlx/mamba2_scan.go

On NVIDIA cards, Ollama's MLX runner now has CUDA kernels for Nemotron's Mamba layers, where it used to fall back to slower generic code. Prompt processing roughly doubles, and generation gets up to a third faster.

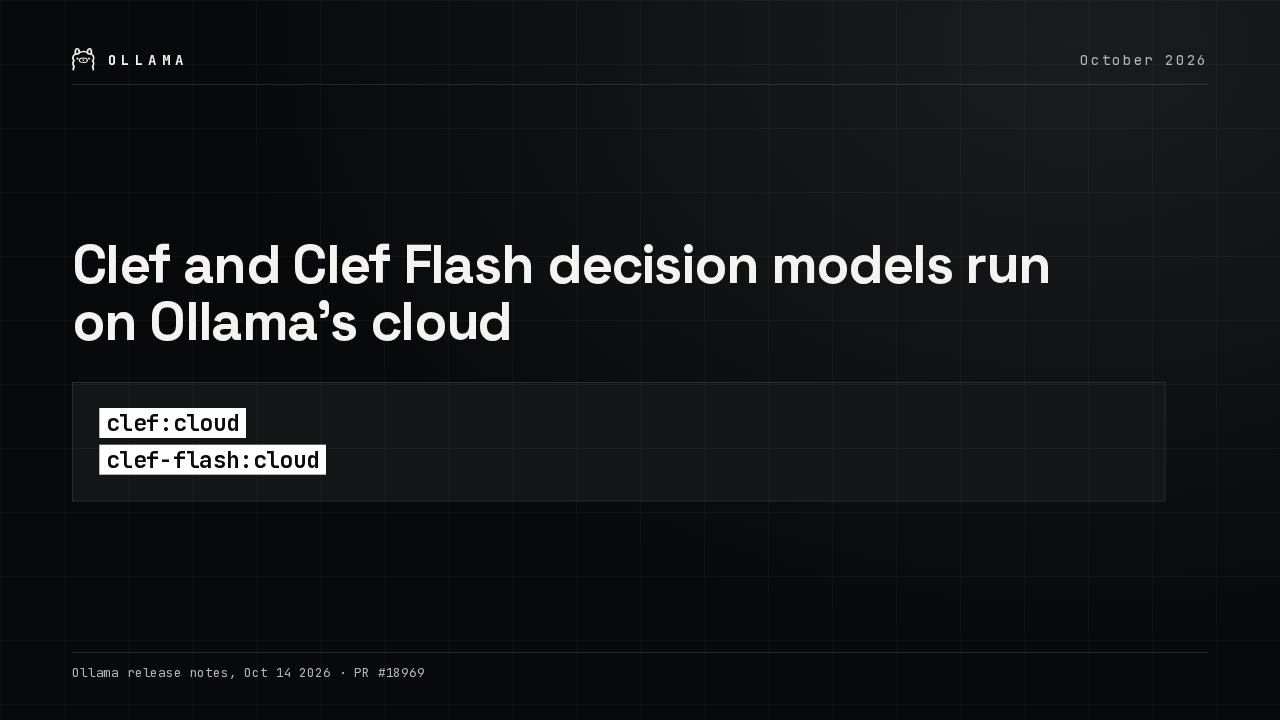
Clef and Clef Flash decision models run on Ollama's cloud

Ollama
Ollama
October 2026

Clef and Clef Flash decision models run on Ollama’s cloud

clef:cloud
clef-flash:cloud
Ollama release notes, Oct 14 2026 · PR #18969

The Clef and Clef Flash decision models now run on Ollama's cloud. Add the cloud tag to either name and the model runs on ollama.com, so your machine skips the download.

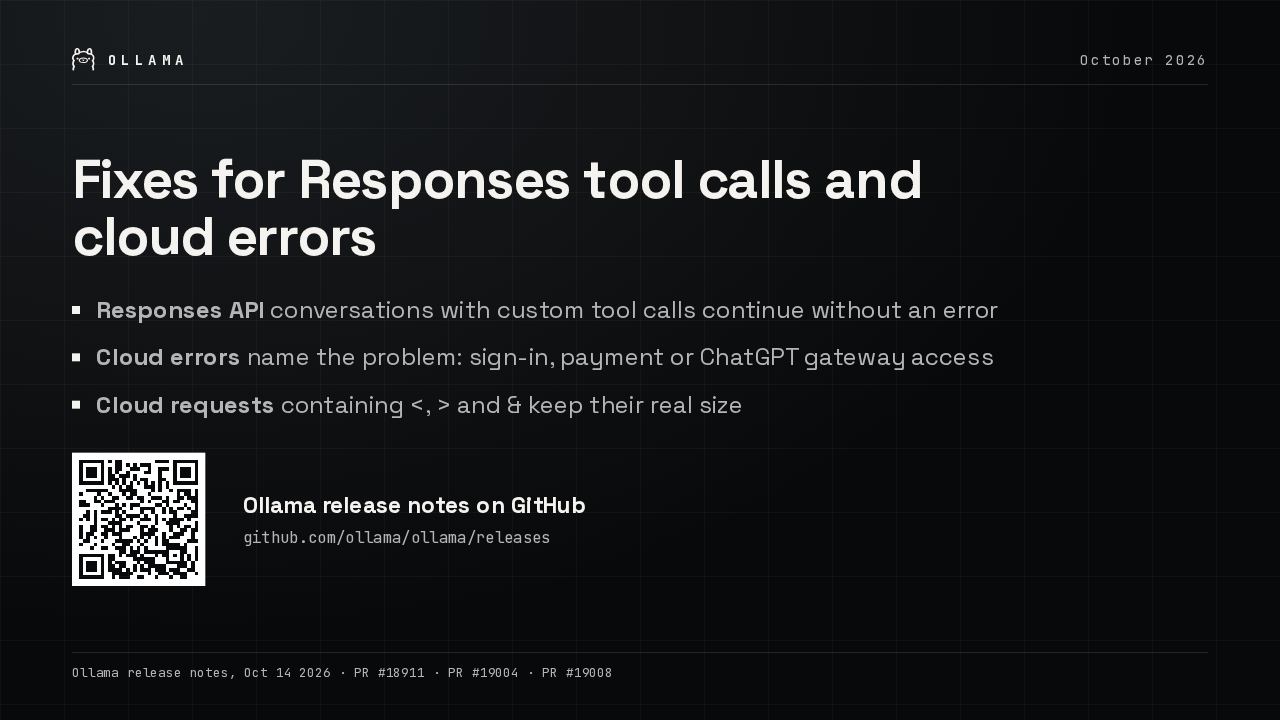
Fixes for Responses tool calls and cloud errors

Ollama
Ollama
October 2026
  • Responses API conversations with custom tool calls continue without an error
  • Cloud errors name the problem: sign-in, payment or ChatGPT gateway access
  • Cloud requests containing <, > and & keep their real size
Ollama release notes on GitHubgithub.com/ollama/ollama/releases
Ollama release notes, Oct 14 2026 · PR #18911 · PR #19004 · PR #19008

Continuing an OpenAI Responses conversation that used custom tool calls no longer fails. Cloud errors now say whether sign-in or payment is the problem. The rest is in Ollama's release notes on GitHub.