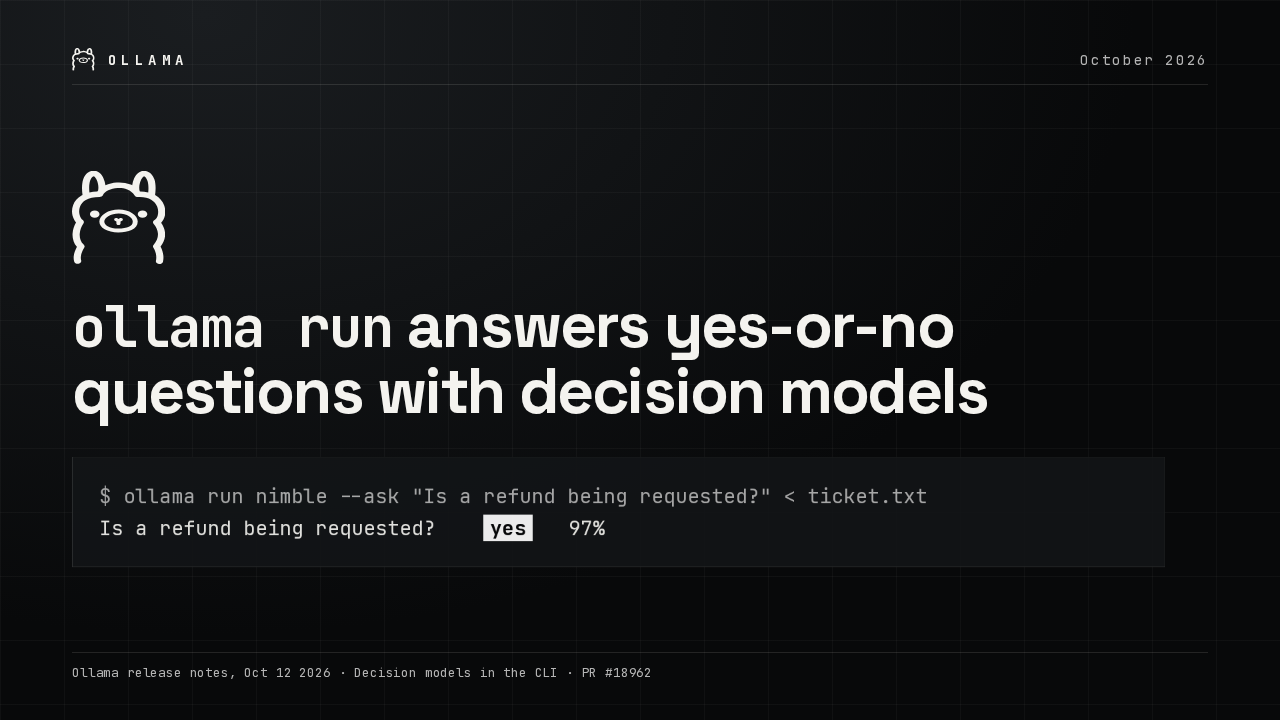
Ollama run now answers yes-or-no questions with decision models

ollama run answers yes-or-no questions with decision models$ ollama run nimble --ask "Is a refund being requested?" < ticket.txt
Is a refund being requested? yes 97%
Ollama run now works with decision models like Nimble, where before it failed outright. Pipe in a support ticket, ask whether a refund is being requested, and it answers yes, with how sure it is.
The same question can pick a label or score a level
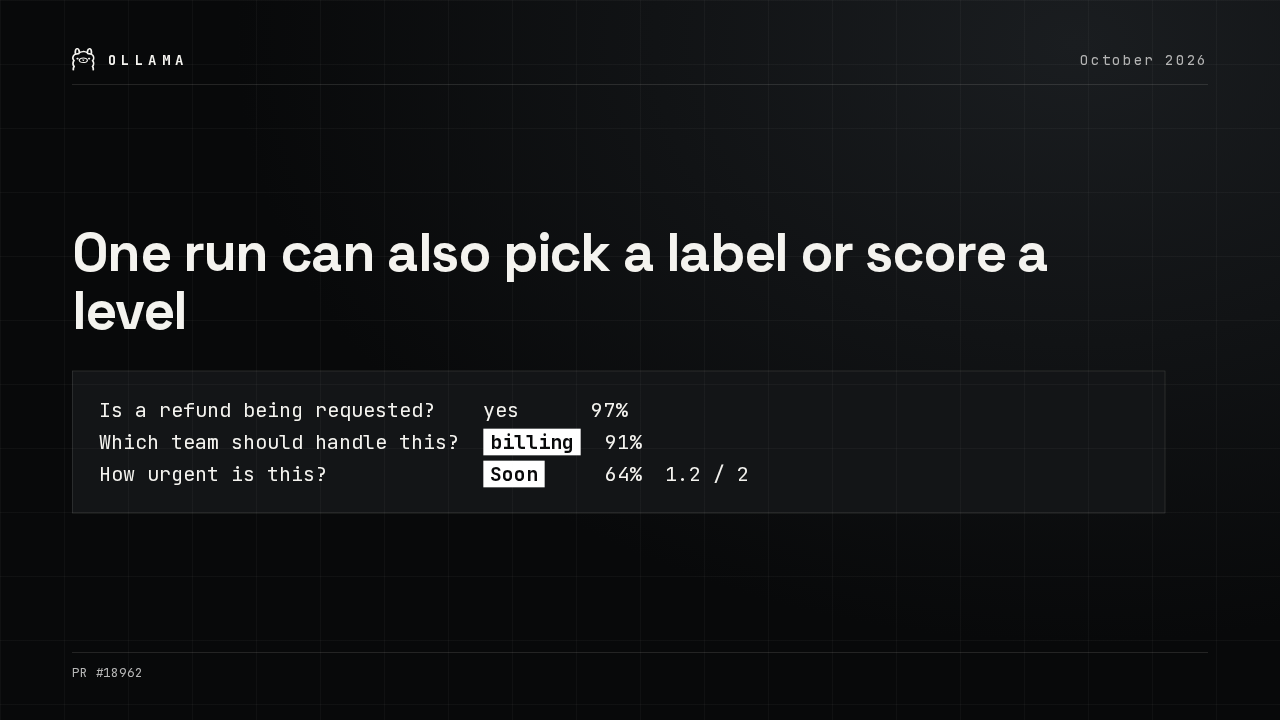
One run can also pick a label or score a level
Is a refund being requested?    yes      97%
Which team should handle this?  billing  91%
How urgent is this?             Soon     64%  1.2 / 2
A question can also choose between labels you name, like billing or technical, or score the text on levels, from routine to immediate. Several questions fit in one run, and each answer prints on its own line.
Kev decision models run on Apple silicon
On a Mac with Apple silicon, Kev decision models now run on Ollama's MLX runner. And the llama.cpp inside Ollama now supports decision models natively.
Background model upgrades are paused
Ollama has paused its background upgrade of models you downloaded with older versions. It added work to every request and slowed heavy embedding workloads. A future release brings it back.
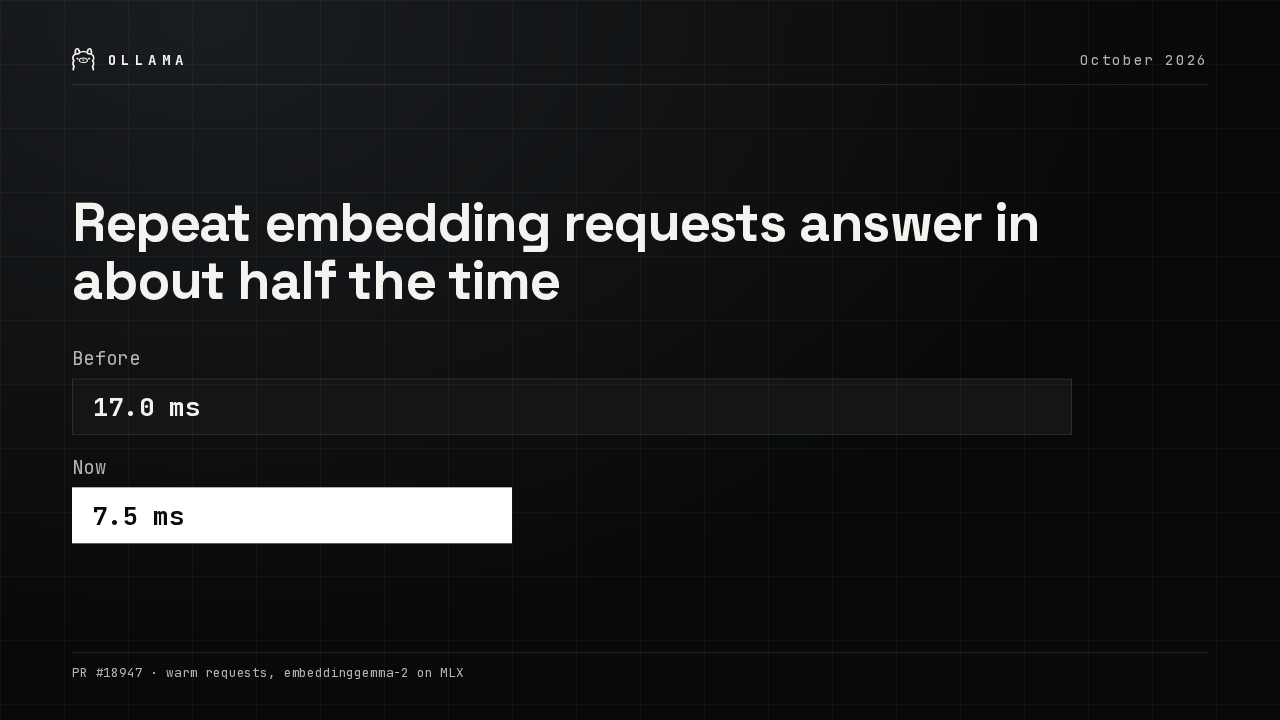
Repeat embedding requests answer in about half the time
When a model is already loaded, Ollama now reuses it instead of looking it up again. A repeat embedding request to Embedding Gemma 2 drops from seventeen milliseconds to about seven and a half.
ollama launch works with more of your models and plans
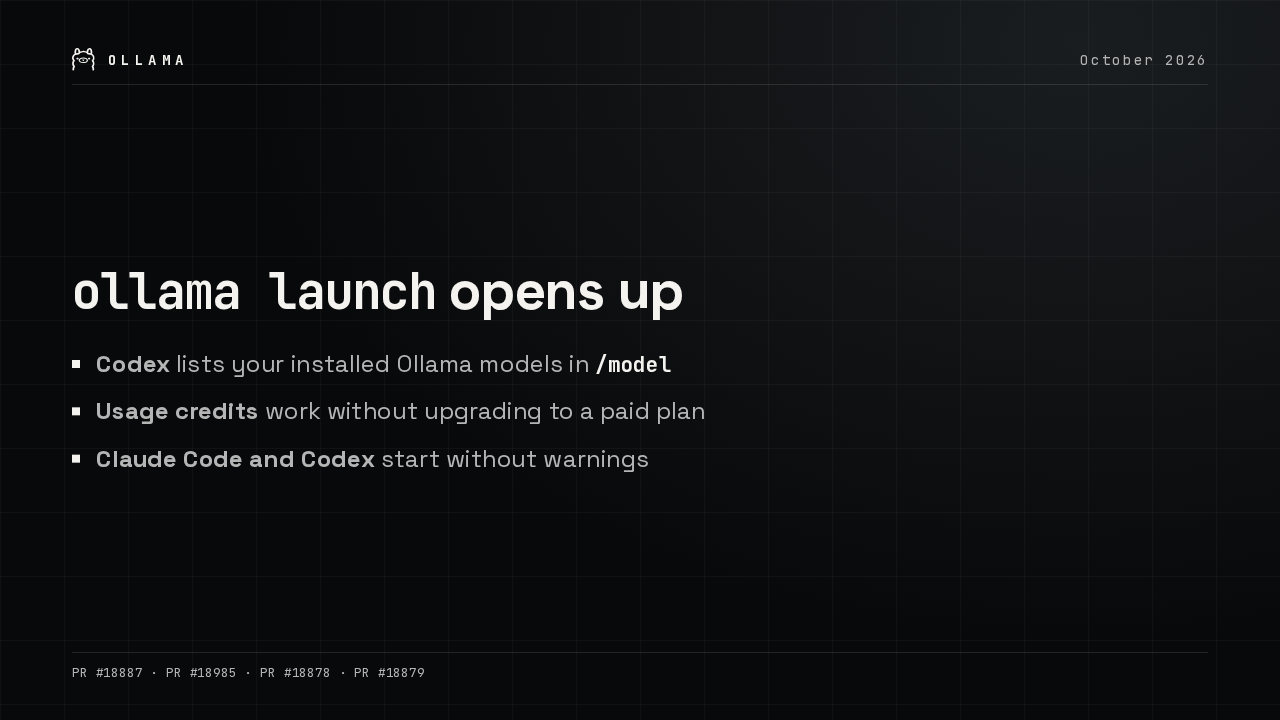
ollama launch opens up
- Codex lists your installed Ollama models in
/model - Usage credits work without upgrading to a paid plan
- Claude Code and Codex start without warnings
Ollama launch Codex now puts your installed local models in Codex's model picker. Launch also works with usage credits without a paid plan, and Claude Code and Codex start without warnings.
Gemma 4 and image embeddings get faster and steadier
Gemma 4 and image embeddings
- Gemma 4 reads prompts 2 to 4× faster on NVIDIA with the MLX runner
- Multimodal embeddings run through llama-server
- Image embedding models load with a small context window
With the MLX runner on NVIDIA, Gemma 4 reads prompts two to four times faster. Image embedding models now run through llama server, and load even with a small context window. The full list is in Ollama's release notes on GitHub.