Same sticker, a bigger invoice
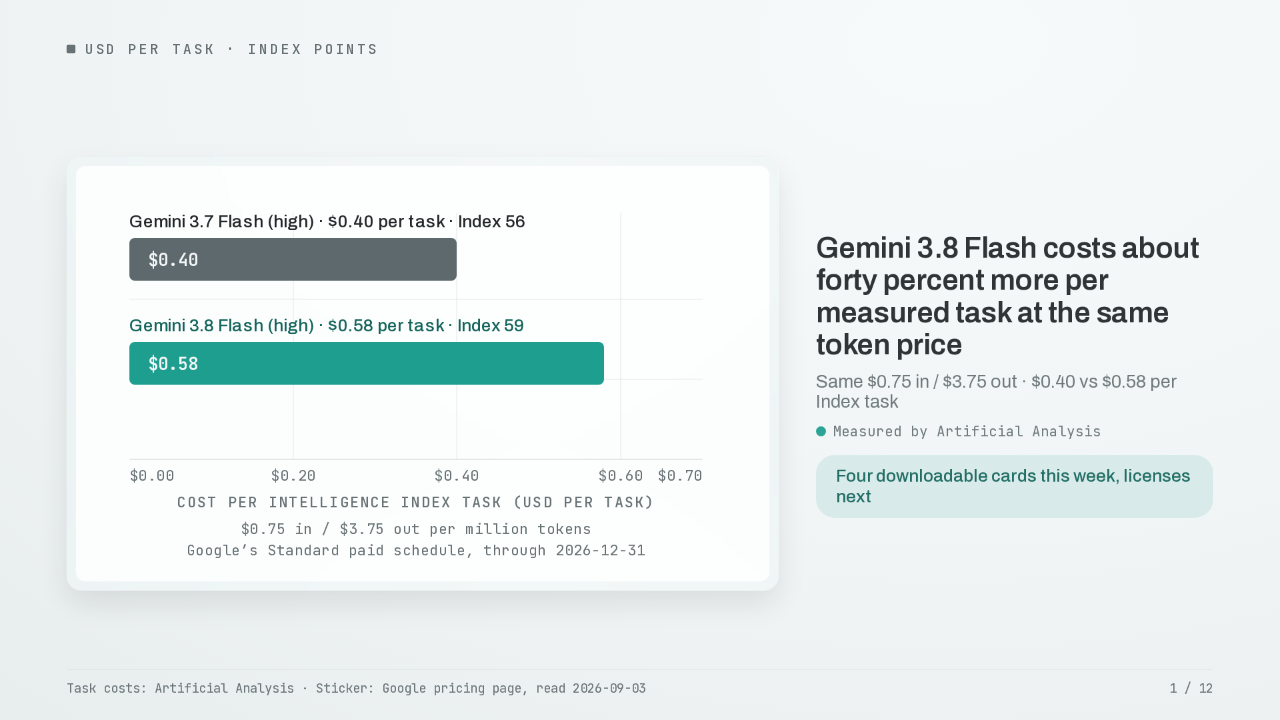
Gemini 3.8 Flash costs about forty percent more per measured task at the same token price
Same $0.75 in / $3.75 out · $0.40 vs $0.58 per Index task
Same sticker. A bigger invoice. Gemini 3.8 Flash is the model that did that. Artificial Analysis billed fifty-eight cents per Intelligence Index task for Gemini 3.8 Flash on high, against forty cents for Gemini 3.7 Flash on high. Cost per Index task is what Artificial Analysis billed to finish one of those tests. The Intelligence Index is a single score Artificial Analysis builds by running the same tests on every model themselves. Gemini 3.8 Flash scores fifty-nine on that index. Gemini 3.7 Flash scores fifty-six on that index. Google lists both at seventy-five cents per million input tokens, the text you send, and three dollars seventy-five per million output tokens, the text the model writes back.
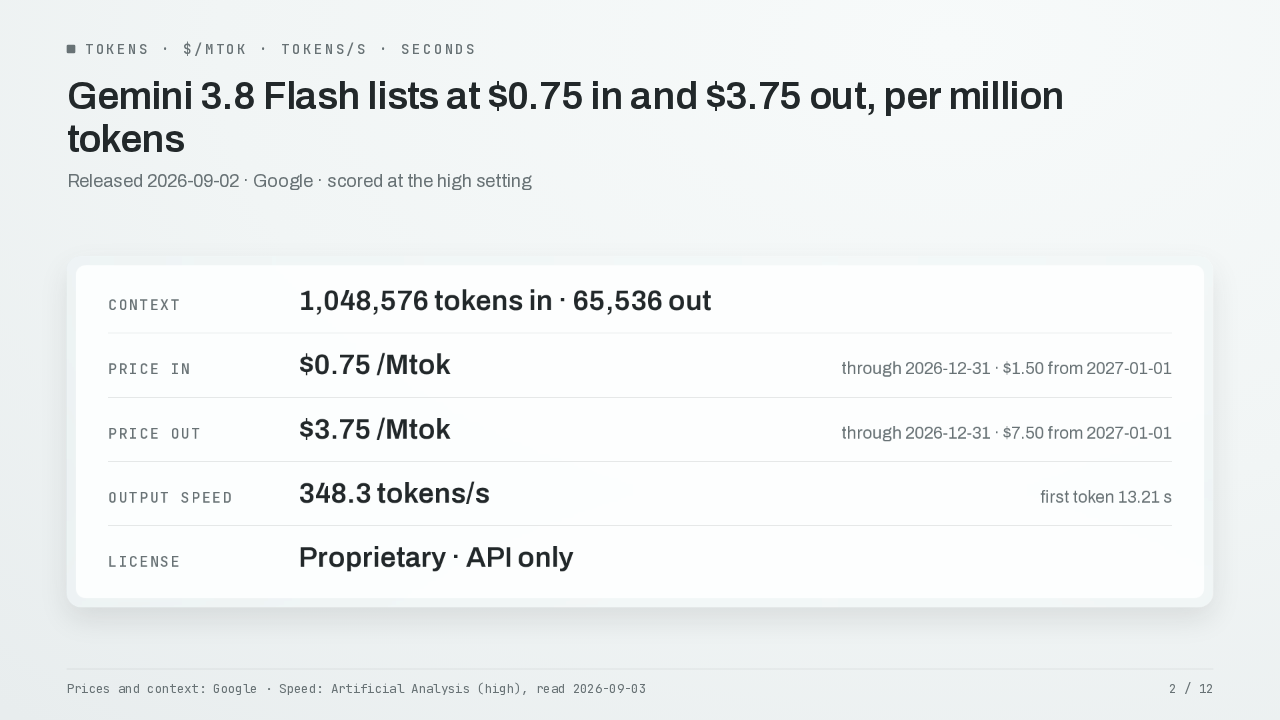
Gemini 3.8 Flash spec card
Gemini 3.8 Flash lists at $0.75 in and $3.75 out, per million tokens
Released 2026-09-02 · Google · scored at the high setting
You can hand Gemini 3.8 Flash about a million tokens at once. Artificial Analysis clocks Gemini 3.8 Flash on high at about three hundred and forty-eight tokens a second. That is how fast the words come out once Gemini 3.8 Flash starts. The wait before the first word is about thirteen seconds. Google does not publish the model itself. Gemini has no license field to read.
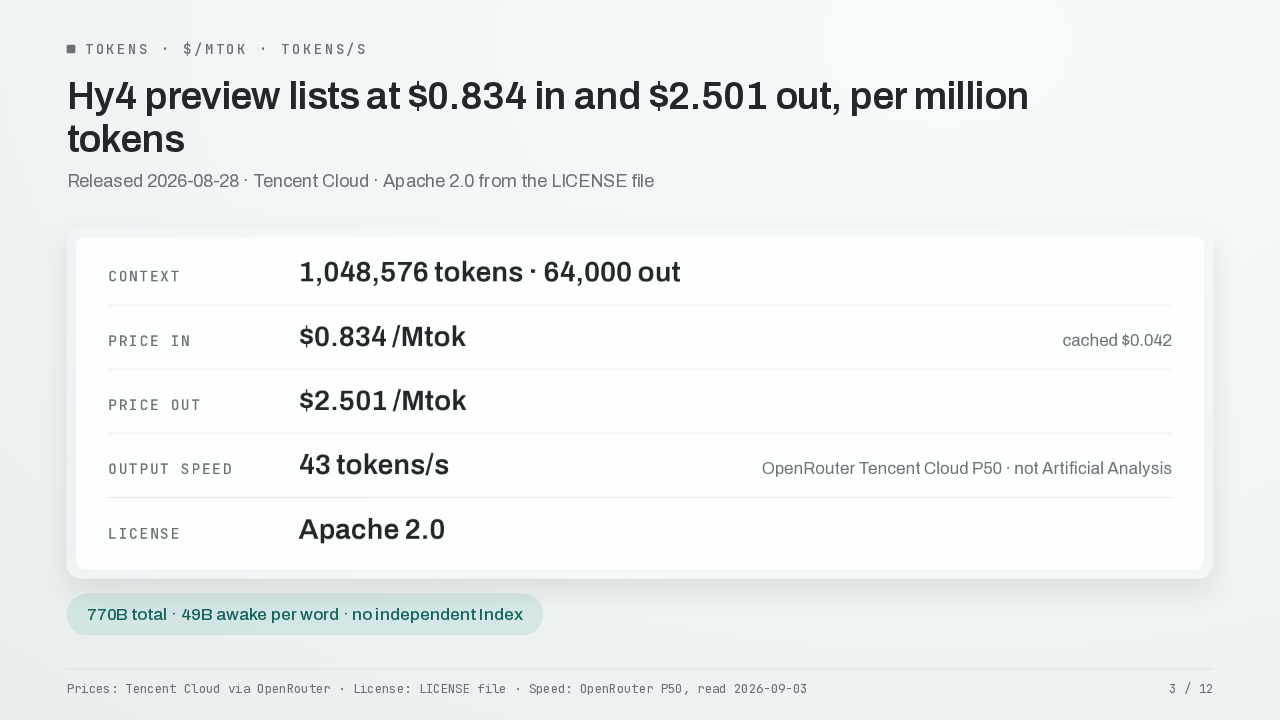
Hy4 preview spec card
Hy4 preview lists at $0.834 in and $2.501 out, per million tokens
Released 2026-08-28 · Tencent Cloud · Apache 2.0 from the LICENSE file
Tencent Cloud lists Hy4 preview at eighty-three point four cents per million input tokens, two point five zero one dollars per million output tokens, and four point two cents cached. OpenRouter clocks Tencent Cloud at forty-three tokens a second. That figure is OpenRouter’s median. The LICENSE file reads Apache 2.0.
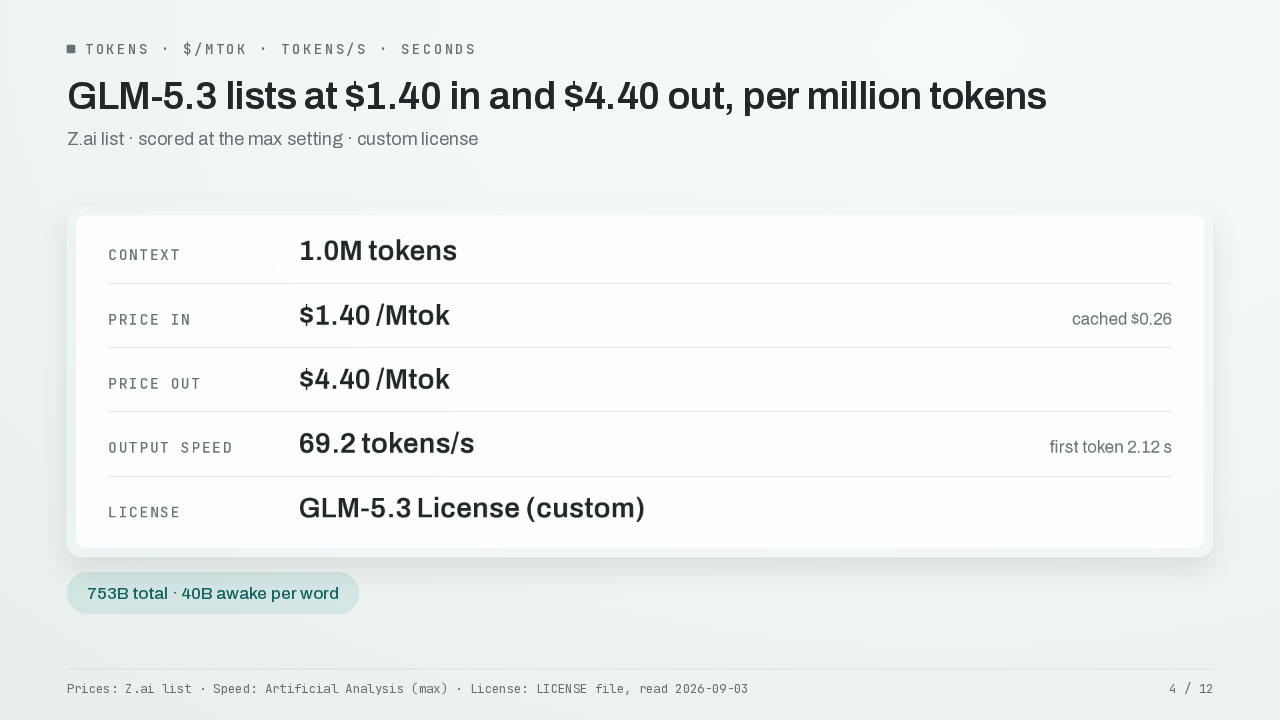
GLM-5.3 spec card
GLM-5.3 lists at $1.40 in and $4.40 out, per million tokens
Z.ai list · scored at the max setting · custom license
Z.ai lists GLM-5.3 at a dollar forty per million input tokens and four dollars forty per million output tokens. Artificial Analysis clocks GLM-5.3 on max at about sixty-nine tokens a second. The LICENSE file is a custom grant Z.AI wrote.
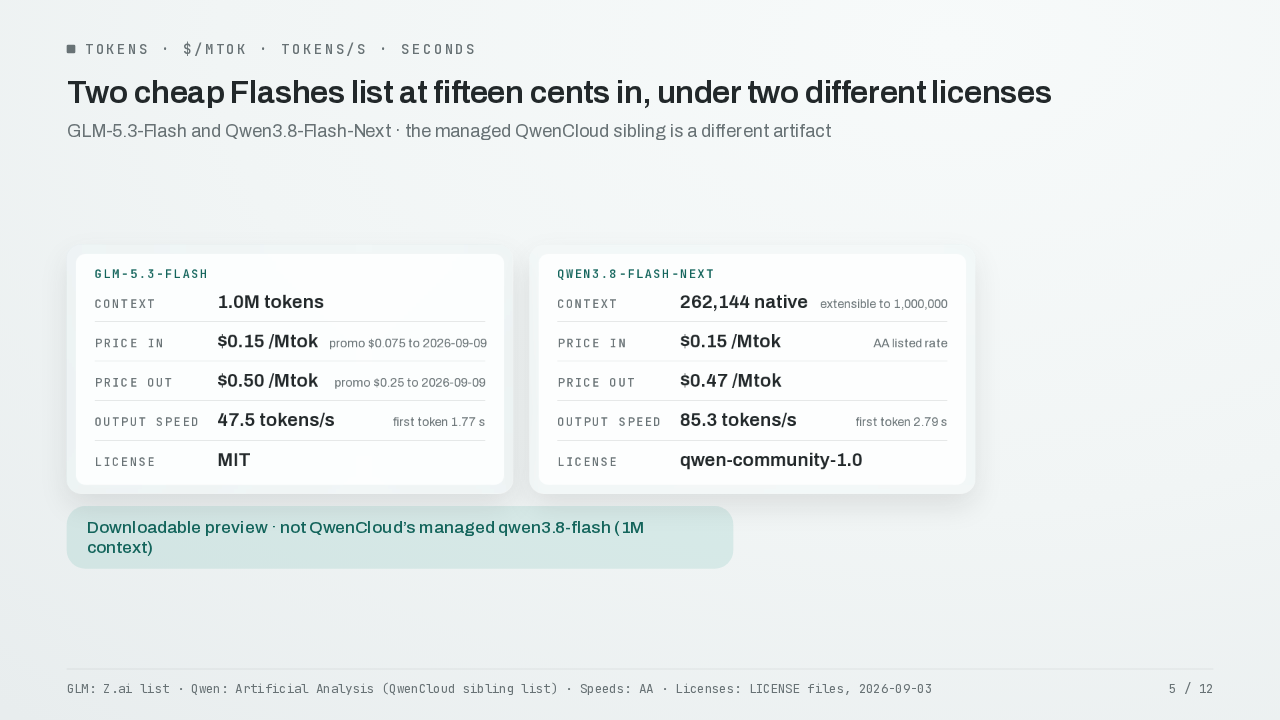
Two cheap Flashes
Two cheap Flashes list at fifteen cents in, under two different licenses
GLM-5.3-Flash and Qwen3.8-Flash-Next · the managed QwenCloud sibling is a different artifact
Z.ai lists GLM-5.3-Flash at fifteen cents in and fifty cents out, per million tokens, with a half-price promo through September ninth. The LICENSE file reads MIT. Qwen3.8-Flash-Next is the downloadable preview. QwenCloud’s managed sibling is a different artifact with a one-million-token window. Artificial Analysis lists the preview at fifteen cents in and forty-seven cents out. The license field reads Qwen community one point zero.
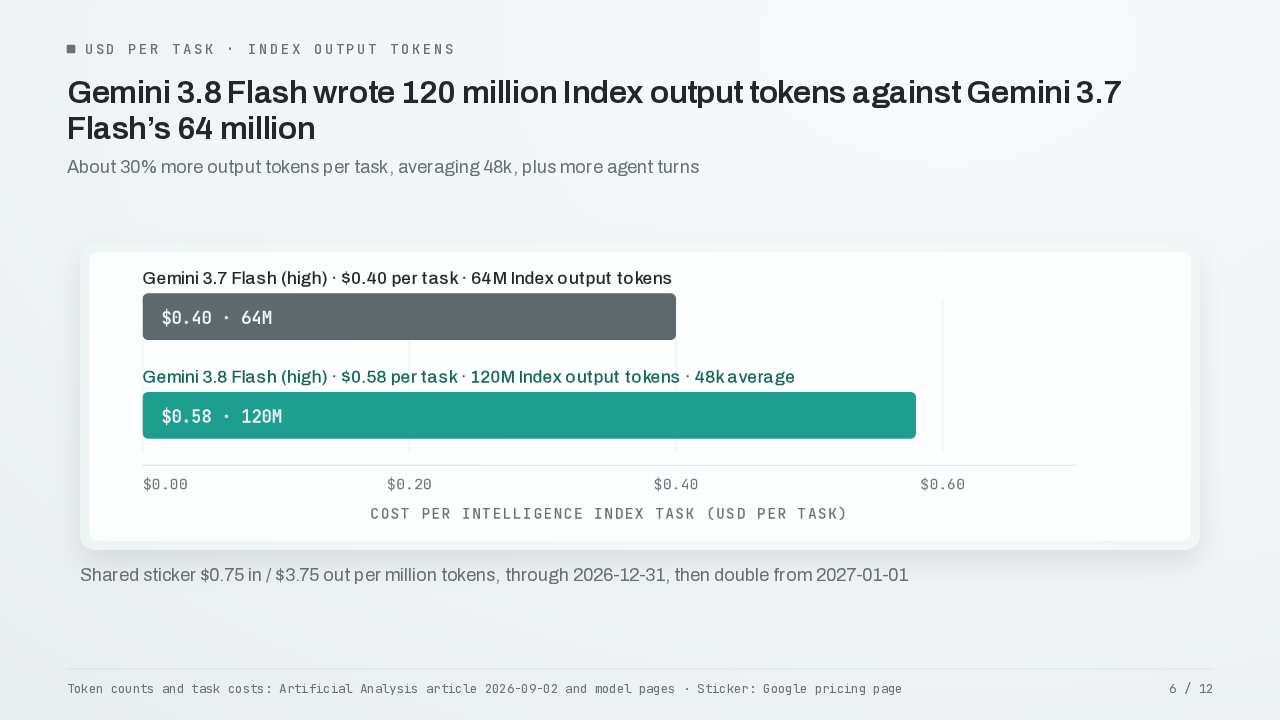
120 million vs 64 million
Gemini 3.8 Flash wrote 120 million Index output tokens against Gemini 3.7 Flash’s 64 million
About 30% more output tokens per task, averaging 48k, plus more agent turns
Shared sticker $0.75 in / $3.75 out per million tokens, through 2026-12-31, then double from 2027-01-01
Google’s Standard paid schedule for both Flashes doubles on January first, twenty twenty-seven. Artificial Analysis counted about thirty percent more output tokens per Index task on Gemini 3.8 Flash, averaging forty-eight thousand output tokens per task, plus more turns on agent tests. Across the whole Index, Gemini 3.8 Flash wrote a hundred and twenty million output tokens. Gemini 3.7 Flash wrote sixty-four million. The thirty percent is the average per task. The hundred and twenty million is the Index total.
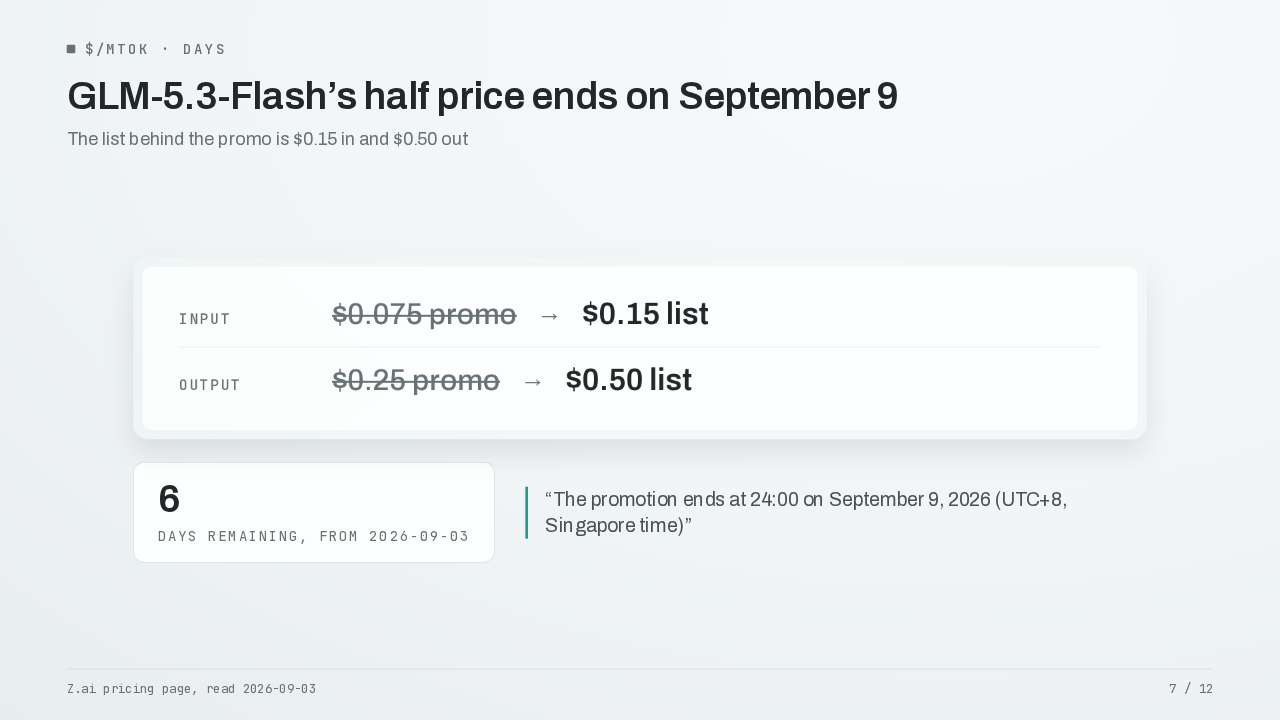
The half price ends September 9
GLM-5.3-Flash’s half price ends on September 9
The list behind the promo is $0.15 in and $0.50 out
“The promotion ends at 24:00 on September 9, 2026 (UTC+8, Singapore time)”
Z.ai’s page sets GLM-5.3-Flash’s launch promotion at seven and a half cents per million input tokens and twenty-five cents per million output tokens, ending at midnight on September ninth, Singapore time, six days from today. Budget on the list behind it: fifteen cents in, fifty cents out, per million tokens.
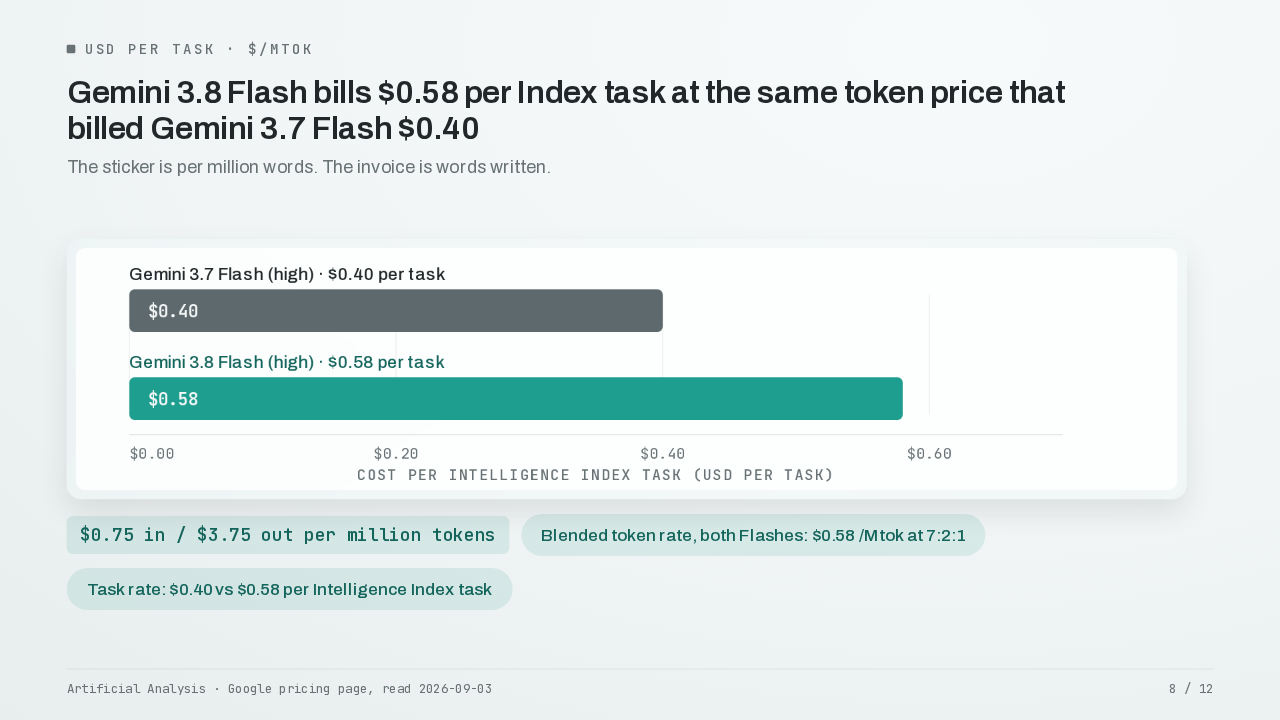
You pay for tokens written
Gemini 3.8 Flash bills $0.58 per Index task at the same token price that billed Gemini 3.7 Flash $0.40
The sticker is per million words. The invoice is words written.
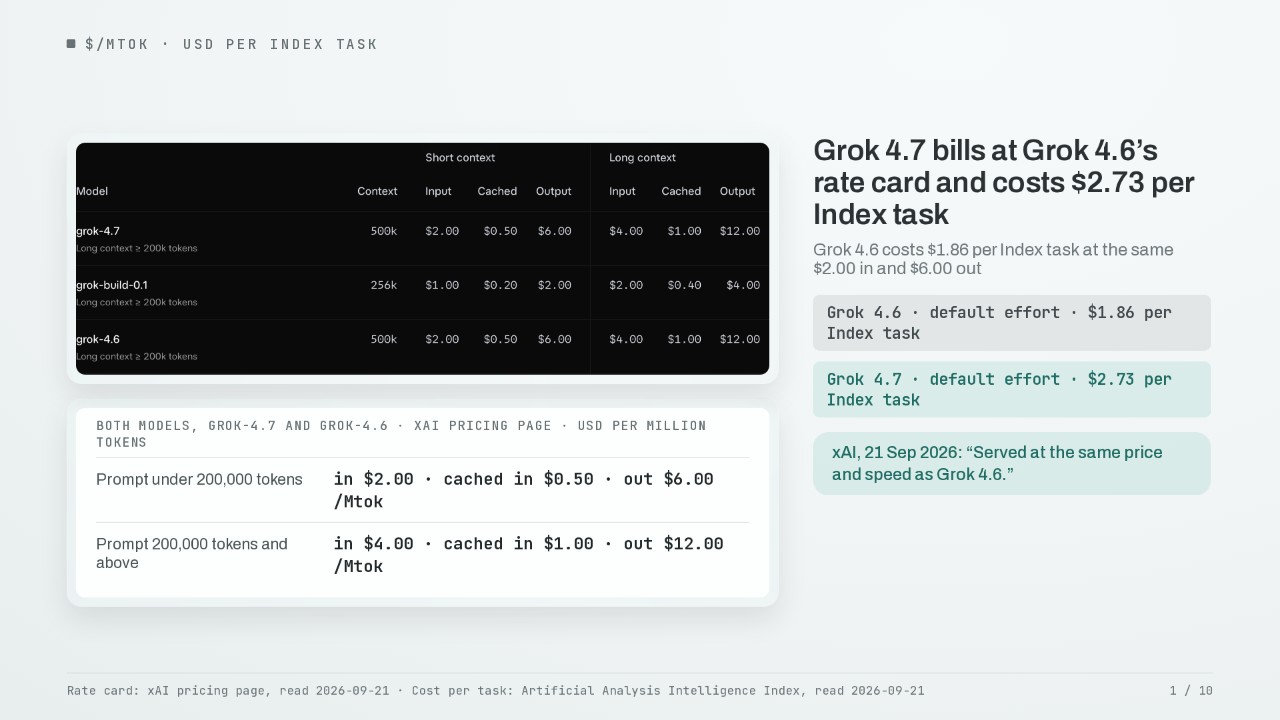
The sticker is a price per million words. The invoice is how many words get written. Google still lists seventy-five cents in and three dollars seventy-five out for both Flashes. Artificial Analysis’s blended token rate is also the same: fifty-eight cents per million tokens for both. A blended price is one dollar figure standing in for a mixed bill: seven parts prompt text the model has already seen, two parts new prompt, one part what it writes back. The task rate is a different number. Artificial Analysis billed fifty-eight cents per Intelligence Index task for Gemini 3.8 Flash on high, against forty cents for Gemini 3.7 Flash on high. Gemini 3.8 Flash wrote more output tokens and took more agent turns on the same tests. A list price that stays put still raises the invoice when the model writes more.
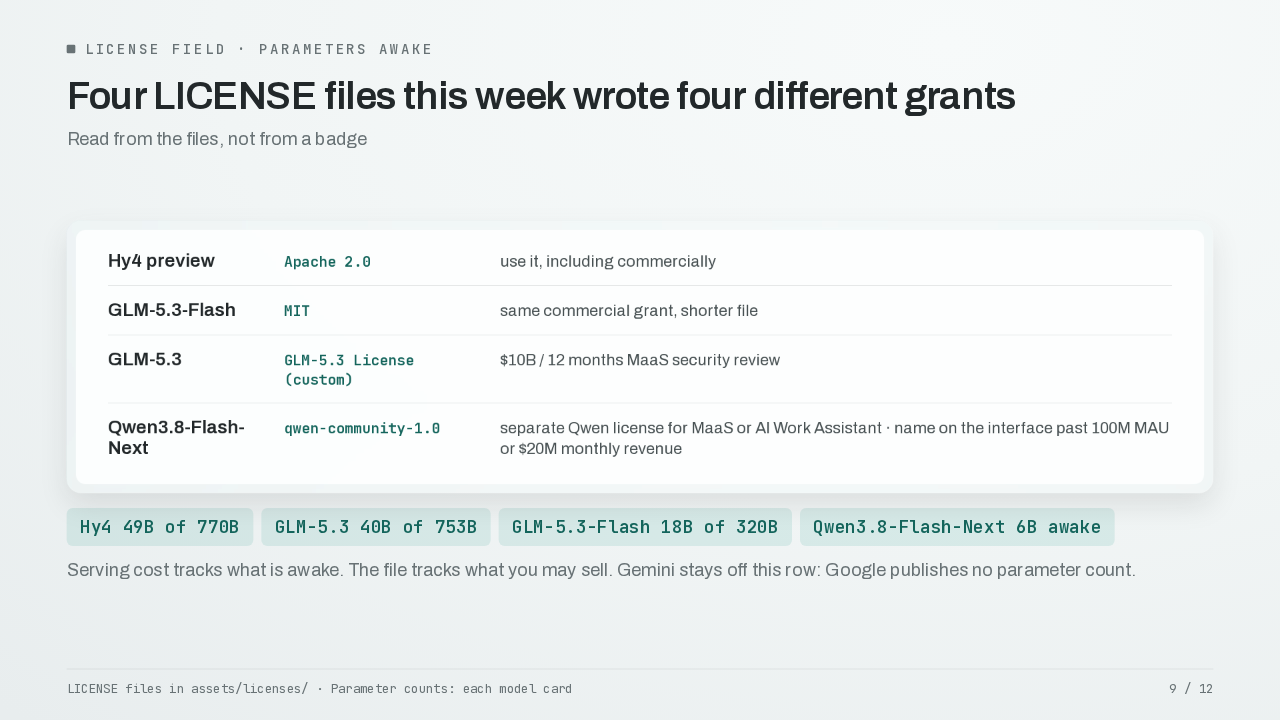
Four LICENSE files, four grants
Four LICENSE files this week wrote four different grants
Read from the files, not from a badge
Serving cost tracks what is awake. The file tracks what you may sell. Gemini stays off this row: Google publishes no parameter count.
A license is a second price. Four files, four grants. Hy4’s LICENSE file is Apache 2.0: use it, including commercially. GLM-5.3-Flash’s file is MIT: the same commercial grant. GLM-5.3 is a custom grant. If you sell GLM-5.3 as a service, and the firm plus affiliates cleared ten billion dollars in any twelve months, you need Z.AI’s security review before commercial use. Products with the model embedded in a feature sit outside that gate. Qwen3.8-Flash-Next’s field is Qwen community one point zero. Selling it as a service or as an AI work assistant needs a separate license from Qwen. Past a hundred million monthly users or twenty million dollars monthly revenue, the model name has to sit on the interface. Serving cost tracks what is awake. The file tracks what you may sell.
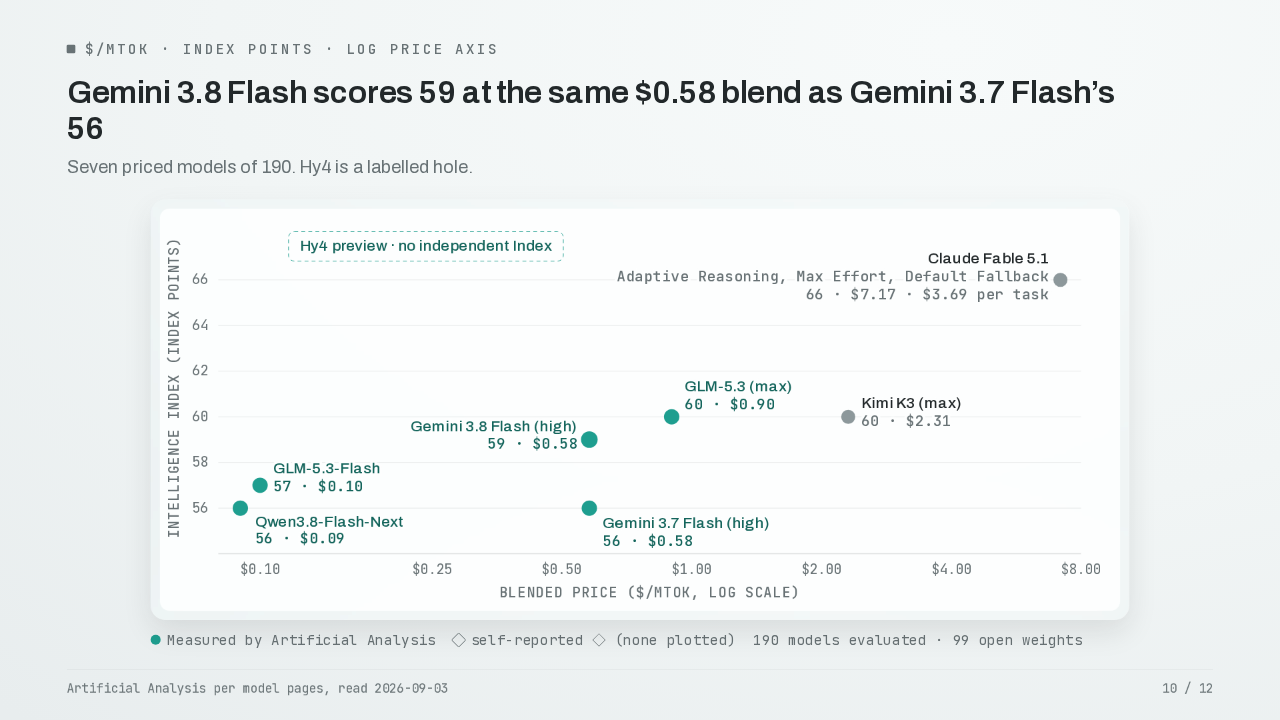
Seven priced models of 190
Gemini 3.8 Flash scores 59 at the same $0.58 blend as Gemini 3.7 Flash’s 56
Seven priced models of 190. Hy4 is a labelled hole.
The cheap corner is GLM-5.3-Flash at fifty-seven points and ten cents blended. Qwen3.8-Flash-Next sits at fifty-six points and nine cents blended. Gemini 3.8 Flash, on high, sits at fifty-nine points and fifty-eight cents blended, straight above Gemini 3.7 Flash on high at fifty-six points and the same blend. Kimi K3 on max is the highest scoring model whose files you can download and run yourself: sixty points and two dollars thirty-one. Claude Fable 5.1, Adaptive Reasoning, Max Effort, Default Fallback, leads at sixty-six points and seven dollars seventeen blended. Hy4 preview has no independent Index. Artificial Analysis’s Hy4 page was empty on September third.
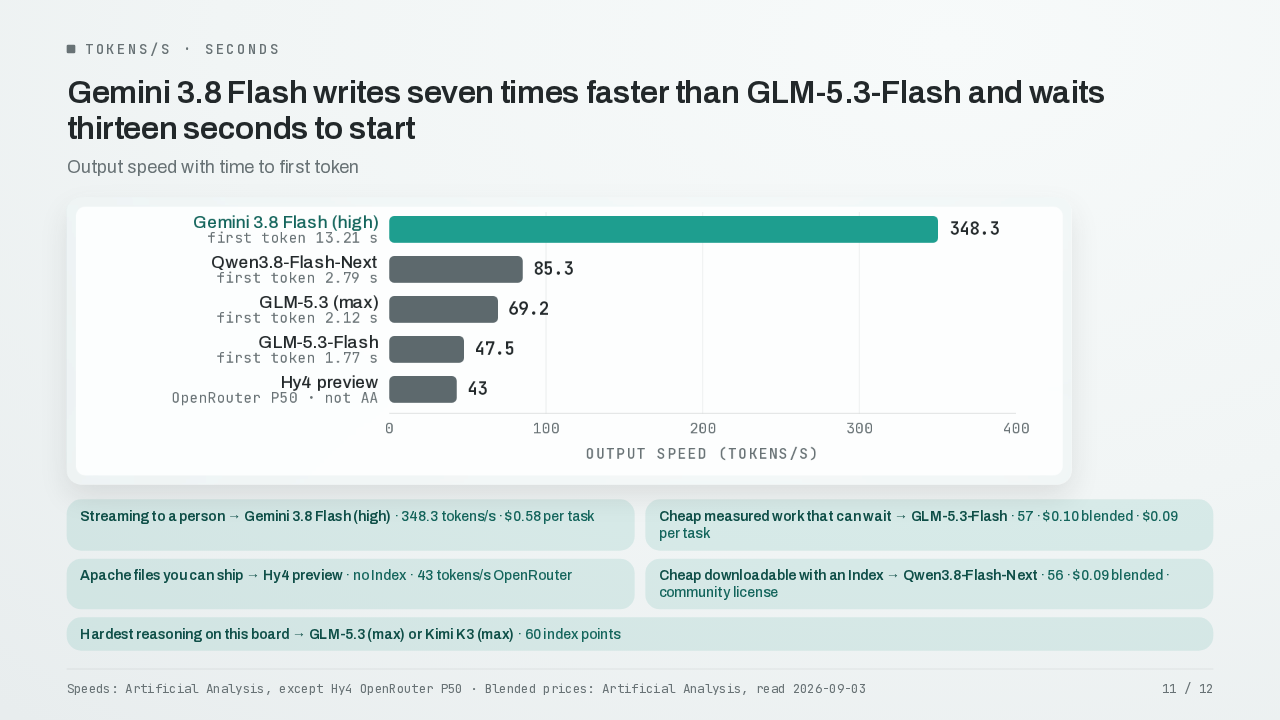
Seven times faster, thirteen seconds to start
Gemini 3.8 Flash writes seven times faster than GLM-5.3-Flash and waits thirteen seconds to start
Output speed with time to first token
For work a person watches stream, run Gemini 3.8 Flash on high at about three hundred and forty-eight tokens a second, Index fifty-nine, fifty-eight cents per Index task. Gemini waits about thirteen seconds before the first word. For cheap measured work that can wait, run GLM-5.3-Flash at fifty-seven on the Index, ten cents blended, nine cents per Index task. For Apache files you can ship, Hy4 is the grant, with no independent Index and forty-three tokens a second on Tencent Cloud. Qwen3.8-Flash-Next sits at fifty-six points and nine cents blended, under the community grant. For the hardest reasoning on this board, GLM-5.3 on max and Kimi K3 on max both sit at sixty points.
Tokens written, and the grant in the file
You pay for tokens written, and for whichever grant is in the file
The sticker stayed put. Four LICENSE files wrote four grants.
Google kept the token price. The invoice still rose. Four LICENSE files wrote four different grants. Pay the score, the tokens written, and the file.