Coding agents and renamed repositories

Coding agents solve fewer SWE-bench issues once a repository's names are changed
Silin Chen, Yufei Yang, Xiaodong Gu and colleagues · Shanghai Jiao Tong University, Xi'an Jiaotong University, East China Normal University
SWE-bench Verified is the score AI coding tools quote to show they can fix real bugs. A team from Shanghai Jiao Tong University and two other universities changed how the code inside it looks, kept its behaviour identical, and ran four models again. Every model solved fewer issues. Their paper, Schrödinger's Code Repository, went up on arXiv on August 21st.
What SWE-bench Verified is
500 real bugs from popular Python projects
The benchmark is 500 real issues from popular open-source Python projects. An agent gets the issue and the code, makes a fix, and the project's own tests decide whether it worked. The catch is that these projects are public and famous. Django is one of them, and their code, issues and fixes can end up in a model's training data.
Models recalled the fixes
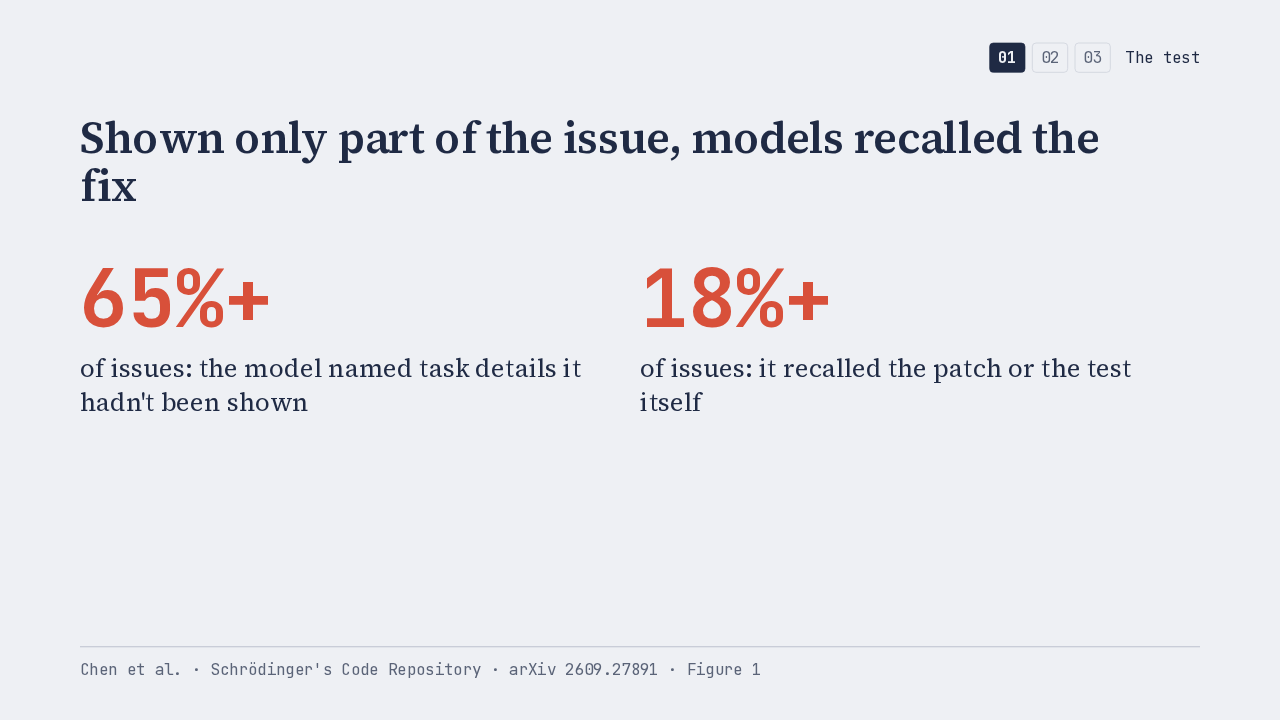
Shown only part of the issue, models recalled the fix
Before changing anything, the authors checked what the models already remembered. Reviewers gave each model the issue's ID and a few details from it, with no code, and compared its answers to the real fix. For every model, about two thirds of the issues showed it knew details it hadn't been shown. For about one in five, it recalled the patch or the test itself.
The test
So the authors built a way to take that familiarity away.
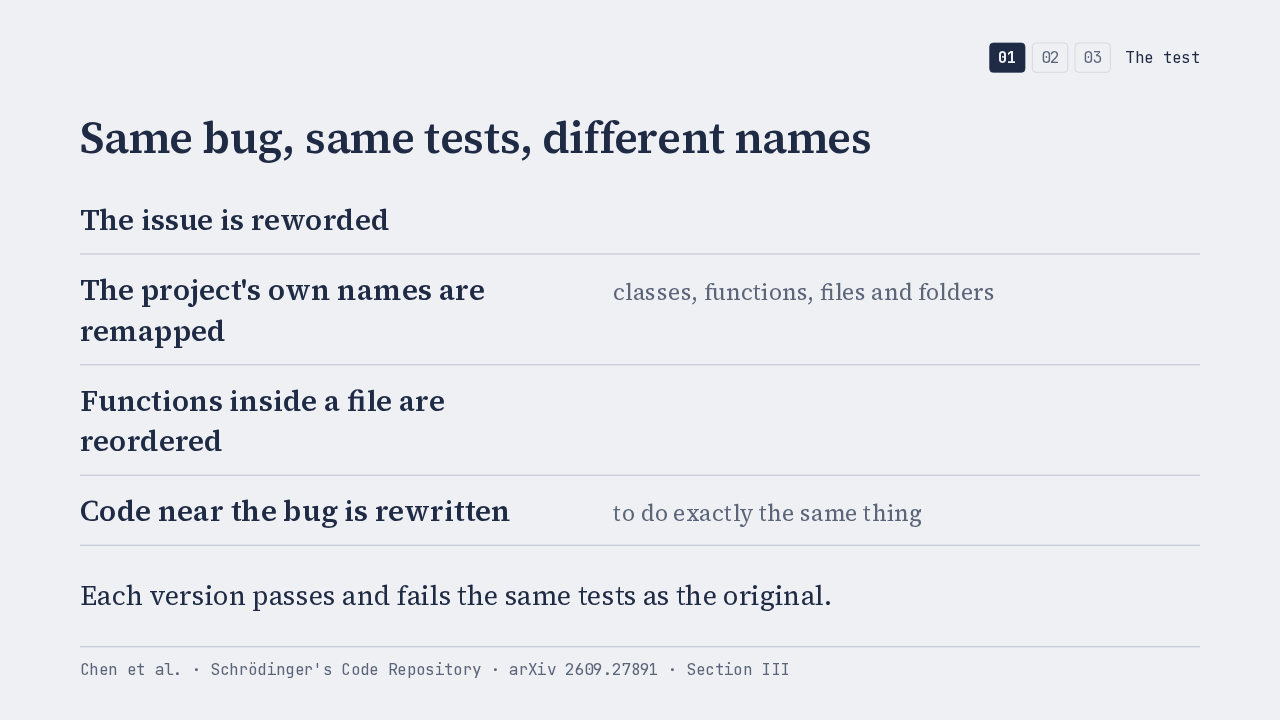
Same bug, same tests, different names
Each version passes and fails the same tests as the original.
Their tool, SchrodingerRepo, builds a fresh copy of each repository whenever an agent starts. It rewords the issue, renames the project's own classes, functions and files, reorders the functions inside a file, and rewrites the code around the bug. Each version is checked against the project's tests, so the bug and the correct fix stay exactly the same.
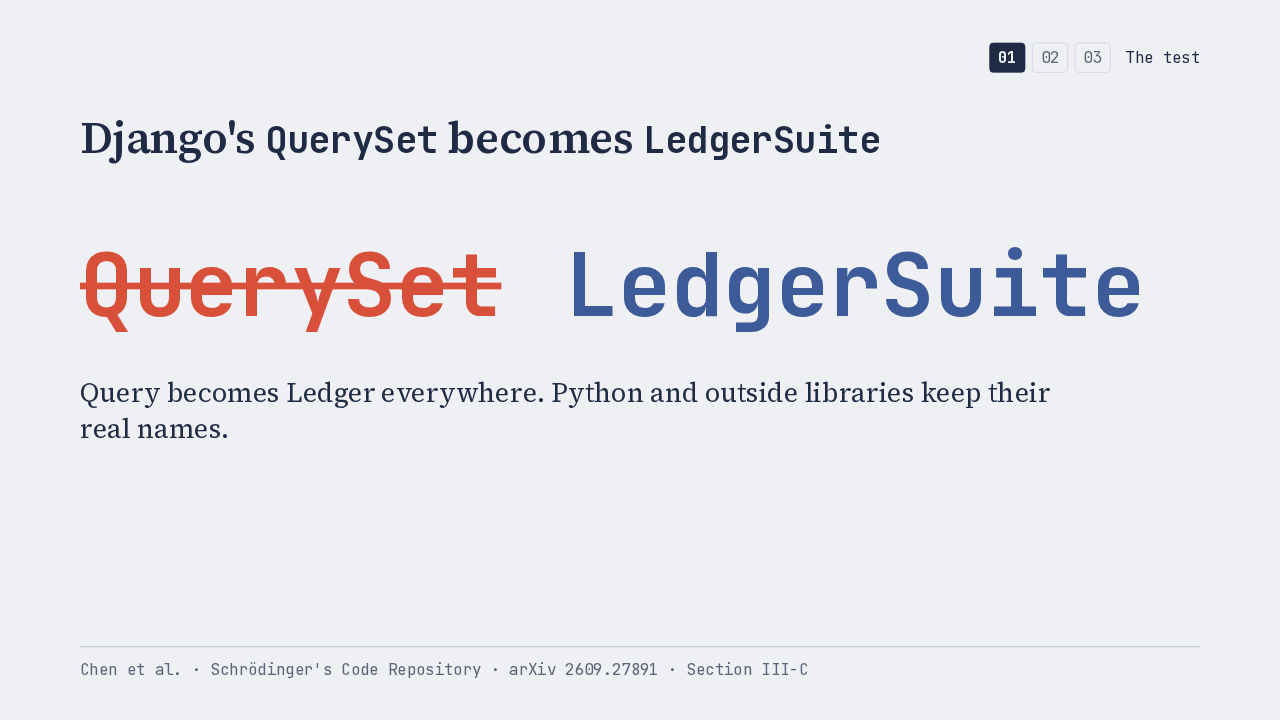
QuerySet becomes LedgerSuite
Django's QuerySet becomes LedgerSuite
Query becomes Ledger everywhere. Python and outside libraries keep their real names.
Here's their own example. Django's QuerySet class becomes LedgerSuite. The swap is consistent, so query turns into ledger everywhere it appears, while Python itself and outside libraries keep their real names. Every command the agent runs is translated back, so it still works on the real project underneath.
What happened
Then they ran four models on both versions.
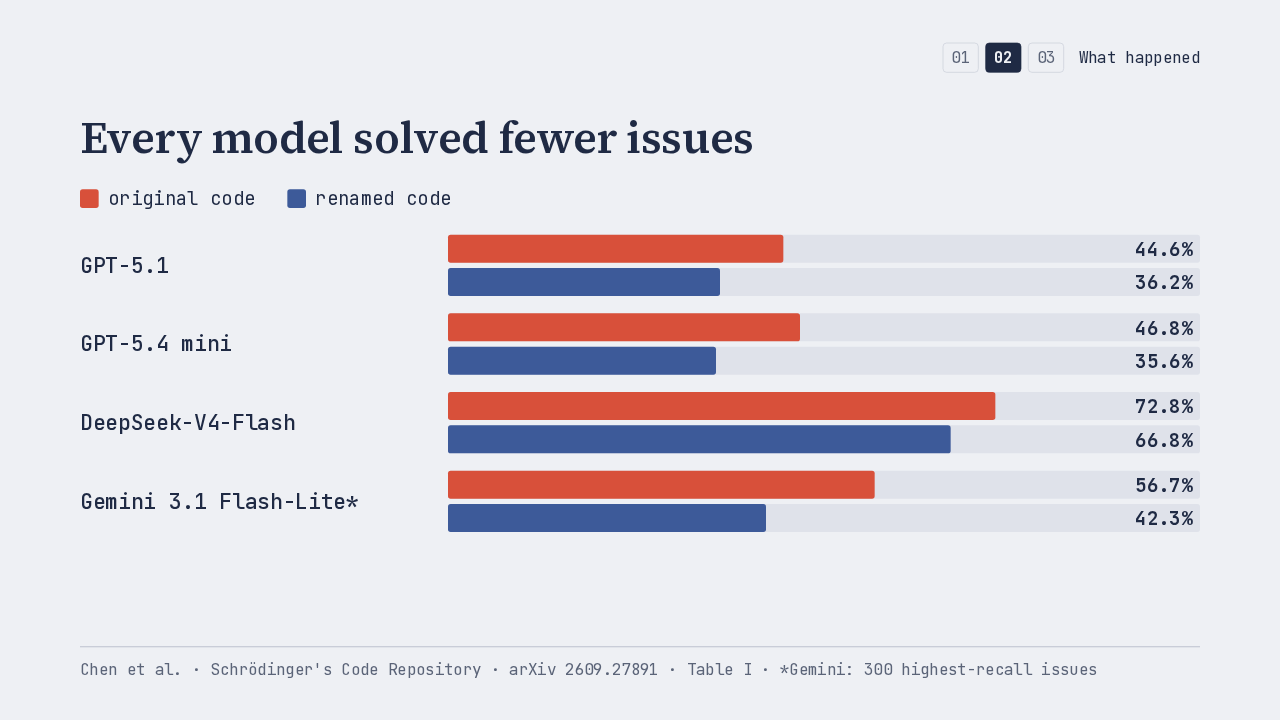
Every model solved fewer issues
Here's the share of issues each model solved, on the original code and on the renamed code. GPT-5.4 mini fell from about 47 percent to about 36. DeepSeek, the strongest here, fell from about 73 to 67. Across the four models the drop ran from 6 to 14 percentage points, and the authors report it as statistically significant.
The renaming did most of the damage
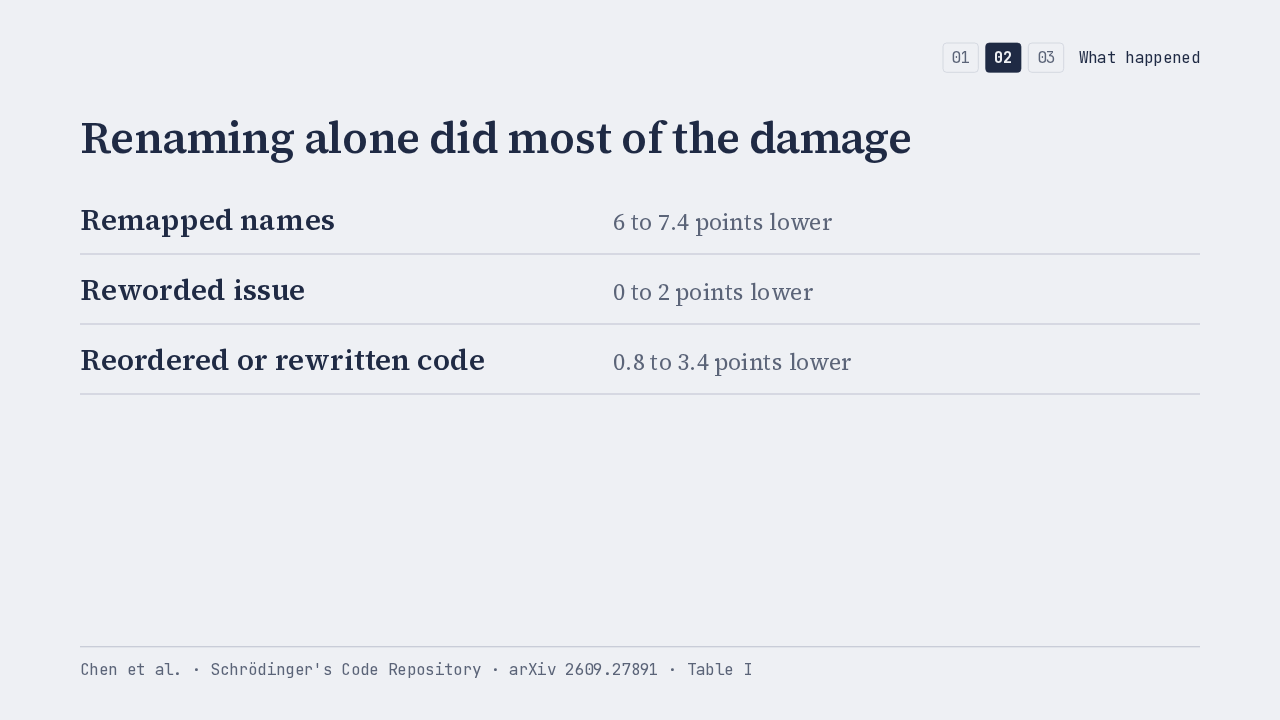
Renaming alone did most of the damage
Tested one change at a time, the renaming did most of the damage. Remapped names alone cost each model six to seven points. Rewording the issue barely mattered. Reordering and rewriting the code cost a few points at most. The authors read this as agents leaning on names they have seen before.
Agents read far more on unfamiliar code
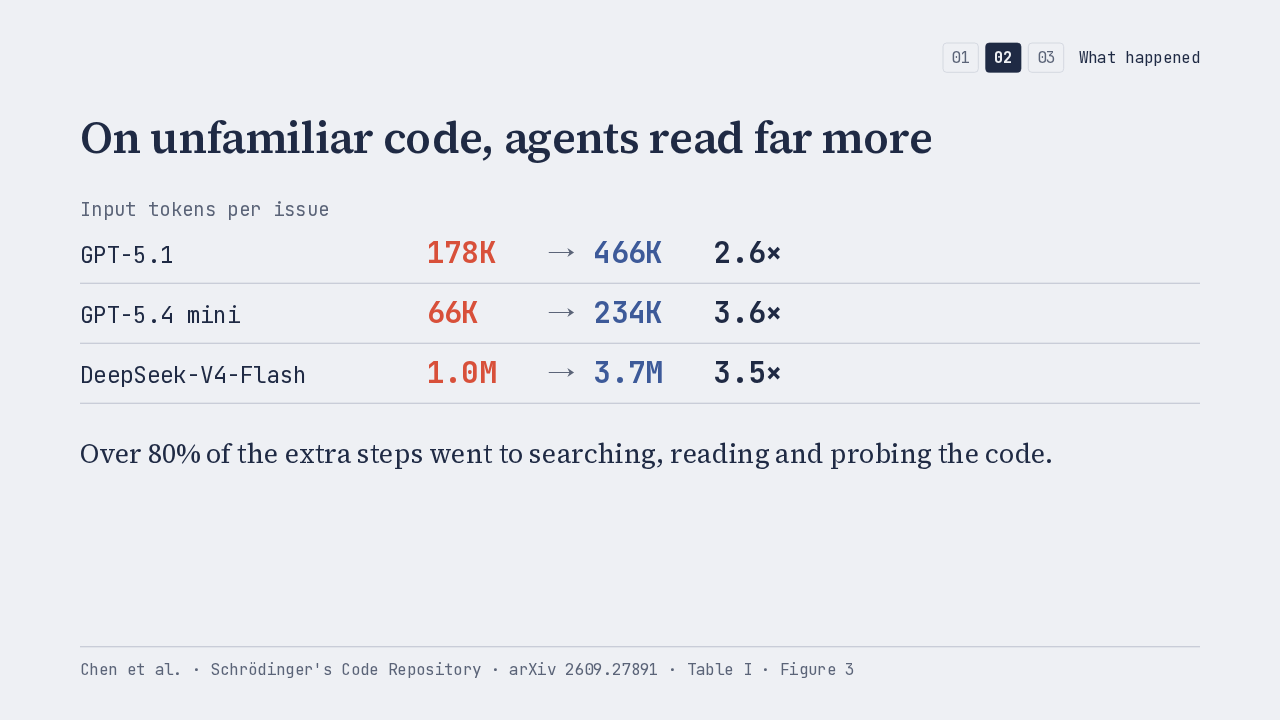
On unfamiliar code, agents read far more
Over 80% of the extra steps went to searching, reading and probing the code.
The cost went up too. On the renamed code, each agent read between two and a half and three and a half times as many tokens per issue. More than 80 percent of the extra steps went to finding its way around: listing folders, searching and reading files, and running small probes. Editing and testing took about the same effort.
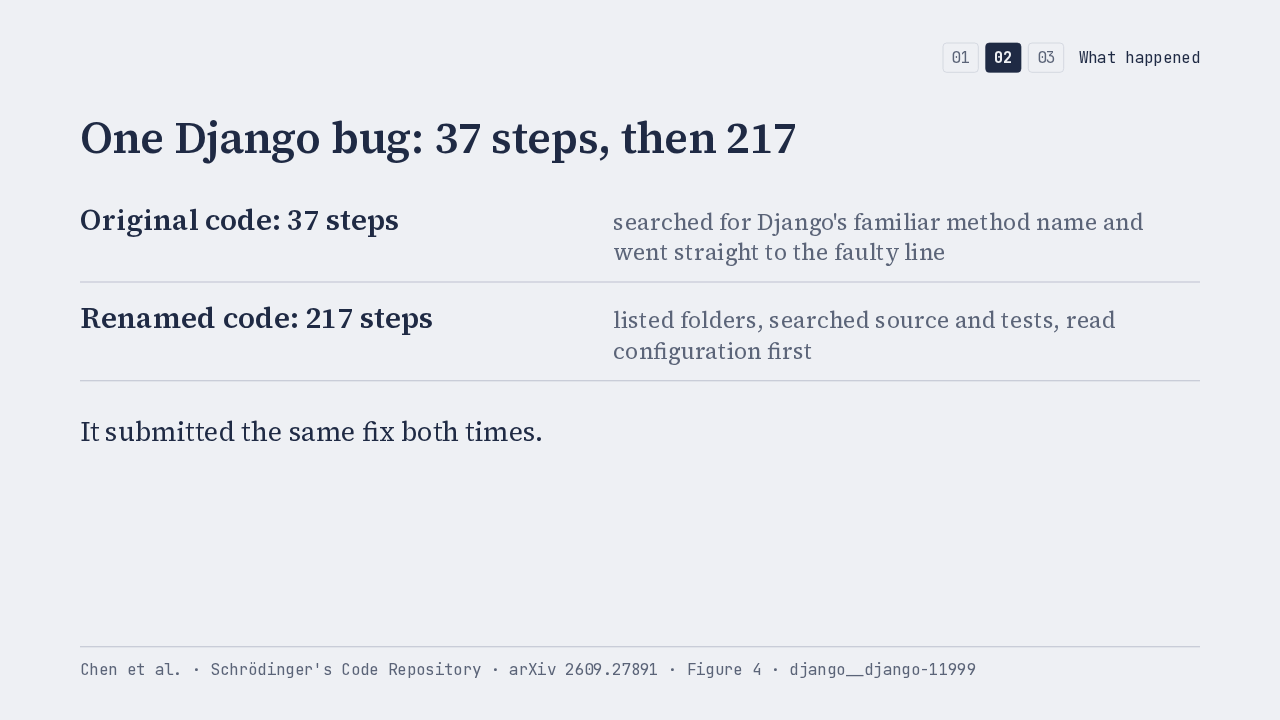
One Django bug: 37 steps, then 217
It submitted the same fix both times.
One Django bug shows the difference. On the original code, the agent searched for Django's familiar method name and found the faulty line almost at once, in 37 steps. On the renamed code it listed folders, searched the source and the tests, and read configuration files first: 217 steps. It submitted the same fix both times.
On newer issues, the score held
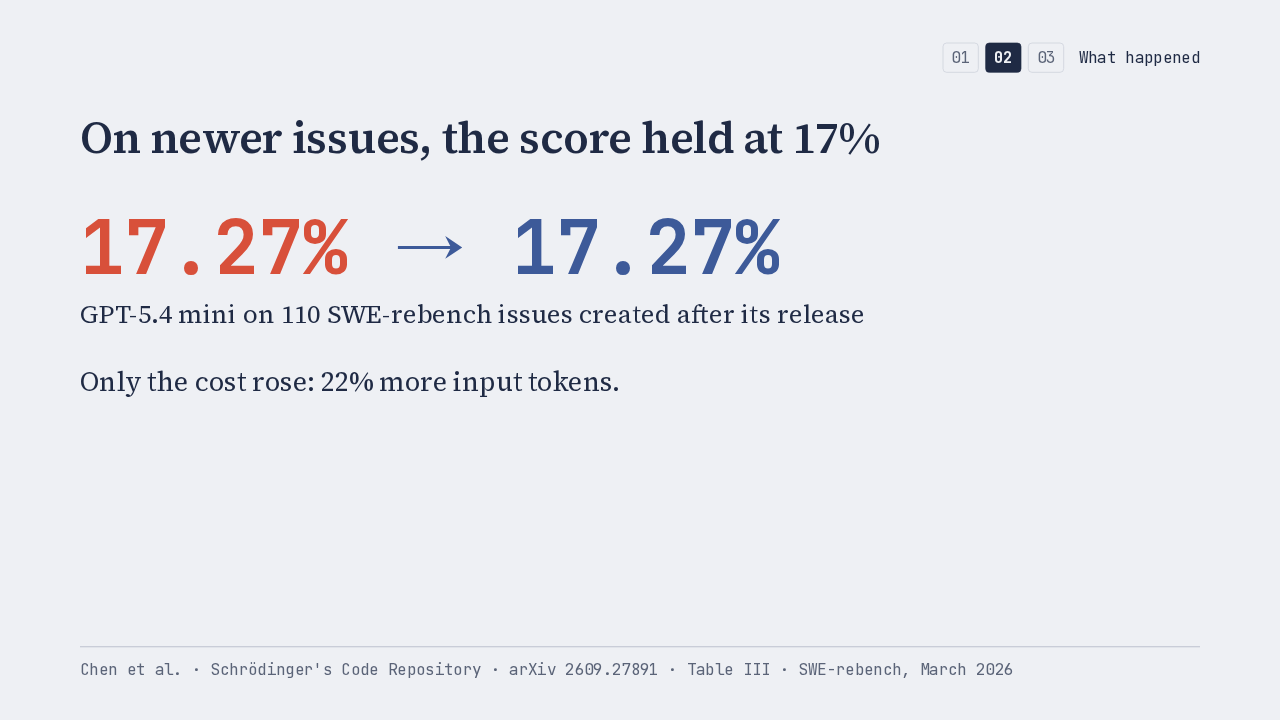
On newer issues, the score held at 17%
Only the cost rose: 22% more input tokens.
Could renaming just make the bugs harder? The authors checked on 110 newer issues from SWE-rebench, created after GPT-5.4 mini was released, so it's unlikely to have seen them. Its score stayed at about 17 percent either way. Only the cost went up, by about a fifth. So the renamed repositories are just as fixable, and the extra cost comes from unfamiliar code.
What it means
Here's what the paper does and doesn't show.
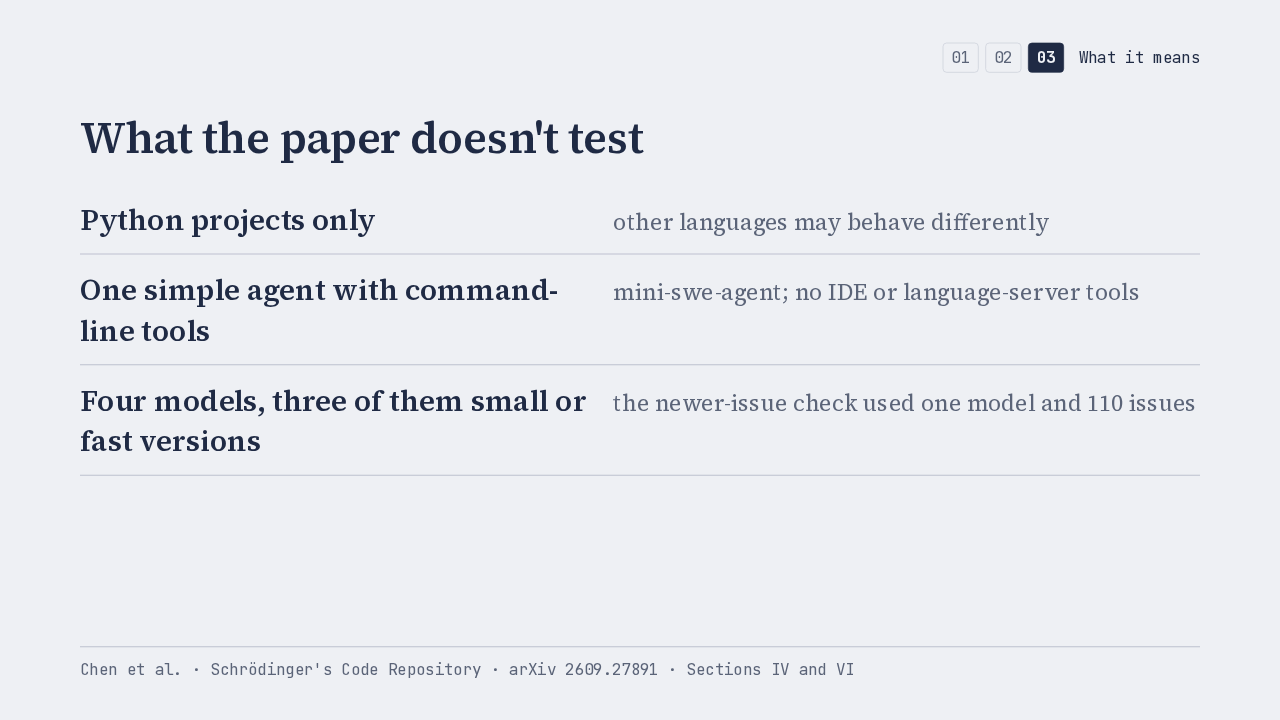
What the paper doesn't test
Here are the limits. Every project was Python. Every run used one simple open-source agent, mini swe agent, with command-line tools only, and the authors say agents that navigate with IDE or language-server tools need more work to test. Three of the four models are small or fast versions, and the check on newer issues used one model and 110 issues. It's a preprint.
What it means for picking a coding agent
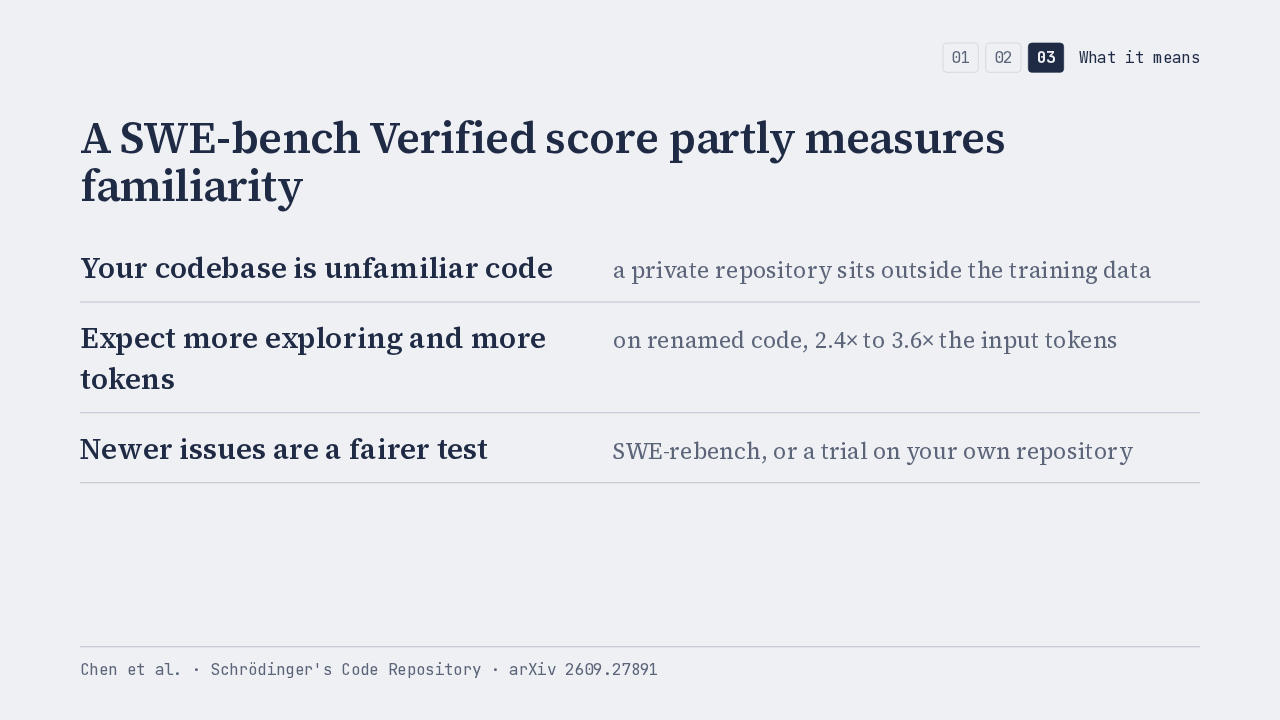
A SWE-bench Verified score partly measures familiarity
For anyone choosing a coding agent, a SWE-bench Verified score partly measures how well a model knows famous projects. The paper didn't test private code, but a private codebase sits outside the models' training data. On unfamiliar code these agents explored far more and read several times the tokens. The authors argue for testing on code a model can't have memorized, and newer issues or a trial on your own repository do that.
The paper and its code
Schrödinger's Code Repository
Four models, one agent, Python only. Within that, every model lost points.
One limit to keep in mind: this is four models, one agent and Python only. Within that, taking away the familiar names cost every model points and multiplied how much it read. The paper is on arXiv, and the code and data are on GitHub. That's how coding agents fare on SWE-bench once a repository's names are changed.