3DCodeVerse makes the same model write better 3D code than Claude Code, Codex or Gemini CLI
4 weeks ago
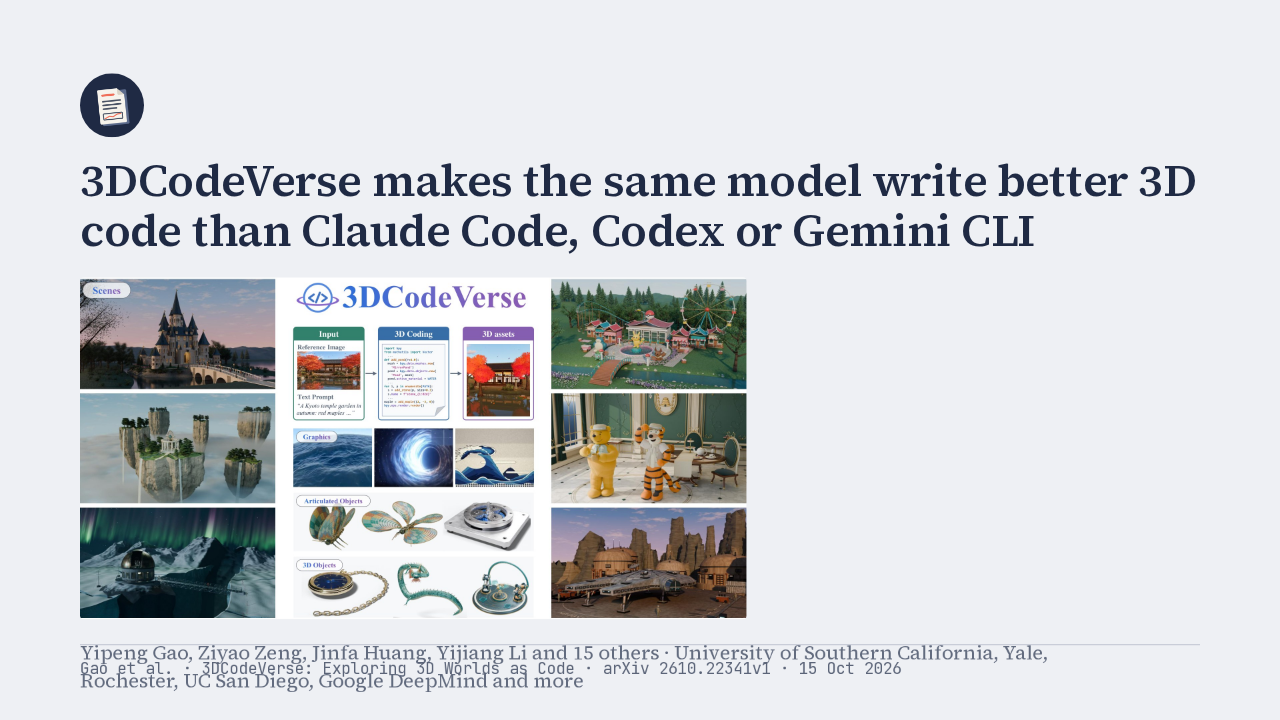
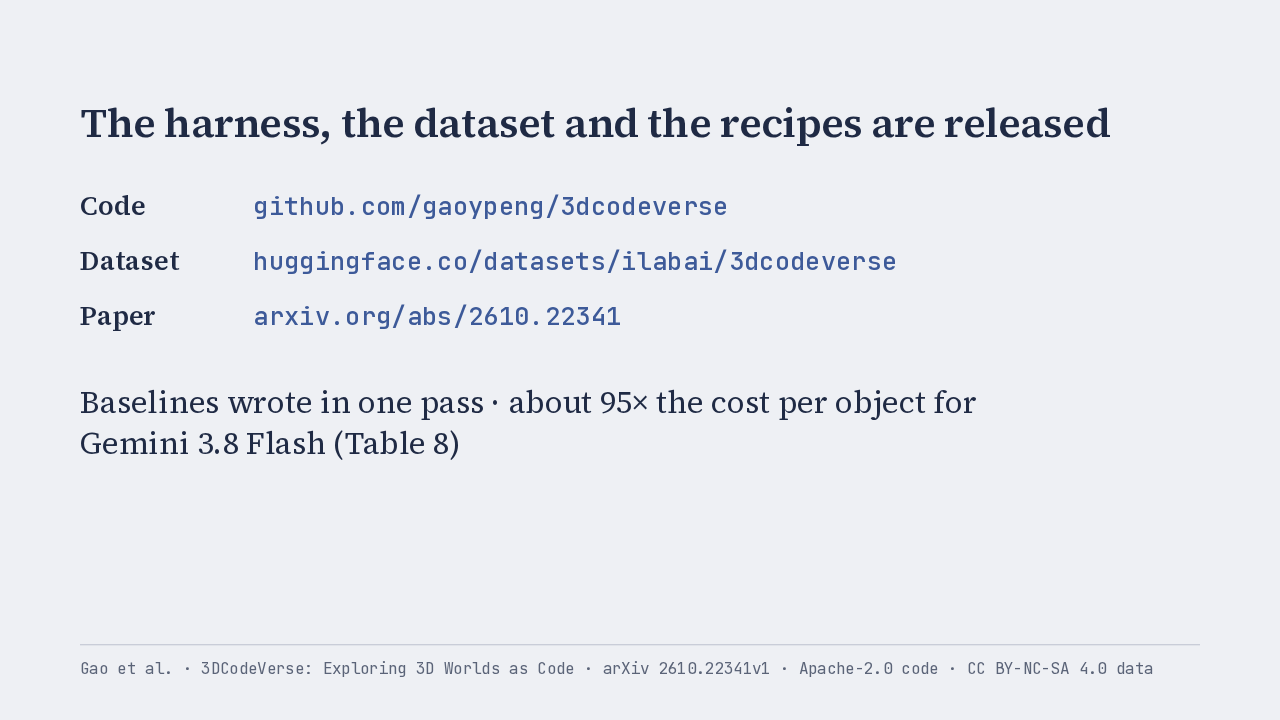
3DCodeVerse is a harness that builds 3D objects as code: it plans the parts, runs the code, measures and renders the result, has a vision model judge it, and fixes the code. With the same model inside, people preferred its objects over Claude Code, Codex and Gemini CLI in 7 to 9 of every 10 pairs, at many times the cost per object. The paper also releases 3DCodeVerse-2M, about two million runnable 3D programs, and fine-tuned Qwen models whose Blender scripts mostly run. Paper (arXiv 2610.22341v1, 15 Oct 2026): https://arxiv.org/abs/2610.22341 Code: https://github.com/gaoypeng/3dcodeverse Dataset: https://huggingface.co/datasets/ilabai/3dcodeverse
Ask about this presentation
Chapters
Show transcriptHide transcript
3DCodeVerse is a harness for building 3D objects as code. With the same model inside, people preferred its objects over those from Claude Code, Codex and Gemini CLI. It comes from the University of Southern California, Google DeepMind and others.
Slide text

3DCodeVerse makes the same model write better 3D code than Claude Code, Codex or Gemini CLI

Yipeng Gao, Ziyao Zeng, Jinfa Huang, Yijiang Li and 15 others · University of Southern California, Yale, Rochester, UC San Diego, Google DeepMind and more
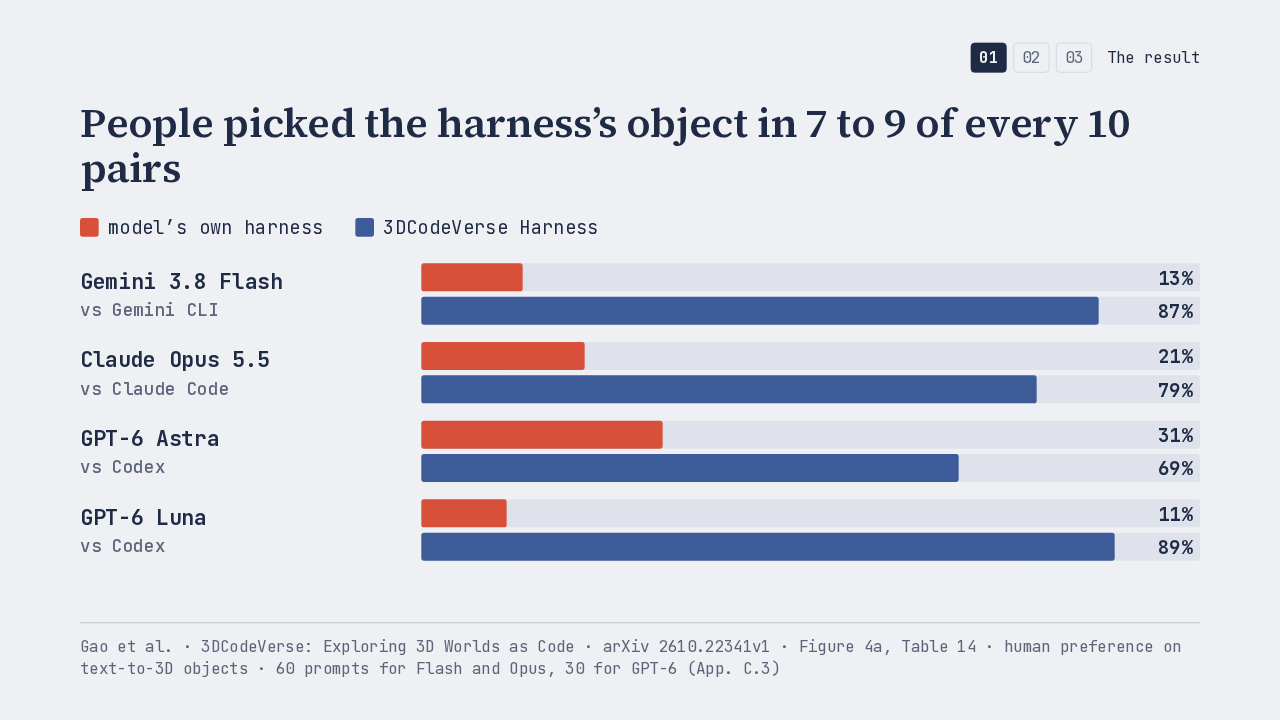
Gao et al. · 3DCodeVerse: Exploring 3D Worlds as Code · arXiv 2610.22341v1 · 15 Oct 2026Each model built the same objects in its usual coding agent and inside the harness. Shown both, people picked the harness version about four times in five. Claude Code with Opus 5.5 won about one pair in five.
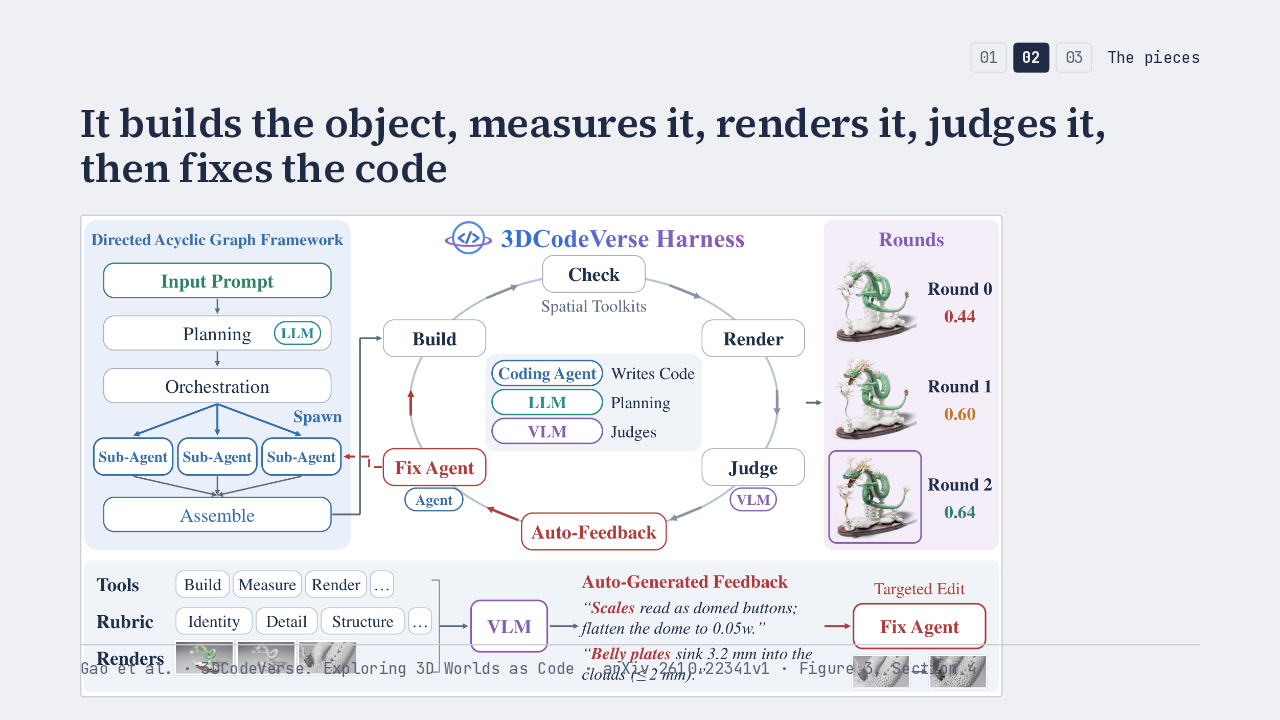
A planner splits the request into parts and sub-agents code each one. The harness runs the code, measures the parts for gaps and collisions, renders it, and a vision model judges the render. A fix agent edits the code, and the loop repeats.
Slide text
01 02 03 The piecesIt builds the object, measures it, renders it, judges it, then fixes the code
 Gao et al. · 3DCodeVerse: Exploring 3D Worlds as Code · arXiv 2610.22341v1 · Figure 3, Section 4
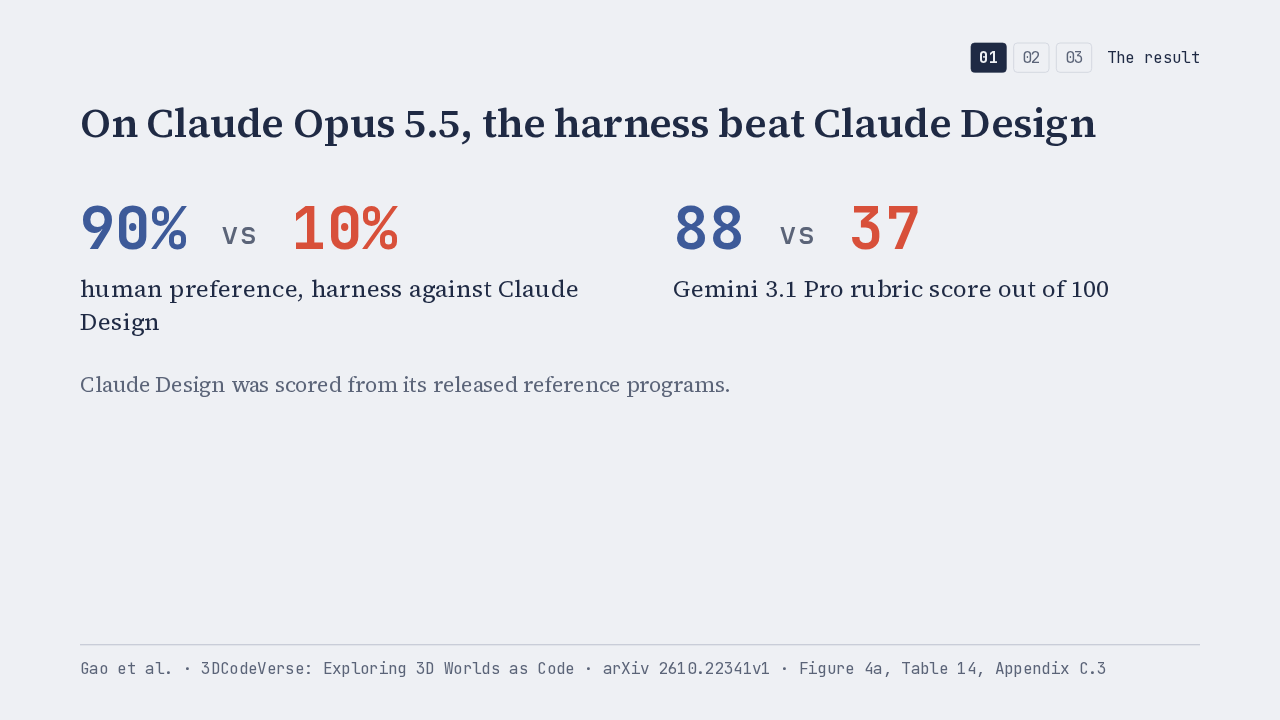
Claude Design runs on the same Claude Opus 5.5. People preferred the harness's object nine times in ten. On the rubric that grades every object out of 100, Claude Design's objects scored less than half as much.
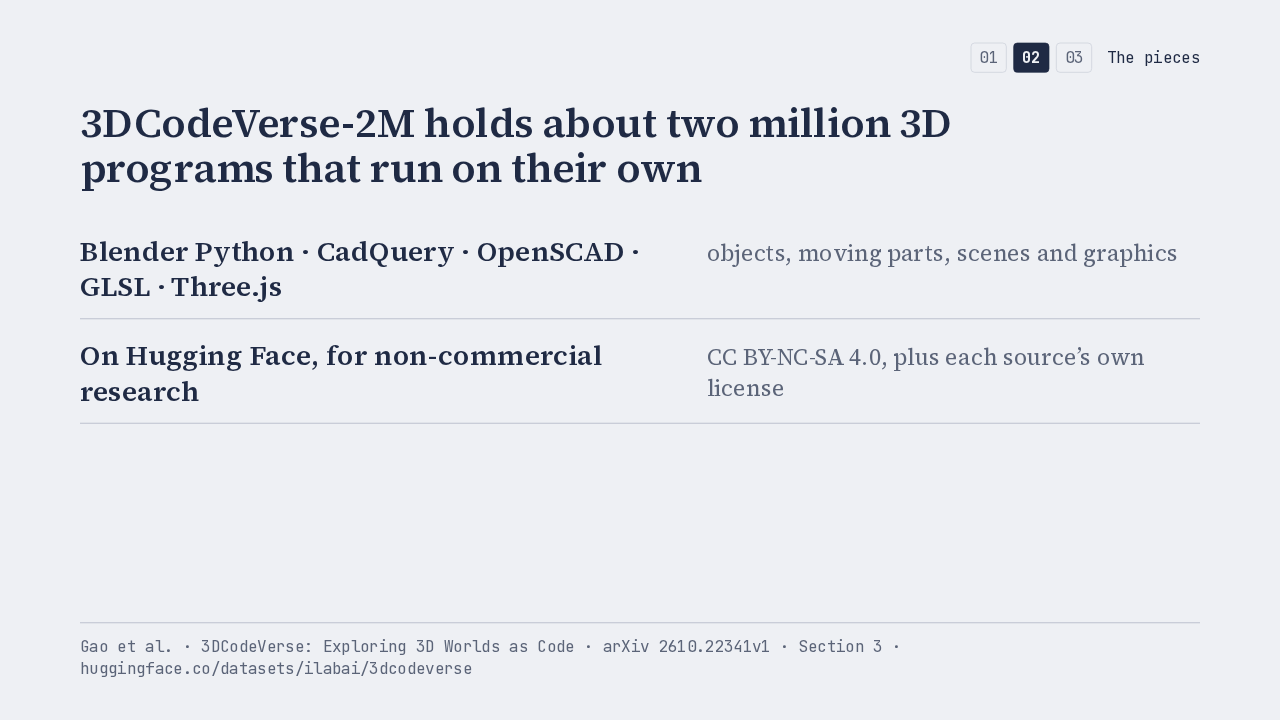
The team also released the training data. 3DCodeVerse-2M is about two million 3D programs that each run on their own, in Blender, CadQuery, OpenSCAD, shader code and Three.js. The license allows non-commercial research only.
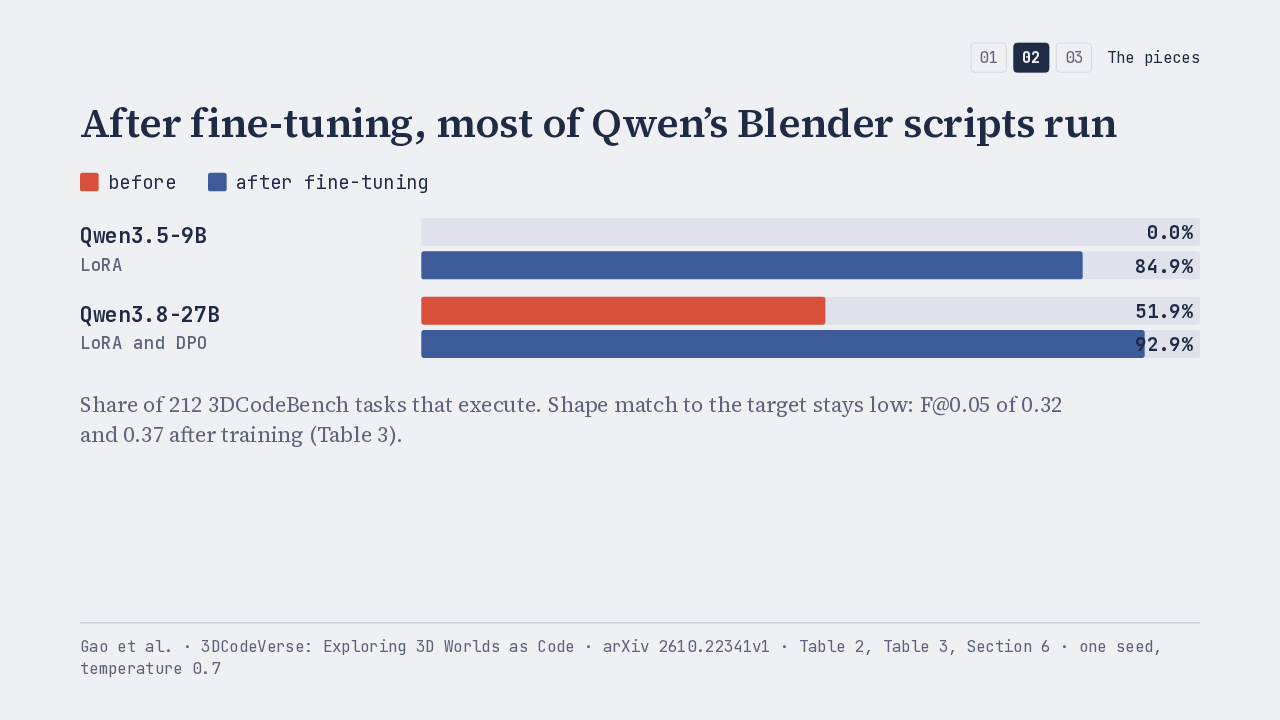
Before training, every Blender script Qwen3.5 9B wrote failed, mostly by calling a scene-clearing command Blender 5 no longer has. After LoRA fine-tuning, about 85 percent ran. The shapes they make still match their targets only loosely.
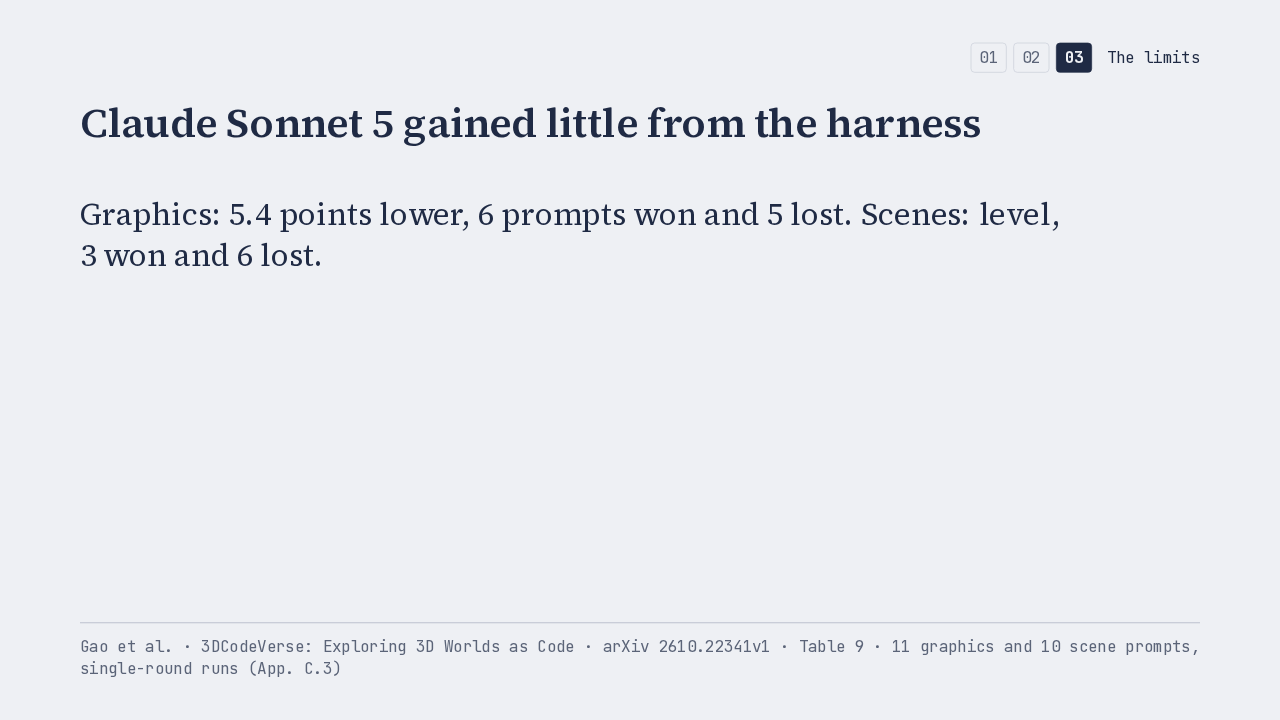
Claude Sonnet 5 is the exception. On shader graphics the harness scored it slightly below Sonnet working alone, and on scenes about the same. Those runs used one round of the loop.
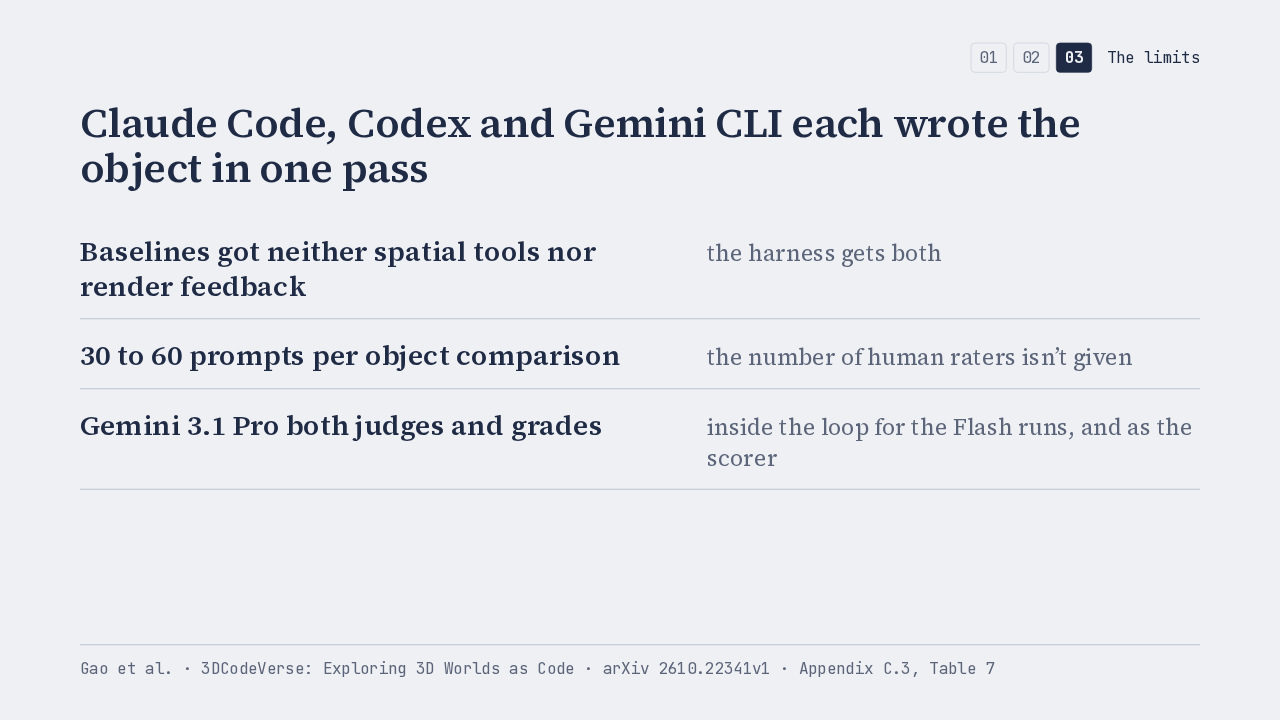
Claude Code, Codex and Gemini CLI each wrote the object in one pass, without measurements or render feedback, while the harness checked and fixed its work. Each comparison used 30 to 60 prompts, and the count of human raters isn't stated.
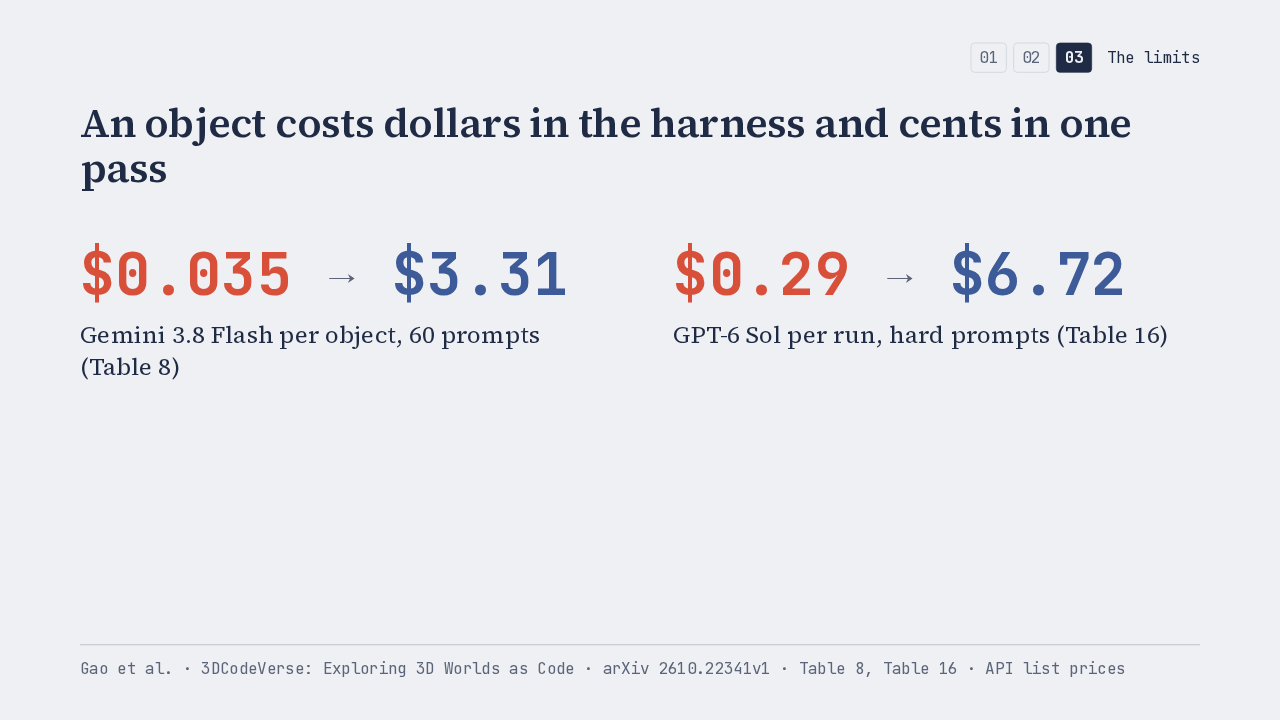
The loop costs more. Gemini 3.8 Flash in one pass cost about 4 cents an object, and inside the harness about 3 dollars 30. On hard prompts, GPT-6 Sol went from about 30 cents a run to almost 7 dollars.
The harness code is on GitHub under Apache 2.0, and the dataset is on Hugging Face. Every win came against agents writing in one pass, and for Gemini 3.8 Flash the loop cost about a hundred times as much per object.
Up next
 2:49
NestOne cuts a Qwen3.5 decision model to 24 layers at nearly full accuracy
@ai-papers
1 day ago
 2:33
MME-VLA robot memory counts a pause as work done and stops early
@ai-papers
3 days ago
 2:16
GPT-6 Astra fixed a small Qwen’s math by editing 1,023 of its weights
@ai-papers
5 days ago
 2:42
LoopVQ cuts looped models’ KV cache to half a bit and lifts Ouro’s throughput up to 6×
@ai-papers
1 week ago
 2:35
CUA-Master-27B is an open computer-use agent that trails only Claude Opus 5 and GPT-5.6-Sol on Agents' Last Exam
@ai-papers
1 week ago
 2:37
CaPtain trains Qwen3.5-4B to control a robot in code and beats several frontier-model agents
@ai-papers
1 week ago
 2:45
Trajectory2Gym data lifts a 4B Qwen3 agent past the stock 30B model on Tau2
@ai-papers
2 weeks ago
 2:46
“Wait” in reasoning models comes from training data, and RL almost never invents it
@ai-papers
3 weeks ago
 2:08
Looking Ahead makes Wan video models more physically plausible, with generation unchanged
@ai-papers
3 weeks ago
 2:30
OpenVLHarness gives vision models tools and a memory, and seven models each gain about 10 points
@ai-papers
3 weeks ago
 2:53
Agent-Reflex trains an 8B agent to recover when its MCP tools fail, and it gets derailed half as often
@ai-papers
1 month ago
 2:45
EmbodiedCLBench: one practice task gives AI agents most of their gain, and more practice doesn’t add to it
@ai-papers
1 month ago