Slide 1
You can now redirect an AI-generated character mid-stream, just by talking to it. Vidu S1, out of Tsinghua and Shengshu, streams the video in real time while you steer it by voice.
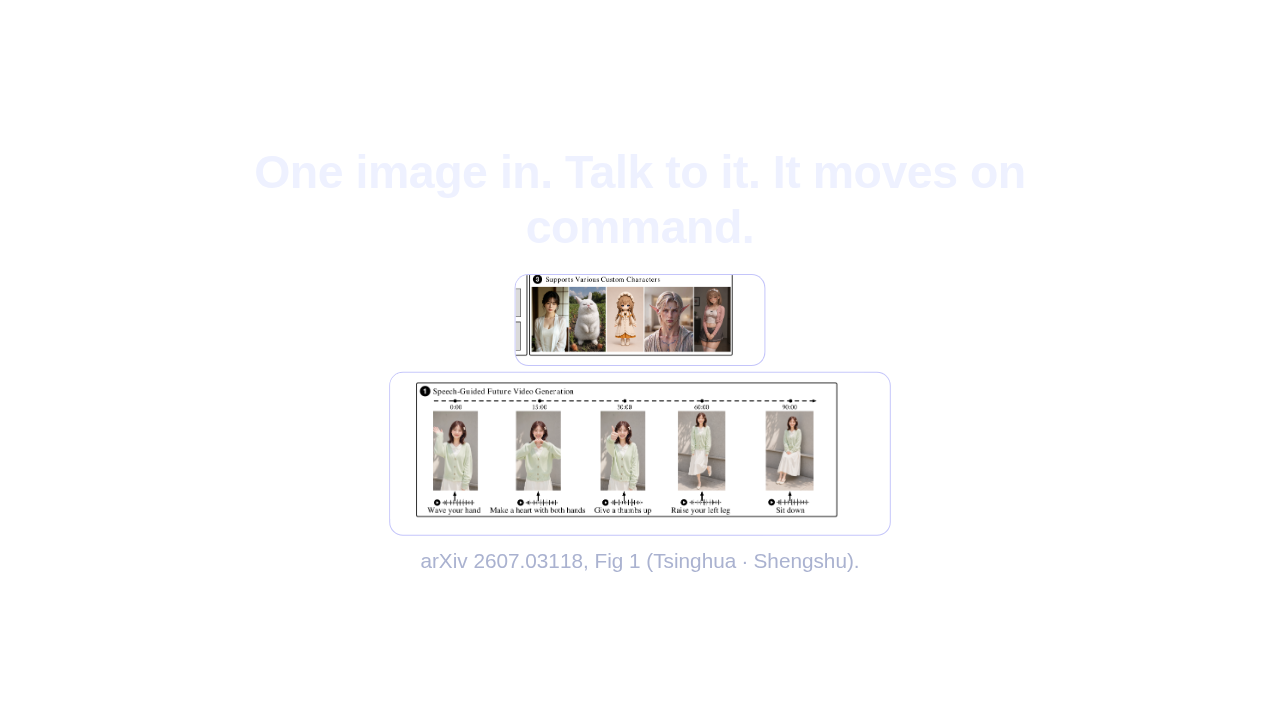
One image in. Talk to it. It moves on command.


Here's how it works. You give it one reference image, a person, a pet, an anime character. Then it streams an animated version you talk to. Tell it to wave, make a heart, sit down, and it does, live, for as long as you keep going, without the face drifting or falling apart.
Slide 3

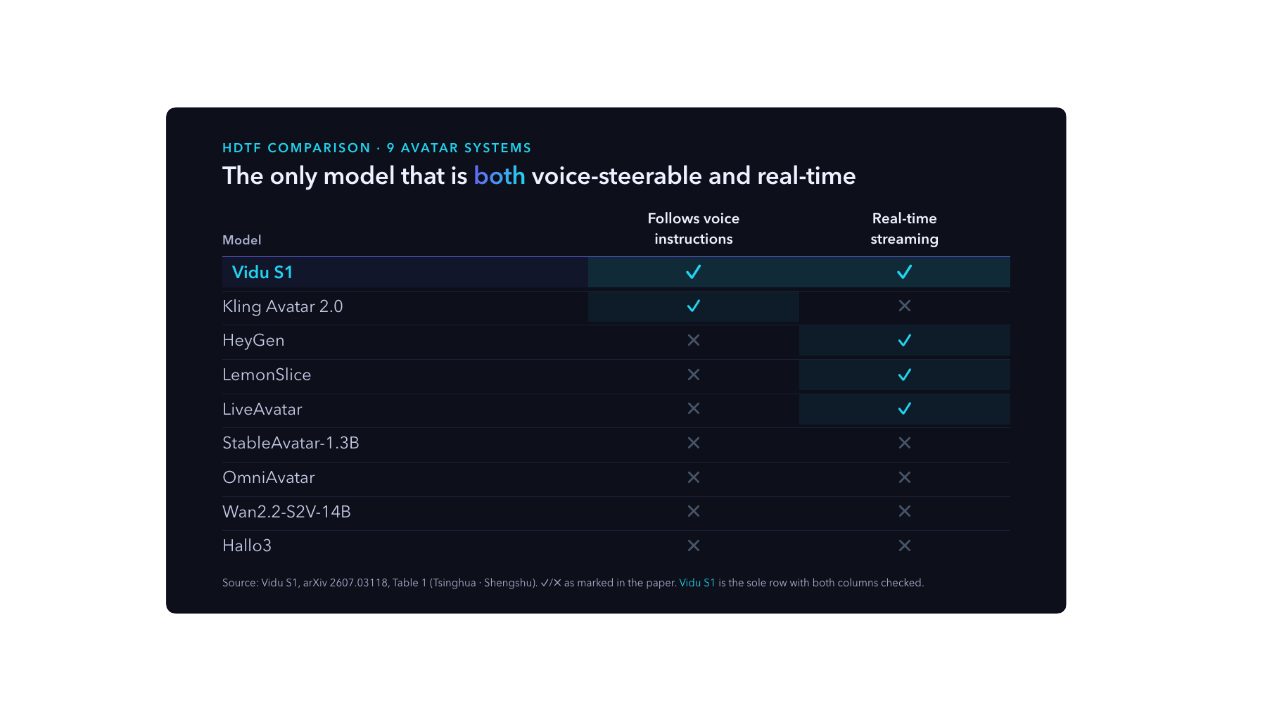
Plenty of models can animate a photo. The shift is the combination. In the paper's own line-up of nine avatar systems, Vidu S1 is the only one that both follows voice instructions and runs in real time. Everything else does one or the other, never both. It manages it by distilling the video model down to a few streaming steps.
Slide 4

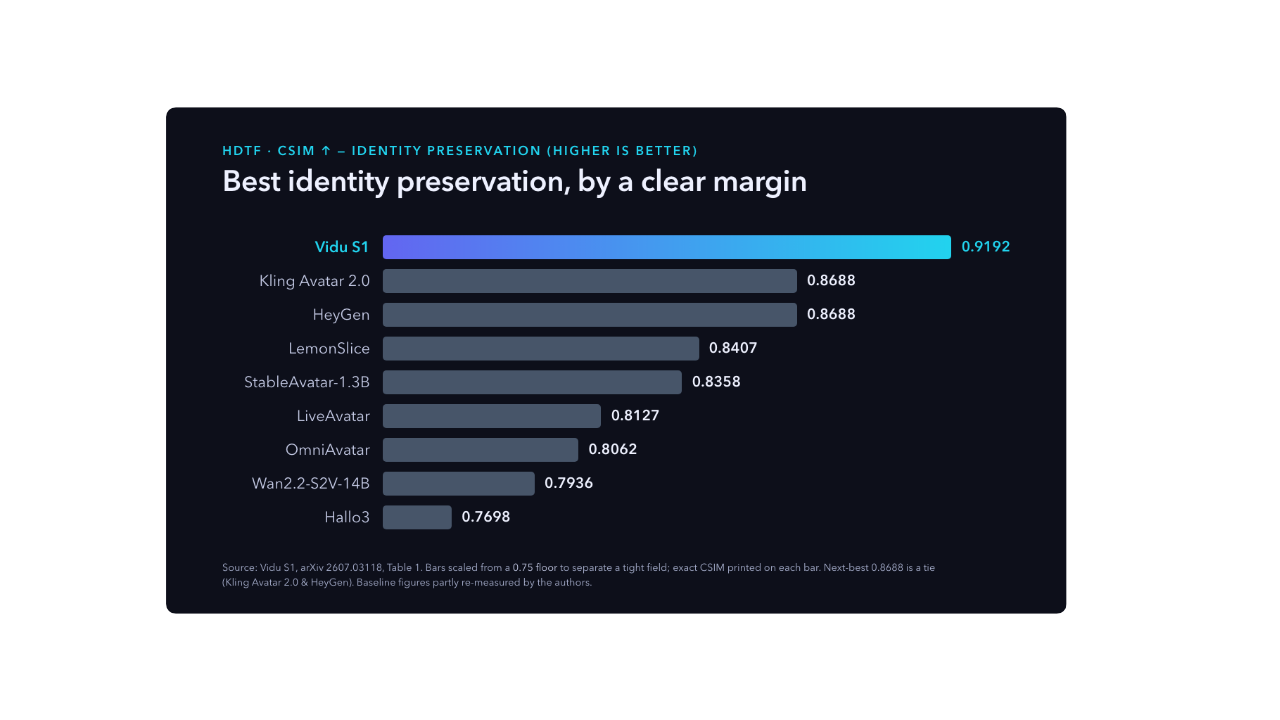
For hard numbers, the paper turns to the public HDTF benchmark. On identity preservation, Vidu S1 scores point nine-two, against point eight-seven for the next best, a clear, real margin. Its other two wins, on lip-sync and perceptual quality, are technically firsts too, but by margins thin enough to call a tie.
It actually does what you tell it.

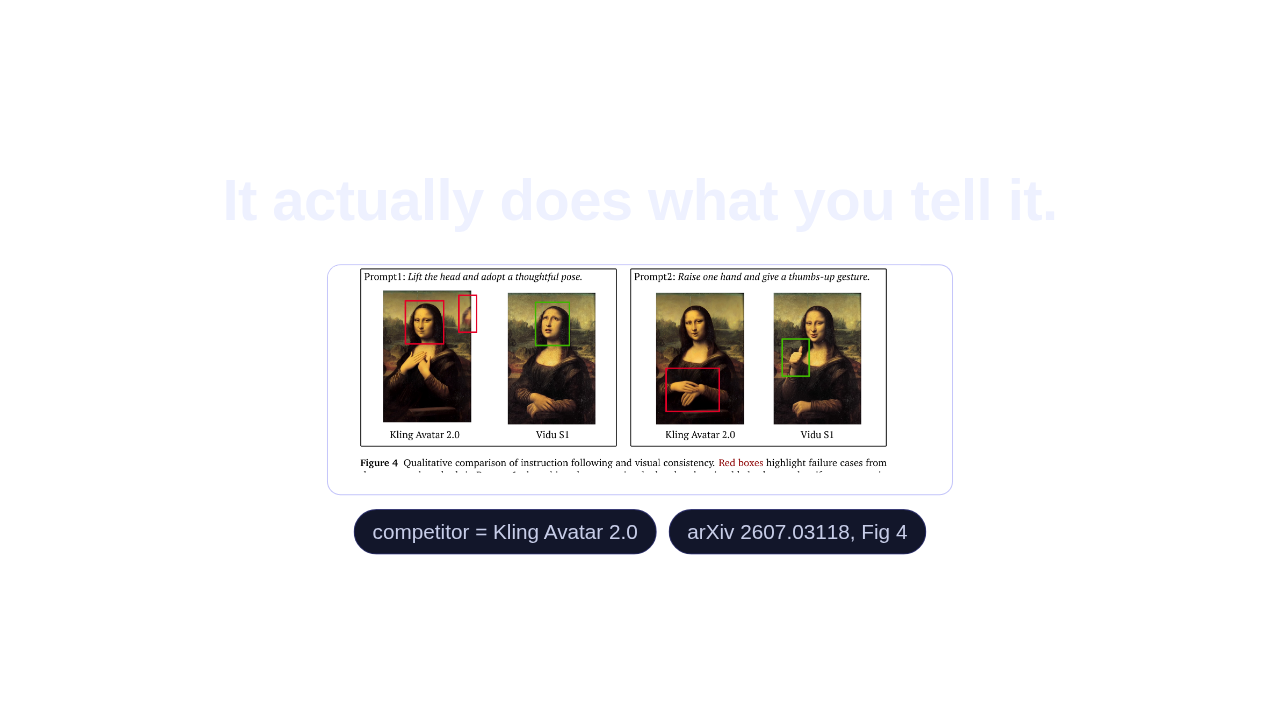
Here's what following instructions actually looks like. Same Mona Lisa portrait, same two commands: lift the head, and give a thumbs-up. Kling Avatar two point zero misses both. Vidu S1 does both.
What you can't do with it (yet).
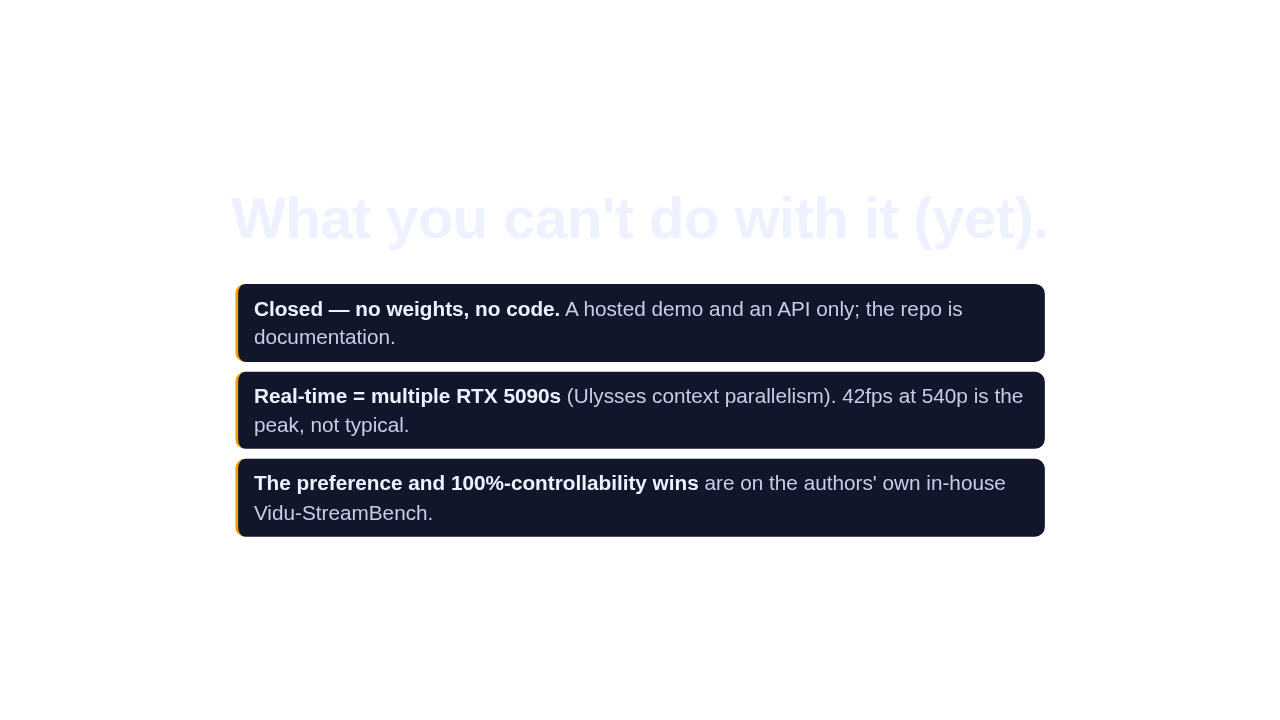
Now the catch, and it matters. No open weights, no code. The repo is documentation only. You get a hosted demo and an API, nothing to download and run yourself. The real-time speed also isn't one card. The paper splits the work across multiple RTX five-thousand-ninetys, and forty-two frames a second is the peak, not the everyday rate. And those preference wins are on the team's own in-house benchmark.
Slide 7
arXiv 2607.03118
license: closed / hosted API
So the capability is real. Real-time, voice-steerable video generation exists now. It just isn't yours to run yet. You can try the live demo, and the full paper is on arXiv.











