MiLMMT-46-v1.0
To teach a machine to translate, you normally show it the English and the French side by side. Xiaomi's translation team finished this translator, MiLMMT-46, on sentences that had no translation attached. Two other AI models did the grading instead.
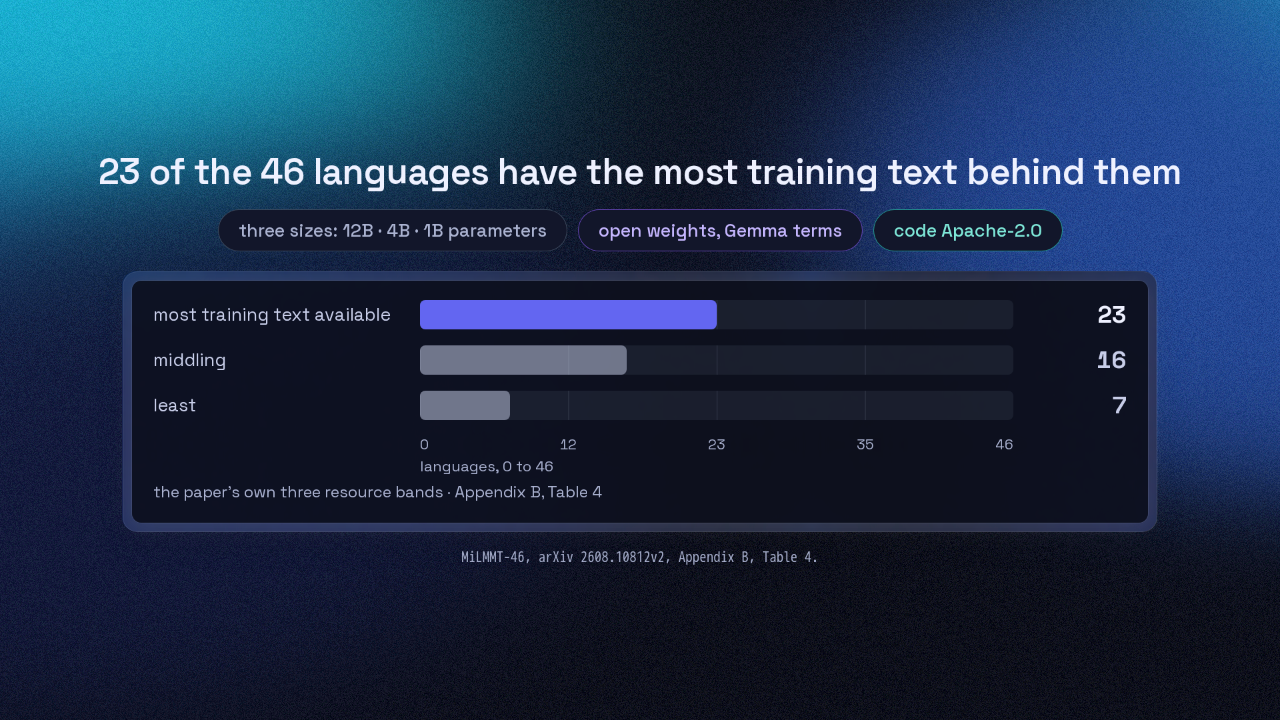
23 of the 46 languages have the most training text behind them
MiLMMT-46 takes a sentence and a target language, and writes the translation, in forty six languages. Xiaomi released three sizes, the biggest one twelve billion parameters, the adjustable numbers a model is made of. Those forty six languages came out of Xiaomi's earlier work. What this paper adds is the last stretch of training. Sentence pairs written by a person run out fast past the biggest languages.
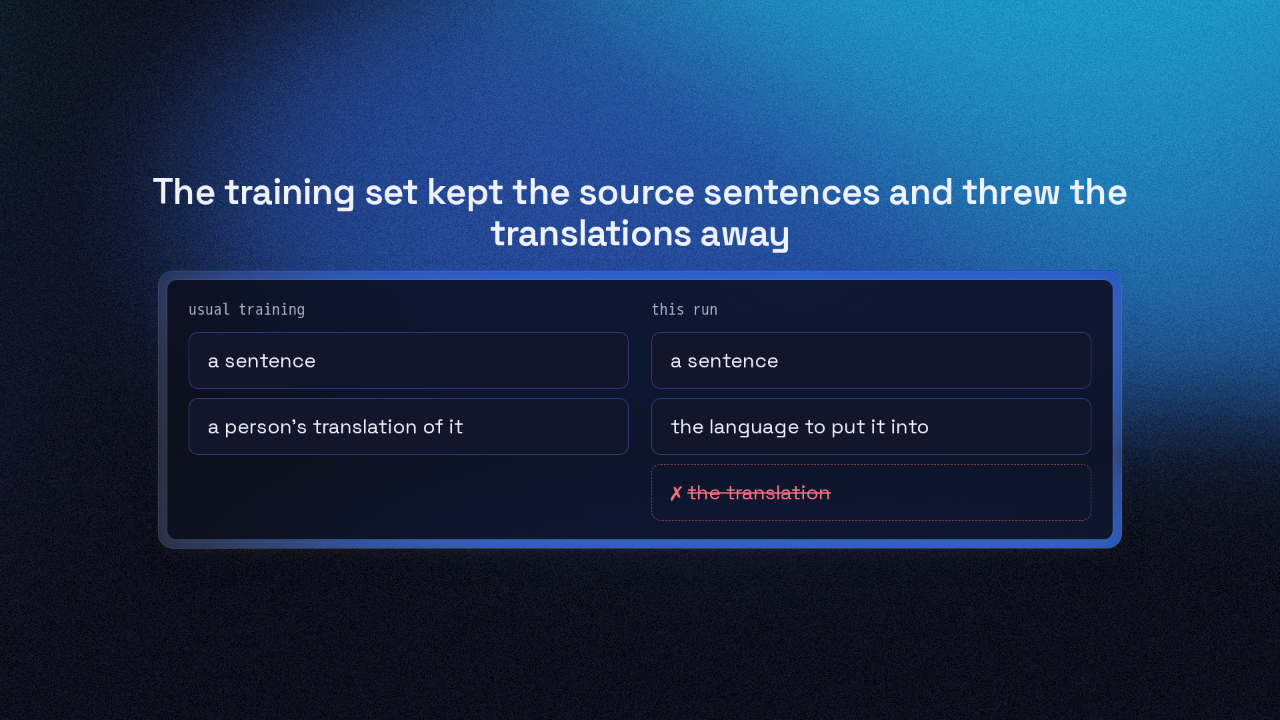
The training set kept the source sentences and threw the translations away
So Xiaomi deleted the translations out of its own training data. Each example kept its source sentence and the target language, and lost the answer. A translation has no single right answer. Ten good translators produce ten different sentences, and all ten can be right.
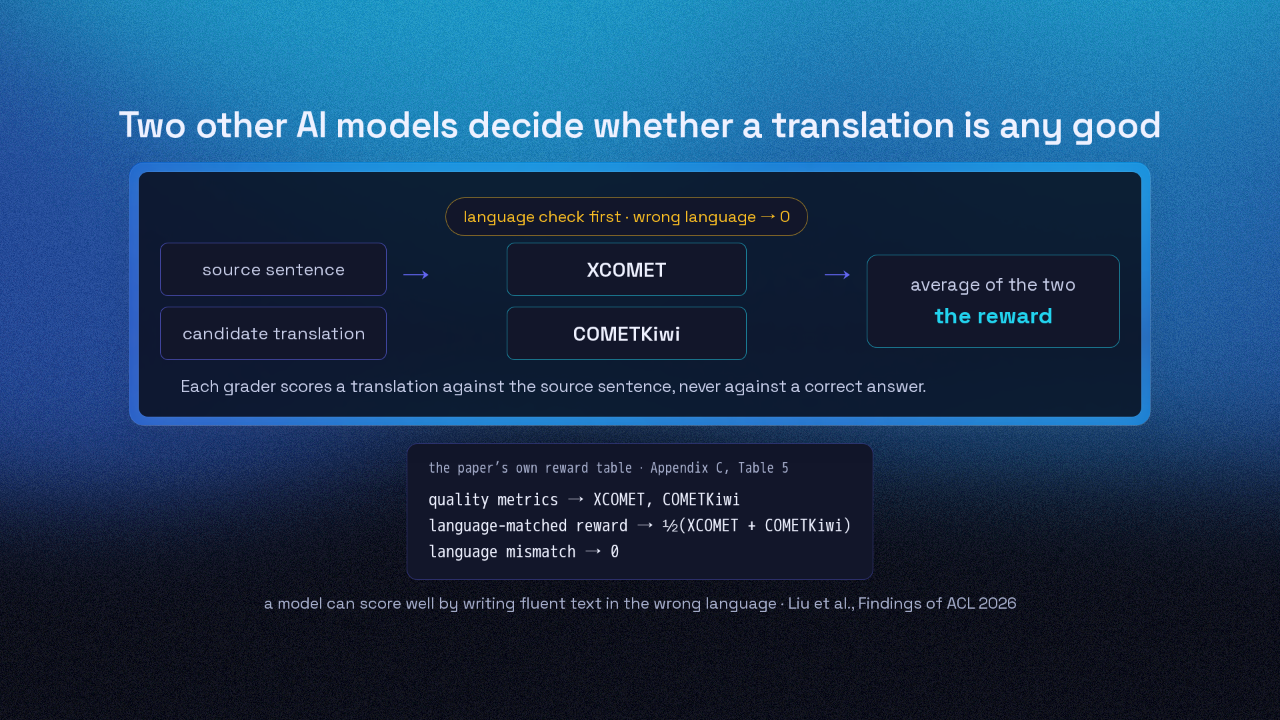
Two other AI models decide whether a translation is any good
The grade comes from two other AI models, called XCOMET and COMETKiwi. Each one reads the original sentence and a candidate translation, and scores how good the translation is. Xiaomi never shows either model a correct answer, because there isn't one. Xiaomi averages the two numbers, and that average is the whole reward. A language detector checks the output first. If the translation is in the wrong language, the score is zero. That gate blocks a known shortcut, where a model wins points for beautiful text in the wrong language.
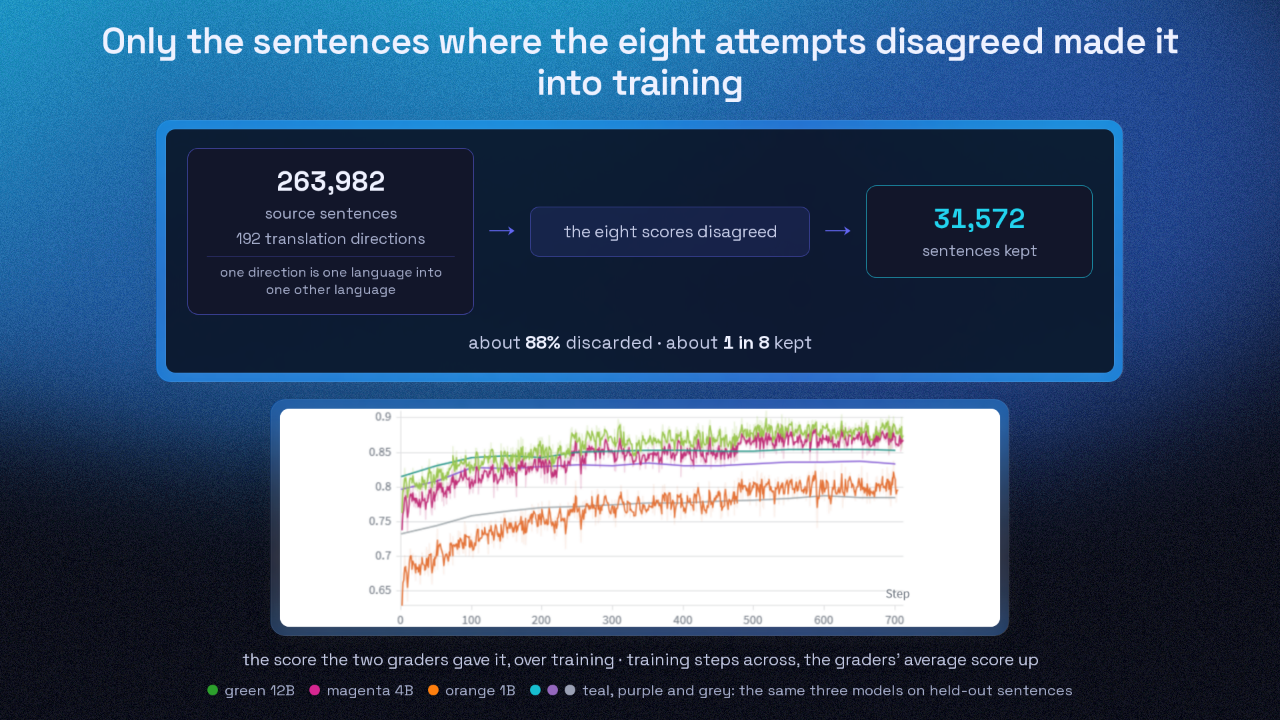
Only the sentences where the eight attempts disagreed made it into training
For one source sentence, the model writes eight different translations. All eight get scored, and the model shifts toward the ones that beat the average of the eight. Those other seven attempts are the only yardstick. Xiaomi started with two hundred and sixty three thousand source sentences, across a hundred and ninety two translation directions. If all eight are excellent, or all eight are hopeless, there is nothing to push toward, so Xiaomi dropped those sentences. That left thirty one thousand five hundred sentences, about one in eight.
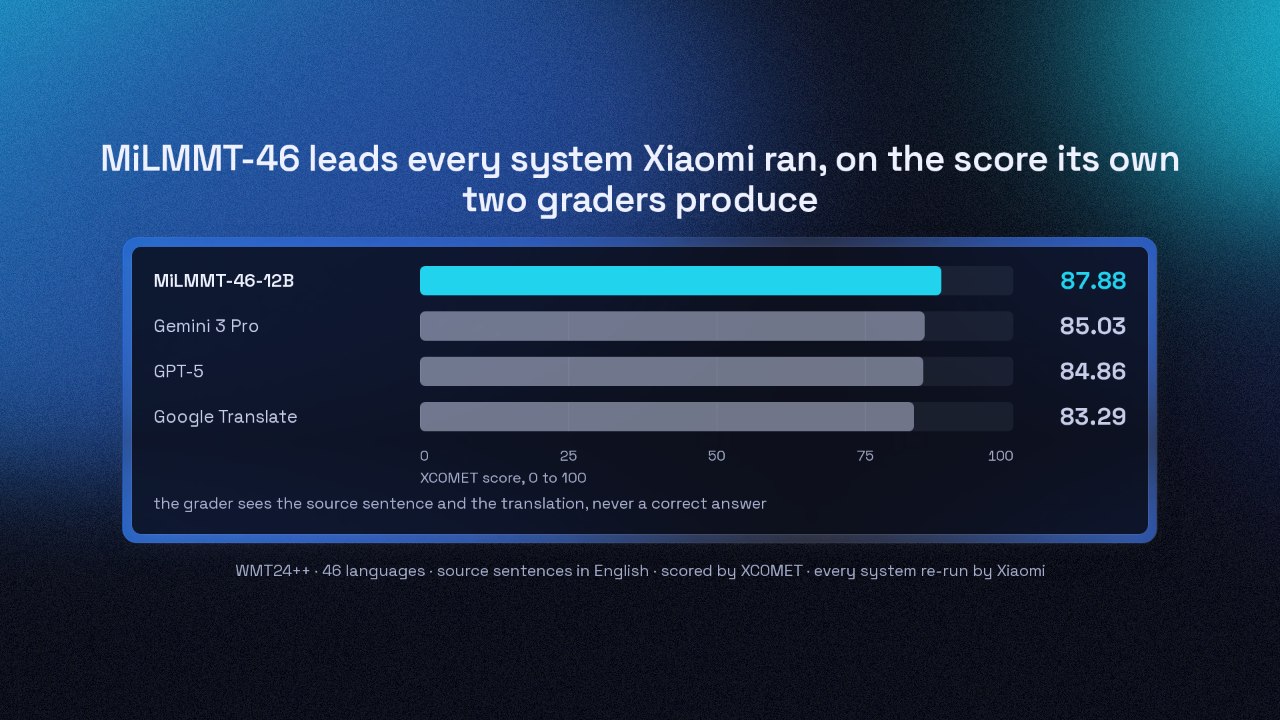
MiLMMT-46 leads every system Xiaomi ran, on the score its own two graders produce
On that same grade from the two graders, the twelve billion version scores eighty seven point eight eight across forty six languages. Gemini 3 Pro comes closest, nearly three points behind, then GPT-5 and Google Translate. Xiaomi ran all four of those systems itself, so every number here is its own measurement.
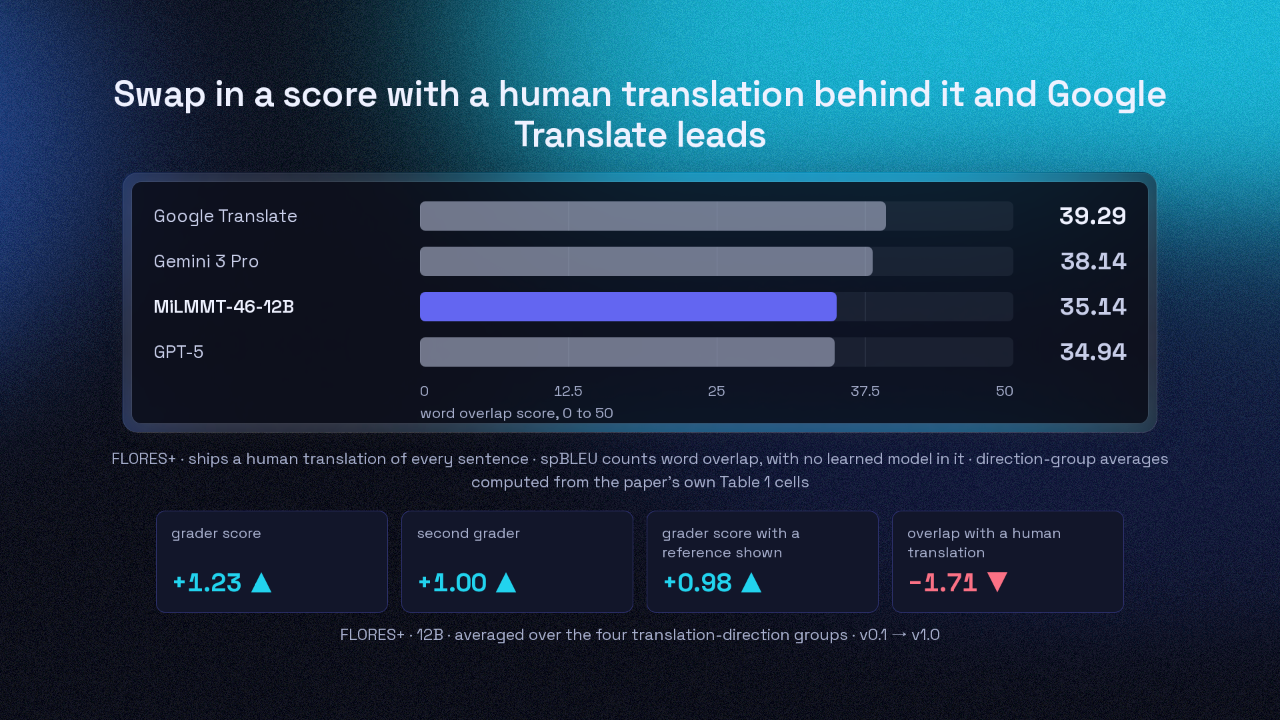
Swap in a score with a human translation behind it and Google Translate leads
That winning score comes from XCOMET and COMETKiwi, the same two models the training reward was made of. The paper names no separate models for the scoring. The paper reports one number that comes from neither grader, a plain overlap count against a translation a person actually wrote. On that overlap count, Google Translate is ahead, thirty nine point two nine against MiLMMT's thirty five point one four. On Xiaomi's own before and after for the twelve billion model, every grader score went up, and the overlap with a person's translation went down.
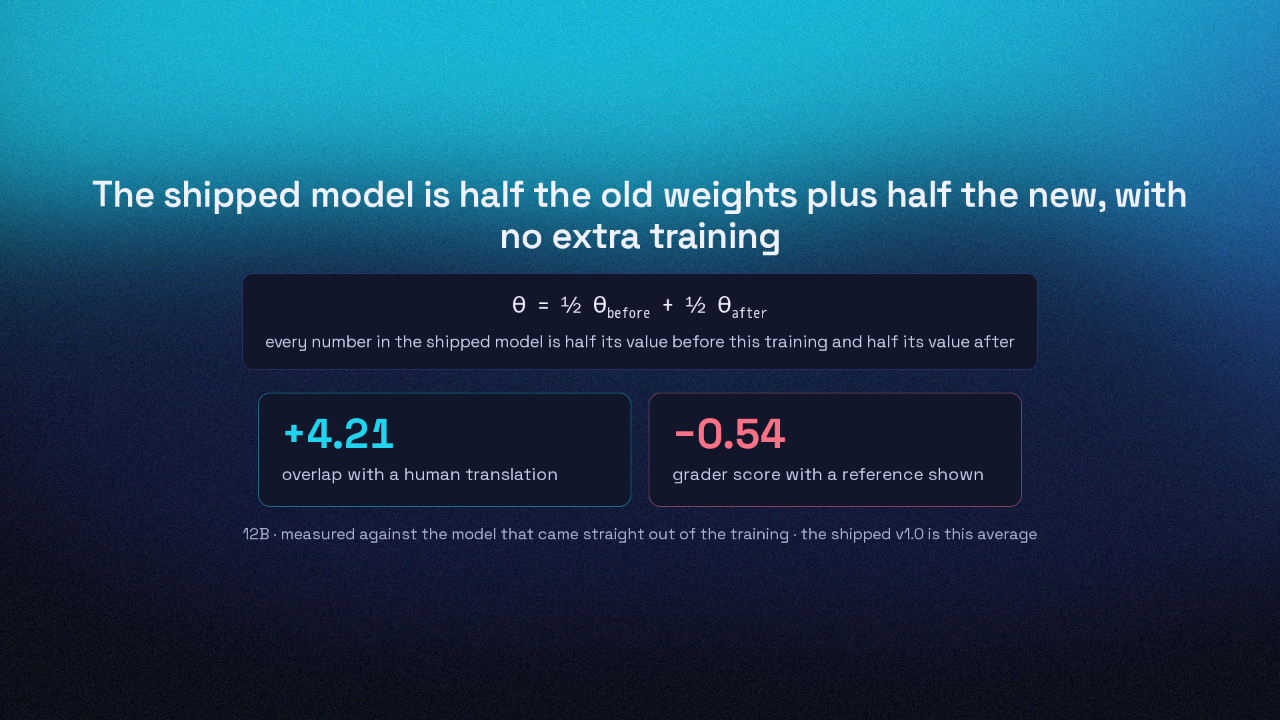
The shipped model is half the old weights plus half the new, with no extra training
Xiaomi's fix for that lost overlap is simple. A model is a big pile of numbers. The team averaged the pile from before this training with the pile from after, half from each, and ran no extra training. Set against the model straight out of that training, the average gives back four point two one points of overlap with a person's translation. That average costs half a point of grader score, this time with the graders shown a correct translation.
MiLMMT-46 learned from two graders standing in for an answer key
MiLMMT-46 learned from two graders standing in for an answer key, and the scores that rose are the graders’ own
So the training used two AI graders where an answer key would normally go. Anyone can download all three sizes, under Google's Gemma terms, which carry use restrictions. Xiaomi scored every system with automatic metrics, and ran no human evaluation at all. Xiaomi's own stated next step is reward models that line up better with human judgment.