Solar Open 2, an open model that reads a million words on about a quarter of the memory

2 months ago

A long AI conversation gets expensive for one big reason. The model has to keep hold of every word you have said. Upstage, an AI lab in South Korea, just released Solar Open 2. It is a very large open model that reads about a million words, a whole shelf of books, on roughly a quarter of the usual memory.

Ask

Ask about this presentation

Answers are generated from this presentation.

Chapters

  1. 0:00Solar Open 2, an open model that reads a million words on about a quarter of the memory
  2. 0:16250 billion internal numbers, only 15 billion awake per word
  3. 0:37Only 1 layer in 4 stores every past word
  4. 1:00Three of four layers keep a running summary, not the words
  5. 1:33Only 12 of 48 layers store the past
  6. 2:08Leads a couple of tests; two bigger rivals win more
  7. 2:42Free for commercial use, if you name derivatives Solar
  8. 2:58A million-word memory, kept as a running summary
Show transcript

Solar Open 2, an open model that reads a million words on about a quarter of the memory

Solar Open 2

An open model that reads a million words on about a quarter of the memory.
Upstage open weights · Solar License text · EN / KR / JA 250B total · 15B active · 1M context

A long AI conversation gets expensive for one big reason. The model has to keep hold of every word you have said. Upstage, an AI lab in South Korea, just released Solar Open 2. It is a very large open model that reads about a million words, a whole shelf of books, on roughly a quarter of the usual memory.

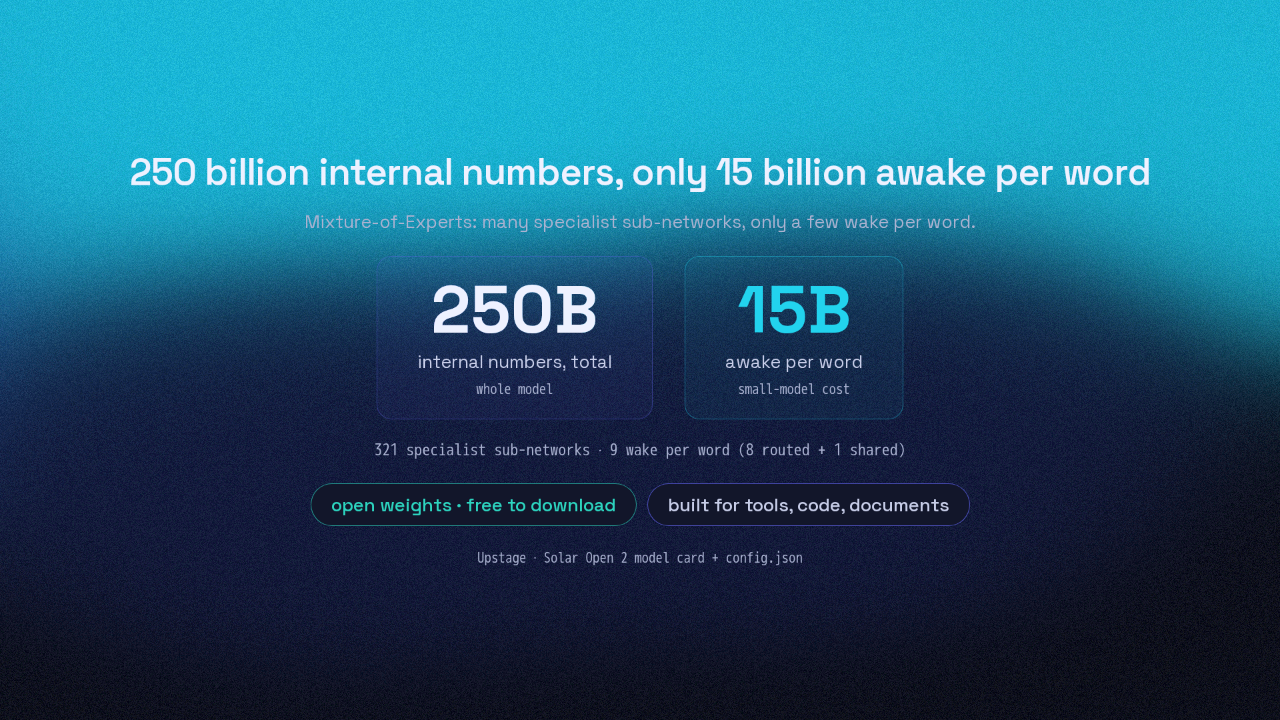
250 billion internal numbers, only 15 billion awake per word

Mixture-of-Experts: many specialist sub-networks, only a few wake per word.
250B
internal numbers, total
whole model
15B
awake per word
small-model cost
321 specialist sub-networks · 9 wake per word (8 routed + 1 shared)
open weights · free to download built for tools, code, documents
Upstage · Solar Open 2 model card + config.json

Solar Open 2 is a big set of specialist sub-networks, and for each word it wakes only a few of them. So it holds two hundred and fifty billion internal numbers in total, but only about fifteen billion do the work on any one word. So a model this large runs at a small model's cost. The weights are public and free to download. And it is built for real work with tools, code, and documents.

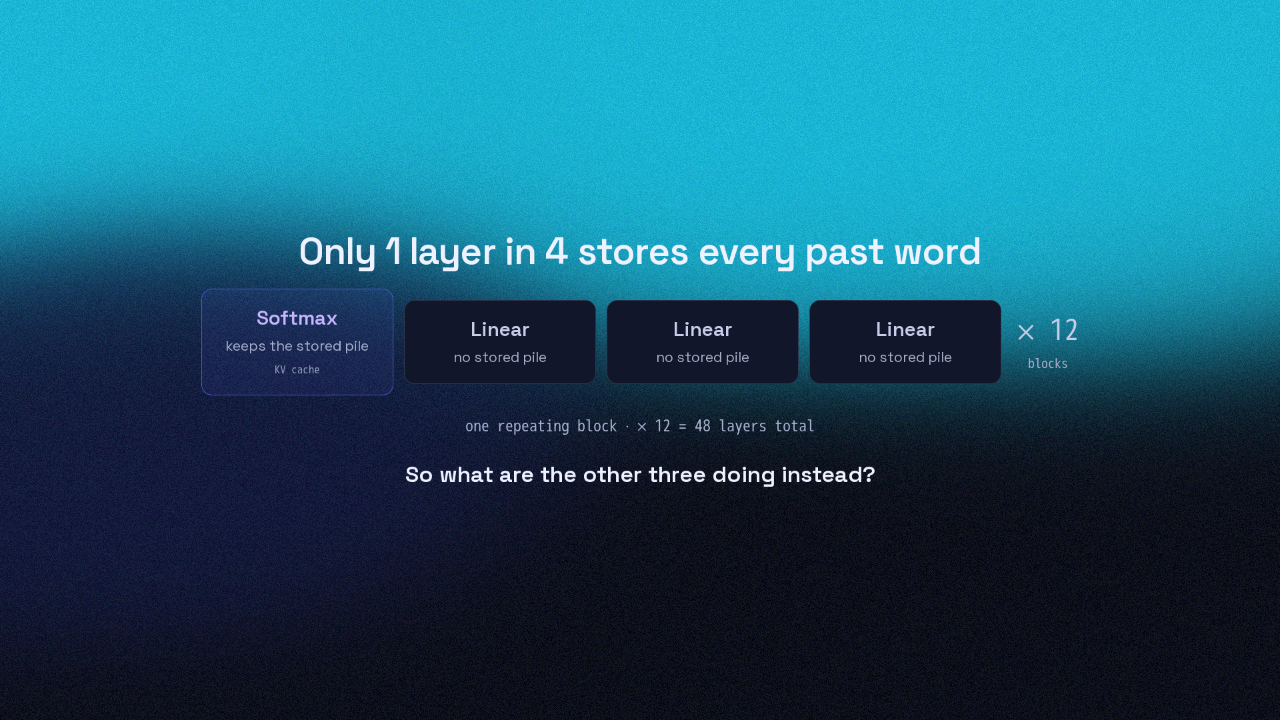
Only 1 layer in 4 stores every past word

Softmax
keeps the stored pile
KV cache
Linear
no stored pile
Linear
no stored pile
Linear
no stored pile
× 12
blocks
one repeating block · × 12 = 48 layers total
So what are the other three doing instead?

That expert setup is not the new part. What is new is how Solar Open 2 handles memory. A model runs each word through dozens of steps, called layers. In a normal layer, to write the next word, the model looks back over every word it has stored so far. Rereading that whole pile each time is what makes long chats slow and expensive. Solar Open 2 lets only one layer in four keep that pile. So what are the other three doing instead?

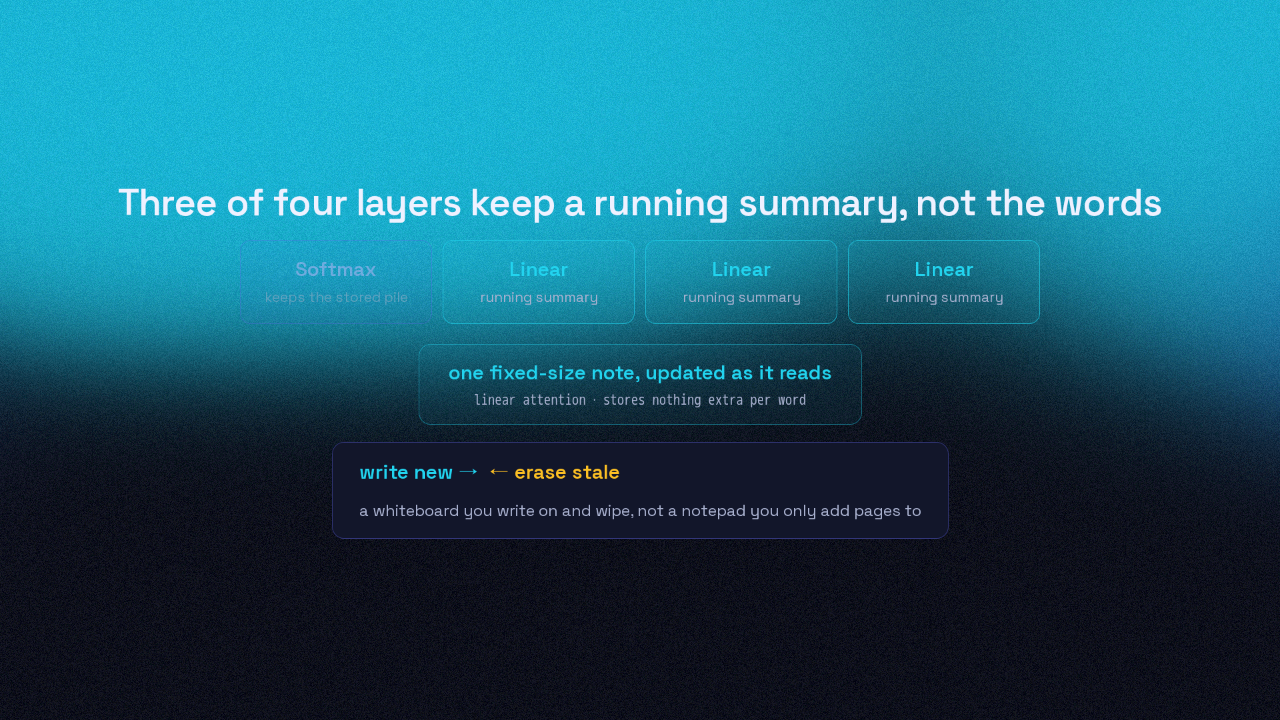
Three of four layers keep a running summary, not the words

Softmax
keeps the stored pile
Linear
running summary
Linear
running summary
Linear
running summary
one fixed-size note, updated as it reads
linear attention · stores nothing extra per word
write new →← erase stale
a whiteboard you write on and wipe, not a notepad you only add pages to

They keep a small running summary instead. As the model reads, each of these layers holds one fixed-size note and updates it with every new word. The real name for this is linear attention. Because that note never grows, these layers store nothing extra per word. That is what lets a million-word context stay affordable. And this note can do two things. It can write new facts in, and wipe old ones out. Picture a whiteboard you can write on and erase, not a notepad where you only keep adding pages. That erasing is what keeps one small note useful even after a million words, instead of letting it clog with stale facts.

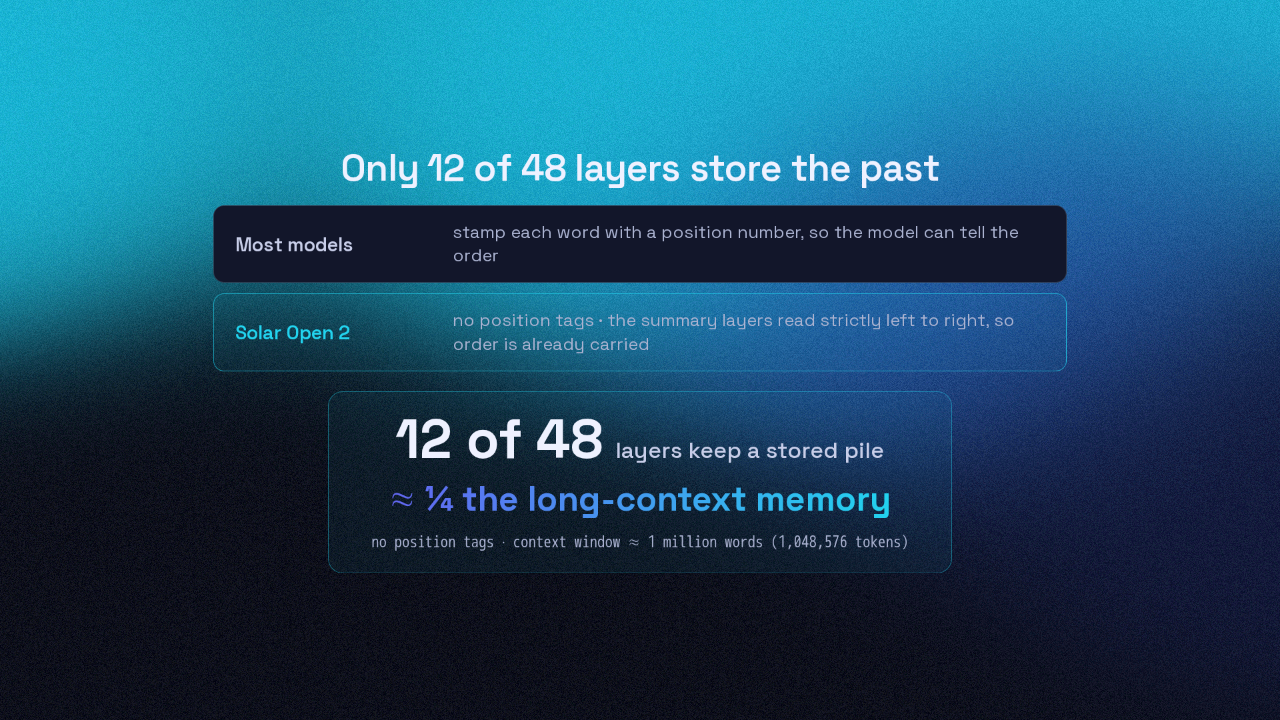
Only 12 of 48 layers store the past

Most models
stamp each word with a position number, so the model can tell the order
Solar Open 2
no position tags · the summary layers read strictly left to right, so order is already carried
12 of 48 layers keep a stored pile
≈ ¼ the long-context memory
no position tags · context window ≈ 1 million words (1,048,576 tokens)

Solar Open 2 also drops one thing almost every other model keeps, its position tags. Most models stamp each word with a number for its place in line, so the model can tell the order. Those tags are also what break when you push a model past the length it was trained on. Solar keeps none. It can, because the running-summary layers read strictly left to right, so the note already carries what came before. Dropping the tags is what stretches the window to a million words. Only twelve of the model's forty-eight layers still keep that growing pile of words. So its memory over a long input is about a quarter of a normal model the same size.

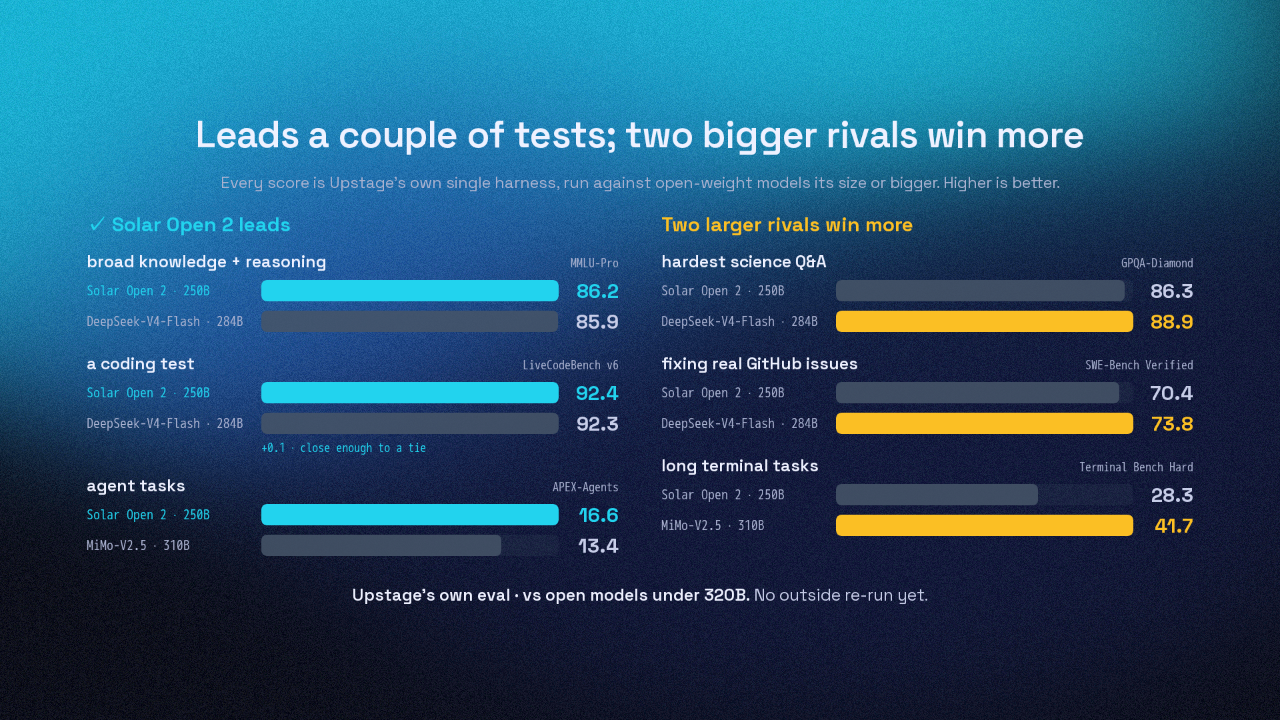
Leads a couple of tests; two bigger rivals win more

Every score is Upstage’s own single harness, run against open-weight models its size or bigger. Higher is better.
✓ Solar Open 2 leads
broad knowledge + reasoningMMLU-Pro
Solar Open 2 · 250B86.2
DeepSeek-V4-Flash · 284B85.9
a coding testLiveCodeBench v6
Solar Open 2 · 250B92.4
DeepSeek-V4-Flash · 284B92.3
+0.1 · close enough to a tie
agent tasksAPEX-Agents
Solar Open 2 · 250B16.6
MiMo-V2.5 · 310B13.4
Two larger rivals win more
hardest science Q&AGPQA-Diamond
Solar Open 2 · 250B86.3
DeepSeek-V4-Flash · 284B88.9
fixing real GitHub issuesSWE-Bench Verified
Solar Open 2 · 250B70.4
DeepSeek-V4-Flash · 284B73.8
long terminal tasksTerminal Bench Hard
Solar Open 2 · 250B28.3
MiMo-V2.5 · 310B41.7
Upstage’s own eval · vs open models under 320B. No outside re-run yet.

Every score here is Upstage's own testing, against other open models its size or bigger. Solar Open 2 leads a few. It tops MMLU Pro, a broad exam of knowledge and reasoning, at eighty-six point two. And it edges a coding test called LiveCodeBench, ninety-two point four to ninety-two point three, close enough to a tie. On many other tests, two larger rivals finish ahead, DeepSeek V4 Flash and MiMo. So Solar Open 2 holds its own against the strongest open models while being smaller, but it is not the outright leader. These numbers are Upstage's own, the only run of them so far.

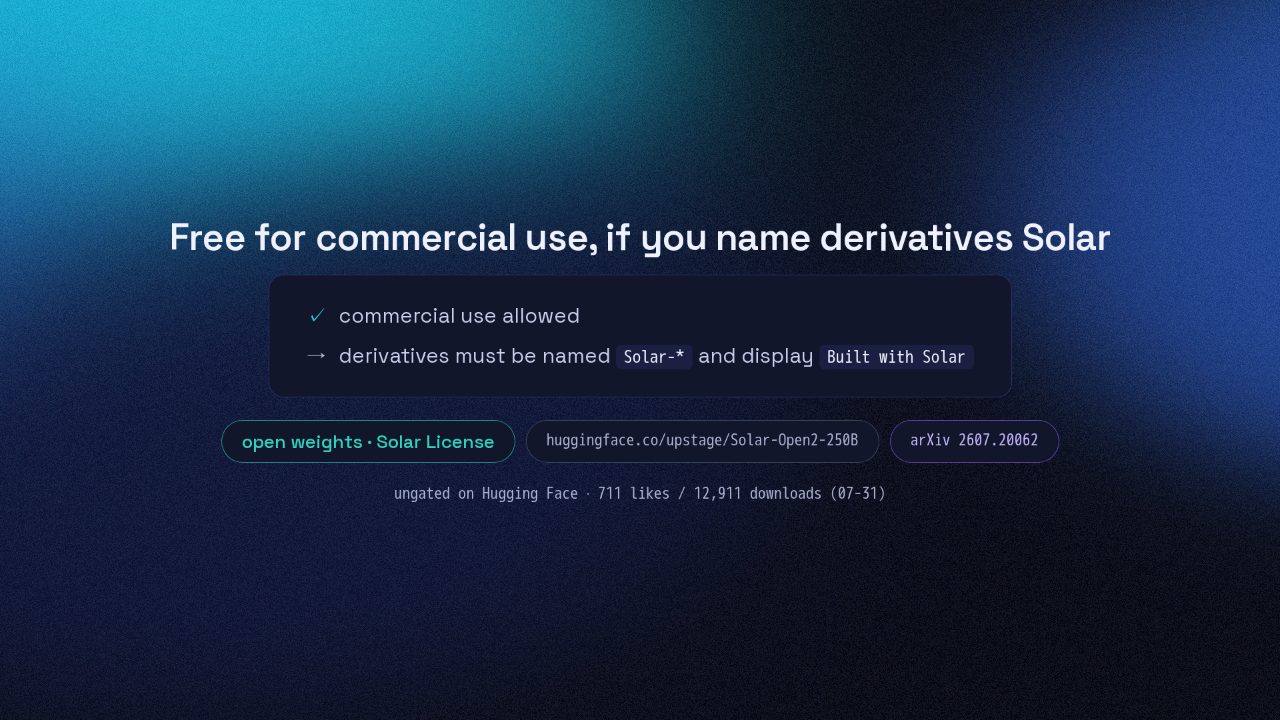
Free for commercial use, if you name derivatives Solar

✓commercial use allowed
→derivatives must be named Solar-* and display Built with Solar
open weights · Solar License huggingface.co/upstage/Solar-Open2-250B arXiv 2607.20062
ungated on Hugging Face · 711 likes / 12,911 downloads (07-31)

You can download the weights right now, and the full technical report is on arXiv. The license lets you use Solar Open 2 commercially. But if you build your own model on top of it, you have to name that model Solar and display the words Built with Solar. So these are open weights, not open source.

A million-word memory, kept as a running summary

Keep a running summary in place of every word

a 250B open model reads a million words on about a quarter of the memory
open weights · Solar License huggingface.co/upstage/Solar-Open2-250B

Most of what makes a long AI conversation expensive is the model holding on to every single word. Solar Open 2 keeps a short running summary on three of every four layers instead. That is how a model this large reads a whole shelf of books at once, on about a quarter of the memory. And you can download it today.


Up next

2:58

Apodex 1.1 mini · the same file, run alone and run as a team

@ai-ml-today · 1 month ago

3:09

Ornith-1.5 · an open model trained on problems it wrote for itself

@ai-ml-today · 1 month ago

3:08

MOSS-VL · an open 11B video model trained to decide, after every frame, whether to speak or stay silent

@ai-ml-today · 1 month ago

3:29

Qwen3.8-27B · a 27B open model anyone can download averages 84.3 across real desktop jobs on Qwen’s own run, and loses the widest row on its own card by nine points

@ai-ml-today · 1 month ago

3:15

MiLMMT-46-v1.0 · Xiaomi finished training an open translator on sentences that had no translation attached, and the scores it now leads on are produced by the two models that graded it

@ai-ml-today · 1 month ago

3:31

BDH-CQ — a 150M-parameter system that learns a puzzle rule from the worked examples in front of it and does its thinking as numbers, never as words

@ai-ml-today · 2 months ago

3:29

Muse Glimmer 30B, Meta’s open agent model, and the second tiny model that guesses sixteen words ahead so it runs fast on one consumer graphics card

@ai-ml-today · 2 months ago

3:05

JoyAI-Video-Edit, JD’s open 16B model that edits a video while the video is still playing, at about 30 frames a second on one Nvidia B200

@ai-ml-today · 2 months ago

3:26

Inkling-Small, Thinking Machines’ 12B-active / 276B open mixture-of-experts model that out-reasons its own 3.5× bigger flagship

@ai-ml-today · 2 months ago

3:42

Maple-Preview, DeepGrove’s 20-billion-parameter ternary reasoning model that runs on a Mac mini

@ai-ml-today · 2 months ago

3:16

Hunyuan3D-Buffalo, Tencent’s one model that builds, understands, and edits 3D from words

@ai-ml-today · 2 months ago

3:28

MiniMax H3, an open model that makes a video and its soundtrack in one pass

@ai-ml-today · 2 months ago









