Turn a PDF of math and tables into clean markdown, on your laptop
You have a PDF full of equations and tables. You copy the text out. The math turns to garbage and the table falls apart.
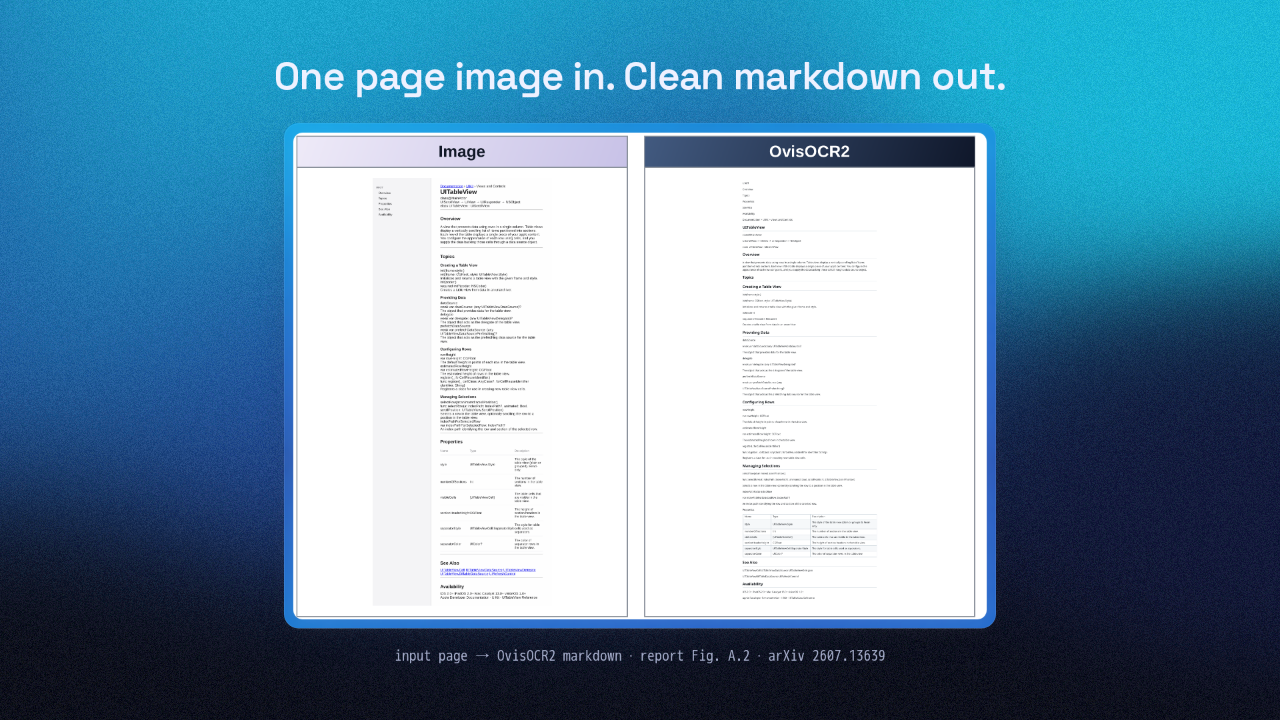
One page image in. Clean markdown out.

Turning a page back into clean text should be solved. It isn't. OvisOCR2 does it in one pass. You hand it one page image. It gives back clean markdown, with the running text in reading order, the formulas as LaTeX, and the tables laid out as tables. And it is small enough to run on your own laptop.
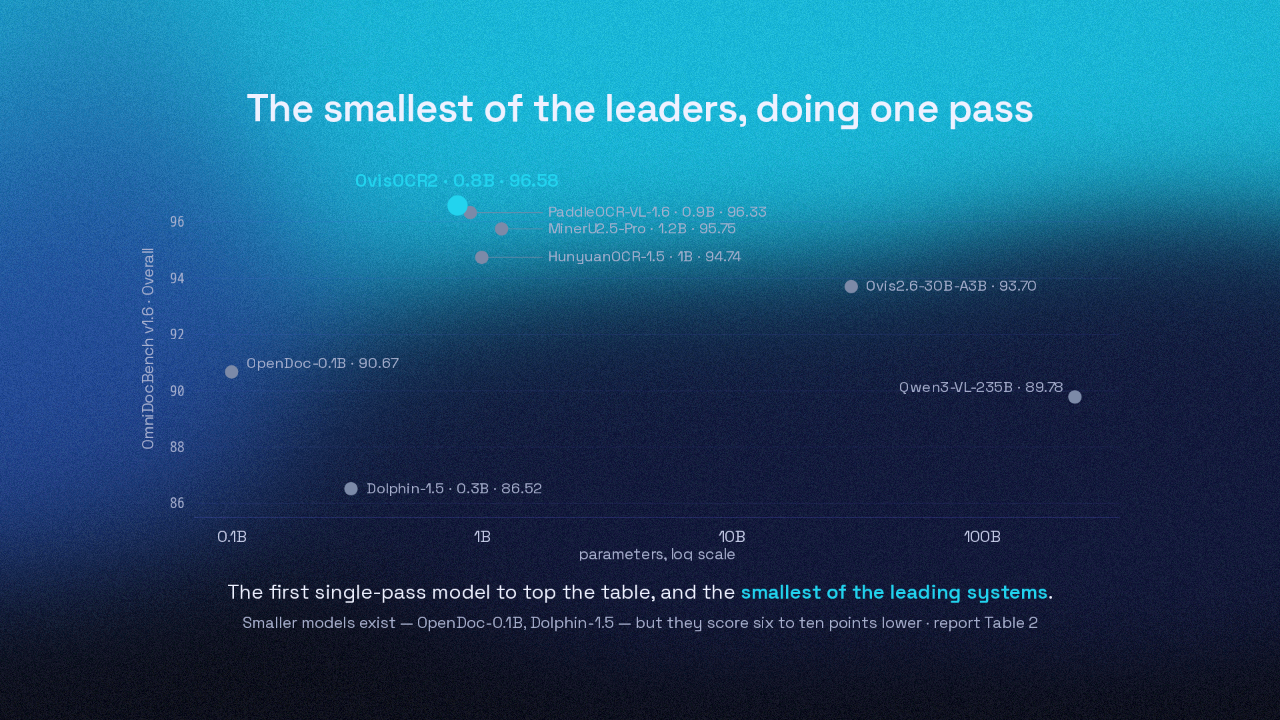
The smallest of the leaders, doing one pass
Page parsing has always belonged to pipelines. Find the layout, crop each region, run a separate OCR model on each one, then stitch it back into order. On this leaderboard the top spots were all pipelines. Single-pass models trailed. OvisOCR2 is the first single-pass model to top them, and it is the smallest of the leading systems on the board.
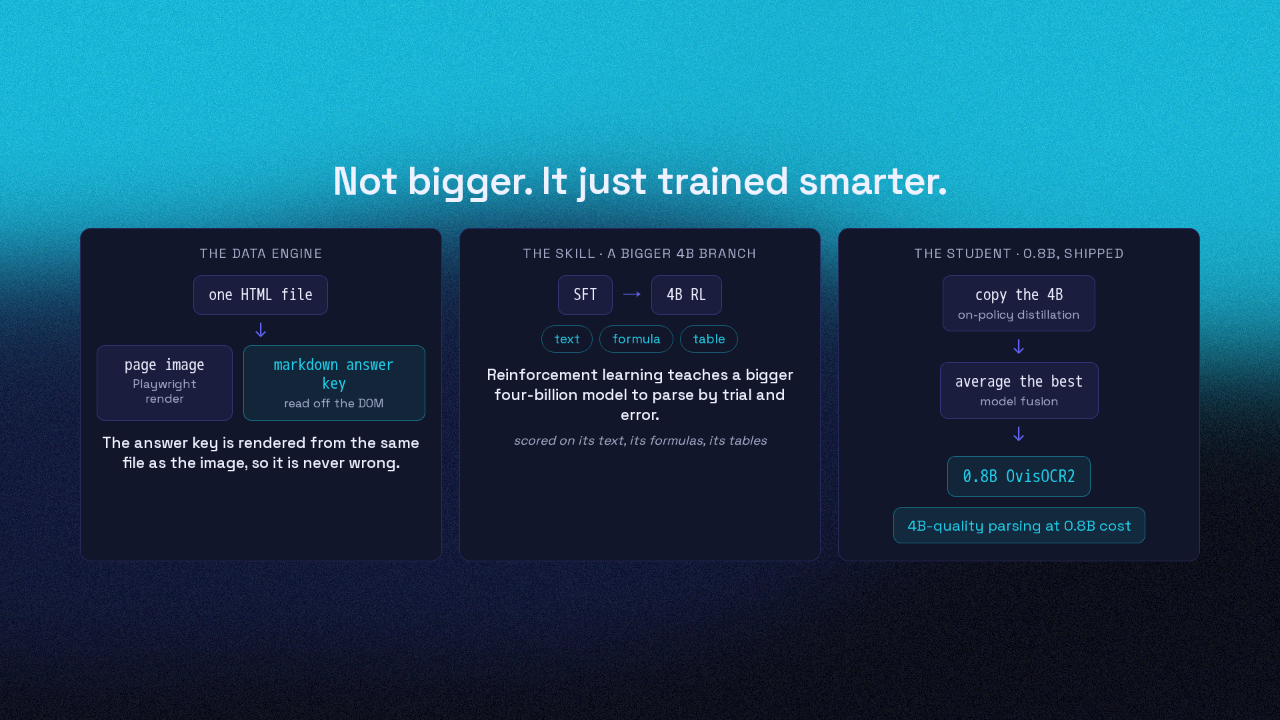
Not bigger. It just trained smarter.
So how does a model this small win? Not by size, but by how it trained. To parse a page you need its exact markdown. Labeling that by hand is slow and noisy. So they let a computer make both sides. It renders an HTML file to an image, then reads the markdown straight off that same HTML. The answer key is never wrong. Next, the skill. They do not reinforcement-train the small model directly. They train a bigger four-billion model to parse by trial and error, scored on its text, its formulas, and its tables. Then they teach the small model to copy that bigger one, and average the best versions into a single model. So the shipped model parses like the four-billion did, at a fraction of the cost.
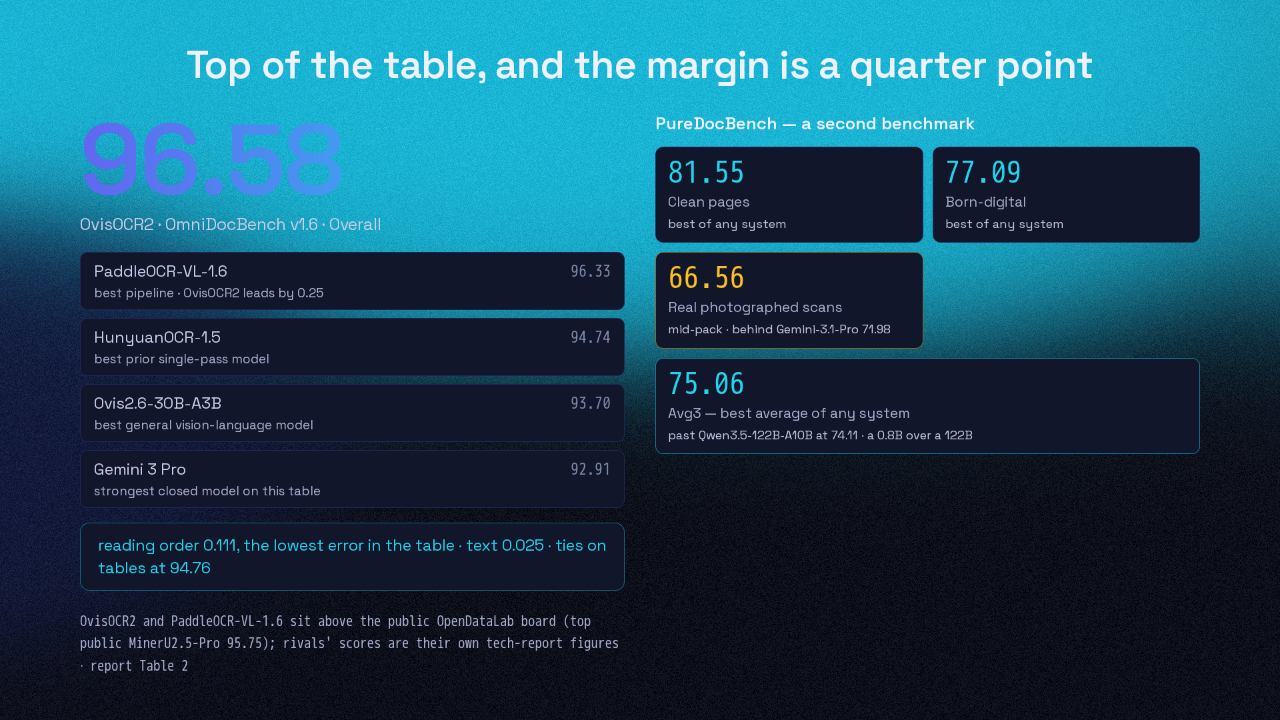
Top of the table, and the margin is a quarter point
On OmniDocBench, OvisOCR2 scores ninety-six point five eight overall, the top of the table. That is a quarter point over the best pipeline. Its cleanest wins are reading order and plain text; on tables it only ties. The margin is thin, and its closest rivals reported their own numbers. On a second benchmark it posts the best average of any system, winning clean and born-digital pages, and beating a model over a hundred times its size. On messy photographed scans it is mid-pack, behind Gemini three point one Pro.
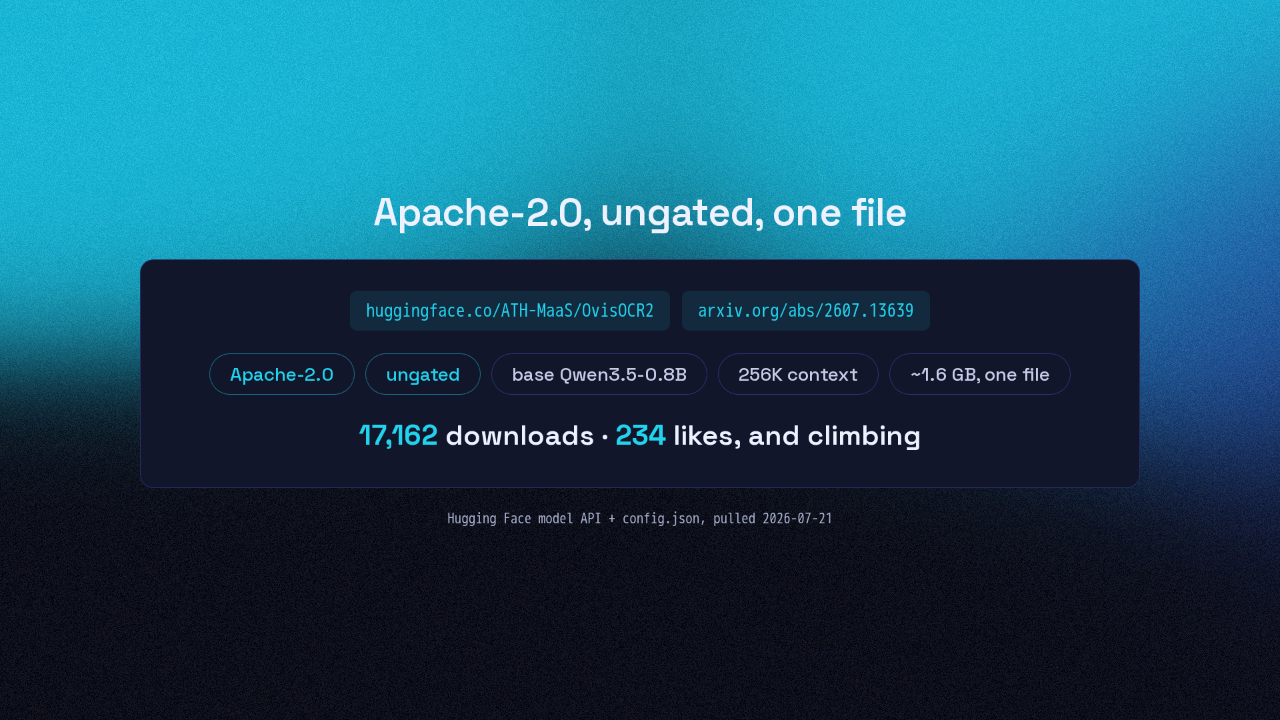
Apache-2.0, ungated, one file
You can get it on Hugging Face, Apache two, ungated. It is one file, under two gigabytes, small enough to run yourself. Seventeen thousand downloads so far, and climbing.
A page in. Clean markdown out. On a model you can run yourself.
So a page that used to come out as garbage now comes out as clean markdown, on a model you can run yourself. It got there by training on answer keys it printed itself. The page it still can't fully crack is the photographed real-world scan, the messy document most people actually need read.











