LongCat-2.0: Meituan's 1.6T model, zero Nvidia GPUs

2 months ago

Meituan is a food-delivery company. It just open-sourced LongCat-2.0, a one-point-six-trillion-parameter model trained on AI accelerators instead of Nvidia GPUs. The weights are already public, under MIT.

Ask

Ask about this presentation

Answers are generated from this presentation.

Chapters

  1. 0:00Slide 1
  2. 0:12The open weights behind "Owl Alpha"
  3. 0:25Trained end-to-end on AI accelerators, not GPUs
  4. 0:47SWE-bench Pro: 59.5, past GPT-5.5, short of Opus
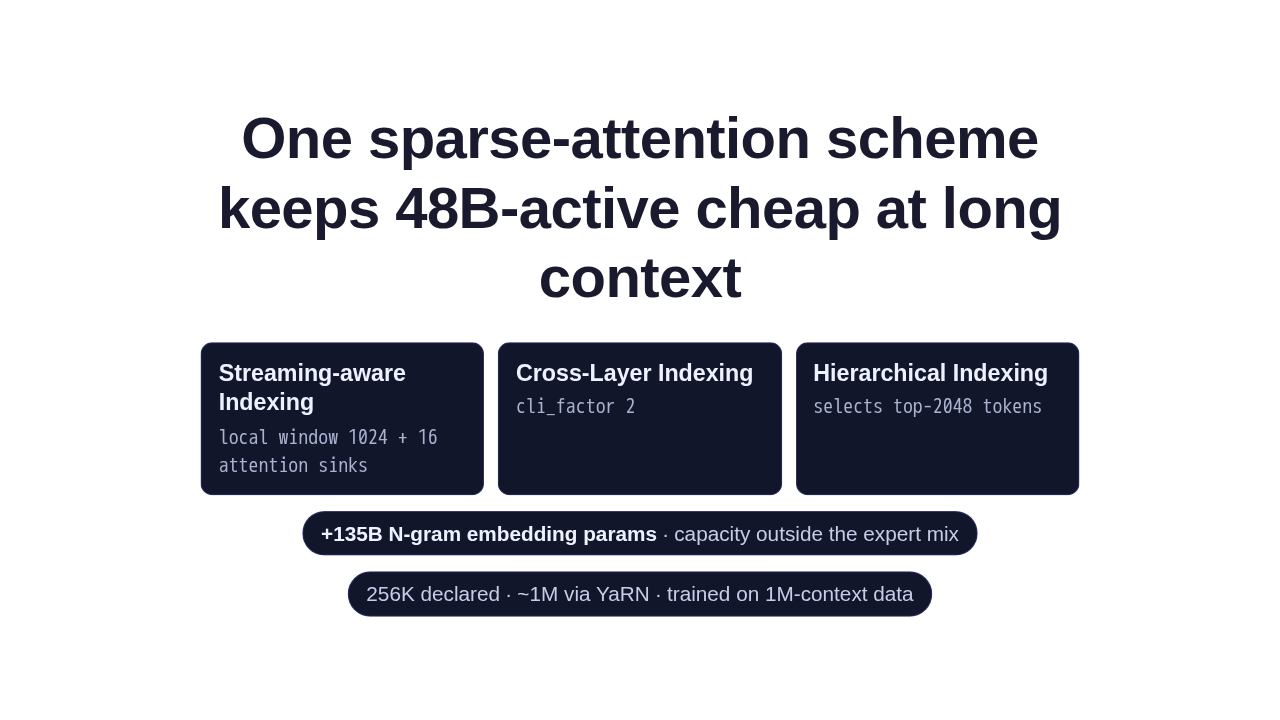
  5. 1:05One sparse-attention scheme keeps 48B-active cheap at long context
  6. 1:20What the leaderboard win leaves out
  7. 1:39Grab the weights
  8. 1:49Slide 8
Show transcript

Slide 1

LongCat-2.0: Meituan's 1.6T model, zero Nvidia GPUs
Open weights under MIT; ~48B of 1.6T parameters active per token.
Meituan MIT · weights + inference text-only 1.6T total · ~48B active/token

Meituan is a food-delivery company. It just open-sourced LongCat-2.0, a one-point-six-trillion-parameter model trained on AI accelerators instead of Nvidia GPUs. The weights are already public, under MIT.

The open weights behind "Owl Alpha"

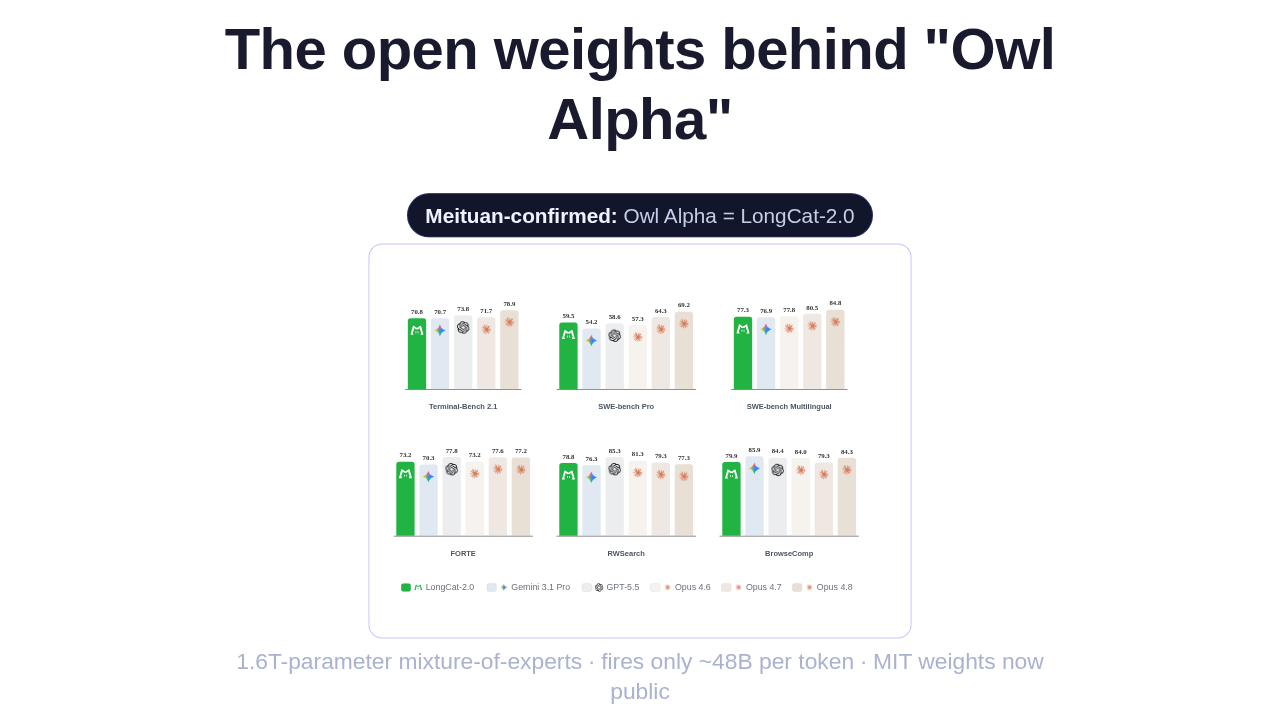
Meituan-confirmed: Owl Alpha = LongCat-2.0
Meituan's official agent-benchmark charts for LongCat-2.0 across six code and agent evals
1.6T-parameter mixture-of-experts · fires only ~48B per token · MIT weights now public

For two months, this model quietly ran near the top of OpenRouter's agent leaderboards under the codename Owl Alpha. Now the name and the weights are public: a one-point-six-trillion-parameter mixture-of-experts, released under MIT.

Trained end-to-end on AI accelerators, not GPUs

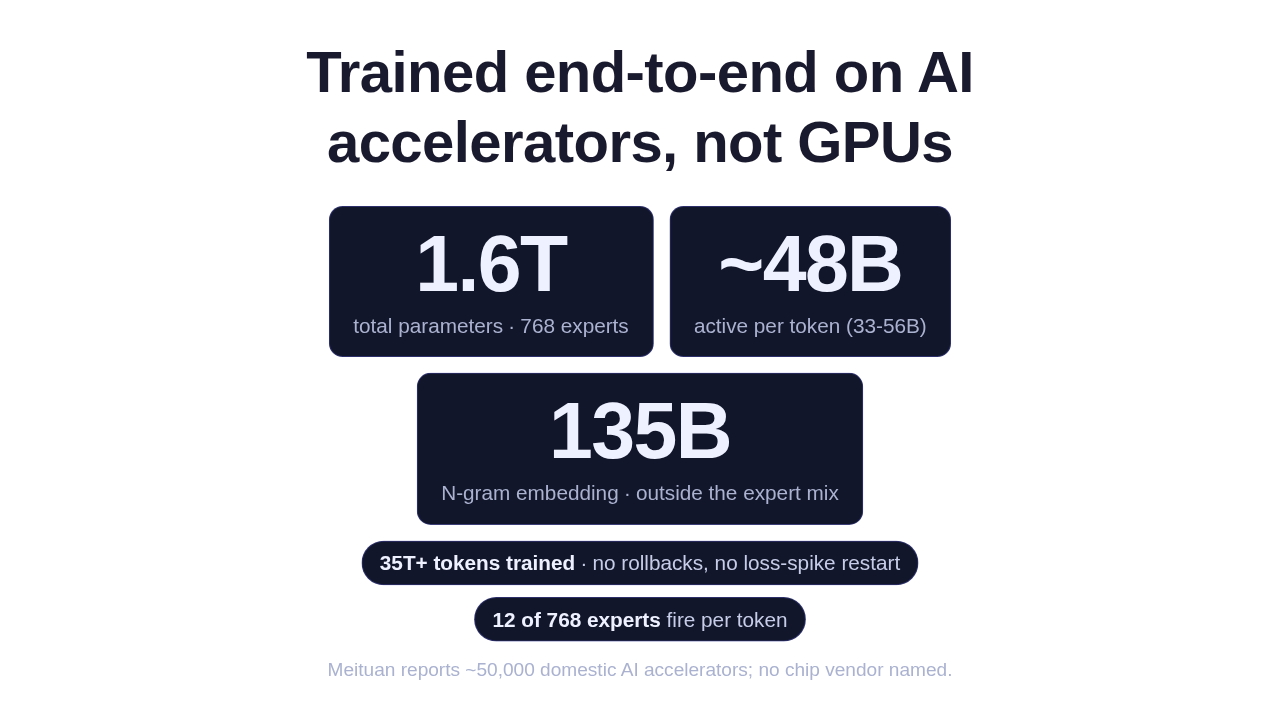
1.6T
total parameters · 768 experts
~48B
active per token (33-56B)
135B
N-gram embedding · outside the expert mix
35T+ tokens trained · no rollbacks, no loss-spike restart 12 of 768 experts fire per token
Meituan reports ~50,000 domestic AI accelerators; no chip vendor named.

The real story isn't a benchmark. It's how it was built. Pretraining ran across more than thirty-five trillion tokens, entirely on purpose-built AI accelerators, with no rollbacks and no irrecoverable loss-spike restarts. A frontier-scale model, trained end to end off the GPU. Only about forty-eight billion of its parameters fire per token, which is what makes that feasible.

SWE-bench Pro: 59.5, past GPT-5.5, short of Opus

Claude Opus 4.8
69.2
Claude Opus 4.7
64.3
LongCat-2.0
59.5
GPT-5.5
58.6
Claude Opus 4.6
57.3
Gemini 3.1 Pro
54.2
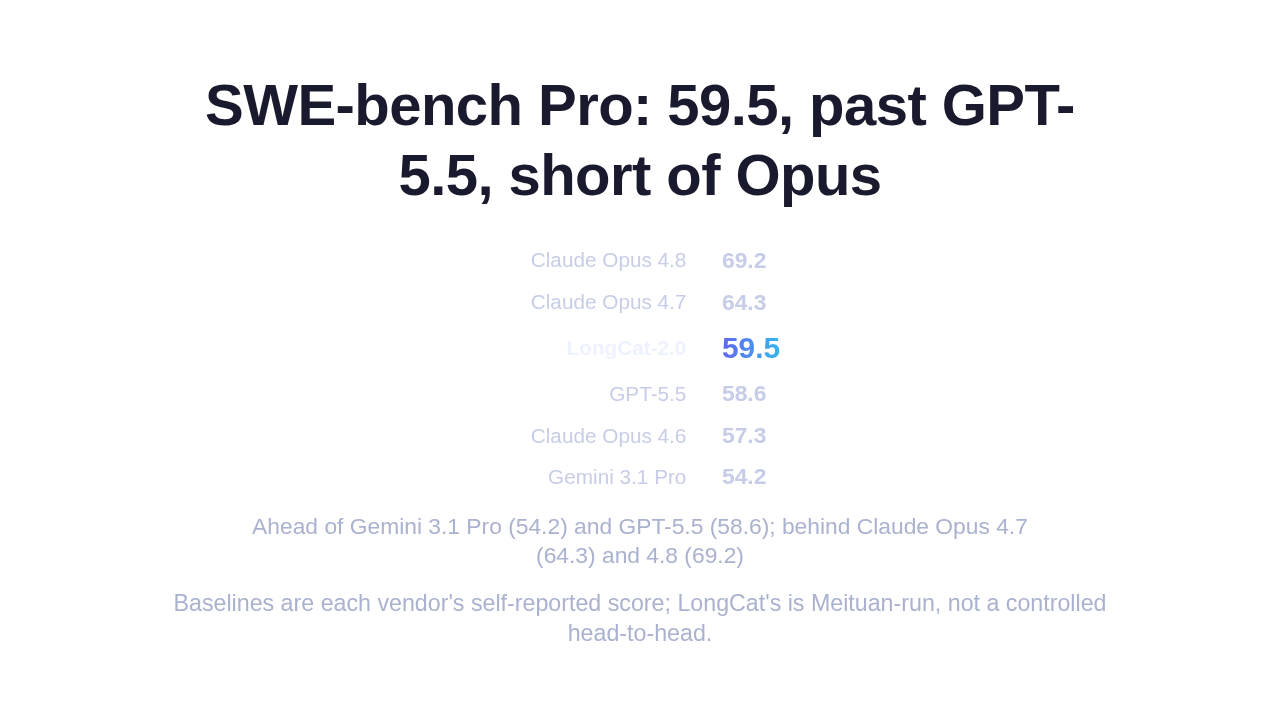
Ahead of Gemini 3.1 Pro (54.2) and GPT-5.5 (58.6); behind Claude Opus 4.7 (64.3) and 4.8 (69.2)
Baselines are each vendor's self-reported score; LongCat's is Meituan-run, not a controlled head-to-head.

On SWE-bench Pro, an agentic coding benchmark, LongCat scores fifty-nine point five. That's ahead of Gemini three point one Pro and GPT five point five, though still behind Claude Opus four point seven and four point eight. And every rival number there is the vendor's own reported score, not a test Meituan re-ran head-to-head.

One sparse-attention scheme keeps 48B-active cheap at long context

Streaming-aware Indexing
local window 1024 + 16 attention sinks
Cross-Layer Indexing
cli_factor 2
Hierarchical Indexing
selects top-2048 tokens
+135B N-gram embedding params · capacity outside the expert mix
256K declared · ~1M via YaRN · trained on 1M-context data

Two design choices keep it cheap at long context. A sparse-attention scheme that learns which tokens are worth attending to, and a hundred and thirty-five billion extra embedding parameters that add capacity outside the expert mix. It's trained on data with context up to a million tokens long.

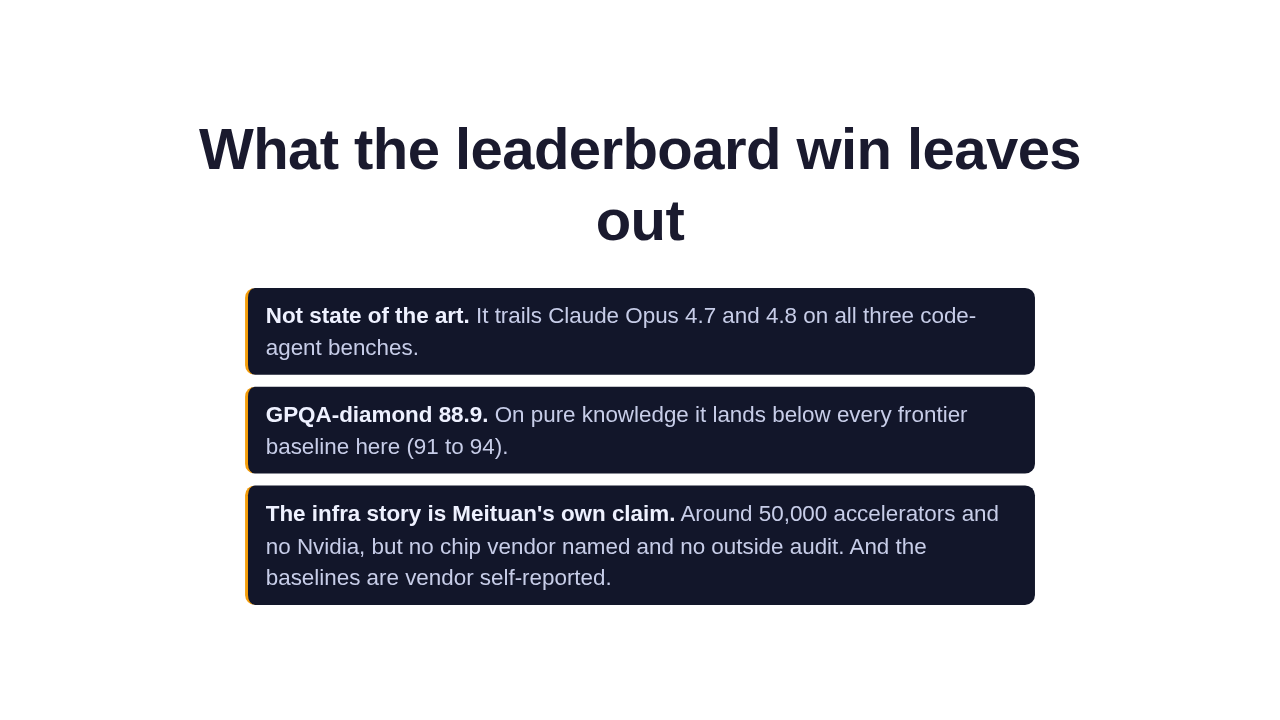
What the leaderboard win leaves out

Not state of the art. It trails Claude Opus 4.7 and 4.8 on all three code-agent benches.
GPQA-diamond 88.9. On pure knowledge it lands below every frontier baseline here (91 to 94).
The infra story is Meituan's own claim. Around 50,000 accelerators and no Nvidia, but no chip vendor named and no outside audit. And the baselines are vendor self-reported.

Three honest caveats. This isn't state of the art. It trails Claude Opus on every code-agent benchmark, and on GPQA-diamond, pure knowledge, it scores eighty-eight point nine, below every frontier model here. The cross-vendor comparison isn't controlled, and the hardware story is Meituan's own claim, with no chip vendor named and no outside audit.

Grab the weights

Weights + inference · MIT huggingface.co/meituan-longcat/LongCat-2.0
Tech report LongCat blog

The weights and inference code are on Hugging Face now, under the MIT license, so you can run it or build on it today. The full tech report is on Meituan's blog.

Slide 8

LongCat-2.0
A frontier-scale open model, trained end-to-end off the GPU.
huggingface.co/meituan-longcat/LongCat-2.0 · MIT

The headline here isn't a new leaderboard king. It's that a frontier-scale open model was trained end to end without a single Nvidia GPU. If that holds up, the map of what you can build these models on just got a lot wider.


Up next

2:58

Apodex 1.1 mini · the same file, run alone and run as a team

@ai-ml-today · 1 month ago

3:09

Ornith-1.5 · an open model trained on problems it wrote for itself

@ai-ml-today · 1 month ago

3:08

MOSS-VL · an open 11B video model trained to decide, after every frame, whether to speak or stay silent

@ai-ml-today · 1 month ago

3:29

Qwen3.8-27B · a 27B open model anyone can download averages 84.3 across real desktop jobs on Qwen’s own run, and loses the widest row on its own card by nine points

@ai-ml-today · 1 month ago

3:15

MiLMMT-46-v1.0 · Xiaomi finished training an open translator on sentences that had no translation attached, and the scores it now leads on are produced by the two models that graded it

@ai-ml-today · 1 month ago

3:31

BDH-CQ — a 150M-parameter system that learns a puzzle rule from the worked examples in front of it and does its thinking as numbers, never as words

@ai-ml-today · 2 months ago

3:29

Muse Glimmer 30B, Meta’s open agent model, and the second tiny model that guesses sixteen words ahead so it runs fast on one consumer graphics card

@ai-ml-today · 2 months ago

3:05

JoyAI-Video-Edit, JD’s open 16B model that edits a video while the video is still playing, at about 30 frames a second on one Nvidia B200

@ai-ml-today · 2 months ago

3:26

Inkling-Small, Thinking Machines’ 12B-active / 276B open mixture-of-experts model that out-reasons its own 3.5× bigger flagship

@ai-ml-today · 2 months ago

3:42

Maple-Preview, DeepGrove’s 20-billion-parameter ternary reasoning model that runs on a Mac mini

@ai-ml-today · 2 months ago

3:16

Hunyuan3D-Buffalo, Tencent’s one model that builds, understands, and edits 3D from words

@ai-ml-today · 2 months ago

3:28

MiniMax H3, an open model that makes a video and its soundtrack in one pass

@ai-ml-today · 2 months ago









