Mistral's Leanstral 1.5 beats Opus 4.6 on formal proof

2 months ago

Mistral just open-sourced a proof model that fires six and a half billion parameters per token, and out-proves models many times its size. The weights are already public, under Apache two.

Ask

Ask about this presentation

Answers are generated from this presentation.

Chapters

  1. 0:00Slide 1
  2. 0:09Top open prover on PutnamBench: 587 of 672
  3. 0:21It doesn't just solve problems. It operates the tools.
  4. 0:39Beats Opus 4.6 on formal proof: pass@8 43.2 vs 39.6
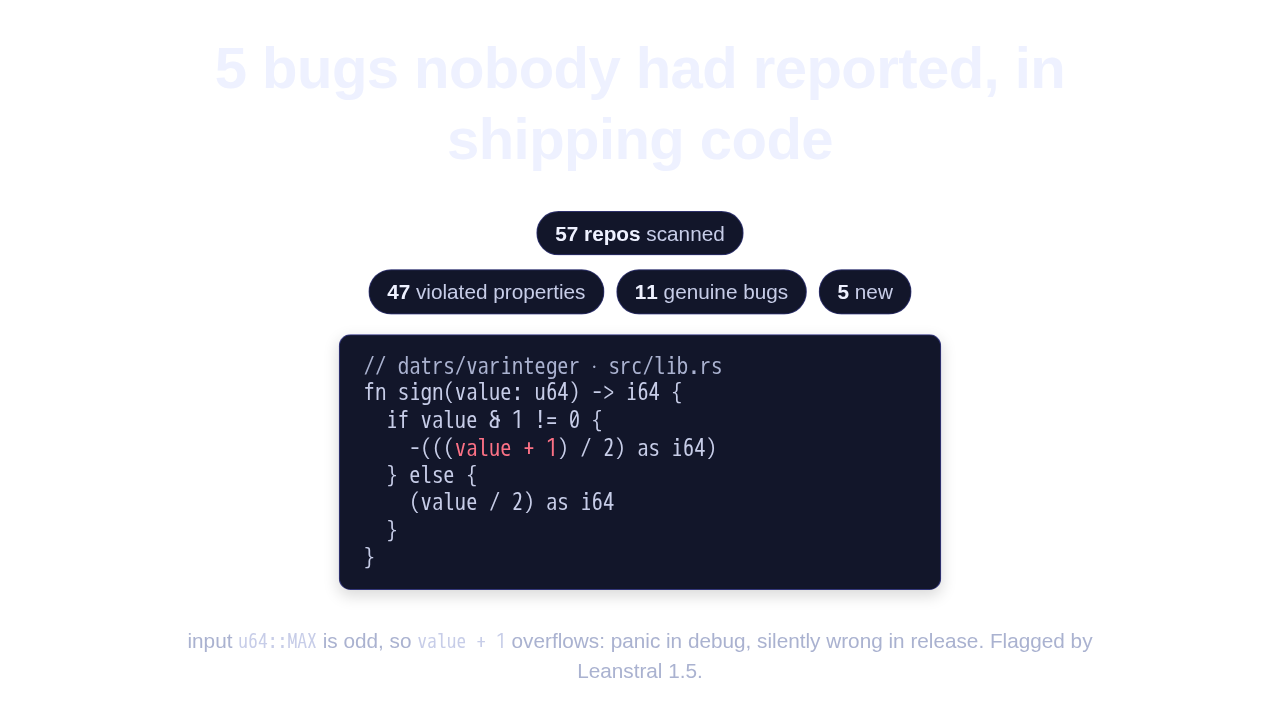
  5. 0:595 bugs nobody had reported, in shipping code
  6. 1:21Read the fine print: whose benchmarks, and at what budget
  7. 1:45Open weights on Hugging Face · Apache-2.0 · free API
  8. 1:51Slide 8
Show transcript

Slide 1

Mistral's Leanstral 1.5 beats Opus 4.6 on formal proof
The open model that proves math (and finds real bugs)
Mistral Apache-2.0 119B total · 6.5B active/token Lean 4

Mistral just open-sourced a proof model that fires six and a half billion parameters per token, and out-proves models many times its size. The weights are already public, under Apache two.

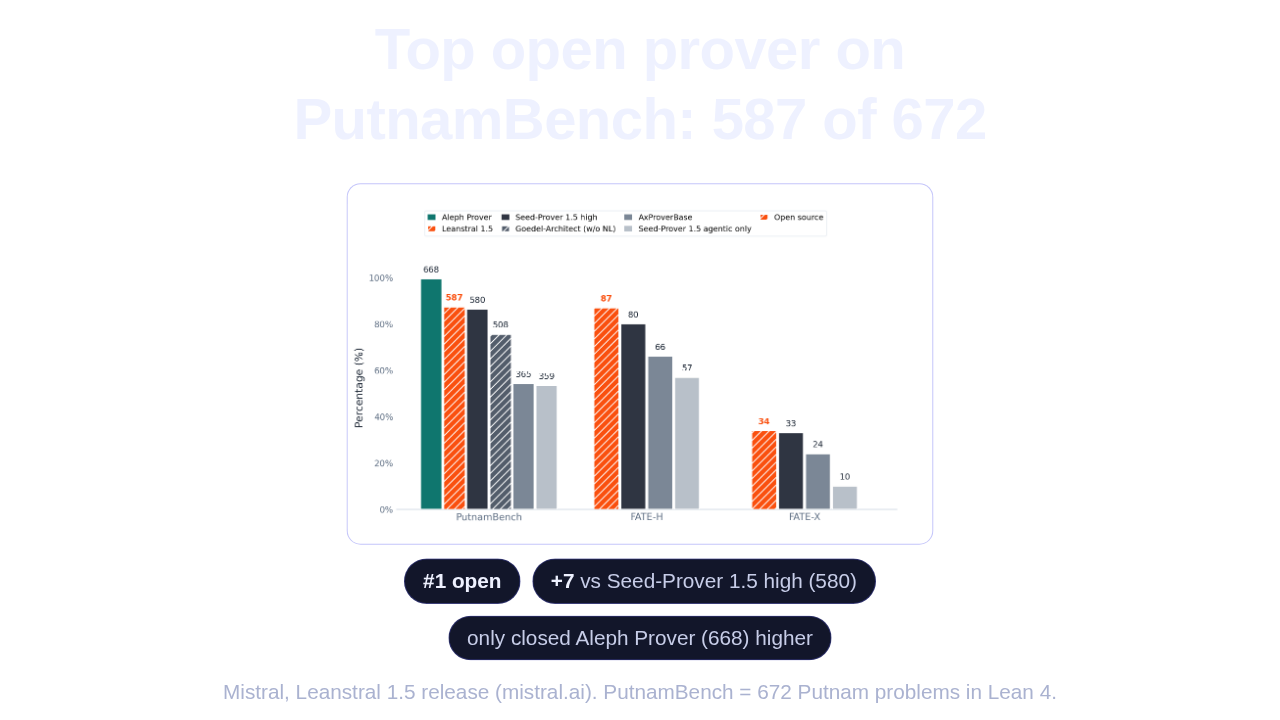
Top open prover on PutnamBench: 587 of 672

Grouped bar chart from Mistral's release: PutnamBench, FATE-H and FATE-X scores for Leanstral 1.5 versus Aleph Prover, Seed-Prover 1.5 and others
#1 open +7 vs Seed-Prover 1.5 high (580) only closed Aleph Prover (668) higher
Mistral, Leanstral 1.5 release (mistral.ai). PutnamBench = 672 Putnam problems in Lean 4.

On PutnamBench, six hundred and seventy-two Putnam problems in Lean four, it solves five hundred eighty-seven. Mistral says that's the top open prover, seven ahead of Seed-Prover, and second only to one closed system.

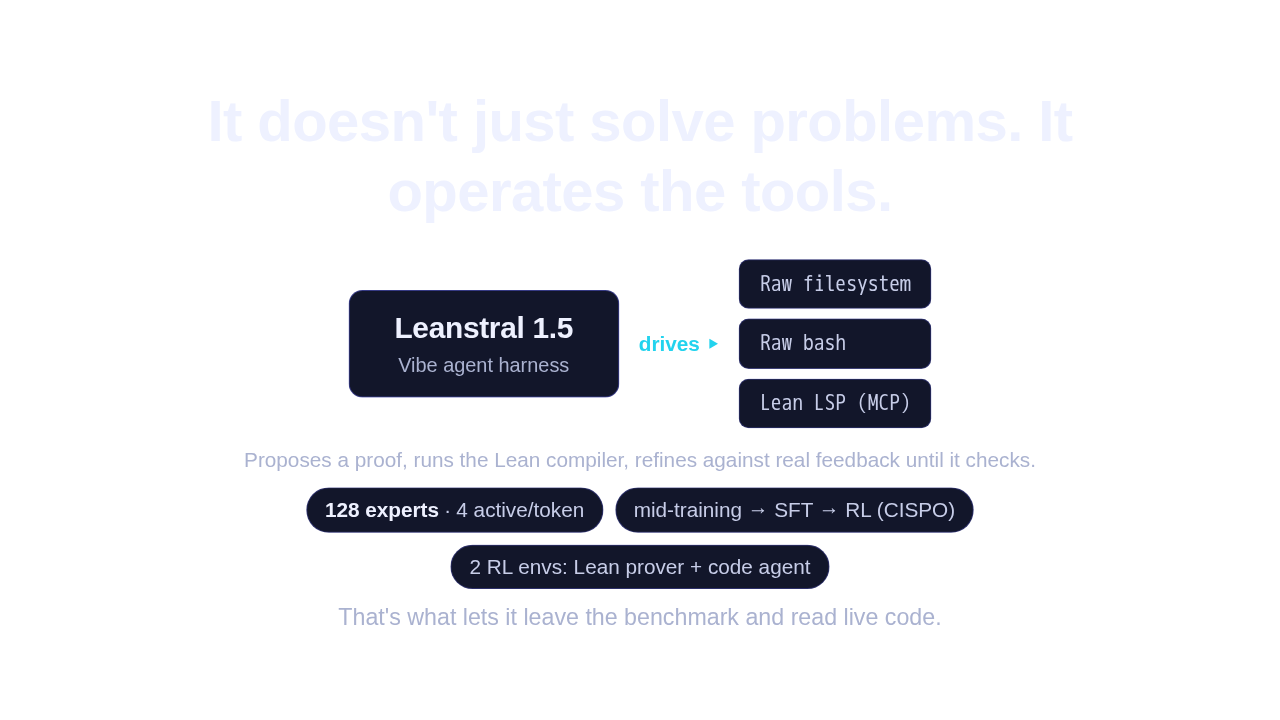
It doesn't just solve problems. It operates the tools.

Leanstral 1.5
Vibe agent harness
drives ▸
Raw filesystem
Raw bash
Lean LSP (MCP)
Proposes a proof, runs the Lean compiler, refines against real feedback until it checks.
128 experts · 4 active/token mid-training → SFT → RL (CISPO) 2 RL envs: Lean prover + code agent
That's what lets it leave the benchmark and read live code.

The novelty isn't the score, it's how it gets there. Only four of its hundred and twenty-eight experts fire per token, and it's trained as an agent: it drives a filesystem, a shell, and the Lean compiler, refining each proof against real feedback until it checks. That's what lets it leave the benchmark and read live code.

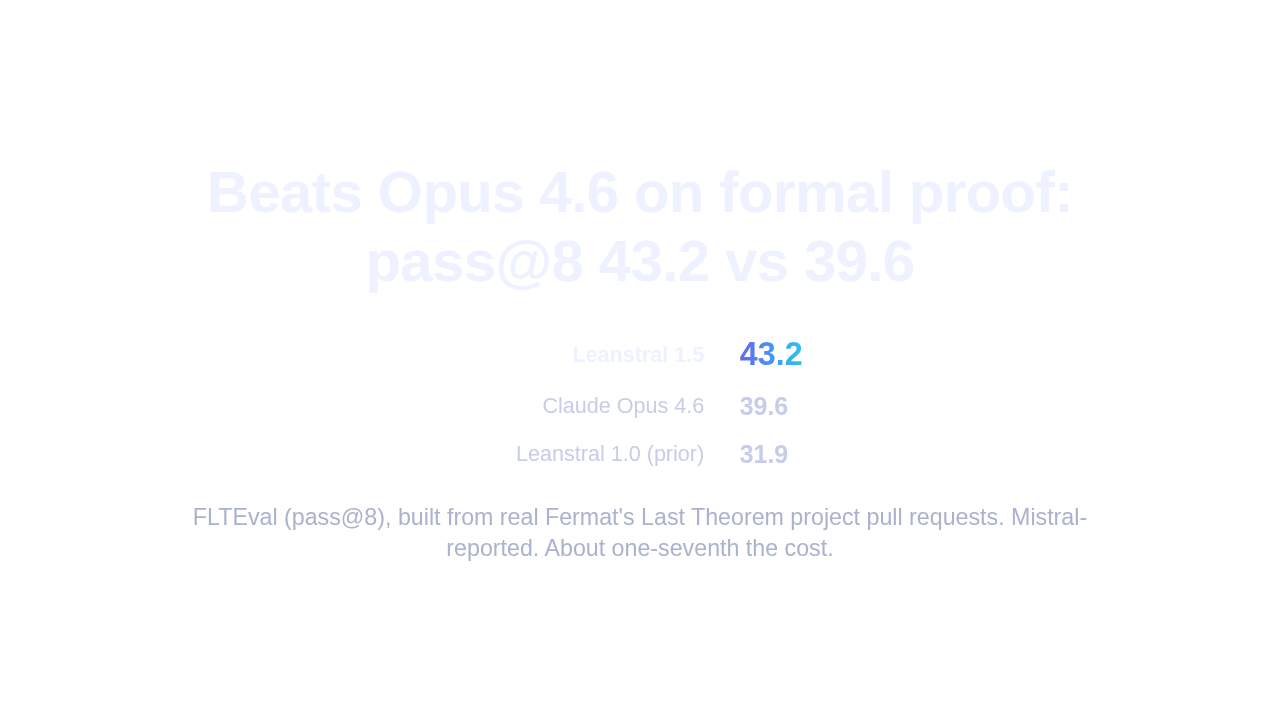
Beats Opus 4.6 on formal proof: pass@8 43.2 vs 39.6

Leanstral 1.5
43.2
Claude Opus 4.6
39.6
Leanstral 1.0 (prior)
31.9
FLTEval (pass@8), built from real Fermat's Last Theorem project pull requests. Mistral-reported. About one-seventh the cost.

Then there's this. On Mistral's FLTEval benchmark, the tiny open model scores forty-three point two at pass eight. That beats Claude Opus four point six, at thirty-nine point six, on formal proof, for about a seventh of the cost. And FLTEval is built from real pull requests in the Fermat's Last Theorem project, not a synthetic set.

5 bugs nobody had reported, in shipping code

57 repos scanned
47 violated properties 11 genuine bugs 5 new
// datrs/varinteger · src/lib.rs
fn sign(value: u64) -> i64 {
  if value & 1 != 0 {
    -(((value + 1) / 2) as i64)
  } else {
    (value / 2) as i64
  }
}
input u64::MAX is odd, so value + 1 overflows: panic in debug, silently wrong in release. Flagged by Leanstral 1.5.

Because it can run code, Mistral pointed it at fifty-seven real repositories. It flagged forty-seven violated properties, eleven genuine bugs, and five nobody had reported before. One was a sign function in a Rust varint library that overflows on the largest unsigned integer, panicking in debug and silently returning the wrong value in release. A proof found it, in shipping code.

Read the fine print: whose benchmarks, and at what budget

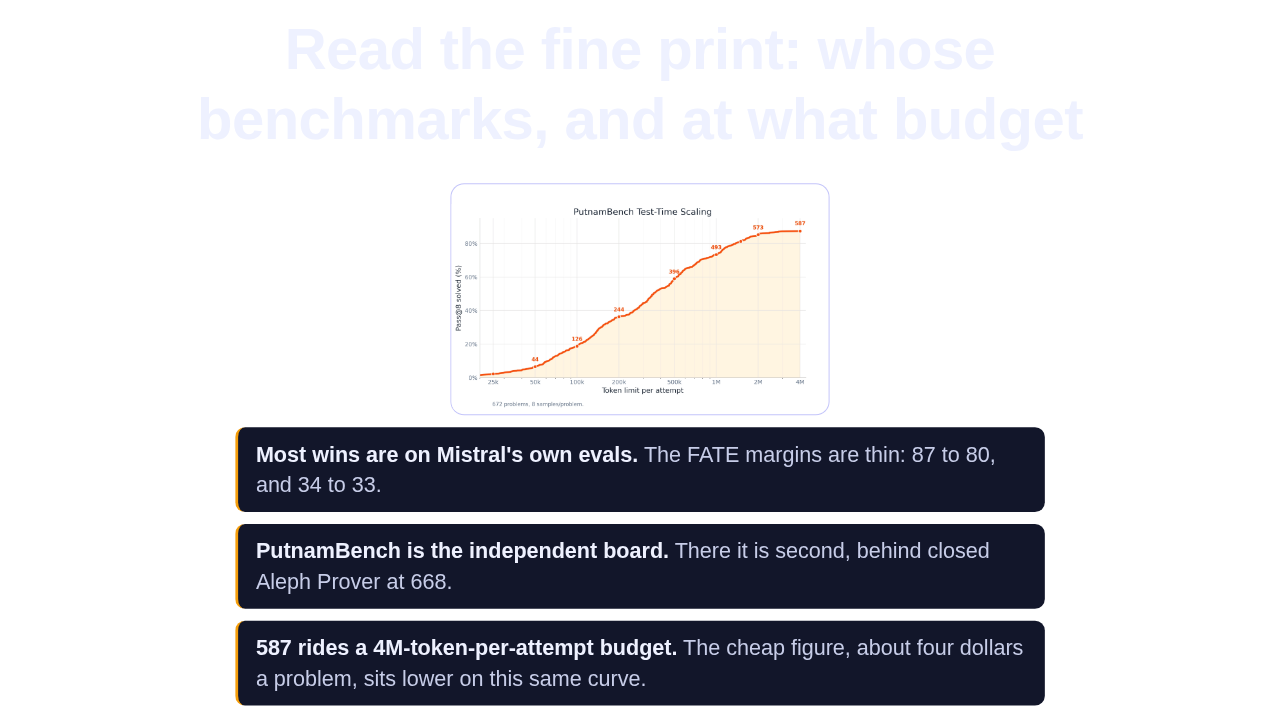
PutnamBench test-time scaling curve: pass@8 solved rises from 44 at a 50k-token budget to 587 at a 4-million-token budget
Most wins are on Mistral's own evals. The FATE margins are thin: 87 to 80, and 34 to 33.
PutnamBench is the independent board. There it is second, behind closed Aleph Prover at 668.
587 rides a 4M-token-per-attempt budget. The cheap figure, about four dollars a problem, sits lower on this same curve.

Now the honest asterisks. Most of those wins are on Mistral's own evals, and the margins are thin: eighty-seven to eighty, thirty-four to thirty-three. The one independent board is PutnamBench, where it's second, behind a closed system that solves six hundred sixty-eight. And that headline five eighty-seven rides a four-million-token budget per problem. The cheap four-dollar figure sits lower on the same curve.

Open weights on Hugging Face · Apache-2.0 · free API

Weights · Apache-2.0 huggingface.co/mistralai/Leanstral-1.5-119B-A6B
API free hosted endpoint, model leanstral-1-5
Release mistral.ai/news/leanstral-1-5

And it's genuinely open. Full weights on Hugging Face under Apache two, plus a free hosted endpoint if you'd rather just call it.

Slide 8

Leanstral 1.5
Machine-checked proof used to be closed and expensive.
One release made it cheap, open, and normal.
huggingface.co/mistralai/Leanstral-1.5-119B-A6B · Apache-2.0

The shift is simple. Machine-checked proof used to be closed and expensive. One release made it cheap and open. Now watch whether the public Putnam leaderboard confirms these numbers out in the open.


Up next

2:58

Apodex 1.1 mini · the same file, run alone and run as a team

@ai-ml-today · 1 month ago

3:09

Ornith-1.5 · an open model trained on problems it wrote for itself

@ai-ml-today · 1 month ago

3:08

MOSS-VL · an open 11B video model trained to decide, after every frame, whether to speak or stay silent

@ai-ml-today · 1 month ago

3:29

Qwen3.8-27B · a 27B open model anyone can download averages 84.3 across real desktop jobs on Qwen’s own run, and loses the widest row on its own card by nine points

@ai-ml-today · 1 month ago

3:15

MiLMMT-46-v1.0 · Xiaomi finished training an open translator on sentences that had no translation attached, and the scores it now leads on are produced by the two models that graded it

@ai-ml-today · 1 month ago

3:31

BDH-CQ — a 150M-parameter system that learns a puzzle rule from the worked examples in front of it and does its thinking as numbers, never as words

@ai-ml-today · 2 months ago

3:29

Muse Glimmer 30B, Meta’s open agent model, and the second tiny model that guesses sixteen words ahead so it runs fast on one consumer graphics card

@ai-ml-today · 2 months ago

3:05

JoyAI-Video-Edit, JD’s open 16B model that edits a video while the video is still playing, at about 30 frames a second on one Nvidia B200

@ai-ml-today · 2 months ago

3:26

Inkling-Small, Thinking Machines’ 12B-active / 276B open mixture-of-experts model that out-reasons its own 3.5× bigger flagship

@ai-ml-today · 2 months ago

3:42

Maple-Preview, DeepGrove’s 20-billion-parameter ternary reasoning model that runs on a Mac mini

@ai-ml-today · 2 months ago

3:16

Hunyuan3D-Buffalo, Tencent’s one model that builds, understands, and edits 3D from words

@ai-ml-today · 2 months ago

3:28

MiniMax H3, an open model that makes a video and its soundtrack in one pass

@ai-ml-today · 2 months ago









