Kimi K3 — the open model you can download that reaches the closed frontier

2 months ago

A model you can download for free just pulled level with the best paid AI from OpenAI and Anthropic on a real set of tasks. This is Kimi K3, from Moonshot. The surprising part is how you fit something with trillions of internal numbers onto real computers at all.

Ask

Ask about this presentation

Answers are generated from this presentation.

Chapters

  1. 0:00Kimi K3 — the open model that reaches the closed frontier
  2. 0:132.8 trillion numbers, only 104 billion awake per word
  3. 0:29The first open model to reach the closed frontier
  4. 0:49Three cuts that make a 2.8-trillion-number model runnable
  5. 1:29Wins a real cluster, loses its own coding bench
  6. 1:55Free to download, but not fully open source
  7. 2:09The frontier is no longer only for rent
Show transcript

Kimi K3 — the open model that reaches the closed frontier

Kimi K3

The open model you can download that keeps up with the paid frontier.
Moonshot AI Kimi K3 License · open weights text + image 2.8T total · 104B active per word

A model you can download for free just pulled level with the best paid AI from OpenAI and Anthropic on a real set of tasks. This is Kimi K3, from Moonshot. The surprising part is how you fit something with trillions of internal numbers onto real computers at all.

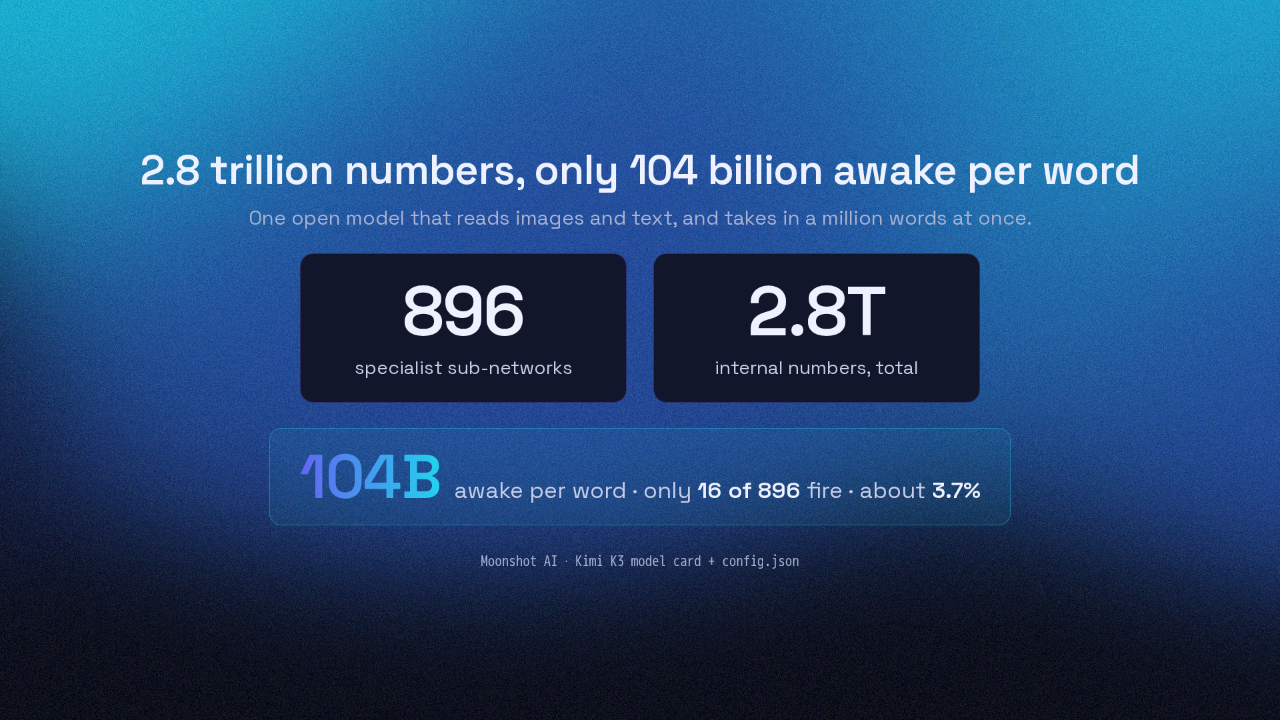
2.8 trillion numbers, only 104 billion awake per word

One open model that reads images and text, and takes in a million words at once.
896
specialist sub-networks
2.8T
internal numbers, total
104B awake per word · only 16 of 896 fire · about 3.7%
Moonshot AI · Kimi K3 model card + config.json

Kimi K3 is built as hundreds of small specialist sub-networks. Together they hold two-point-eight trillion internal numbers. But for each word, the model wakes only about a hundred and four billion of them. Kimi K3 also reads images, not just text, and takes in a million words at once, about a small library's worth.

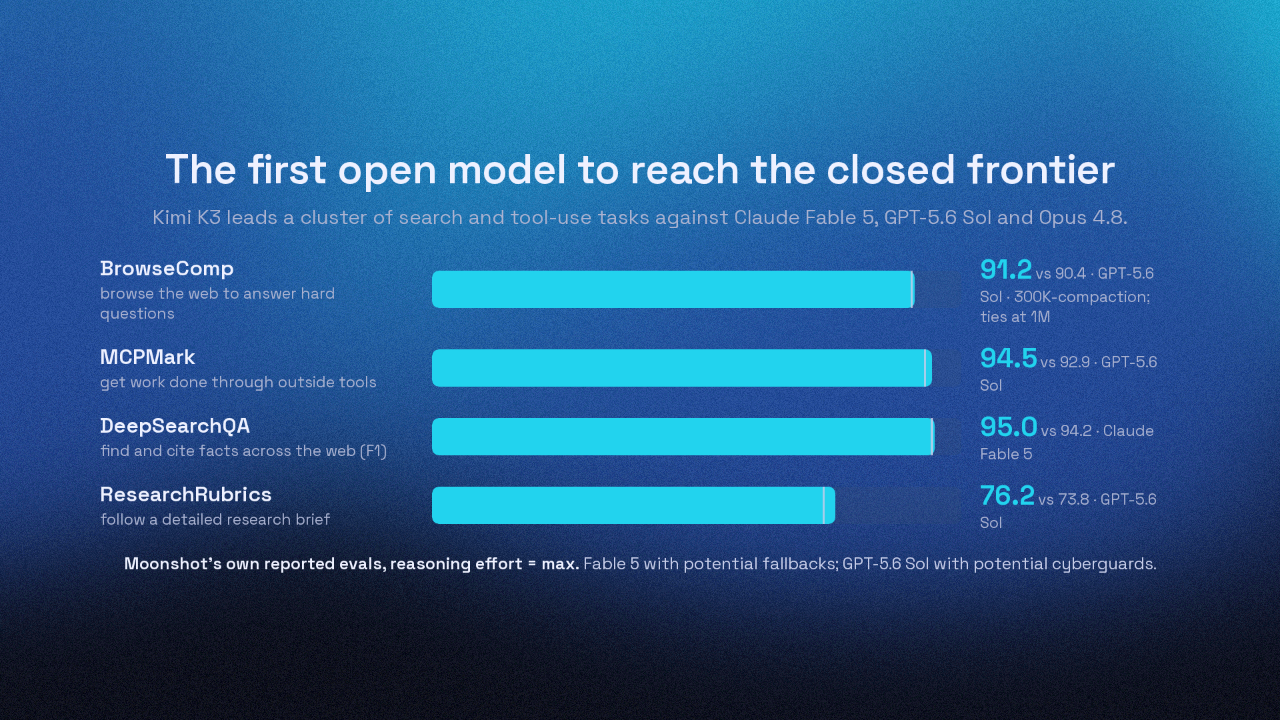
The first open model to reach the closed frontier

Kimi K3 leads a cluster of search and tool-use tasks against Claude Fable 5, GPT-5.6 Sol and Opus 4.8.
BrowseComp
browse the web to answer hard questions
91.2 vs 90.4 · GPT-5.6 Sol · 300K-compaction; ties at 1M
MCPMark
get work done through outside tools
94.5 vs 92.9 · GPT-5.6 Sol
DeepSearchQA
find and cite facts across the web (F1)
95.0 vs 94.2 · Claude Fable 5
ResearchRubrics
follow a detailed research brief
76.2 vs 73.8 · GPT-5.6 Sol
Moonshot's own reported evals, reasoning effort = max. Fable 5 with potential fallbacks; GPT-5.6 Sol with potential cyberguards.

The strongest models have been paid and closed. Kimi K3 is the first open model you can download that trades blows with that closed frontier. On Moonshot's own reported tests, at maximum effort, it wins a real cluster of tasks that use web search and outside tools. It tops BrowseComp, an AI browsing the web to answer hard questions, just past GPT-5.6.

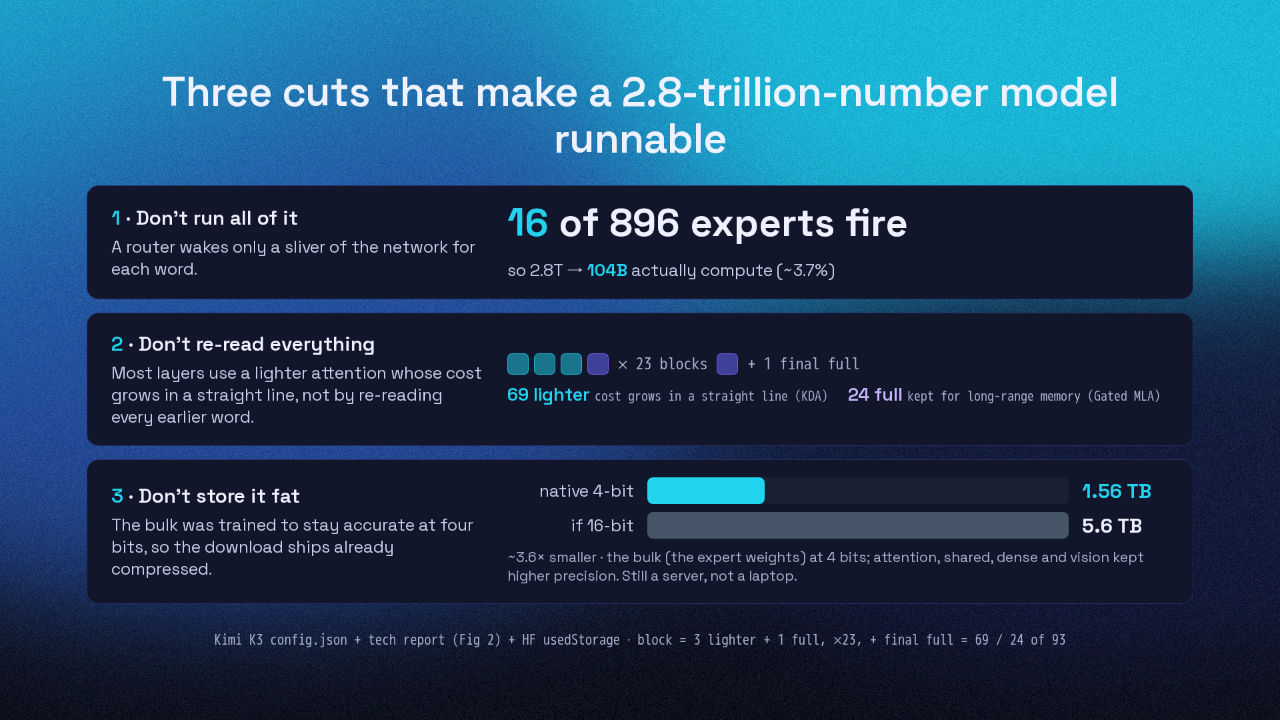
Three cuts that make a 2.8-trillion-number model runnable

1 · Don't run all of it
A router wakes only a sliver of the network for each word.
16 of 896 experts fire
so 2.8T → 104B actually compute (~3.7%)
2 · Don't re-read everything
Most layers use a lighter attention whose cost grows in a straight line, not by re-reading every earlier word.
× 23 blocks + 1 final full
69 lighter cost grows in a straight line (KDA) 24 full kept for long-range memory (Gated MLA)
3 · Don't store it fat
The bulk was trained to stay accurate at four bits, so the download ships already compressed.
native 4-bit
1.56 TB
if 16-bit
5.6 TB
~3.6× smaller · the bulk (the expert weights) at 4 bits; attention, shared, dense and vision kept higher precision. Still a server, not a laptop.
Kimi K3 config.json + tech report (Fig 2) + HF usedStorage · block = 3 lighter + 1 full, ×23, + final full = 69 / 24 of 93

So how do you train and run a model with trillions of internal numbers at all? Three cuts. First, don't run all of it. For each word, a router wakes just sixteen of eight hundred and ninety-six sub-networks. So only about a hundred and four billion numbers actually compute. Second, don't re-read everything. Normal attention re-reads every earlier word for each new word, and that explodes at a million words. So on sixty-nine of its ninety-three layers, Kimi K3 uses a lighter kind of attention whose cost grows in a straight line. Third, don't store it fat. The bulk of the model was trained to stay accurate at four bits instead of sixteen. So the download ships already compressed, about one-and-a-half terabytes instead of five-point-six. That's still a server, not a laptop.

Wins a real cluster, loses its own coding bench

Wins
search, tools, reading documents
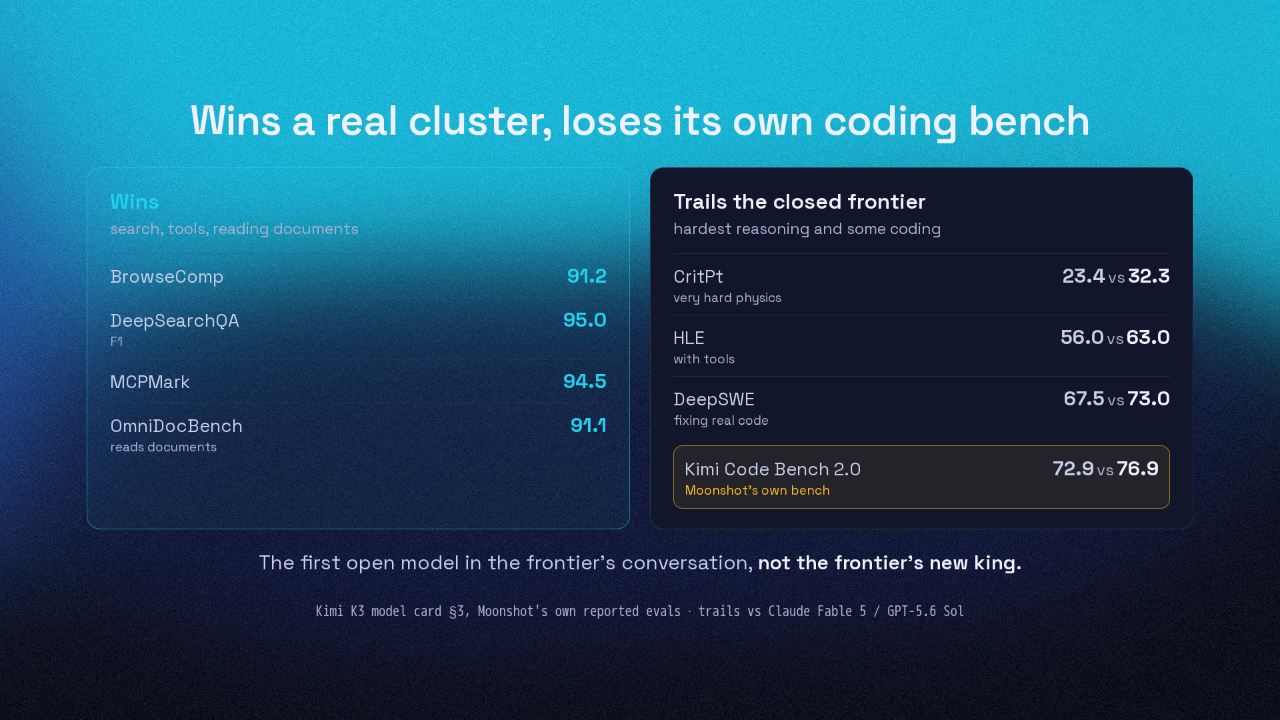
BrowseComp91.2
DeepSearchQA F195.0
MCPMark94.5
OmniDocBench reads documents91.1
Trails the closed frontier
hardest reasoning and some coding
CritPt very hard physics23.4vs32.3
HLE with tools56.0vs63.0
DeepSWE fixing real code67.5vs73.0
Kimi Code Bench 2.0 Moonshot's own bench72.9vs76.9
The first open model in the frontier's conversation, not the frontier's new king.
Kimi K3 model card §3, Moonshot's own reported evals · trails vs Claude Fable 5 / GPT-5.6 Sol

Those wins cluster in one place, using web search, outside tools, and reading documents. On the hardest reasoning and some coding, Kimi K3 trails the closed frontier. On CritPt, a set of very hard physics problems, it scores twenty-three to GPT-5.6's thirty-two. And on Moonshot's own coding benchmark, Kimi Code Bench, it loses, seventy-three to Claude Fable 5's seventy-seven. So it's the first open model in the frontier's conversation, not the frontier's new king.

Free to download, but not fully open source

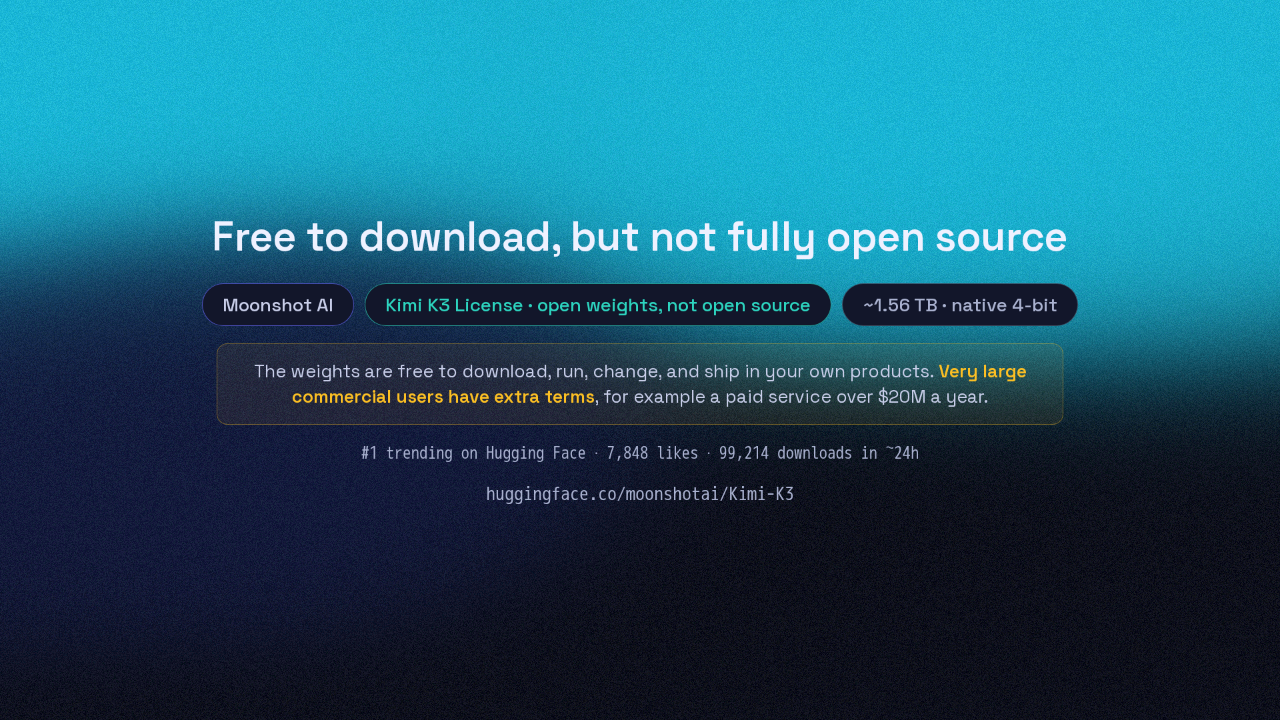
Moonshot AI Kimi K3 License · open weights, not open source ~1.56 TB · native 4-bit
The weights are free to download, run, change, and ship in your own products. Very large commercial users have extra terms, for example a paid service over $20M a year.
#1 trending on Hugging Face · 7,848 likes · 99,214 downloads in ~24h
huggingface.co/moonshotai/Kimi-K3

The weights are free to download, run, change, and even ship in your own products. But Kimi K3 is not fully open source. Its license adds extra terms for very large commercial users. So Moonshot calls it open weights, not open source.

The frontier is no longer only for rent

a free model you can download reached it
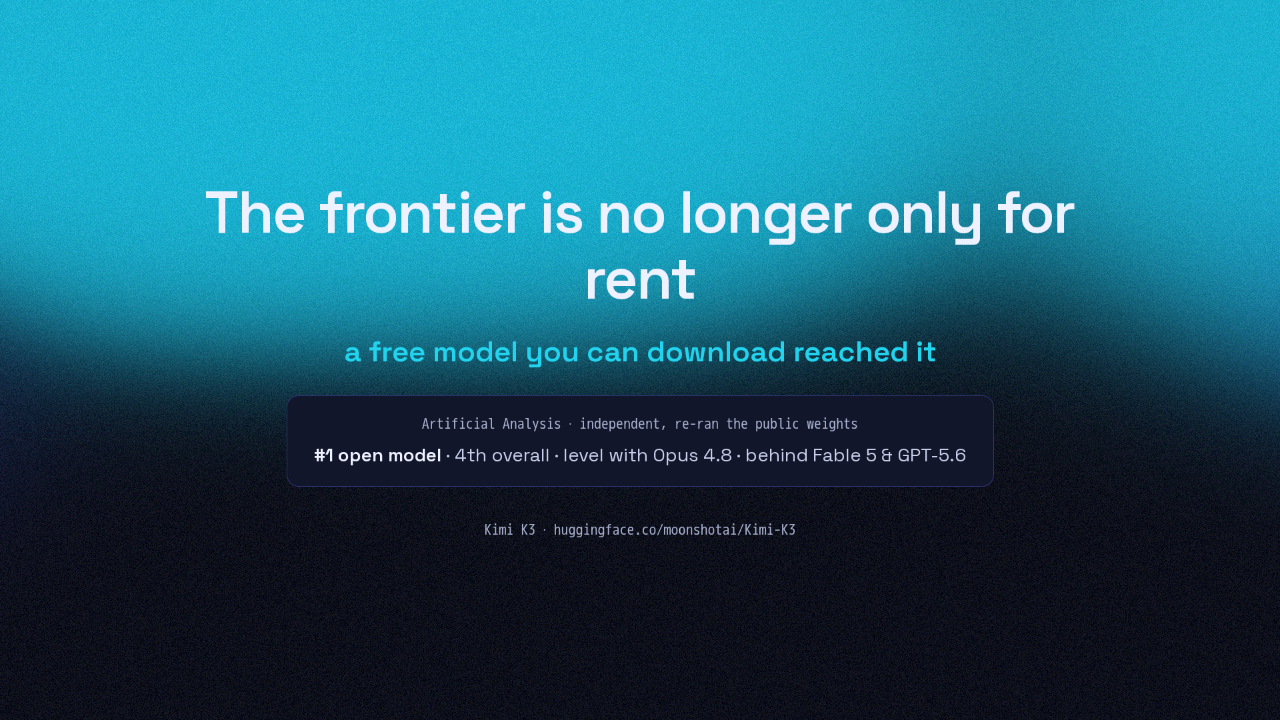
Artificial Analysis · independent, re-ran the public weights #1 open model · 4th overall · level with Opus 4.8 · behind Fable 5 & GPT-5.6
Kimi K3 · huggingface.co/moonshotai/Kimi-K3

So the frontier is no longer only something you rent from a company's servers. A free model you can download reached that frontier. And an independent board, Artificial Analysis, re-ran the public weights and landed in the same place: the top open model, level with Opus 4.8, still behind the very best.


Up next

2:58

Apodex 1.1 mini · the same file, run alone and run as a team

@ai-ml-today · 1 month ago

3:09

Ornith-1.5 · an open model trained on problems it wrote for itself

@ai-ml-today · 1 month ago

3:08

MOSS-VL · an open 11B video model trained to decide, after every frame, whether to speak or stay silent

@ai-ml-today · 1 month ago

3:29

Qwen3.8-27B · a 27B open model anyone can download averages 84.3 across real desktop jobs on Qwen’s own run, and loses the widest row on its own card by nine points

@ai-ml-today · 1 month ago

3:15

MiLMMT-46-v1.0 · Xiaomi finished training an open translator on sentences that had no translation attached, and the scores it now leads on are produced by the two models that graded it

@ai-ml-today · 1 month ago

3:31

BDH-CQ — a 150M-parameter system that learns a puzzle rule from the worked examples in front of it and does its thinking as numbers, never as words

@ai-ml-today · 2 months ago

3:29

Muse Glimmer 30B, Meta’s open agent model, and the second tiny model that guesses sixteen words ahead so it runs fast on one consumer graphics card

@ai-ml-today · 2 months ago

3:05

JoyAI-Video-Edit, JD’s open 16B model that edits a video while the video is still playing, at about 30 frames a second on one Nvidia B200

@ai-ml-today · 2 months ago

3:26

Inkling-Small, Thinking Machines’ 12B-active / 276B open mixture-of-experts model that out-reasons its own 3.5× bigger flagship

@ai-ml-today · 2 months ago

3:42

Maple-Preview, DeepGrove’s 20-billion-parameter ternary reasoning model that runs on a Mac mini

@ai-ml-today · 2 months ago

3:16

Hunyuan3D-Buffalo, Tencent’s one model that builds, understands, and edits 3D from words

@ai-ml-today · 2 months ago

3:28

MiniMax H3, an open model that makes a video and its soundtrack in one pass

@ai-ml-today · 2 months ago









