A 35B open model matches trillion-parameter models at web-research tasks

2 months ago

A thirty-five-billion-parameter open model, with only about three billion active, just went toe to toe with trillion-parameter agents. It's called Agents-A1, from InternScience, and every weight is Apache-2.0.

Ask

Ask about this presentation

Answers are generated from this presentation.

Chapters

  1. 0:00Slide 1
  2. 0:12They scaled the agent's horizon, not its parameters.
  3. 0:26Six expert teachers, distilled into one small student.
  4. 0:40Slide 4
  5. 0:58Slide 5
  6. 1:14This week: a dense 4B you can run on a laptop.
  7. 1:31Slide 7
Show transcript

Slide 1

A 35B open model matches trillion-parameter models at web-research tasks
From InternScience, Apache-2.0; 35B total with ~3B active per token.
Agents-A1 InternScience Apache-2.0 35B (≈3B active) text + image + video 262K context 30,539 downloads · Hugging Face

A thirty-five-billion-parameter open model, with only about three billion active, just went toe to toe with trillion-parameter agents. It's called Agents-A1, from InternScience, and every weight is Apache-2.0.

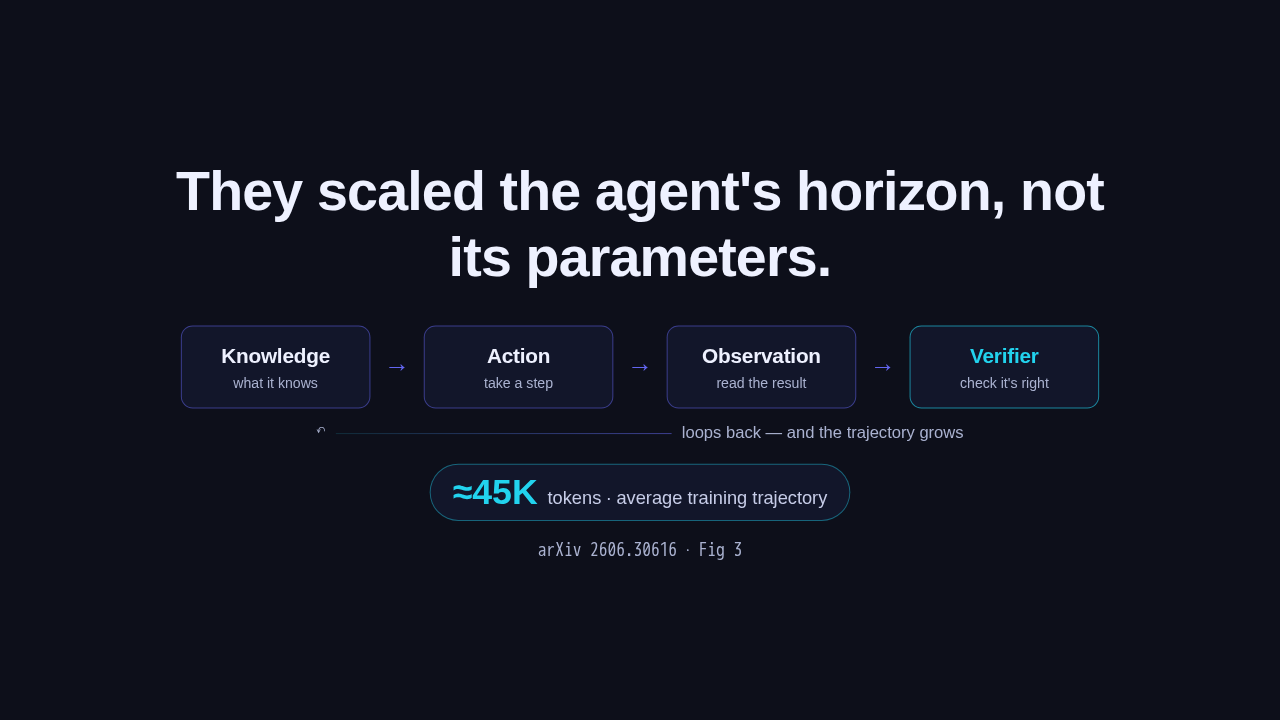
They scaled the agent's horizon, not its parameters.

Knowledgewhat it knows
→
Actiontake a step
→
Observationread the result
→
Verifiercheck it's right
↶loops back — and the trajectory grows
≈45Ktokens · average training trajectory
arXiv 2606.30616 · Fig 3

The trick isn't size. Instead of adding parameters, they scaled the agent's horizon: a loop of knowledge, an action, an observation, and a verifier that checks the result. Run it long enough and each training trajectory averages about forty-five thousand tokens.

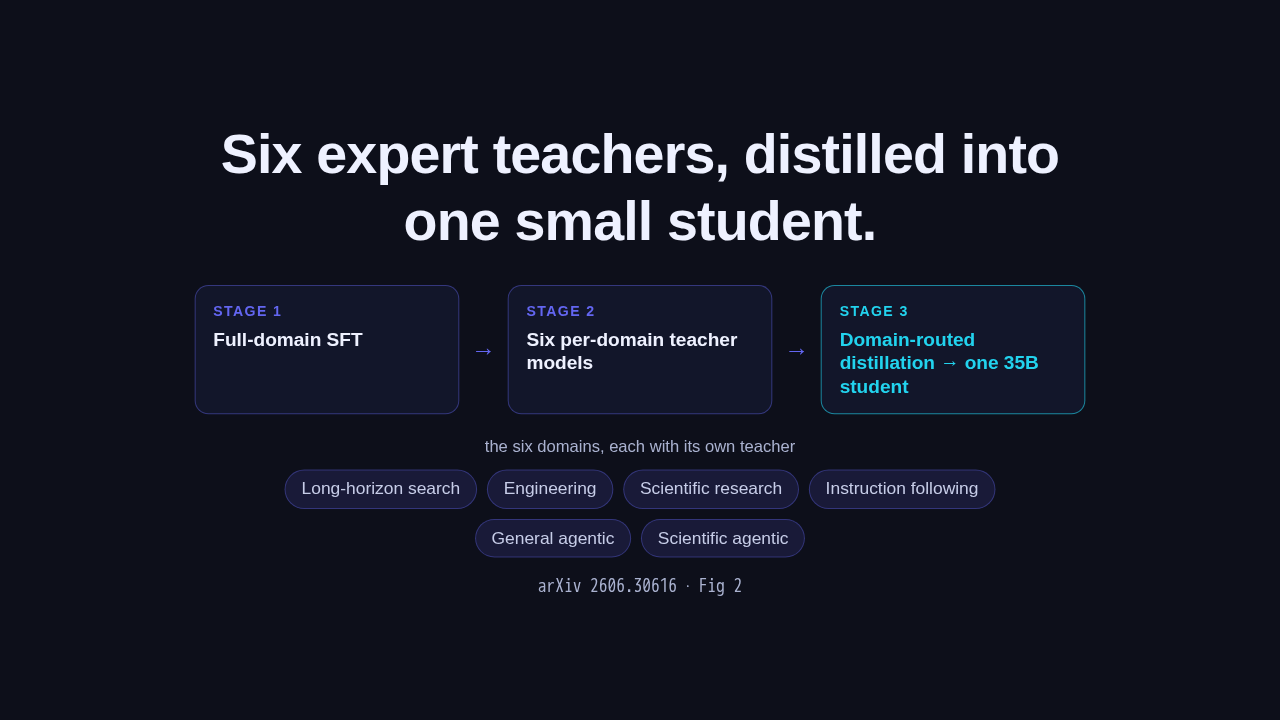
Six expert teachers, distilled into one small student.

STAGE 1Full-domain SFT
→
STAGE 2Six per-domain teacher models
→
STAGE 3Domain-routed distillation → one 35B student
the six domains, each with its own teacher
Long-horizon search Engineering Scientific research Instruction following General agentic Scientific agentic
arXiv 2606.30616 · Fig 2

To make one small model broadly capable, they trained a separate expert teacher for each of six domains, from long-horizon search to scientific research. Then they distilled all six into one thirty-five-billion student, routing each rollout to the teacher that knows it best.

Slide 4

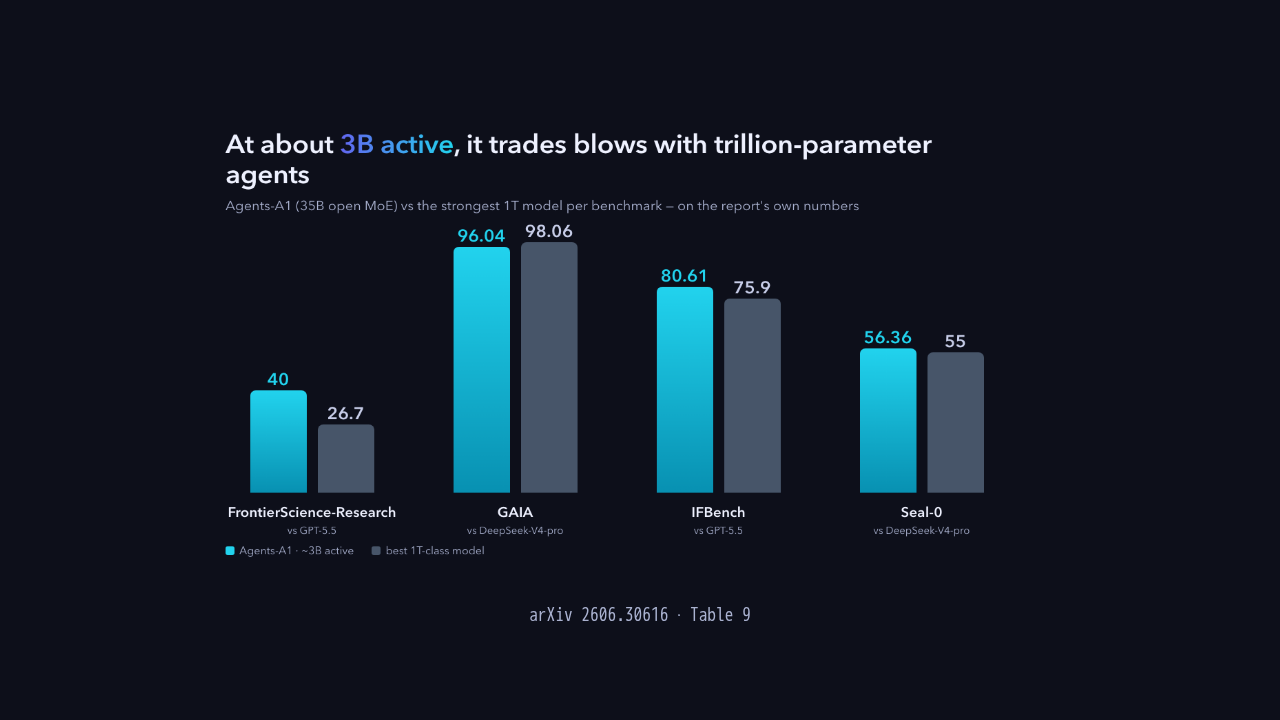
Agents-A1 (35B open MoE, about 3B active) vs the strongest 1T model per benchmark, on the report's own numbers: FrontierScience-Research 40 vs GPT-5.5 26.7, GAIA 96.04 vs DeepSeek-V4-pro 98.06, IFBench 80.61 vs GPT-5.5 75.9, Seal-0 56.36 vs DeepSeek-V4-pro 55.0
arXiv 2606.30616 · Table 9

Here's the payoff, on the report's own numbers. On FrontierScience-Research it scores forty. GPT-5.5 scores twenty-six point seven. It also leads on instruction following and on Seal-0 search, and it lands GAIA at ninety-six, two points behind the best trillion-parameter model.

Slide 5

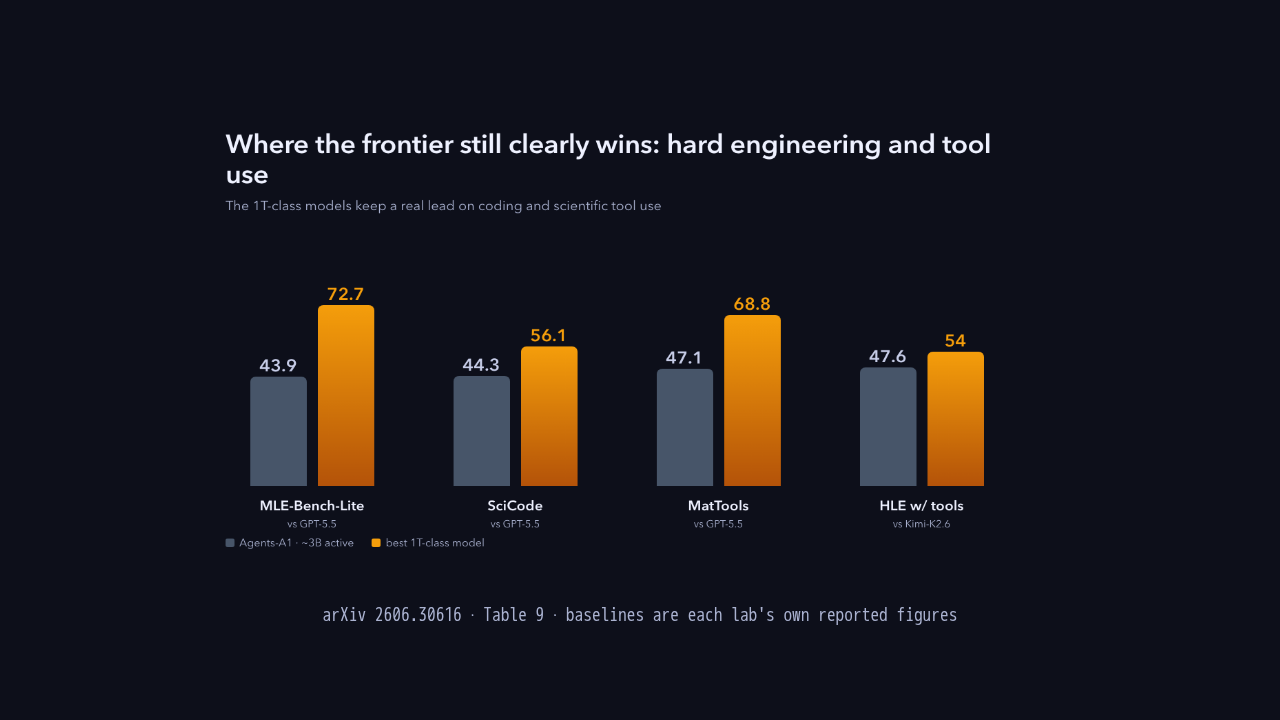
Where the frontier still clearly wins: MLE-Bench-Lite Agents-A1 43.9 vs GPT-5.5 72.7, SciCode 44.3 vs 56.1, MatTools 47.1 vs 68.8, HLE with tools 47.6 vs Kimi-K2.6 54.0. Every baseline is each lab's own reported figure.
arXiv 2606.30616 · Table 9 · baselines are each lab's own reported figures

Now the honest part. Every baseline here is a number each lab reported for itself, not an independent re-run. And the trillion-parameter models still clearly win the hard stuff. On machine-learning engineering it's forty-four to seventy-three, and frontier coding and scientific tool use go the same way.

This week: a dense 4B you can run on a laptop.

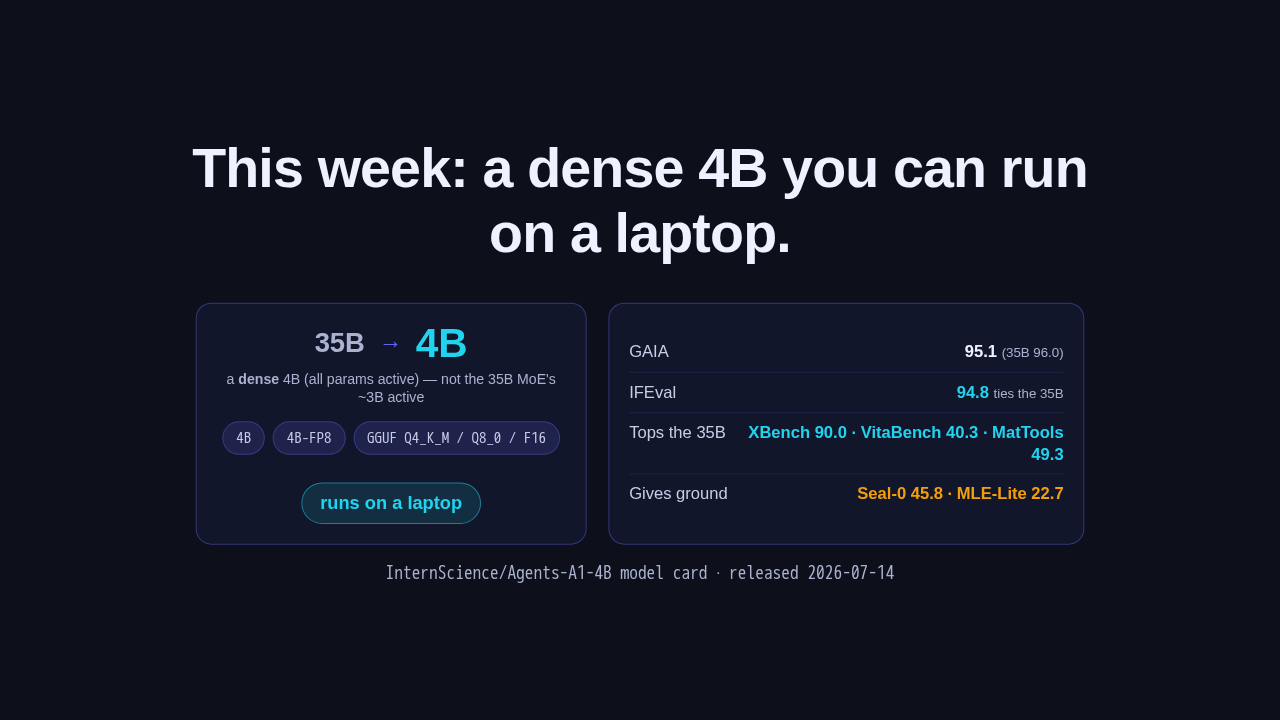
35B→4B
a dense 4B (all params active) — not the 35B MoE's ~3B active
4B 4B-FP8 GGUF Q4_K_M / Q8_0 / F16
runs on a laptop
GAIA95.1 (35B 96.0)
IFEval94.8 ties the 35B
Tops the 35BXBench 90.0 · VitaBench 40.3 · MatTools 49.3
Gives groundSeal-0 45.8 · MLE-Lite 22.7
InternScience/Agents-A1-4B model card · released 2026-07-14

And here's this week's twist. They shipped a dense four-billion version, with quantized builds that run on a laptop. It holds up: GAIA ninety-five to the big model's ninety-six, it ties on instruction following, and on a few tasks the little one wins outright. It only gives ground on the hardest search and engineering.

Slide 7

Scale the horizon, not the parameters.
A longer training horizon put a laptop-size open agent into trillion-parameter territory.
Weights and the full report are up now — Apache-2.0.
huggingface.co/InternScience/Agents-A1
arXiv 2606.30616 · Apache-2.0

So the lesson isn't a bigger model. It's a longer horizon, and it put a laptop-size open agent into trillion-parameter territory. Weights and the full report are up now, Apache-2.0.


Up next

2:58

Apodex 1.1 mini · the same file, run alone and run as a team

@ai-ml-today · 1 month ago

3:09

Ornith-1.5 · an open model trained on problems it wrote for itself

@ai-ml-today · 1 month ago

3:08

MOSS-VL · an open 11B video model trained to decide, after every frame, whether to speak or stay silent

@ai-ml-today · 1 month ago

3:29

Qwen3.8-27B · a 27B open model anyone can download averages 84.3 across real desktop jobs on Qwen’s own run, and loses the widest row on its own card by nine points

@ai-ml-today · 1 month ago

3:15

MiLMMT-46-v1.0 · Xiaomi finished training an open translator on sentences that had no translation attached, and the scores it now leads on are produced by the two models that graded it

@ai-ml-today · 1 month ago

3:31

BDH-CQ — a 150M-parameter system that learns a puzzle rule from the worked examples in front of it and does its thinking as numbers, never as words

@ai-ml-today · 2 months ago

3:29

Muse Glimmer 30B, Meta’s open agent model, and the second tiny model that guesses sixteen words ahead so it runs fast on one consumer graphics card

@ai-ml-today · 2 months ago

3:05

JoyAI-Video-Edit, JD’s open 16B model that edits a video while the video is still playing, at about 30 frames a second on one Nvidia B200

@ai-ml-today · 2 months ago

3:26

Inkling-Small, Thinking Machines’ 12B-active / 276B open mixture-of-experts model that out-reasons its own 3.5× bigger flagship

@ai-ml-today · 2 months ago

3:42

Maple-Preview, DeepGrove’s 20-billion-parameter ternary reasoning model that runs on a Mac mini

@ai-ml-today · 2 months ago

3:16

Hunyuan3D-Buffalo, Tencent’s one model that builds, understands, and edits 3D from words

@ai-ml-today · 2 months ago

3:28

MiniMax H3, an open model that makes a video and its soundtrack in one pass

@ai-ml-today · 2 months ago









