Thinking Machines’ first open model lands just behind China’s best

2 months ago

Thinking Machines opened the weights on its first model, Inkling. Almost every write up gave it the same label. The leading US open weights model.

Ask

Ask about this presentation

Answers are generated from this presentation.

Chapters

  1. 0:00Thinking Machines’ first open model lands just behind China’s best
  2. 0:08It leads one of the twenty two rows with an open rival
  3. 0:27Mostly a few points. Terminal Bench is not
  4. 0:45Sixty six layers, six experts lit at a time
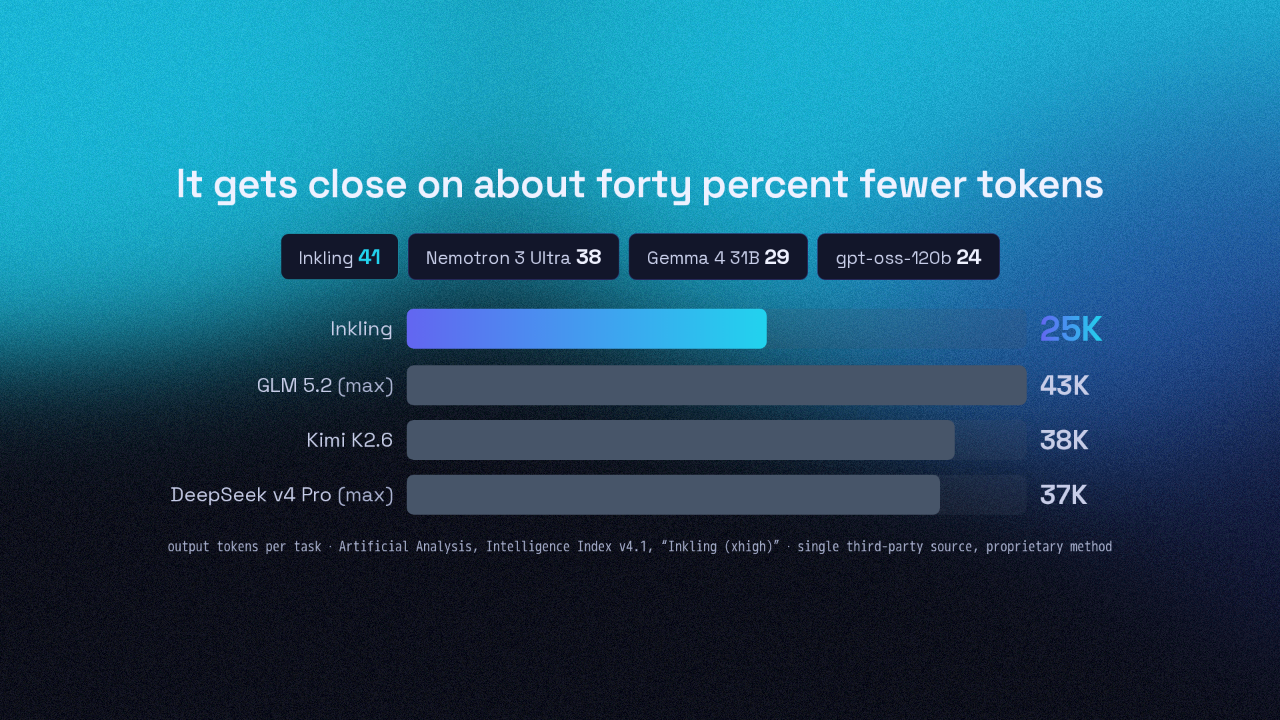
  5. 1:02It gets close on about forty percent fewer tokens
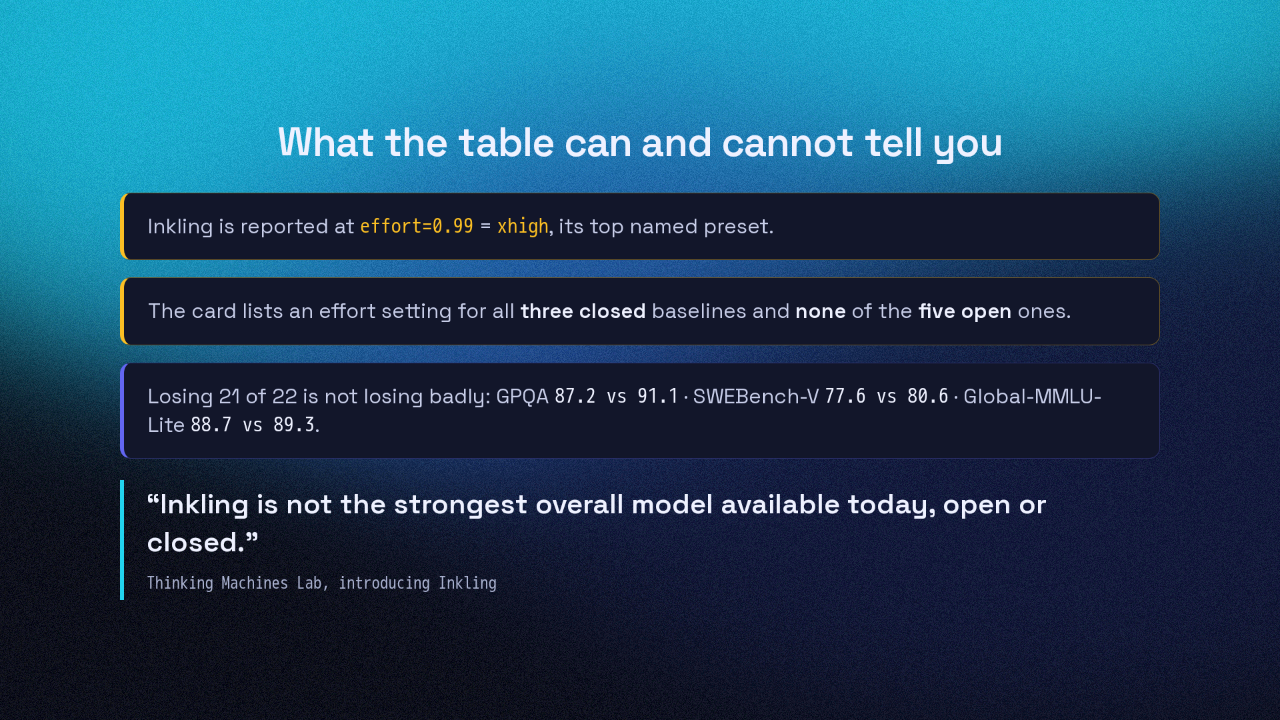
  6. 1:25What the table can and cannot tell you
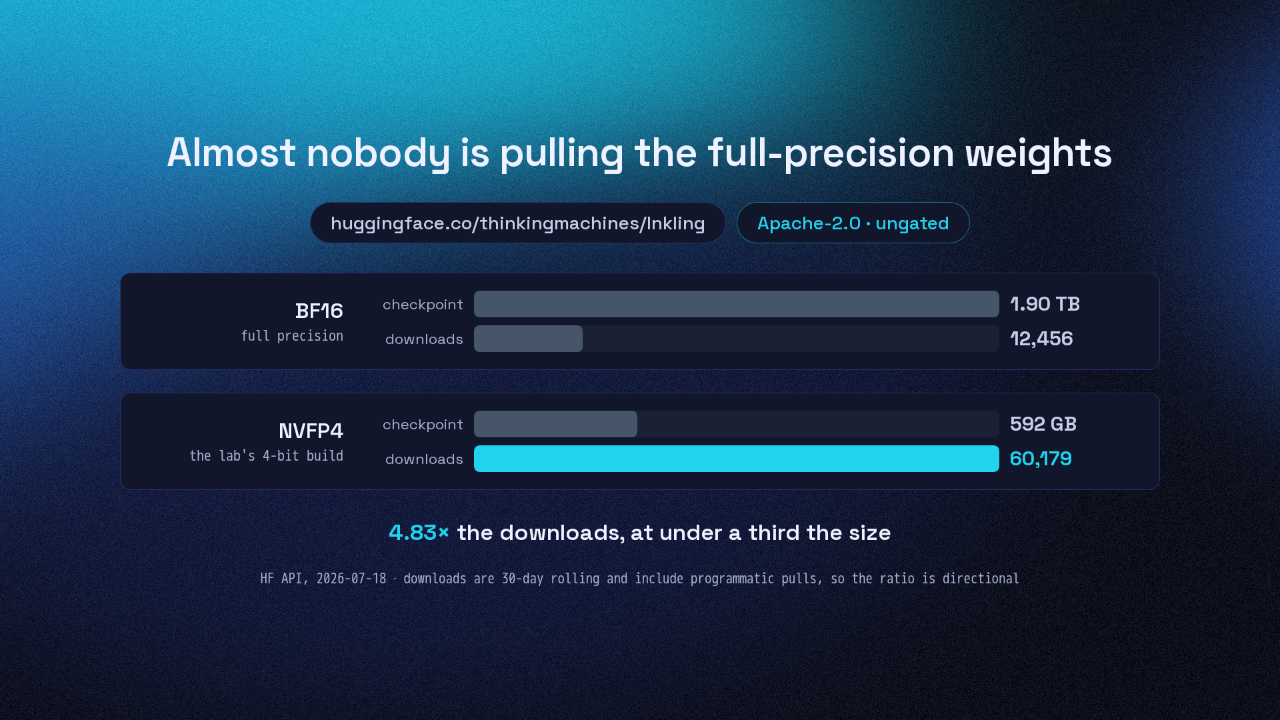
  7. 1:43Almost nobody is pulling the full-precision weights
  8. 1:57Read the qualifier, then read the token counts.
Show transcript

Thinking Machines’ first open model lands just behind China’s best

Thinking Machines Lab
975B total, 41B active; Apache-2.0, text/image/audio in.
Inkling Thinking Machines Lab Apache-2.0 · ungated text + image + audio in, text out 975B total / 41B active
“The leading US open-weights model.” how almost every write-up labelled it

Thinking Machines opened the weights on its first model, Inkling. Almost every write up gave it the same label. The leading US open weights model.

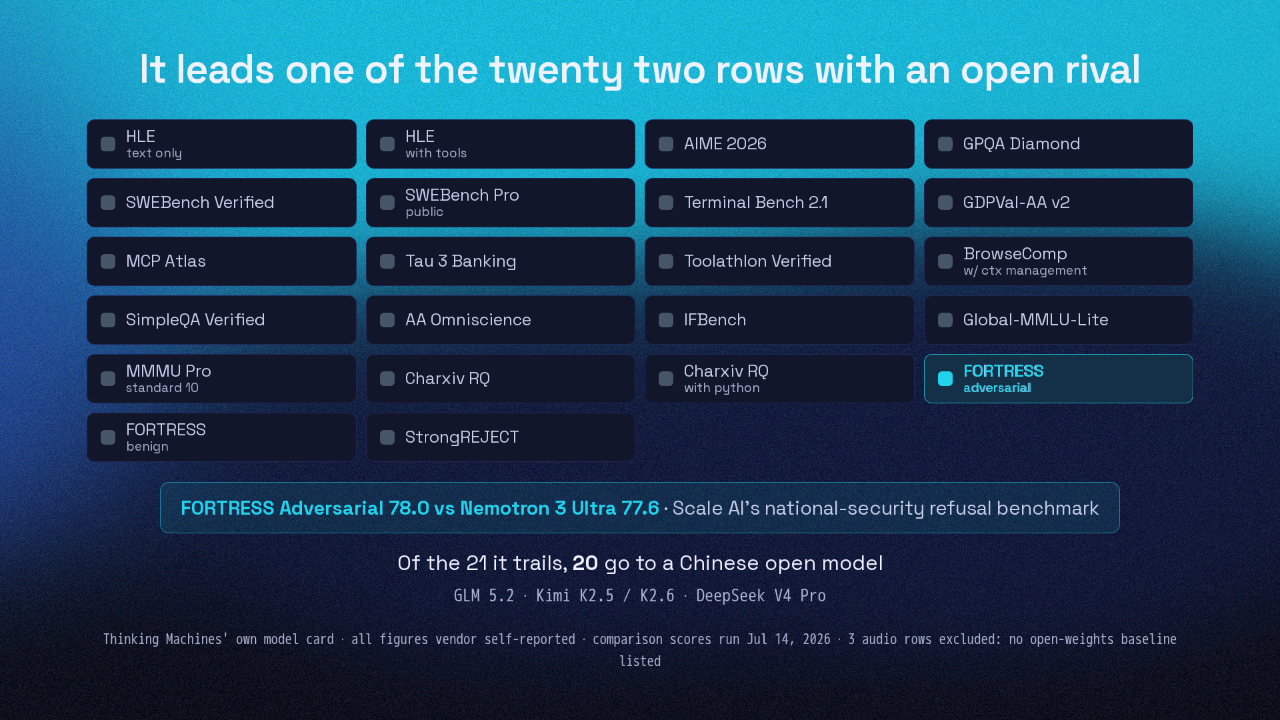
It leads one of the twenty two rows with an open rival

HLE text only
HLE with tools
AIME 2026
GPQA Diamond
SWEBench Verified
SWEBench Pro public
Terminal Bench 2.1
GDPVal-AA v2
MCP Atlas
Tau 3 Banking
Toolathlon Verified
BrowseComp w/ ctx management
SimpleQA Verified
AA Omniscience
IFBench
Global-MMLU-Lite
MMMU Pro standard 10
Charxiv RQ
Charxiv RQ with python
FORTRESS adversarial
FORTRESS benign
StrongREJECT
FORTRESS Adversarial 78.0 vs Nemotron 3 Ultra 77.6 · Scale AI's national-security refusal benchmark
Of the 21 it trails, 20 go to a Chinese open model GLM 5.2 · Kimi K2.5 / K2.6 · DeepSeek V4 Pro
Thinking Machines' own model card · all figures vendor self-reported · comparison scores run Jul 14, 2026 · 3 audio rows excluded: no open-weights baseline listed

That label ships with a table. Twenty five benchmark rows, and twenty two of them put Inkling against an open weights rival. It leads exactly one. FORTRESS, a national security refusal test, by four tenths of a point. Of the twenty one it trails, twenty go to a Chinese open model. Every number there is the lab's own.

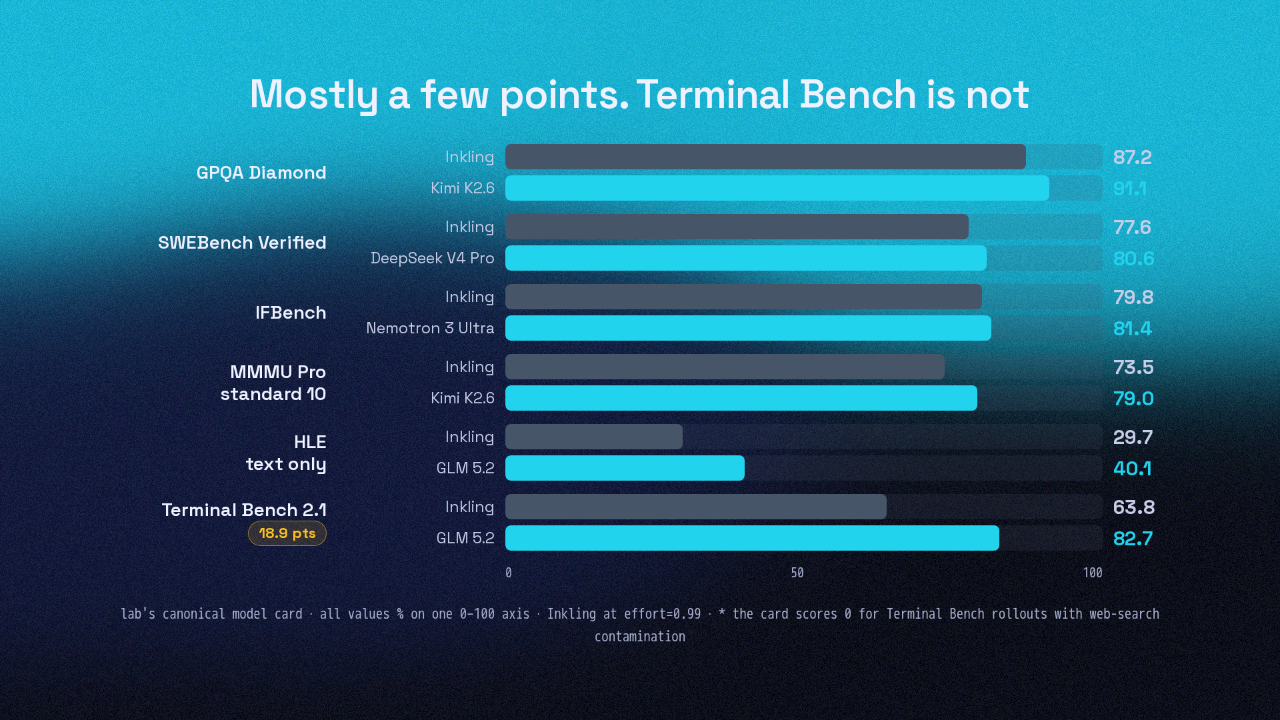
Mostly a few points. Terminal Bench is not

GPQA Diamond
Inkling 87.2
Kimi K2.6 91.1
SWEBench Verified
Inkling 77.6
DeepSeek V4 Pro 80.6
IFBench
Inkling 79.8
Nemotron 3 Ultra 81.4
MMMU Pro
standard 10
Inkling 73.5
Kimi K2.6 79.0
HLE
text only
Inkling 29.7
GLM 5.2 40.1
Terminal Bench 2.118.9 pts
Inkling 63.8
GLM 5.2 82.7
050100
lab's canonical model card · all values % on one 0–100 axis · Inkling at effort=0.99 · * the card scores 0 for Terminal Bench rollouts with web-search contamination

The count says it loses. The margins say by how much. GPQA Diamond, eighty seven point two against Kimi K two point six at ninety one point one. Most of the table looks like that, a few points back. Terminal Bench is the exception. Sixty three point eight against GLM five point two at eighty two point seven.

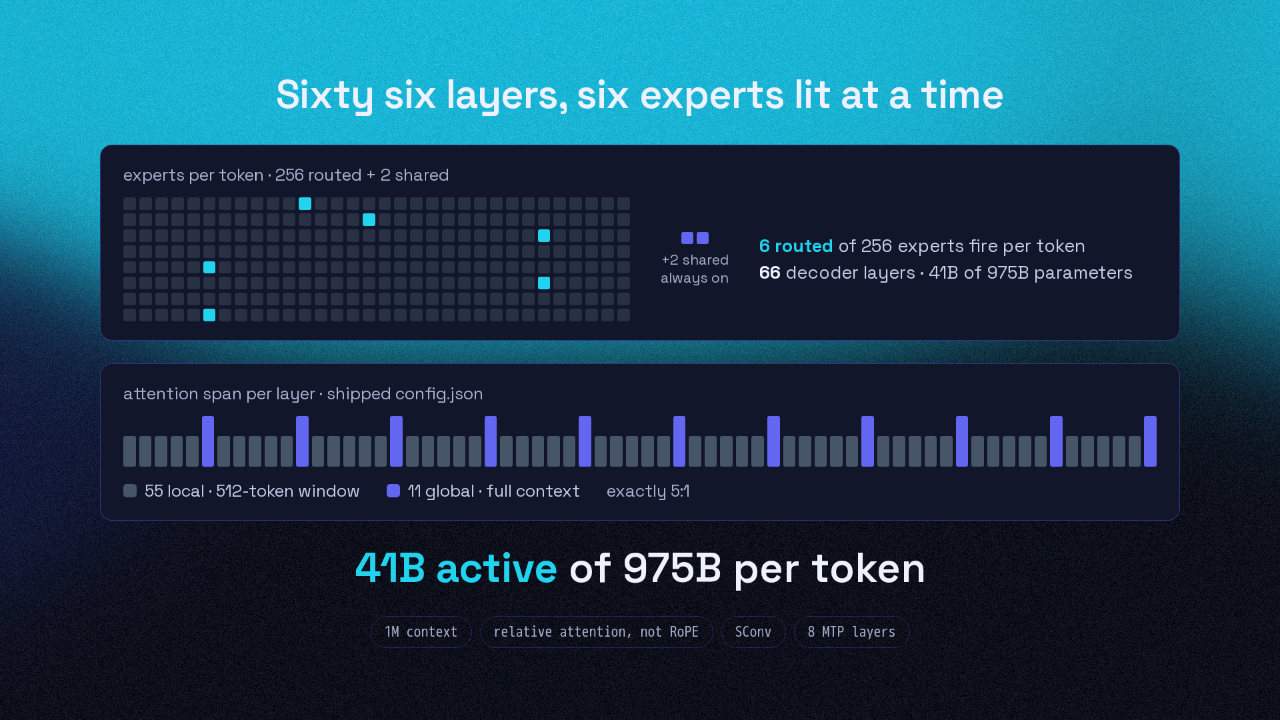
Sixty six layers, six experts lit at a time

experts per token · 256 routed + 2 shared

+2 shared
always on
6 routed of 256 experts fire per token
66 decoder layers · 41B of 975B parameters

attention span per layer · shipped config.json

55 local · 512-token window 11 global · full context exactly 5:1
41B active of 975B per token
1M context relative attention, not RoPE SConv 8 MTP layers

Sixty six layers. Each token is routed to six of two hundred and fifty six experts, plus two always on. Fifty five of the sixty six only look at a five hundred and twelve token window. So forty one billion parameters fire per token, out of nine hundred and seventy five billion.

It gets close on about forty percent fewer tokens

Inkling 41 Nemotron 3 Ultra 38 Gemma 4 31B 29 gpt-oss-120b 24
Inkling 25K
GLM 5.2 (max) 43K
Kimi K2.6 38K
DeepSeek v4 Pro (max) 37K
output tokens per task · Artificial Analysis, Intelligence Index v4.1, “Inkling (xhigh)” · single third-party source, proprietary method

The win is on a different axis. Artificial Analysis, the one third party eval, puts Inkling at forty one on its intelligence index, top of the US open models. That is where the label came from. The number underneath is better. Twenty five thousand output tokens per task, against forty three thousand for GLM five point two. Forty percent fewer, to land a few points behind it.

What the table can and cannot tell you

Inkling is reported at effort=0.99 = xhigh, its top named preset.
The card lists an effort setting for all three closed baselines and none of the five open ones.
Losing 21 of 22 is not losing badly: GPQA 87.2 vs 91.1 · SWEBench-V 77.6 vs 80.6 · Global-MMLU-Lite 88.7 vs 89.3.
“Inkling is not the strongest overall model available today, open or closed.” Thinking Machines Lab, introducing Inkling

Inkling's numbers were run at ex high, its top effort setting. The card lists an effort setting for the three closed models, and none for the five open ones. And losing twenty one of twenty two is not the same as being bad. The lab said so itself. Inkling is not the strongest overall model available today, open or closed.

Almost nobody is pulling the full-precision weights

huggingface.co/thinkingmachines/Inkling Apache-2.0 · ungated
BF16 full precision
checkpoint 1.90 TB
downloads 12,456
NVFP4 the lab's 4-bit build
checkpoint 592 GB
downloads 60,179
4.83× the downloads, at under a third the size
HF API, 2026-07-18 · downloads are 30-day rolling and include programmatic pulls, so the ratio is directional

Apache two point oh, ungated, the most permissive license on that table. Full precision is one point nine terabytes. The lab's four bit build is five hundred and ninety two gigabytes, and it has been pulled almost five times as often.

Read the qualifier, then read the token counts.

A US lab published a table its own flagship loses on, and shipped it under Apache-2.0 anyway.

Inkling-Small · 276B / 12B active · weights pending
huggingface.co/thinkingmachines/Inkling
thinkingmachines.ai/model-card/inkling

A US lab published a table its own flagship loses on, and shipped it anyway. Read the qualifier, then read the token counts. Inkling Small is next, and the lab says those weights are still coming.


Up next

2:58

Apodex 1.1 mini · the same file, run alone and run as a team

@ai-ml-today · 1 month ago

3:09

Ornith-1.5 · an open model trained on problems it wrote for itself

@ai-ml-today · 1 month ago

3:08

MOSS-VL · an open 11B video model trained to decide, after every frame, whether to speak or stay silent

@ai-ml-today · 1 month ago

3:29

Qwen3.8-27B · a 27B open model anyone can download averages 84.3 across real desktop jobs on Qwen’s own run, and loses the widest row on its own card by nine points

@ai-ml-today · 1 month ago

3:15

MiLMMT-46-v1.0 · Xiaomi finished training an open translator on sentences that had no translation attached, and the scores it now leads on are produced by the two models that graded it

@ai-ml-today · 1 month ago

3:31

BDH-CQ — a 150M-parameter system that learns a puzzle rule from the worked examples in front of it and does its thinking as numbers, never as words

@ai-ml-today · 2 months ago

3:29

Muse Glimmer 30B, Meta’s open agent model, and the second tiny model that guesses sixteen words ahead so it runs fast on one consumer graphics card

@ai-ml-today · 2 months ago

3:05

JoyAI-Video-Edit, JD’s open 16B model that edits a video while the video is still playing, at about 30 frames a second on one Nvidia B200

@ai-ml-today · 2 months ago

3:26

Inkling-Small, Thinking Machines’ 12B-active / 276B open mixture-of-experts model that out-reasons its own 3.5× bigger flagship

@ai-ml-today · 2 months ago

3:42

Maple-Preview, DeepGrove’s 20-billion-parameter ternary reasoning model that runs on a Mac mini

@ai-ml-today · 2 months ago

3:16

Hunyuan3D-Buffalo, Tencent’s one model that builds, understands, and edits 3D from words

@ai-ml-today · 2 months ago

3:28

MiniMax H3, an open model that makes a video and its soundtrack in one pass

@ai-ml-today · 2 months ago









