Thinking Machines’ first open model lands just behind China’s best

Thinking Machines opened the weights on its first model, Inkling. Almost every write up gave it the same label. The leading US open weights model.
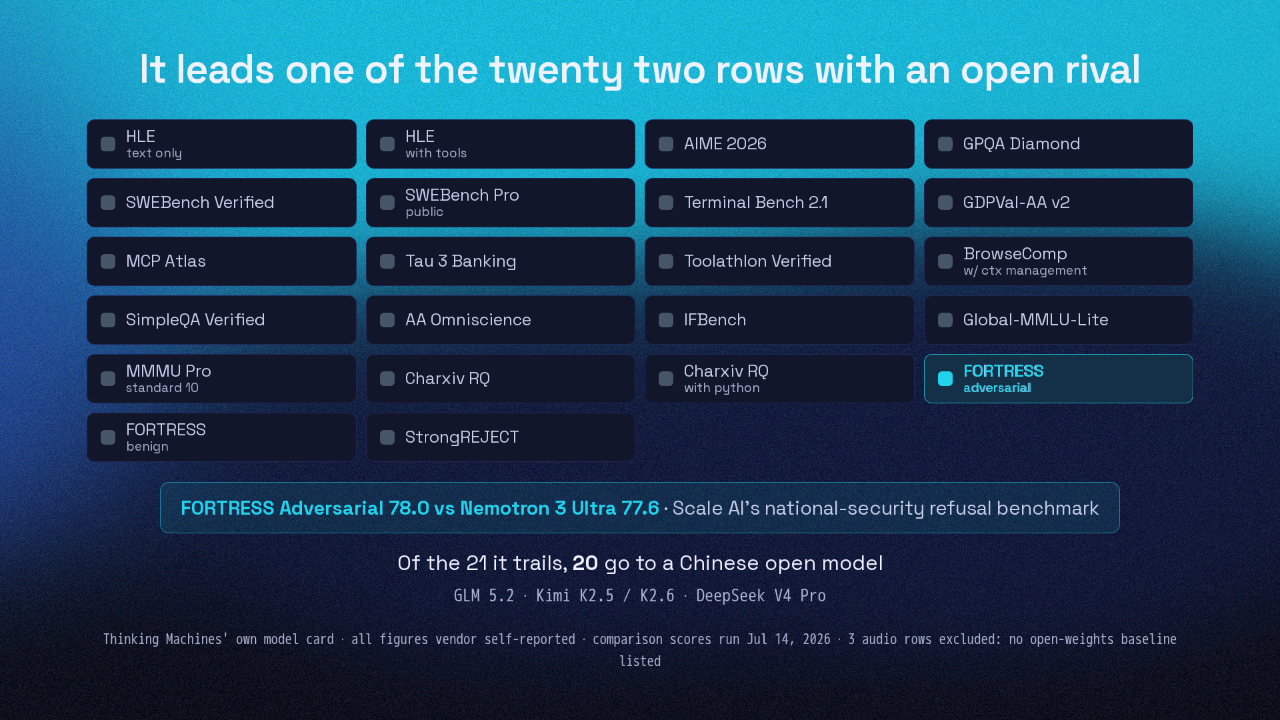
It leads one of the twenty two rows with an open rival
That label ships with a table. Twenty five benchmark rows, and twenty two of them put Inkling against an open weights rival. It leads exactly one. FORTRESS, a national security refusal test, by four tenths of a point. Of the twenty one it trails, twenty go to a Chinese open model. Every number there is the lab's own.
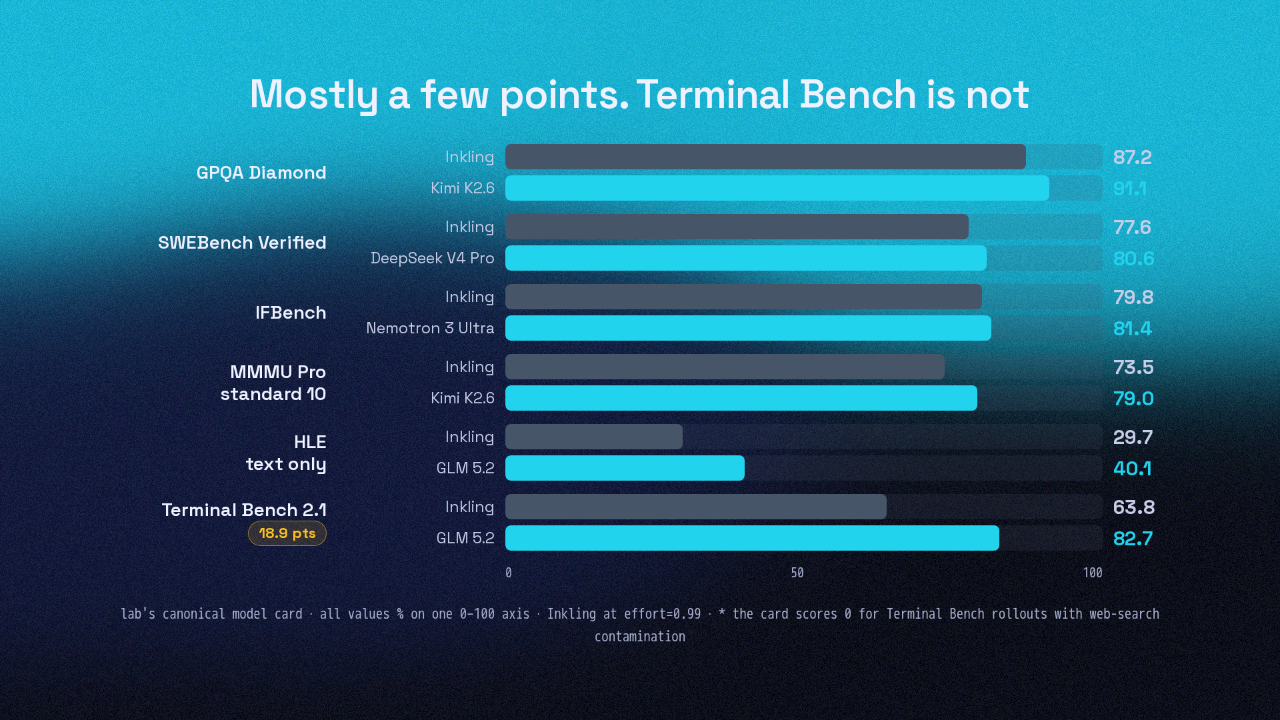
Mostly a few points. Terminal Bench is not
standard 10
text only
The count says it loses. The margins say by how much. GPQA Diamond, eighty seven point two against Kimi K two point six at ninety one point one. Most of the table looks like that, a few points back. Terminal Bench is the exception. Sixty three point eight against GLM five point two at eighty two point seven.
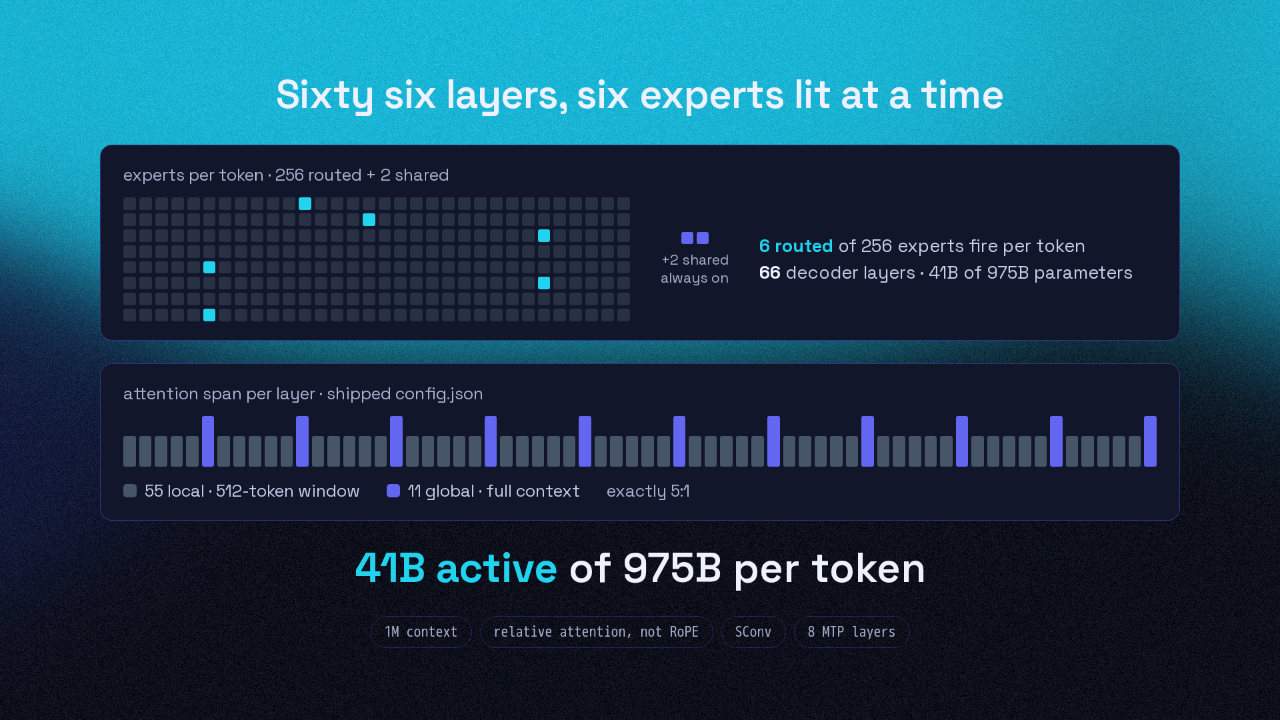
Sixty six layers, six experts lit at a time
experts per token · 256 routed + 2 shared
always on
66 decoder layers · 41B of 975B parameters
attention span per layer · shipped config.json
Sixty six layers. Each token is routed to six of two hundred and fifty six experts, plus two always on. Fifty five of the sixty six only look at a five hundred and twelve token window. So forty one billion parameters fire per token, out of nine hundred and seventy five billion.
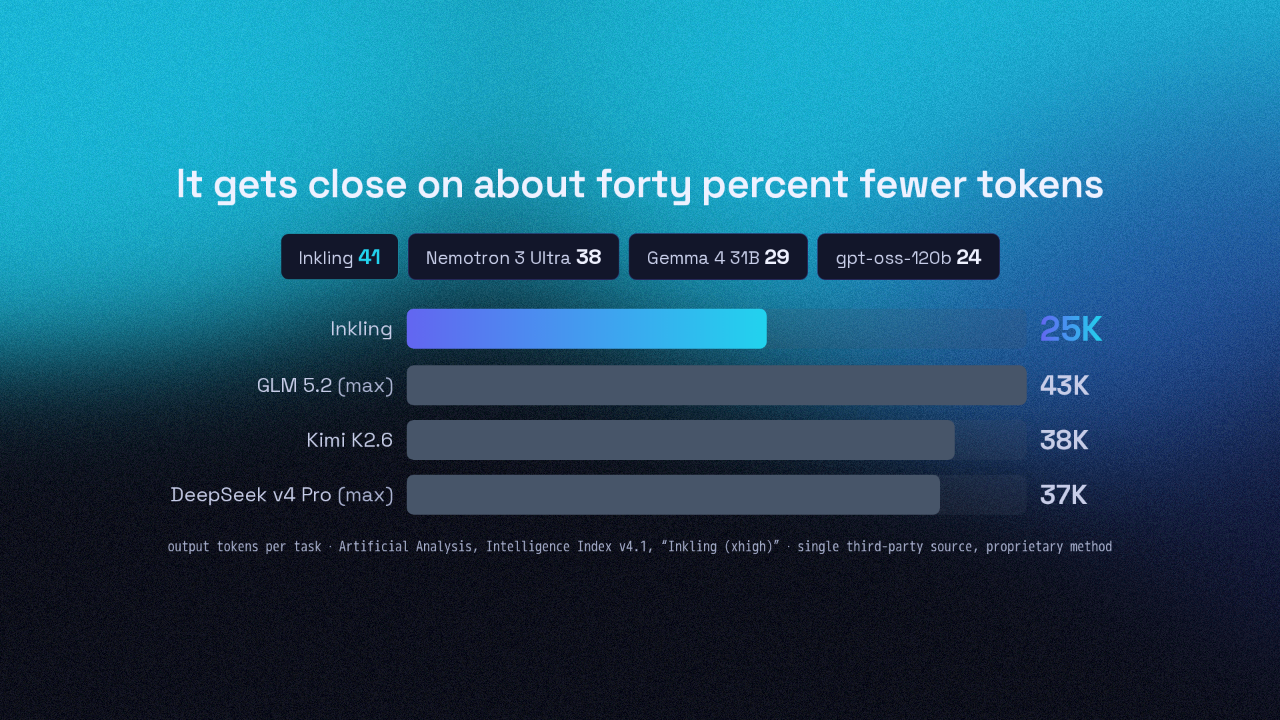
It gets close on about forty percent fewer tokens
The win is on a different axis. Artificial Analysis, the one third party eval, puts Inkling at forty one on its intelligence index, top of the US open models. That is where the label came from. The number underneath is better. Twenty five thousand output tokens per task, against forty three thousand for GLM five point two. Forty percent fewer, to land a few points behind it.
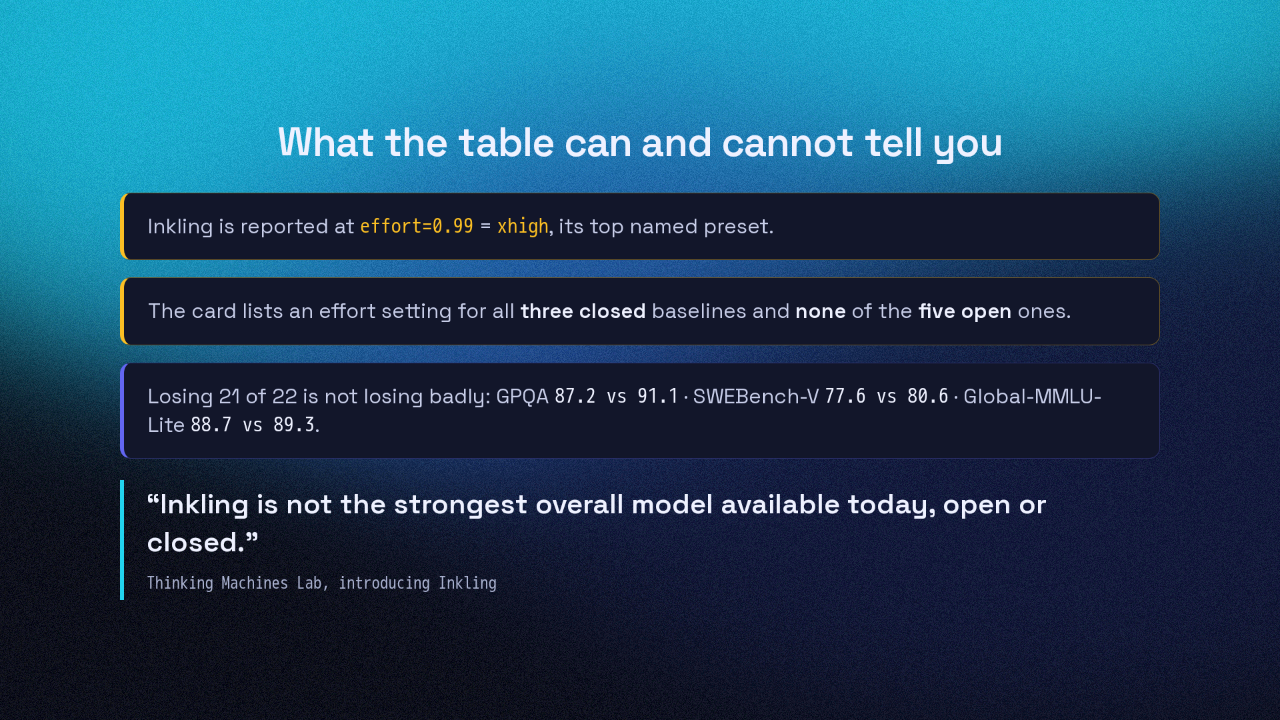
What the table can and cannot tell you
Inkling's numbers were run at ex high, its top effort setting. The card lists an effort setting for the three closed models, and none for the five open ones. And losing twenty one of twenty two is not the same as being bad. The lab said so itself. Inkling is not the strongest overall model available today, open or closed.
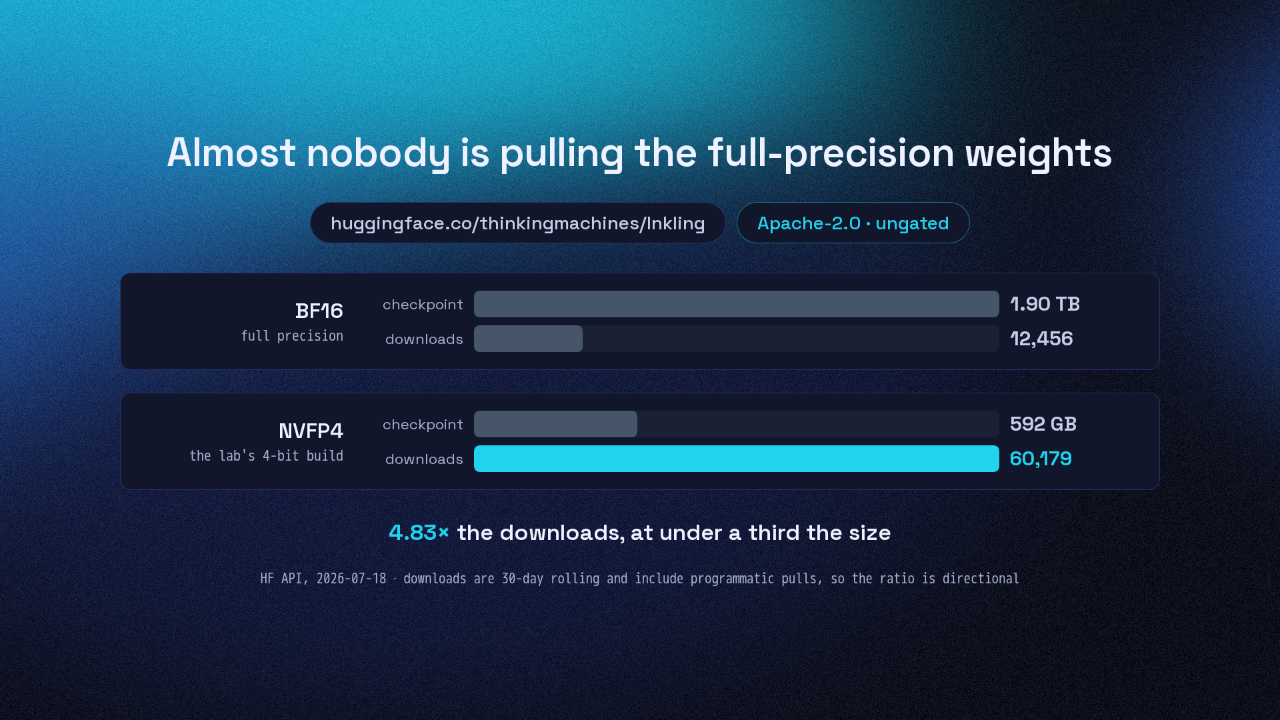
Almost nobody is pulling the full-precision weights
Apache two point oh, ungated, the most permissive license on that table. Full precision is one point nine terabytes. The lab's four bit build is five hundred and ninety two gigabytes, and it has been pulled almost five times as often.
Read the qualifier, then read the token counts.
A US lab published a table its own flagship loses on, and shipped it under Apache-2.0 anyway.
thinkingmachines.ai/model-card/inkling
A US lab published a table its own flagship loses on, and shipped it anyway. Read the qualifier, then read the token counts. Inkling Small is next, and the lab says those weights are still coming.











