FLUX 3 Image lets you place every part of a picture with a box

On October first, Black Forest Labs released FLUX three Image. Most image models take a prompt and decide the layout themselves. This one lets you lay the picture out: draw a box for everything that matters, say what goes in it, and add one line for the whole scene.
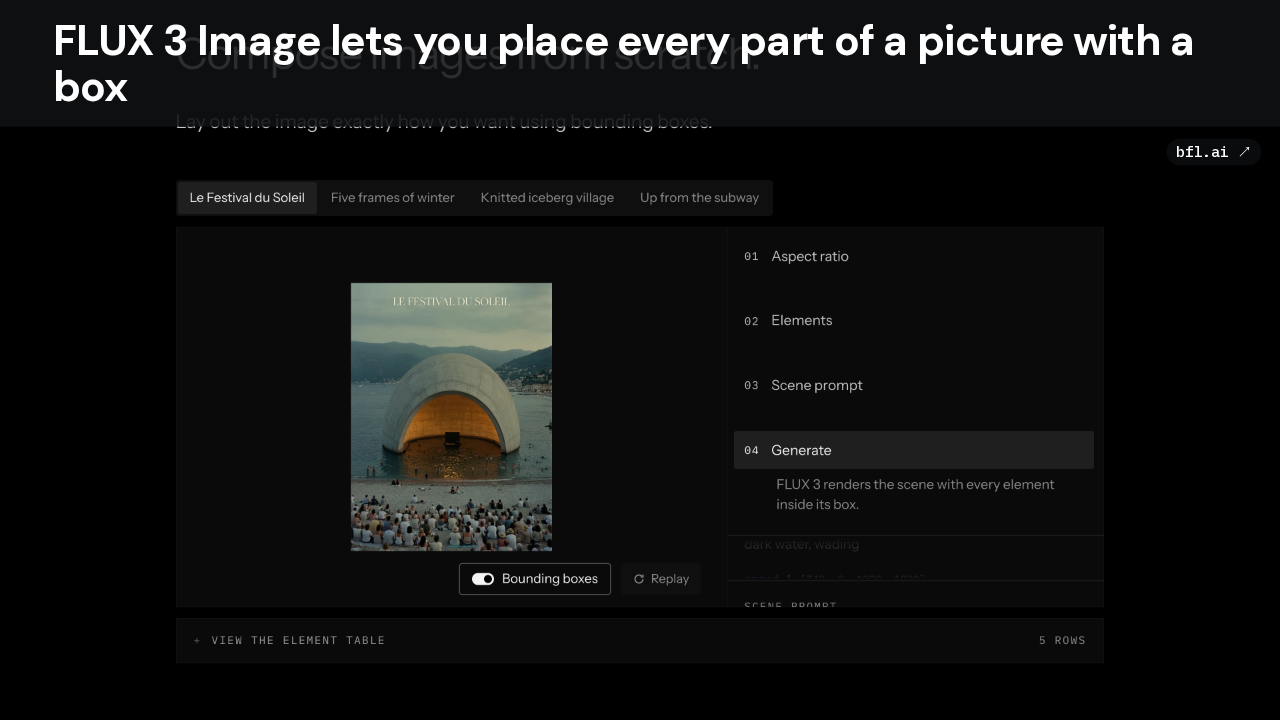
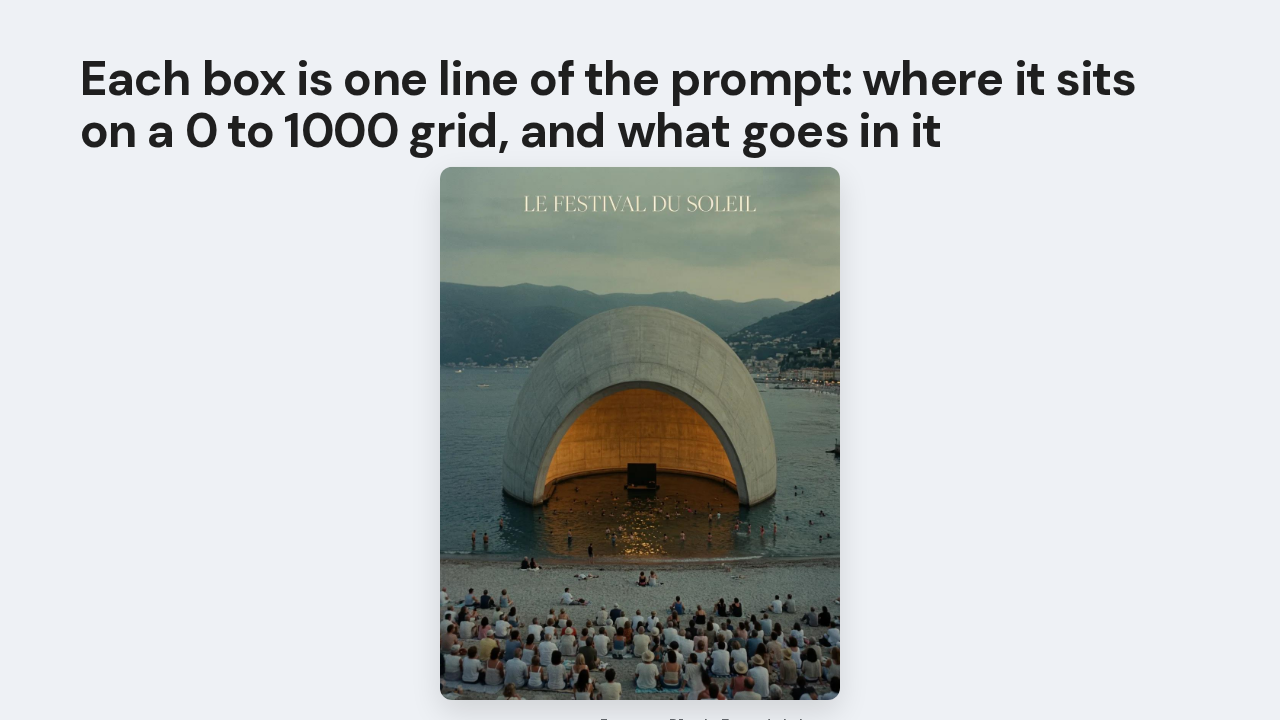
Each box is one line of the prompt: where it sits on a 0 to 1000 grid, and what goes in it

Here's that picture, with B F L's own boxes from the example. The festival's name across the top. A huge concrete dome. Swimmers in the water. A crowd on the beach. And the lights of a town on the hills. Each box is four numbers on a grid from zero to a thousand, plus a description. One more line ties the scene together.
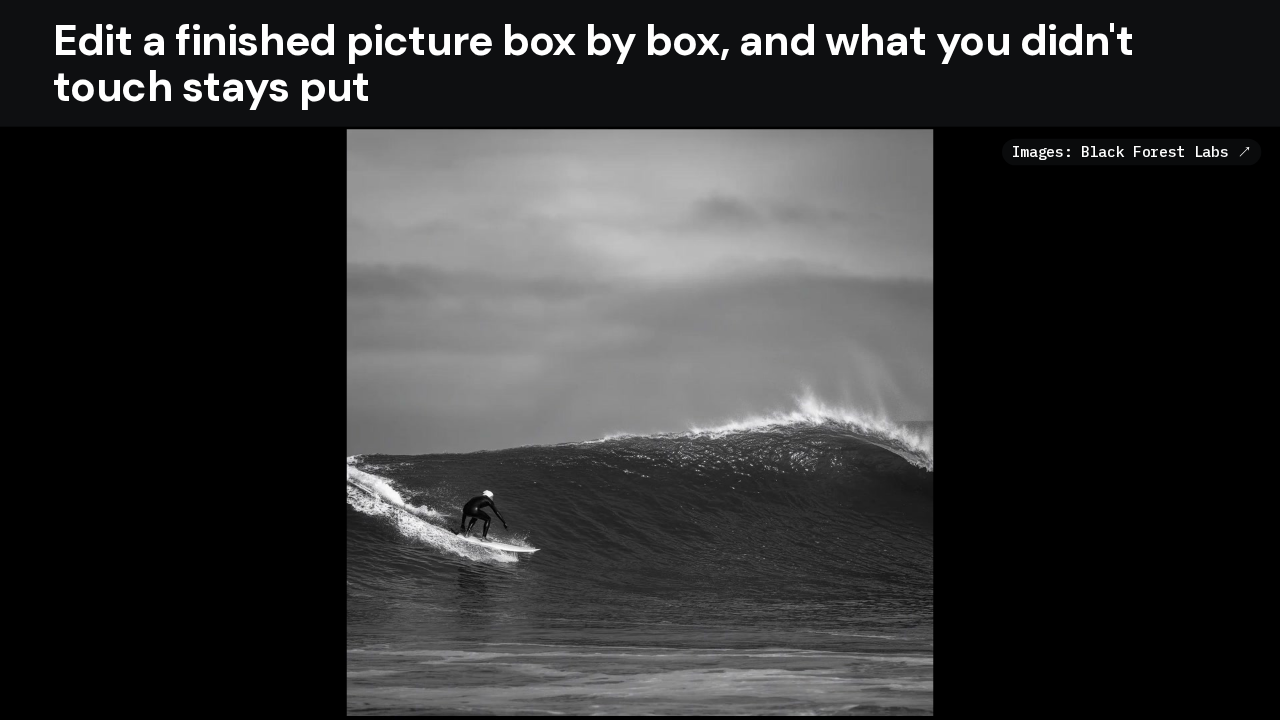
Edit a finished picture box by box, and what you didn't touch stays put
It edits the same way. In this black and white photo, the boxes say: the wetsuit becomes bright red, and so does the board. The wave and the sky are marked as locked, and they don't change.
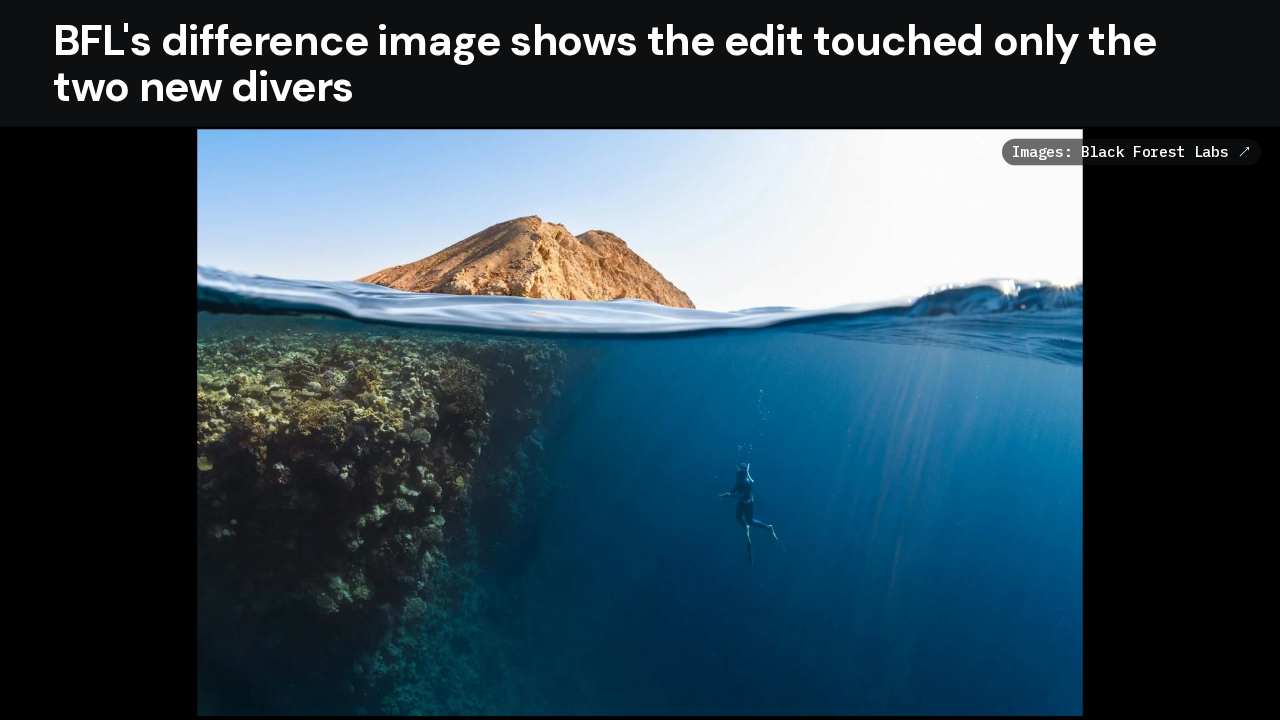
BFL's difference image shows the edit touched only the two new divers
Here's a harder one: add two divers to this underwater photo. Before. After. And then B F L's difference image, which lights up only the pixels that changed. It's black almost everywhere except the two new divers.
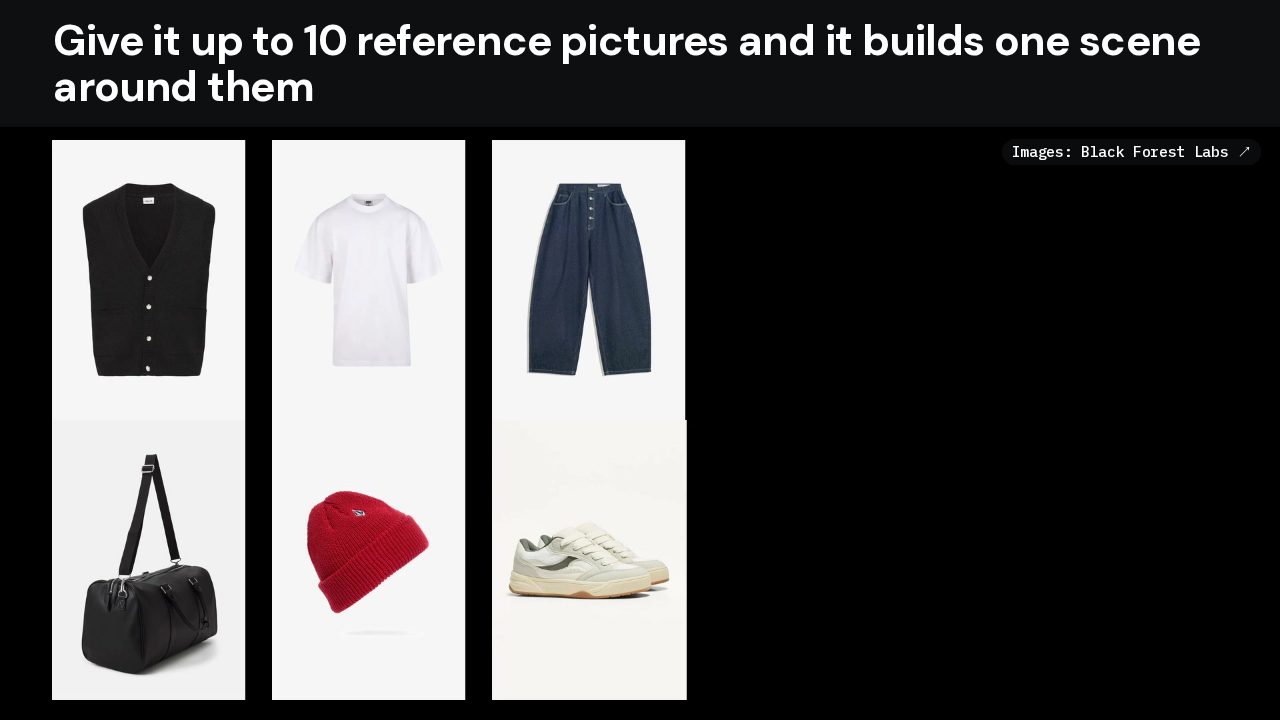
Give it up to 10 reference pictures and it builds one scene around them
You can also hand it reference pictures, up to ten. Here, six product shots: a vest, a tee, jeans, a duffel bag, a beanie and trainers. The prompt asks for a streetwear portrait in Times Square with all six, and FLUX three decides where each one goes.
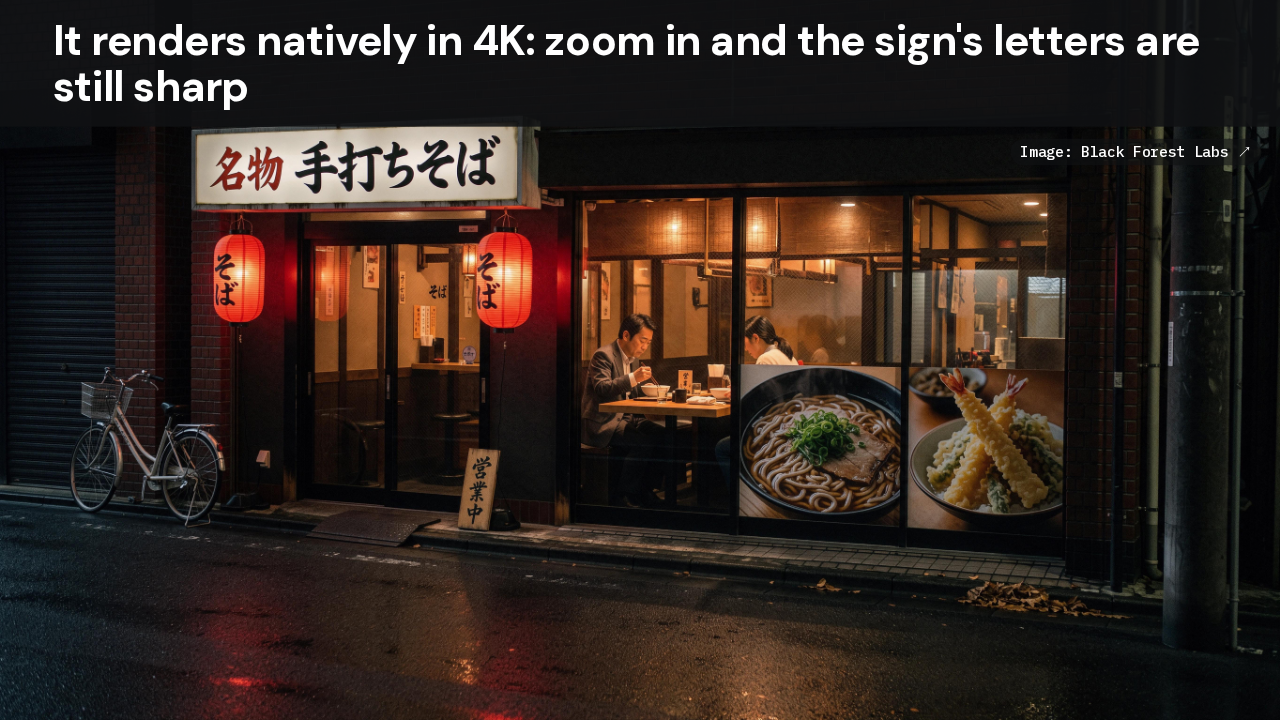
It renders natively in 4K: zoom in and the sign's letters are still sharp

And it renders at full size, up to 4 K, rather than scaling up a small picture. This soba shop is about sixteen megapixels, all from the model. Here's the sign at the file's own pixels: hand-lettered characters, each about two hundred pixels tall. And through the window, a man eating, chopsticks in hand.
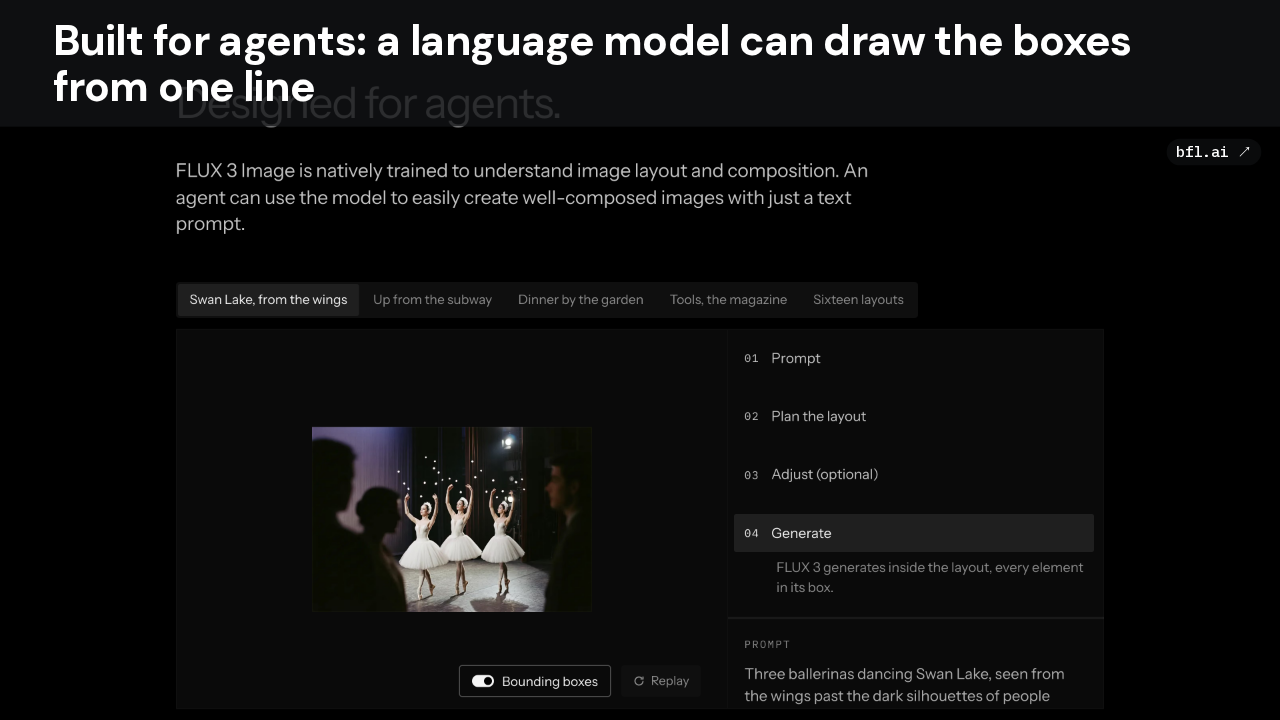
Built for agents: a language model can draw the boxes from one line

You don't have to draw the boxes yourself. B F L says it's built so an agent can use it from a plain text prompt. A language model writes the caption and the table of boxes, and FLUX three paints inside them.
FLUX 3 Image is in Black Forest Labs' API now, and companies can license the weights
Released 1 October 2026 (BFL's API release notes). Not open weights: BFL offers the weights under a commercial licence, to fine-tune and run on your own servers.
FLUX three Image went into B F L's API on October first, 2026. The weights aren't open: companies can license them to fine-tune and run on their own servers. The model page and the release notes are linked below.