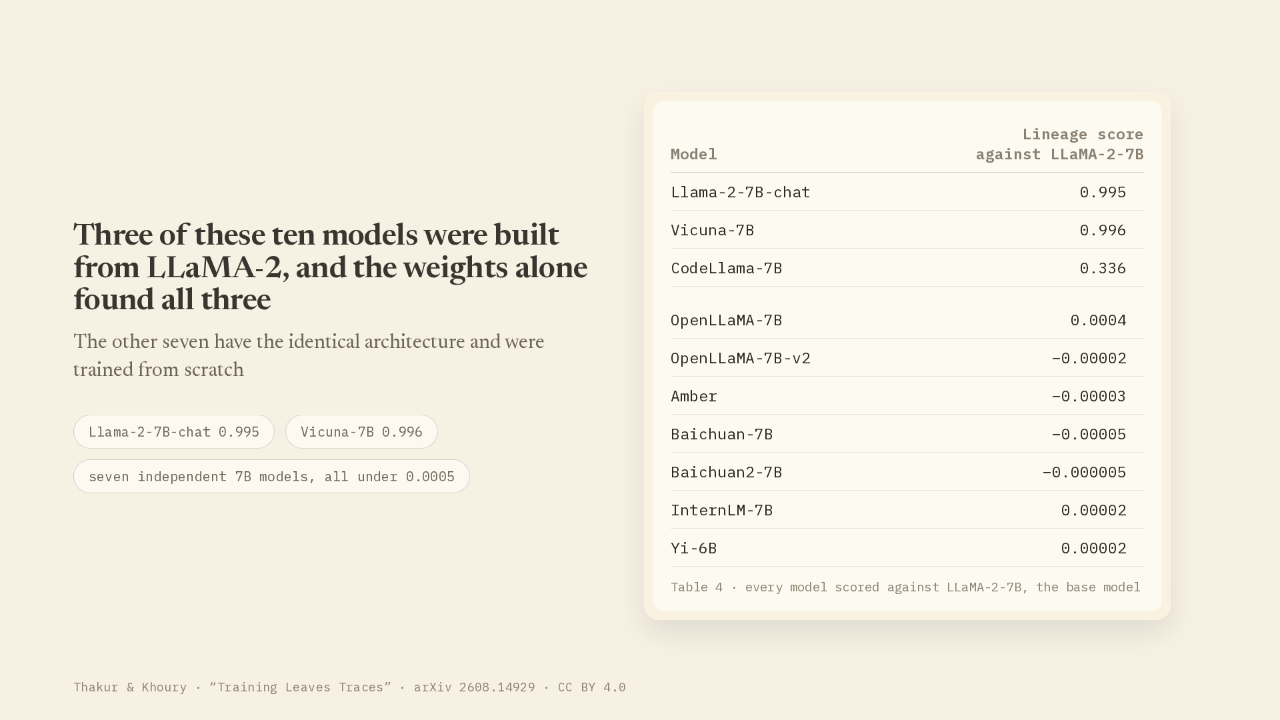
Three of these ten models were built from LLaMA-2, and the weights alone found all three
| Model | Lineage score against LLaMA-2-7B |
|---|---|
| Llama-2-7B-chat | 0.995 |
| Vicuna-7B | 0.996 |
| CodeLlama-7B | 0.336 |
| OpenLLaMA-7B | 0.0004 |
| OpenLLaMA-7B-v2 | −0.00002 |
| Amber | −0.00003 |
| Baichuan-7B | −0.00005 |
| Baichuan2-7B | −0.000005 |
| InternLM-7B | 0.00002 |
| Yi-6B | 0.00002 |
Somebody releases a model, and you think they built it out of yours. Can you show that from the files? Weights are the millions of numbers training adjusts, and the only thing you get when you download a model. The team compared Llama-2 with ten other models using the weights and nothing else. The three models built from Llama-2 scored near the top of the scale. The seven models trained from scratch scored essentially zero.
Two model files of the same shape, and nothing else, decide the question

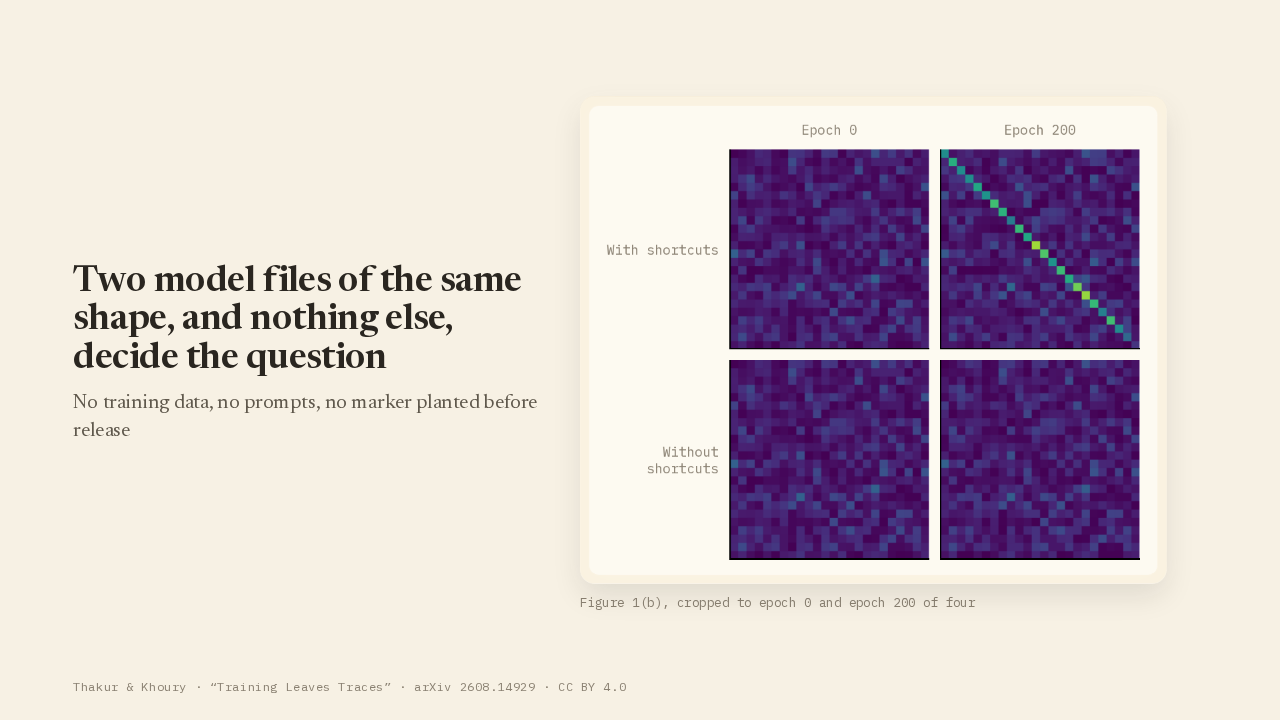
Give this method two model files and nothing more. The two models have to be the same shape: same number of layers, same width. The method tells you whether one model was trained from the other. The signal survives fine-tuning. Fine-tuning is training an existing model a bit further on new material, and it is how most released models are made. The signal also survives when somebody scrambles a model's insides on purpose to hide where it came from.
Every layer learns to change its input less and less
input out
back
together
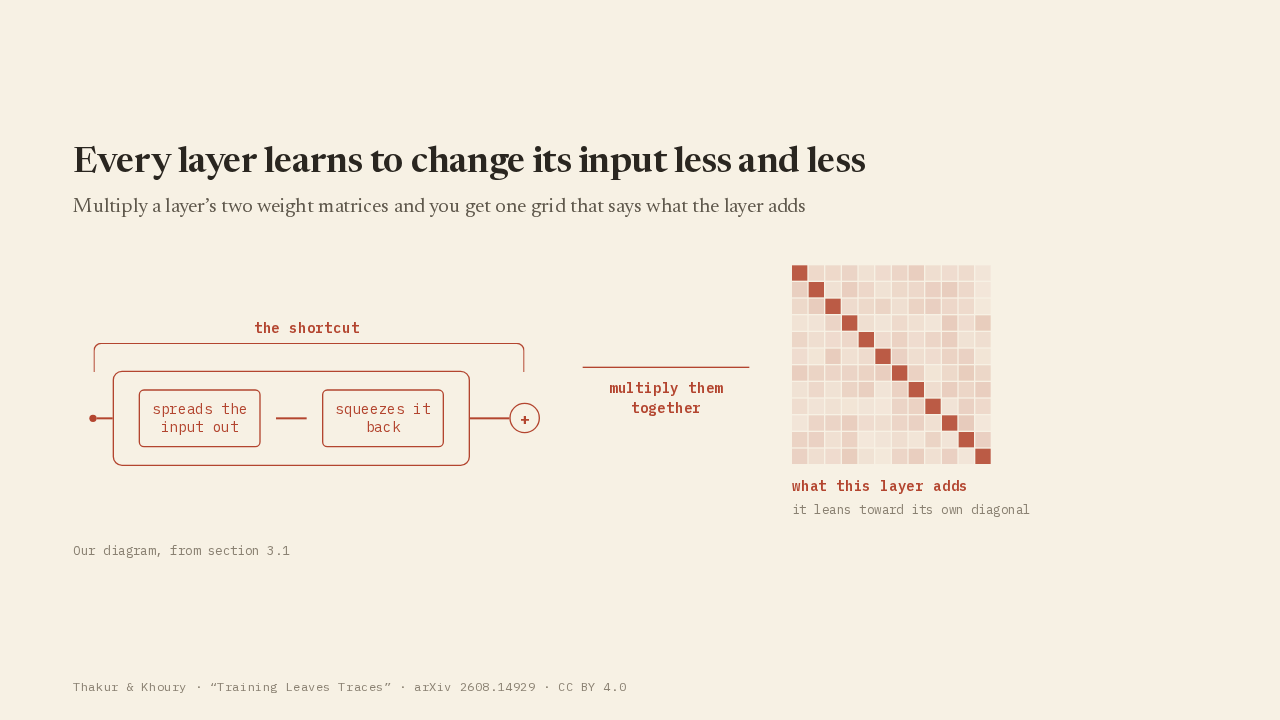
Modern models are built in layers, and each layer adds a small correction on top of what came in, rather than replacing it. The input runs past on a shortcut, untouched, and the layer only decides what to add. Inside one of those corrections sit two blocks of numbers. The first block spreads the input out. The second block squeezes it back down. Multiply those two blocks together and you get one square grid of numbers that says everything this layer adds. Training pushes that grid in one direction: it drifts toward doing almost nothing. Step after step, the grid moves closer to simply passing its input straight through.
The part every trained model shares is the part that cannot identify one
the leftover
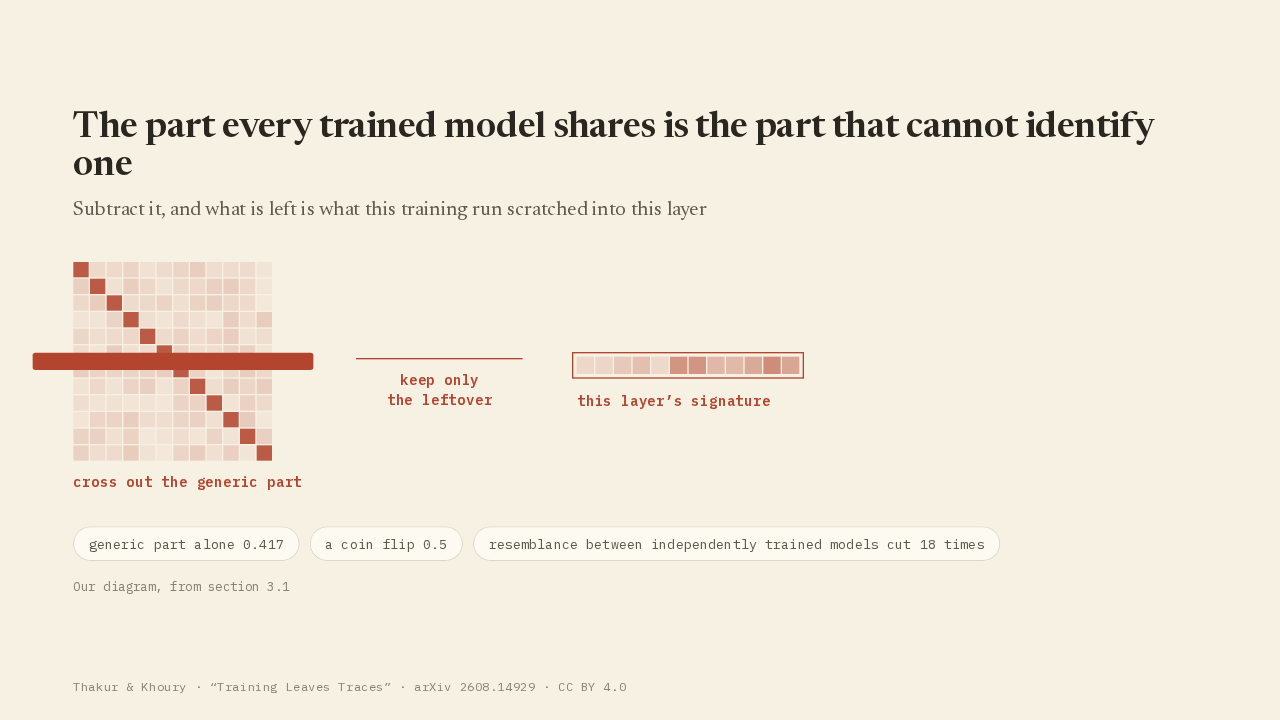
So you could measure how far along that drift a model has gone, and compare two models on that one number. That fails, and the failure teaches you the whole paper. A checker built on that measurement scored 0.417, where a coin flip scores 0.5. That is worse than guessing. The reason is that every trained model has this generic part. Drifting toward doing nothing is what training does, so the generic part cannot tell two models apart. The fix is to subtract the generic part and keep only the leftover. The leftover is the pattern this training run scratched into this layer, and that pattern is what a descendant inherits. Throwing the generic part away cut the accidental resemblance between two independently trained models by a factor of eighteen.
Two models reduce to one number, built from every layer’s leftover
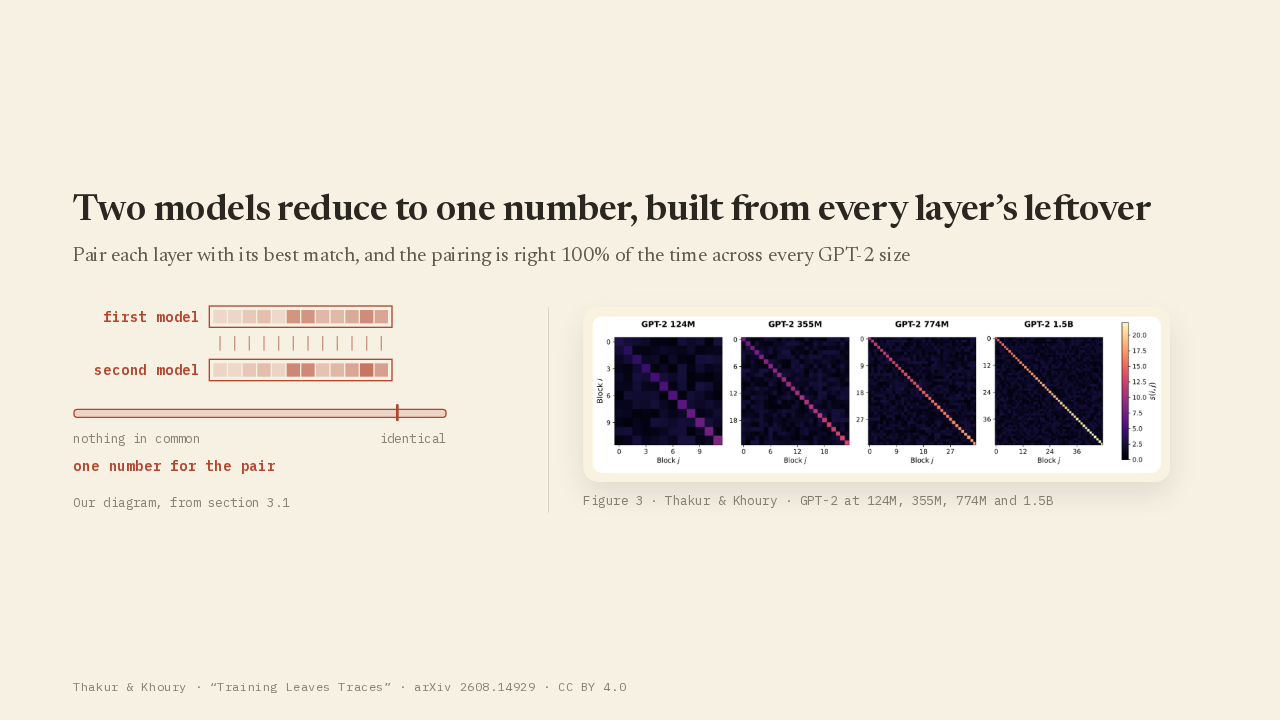
Now the comparison is simple. Take every layer of the first model and every layer of the second, and check how closely their leftovers line up, on a scale from nothing in common to identical. Pair each layer with its best match in the other model, average those matches, and you have a single number. Related models land near one. Unrelated models land near zero. Across GPT-2 models, from a hundred and twenty-four million of those numbers up to one and a half billion, every layer matched its own counterpart, a hundred percent of the time. Plot each layer against each layer and the matches land on the diagonal.
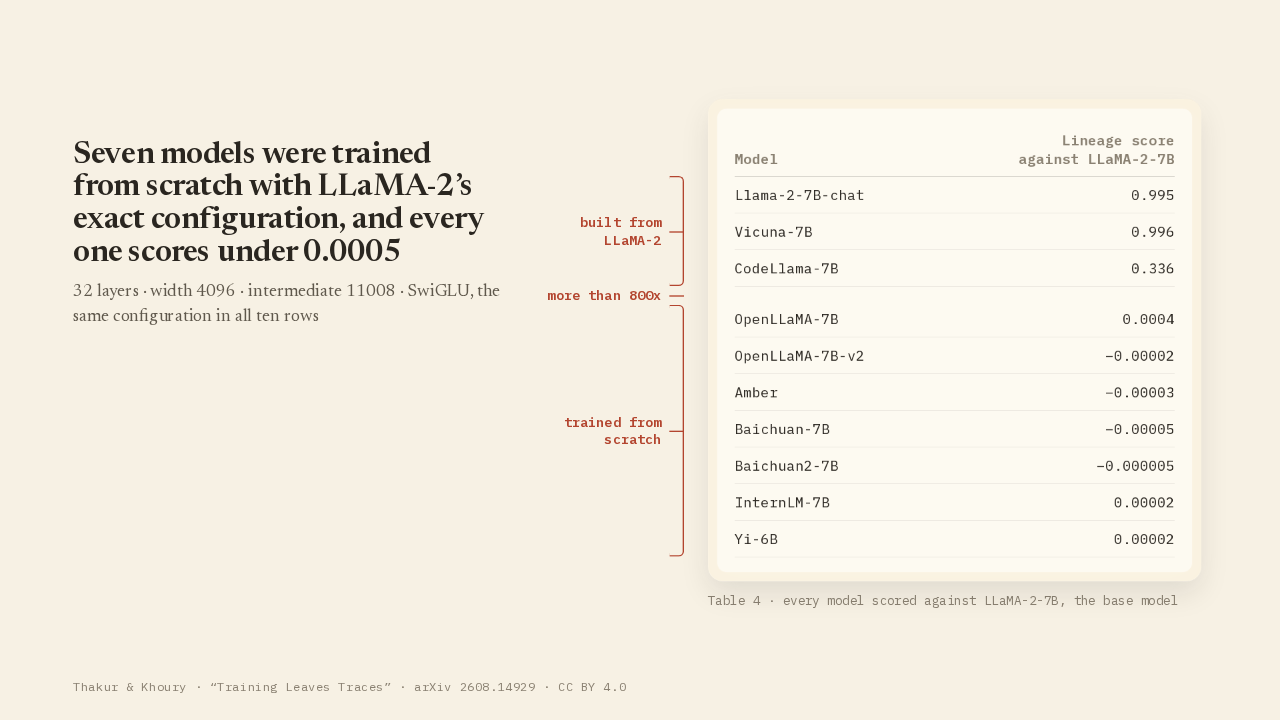
Seven models were trained from scratch with LLaMA-2’s exact configuration, and every one scores under 0.0005
LLaMA-2
scratch
| Model | Lineage score against LLaMA-2-7B |
|---|---|
| Llama-2-7B-chat | 0.995 |
| Vicuna-7B | 0.996 |
| CodeLlama-7B | 0.336 |
| OpenLLaMA-7B | 0.0004 |
| OpenLLaMA-7B-v2 | −0.00002 |
| Amber | −0.00003 |
| Baichuan-7B | −0.00005 |
| Baichuan2-7B | −0.000005 |
| InternLM-7B | 0.00002 |
| Yi-6B | 0.00002 |
Here are those ten models again. Llama-2-7B-chat scores 0.995. Vicuna, a fine-tune of the same base model, scores 0.996. CodeLlama was trained much further, on code, and drifted a long way. CodeLlama scores 0.336, lower, and still unmistakable. Then come the seven models trained independently. Every one of those seven has Llama-2's exact architecture, thirty-two layers and the same width, so on paper they look identical to it. All seven score under 0.0005. CodeLlama, the weakest of the three built from Llama-2, still sits more than eight hundred times above the strongest independent.
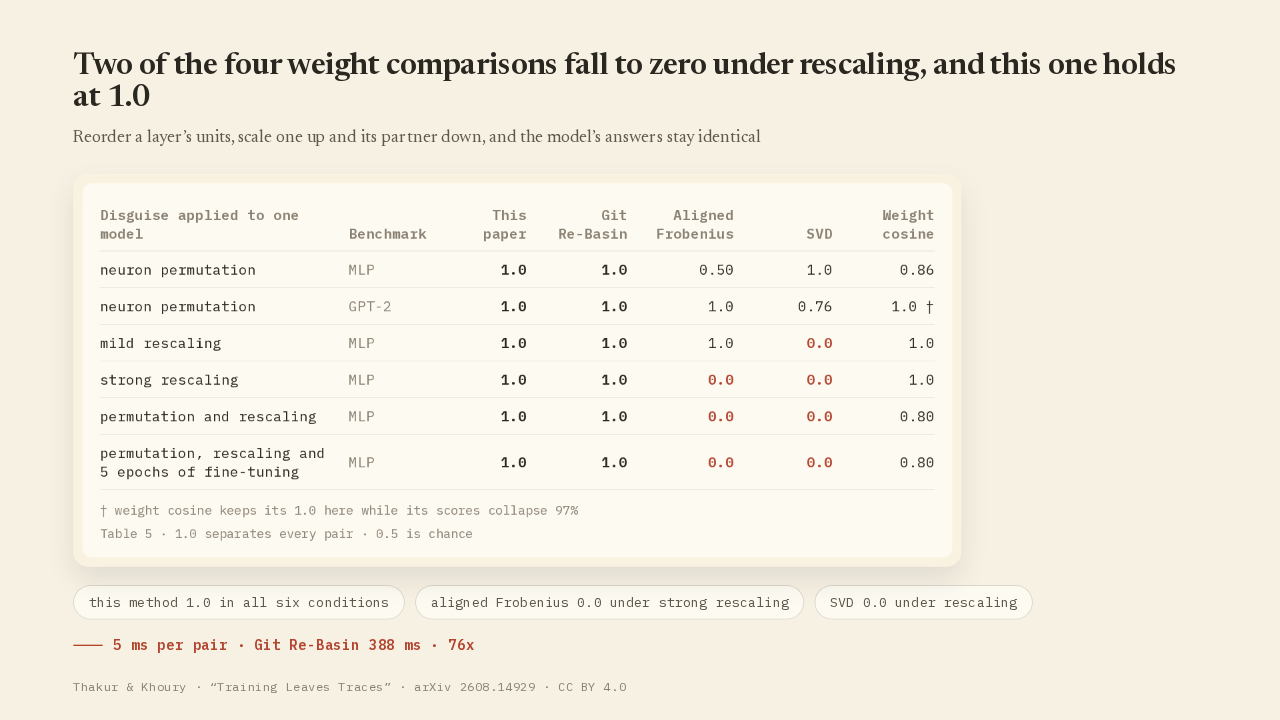
Two of the four weight comparisons fall to zero under rescaling, and this one holds at 1.0
| Disguise applied to one model | Benchmark | This paper | Git Re-Basin | Aligned Frobenius | SVD | Weight cosine |
|---|---|---|---|---|---|---|
| neuron permutation | MLP | 1.0 | 1.0 | 0.50 | 1.0 | 0.86 |
| neuron permutation | GPT-2 | 1.0 | 1.0 | 1.0 | 0.76 | 1.0 † |
| mild rescaling | MLP | 1.0 | 1.0 | 1.0 | 0.0 | 1.0 |
| strong rescaling | MLP | 1.0 | 1.0 | 0.0 | 0.0 | 1.0 |
| permutation and rescaling | MLP | 1.0 | 1.0 | 0.0 | 0.0 | 0.80 |
| permutation, rescaling and 5 epochs of fine-tuning | MLP | 1.0 | 1.0 | 0.0 | 0.0 | 0.80 |
Inside a layer you can reorder the internal units, and you can scale one unit up while scaling its partner down, and the model still computes exactly the same answers. That is what somebody would do to hide a stolen model. The rescaling is what breaks the obvious weight comparisons: at full strength, two of the four methods tested lose all their separating power. This paper's score does not move at all. Across four public model families, shuffling the units changed the score by less than one ten-millionth. One rival holds up too. Git Re-Basin searches for the right reordering and matches this method on the test set, at three hundred and eighty-eight milliseconds a pair against five.
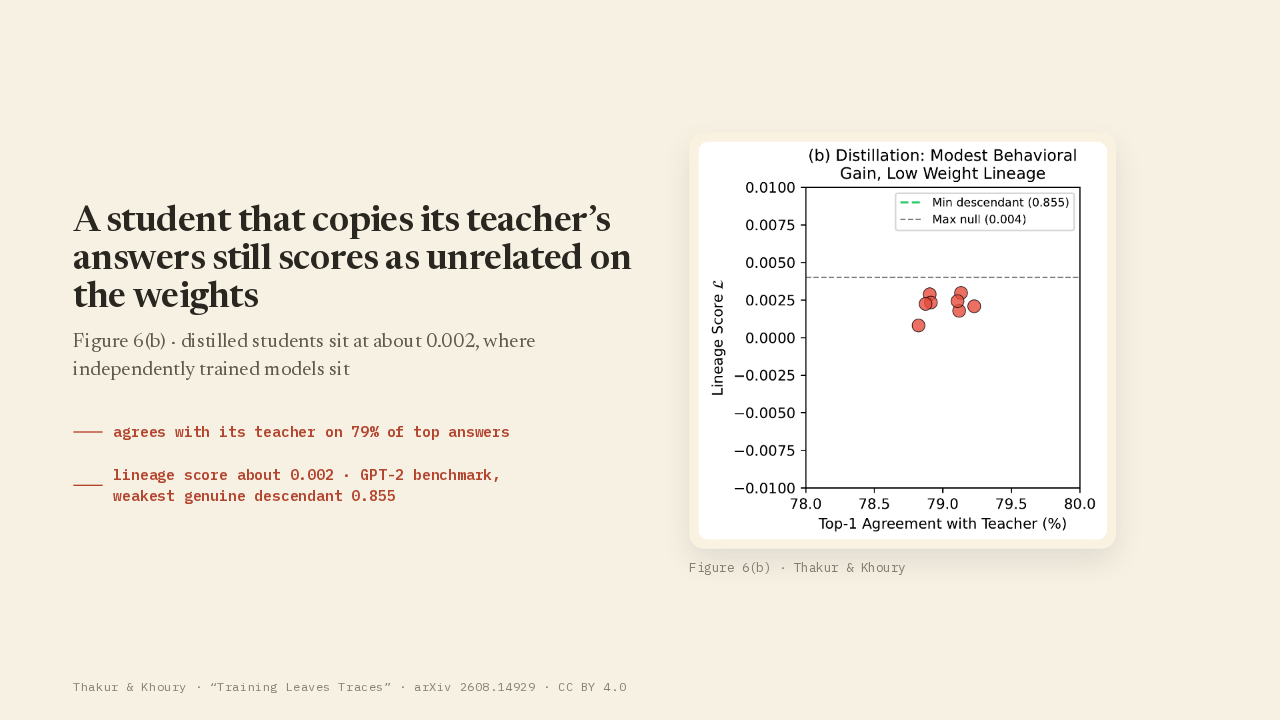
A student that copies its teacher’s answers still scores as unrelated on the weights
weakest genuine descendant 0.855
Distillation is training a fresh model to imitate an existing model's answers, without ever copying its numbers. You would expect a copy to give itself away by behaving like the original. This distilled student agreed with its teacher on seventy-nine percent of its top answers, and its weights still scored about 0.002, deep in the unrelated range. The student and its teacher sit in the GPT-2 benchmark, where the weakest genuine descendant scored 0.855. The score measures how a model was built. How a model answers is a separate question.
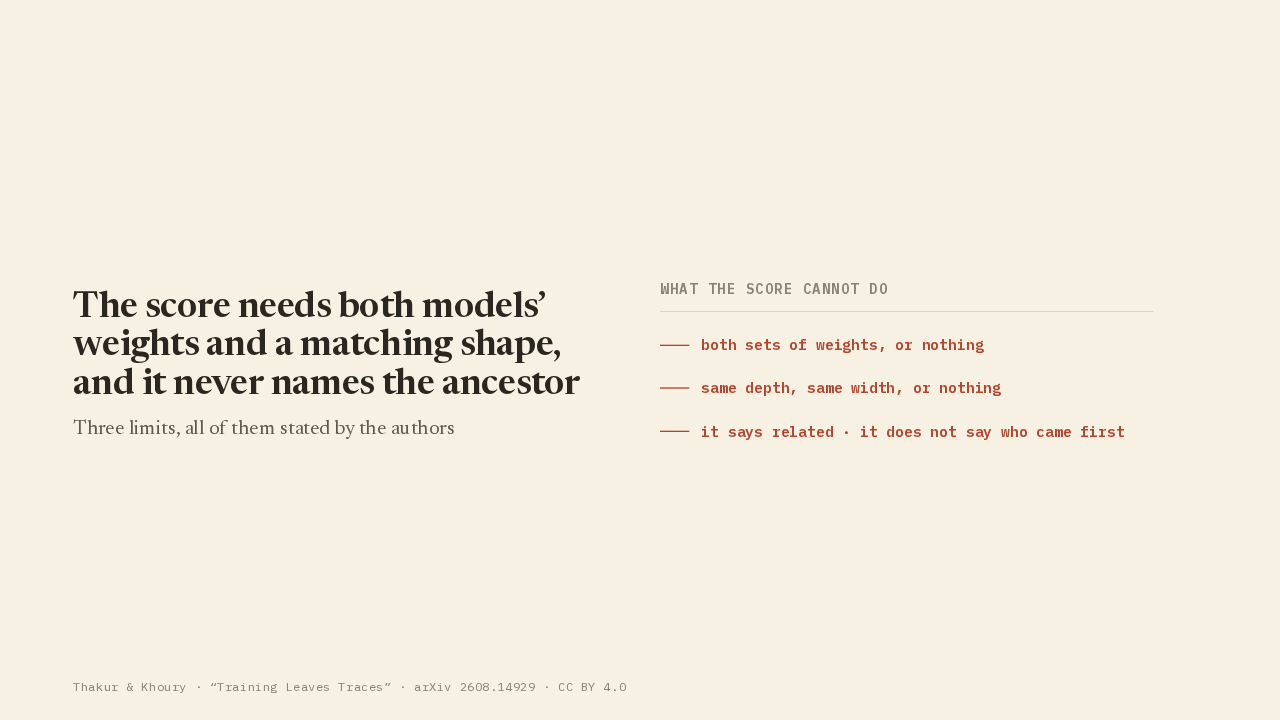
The score needs both models’ weights and a matching shape, and it never names the ancestor
Three hard limits, all stated by the authors. You need the actual model files for both sides. A model you can only reach over the internet, by sending it questions and reading its answers, cannot be checked at all. Both models have to be the same shape, the same number of layers and the same width, so there is no comparing a Llama with a GPT-2. And the score is symmetric. It says these two models are related, and it cannot say which one came first.
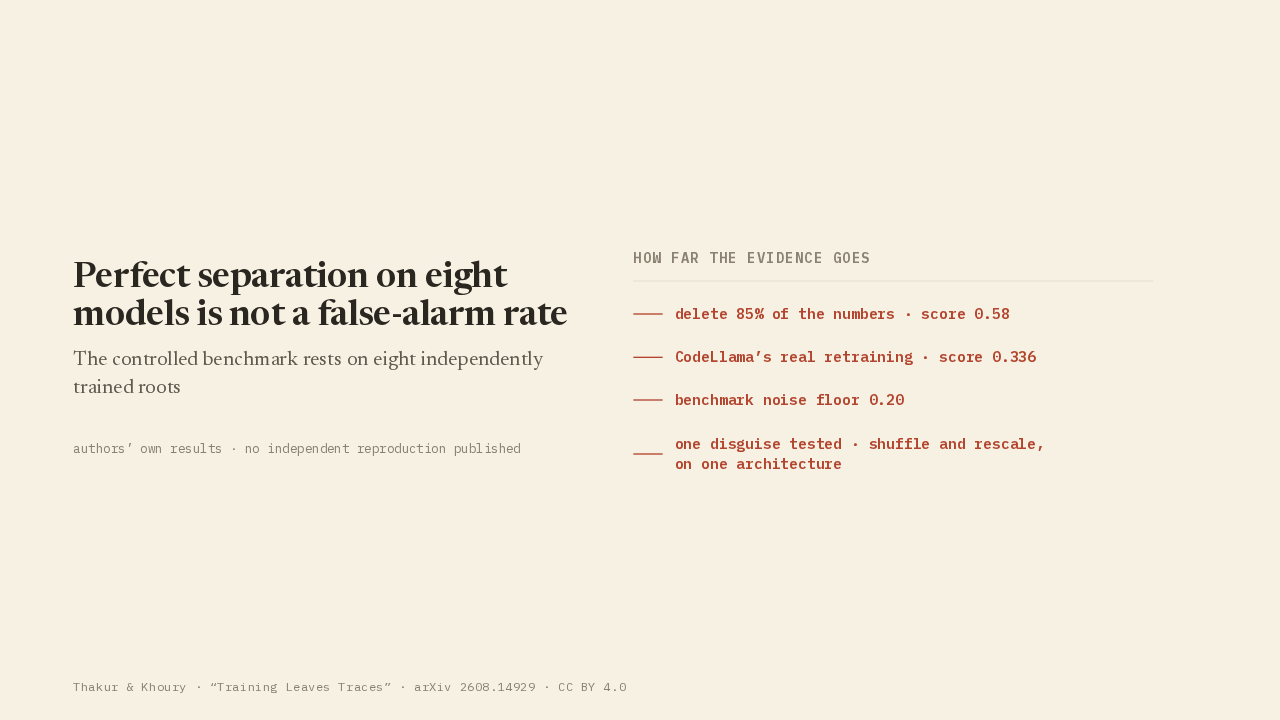
Perfect separation on eight models is not a false-alarm rate
on one architecture
Delete eighty-five percent of a model's numbers and the score falls to 0.58. CodeLlama's real retraining brought its score to 0.336. Both stay above the benchmark's noise floor of 0.20, with less room to spare. The controlled benchmark rests on eight independently trained models. That is why the authors report what their own test set showed and leave the false-alarm rate unstated. They tested one disguise, shuffling and rescaling, on one architecture.
Read it
“Training Leaves Traces: Centered Residual Signatures
for Language Model Lineage Verification”
arXiv:2608.14929v1 · 14 August 2026 · preprint, no venue stated
Read it. The mechanism is a page of linear algebra you can follow in one sitting, and the idea under it travels: the part every trained model shares is exactly the part that cannot identify one. Read it rather than build on it. With eight models of calibration and no way to say which model came first, this paper hands you a strong signal and stops there. Aman Singh Thakur, at Amazon, and Rayan Khoury, at MIT. Training Leaves Traces, arXiv two six zero eight point one four nine two nine.