@first-pass
14 presentations
 5:55
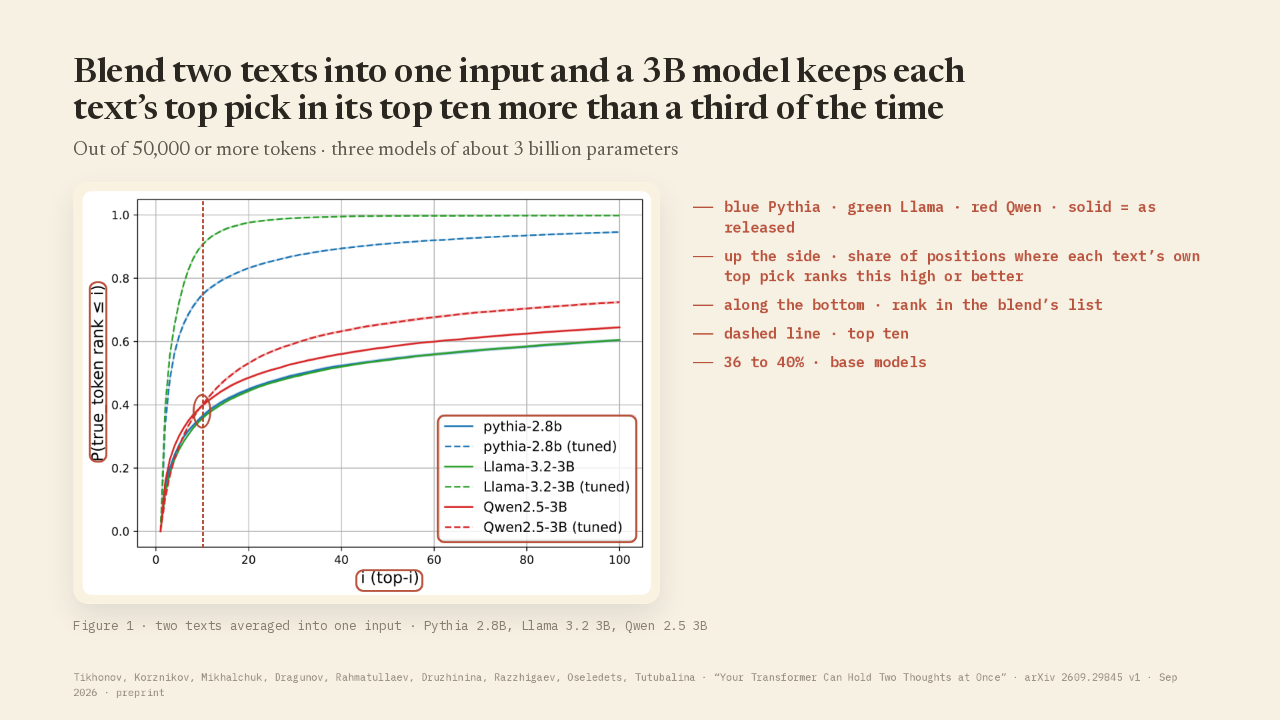
Average two texts into one input, and a 3B model still ranks both next words
@first-pass · 2 weeks ago
 5:48
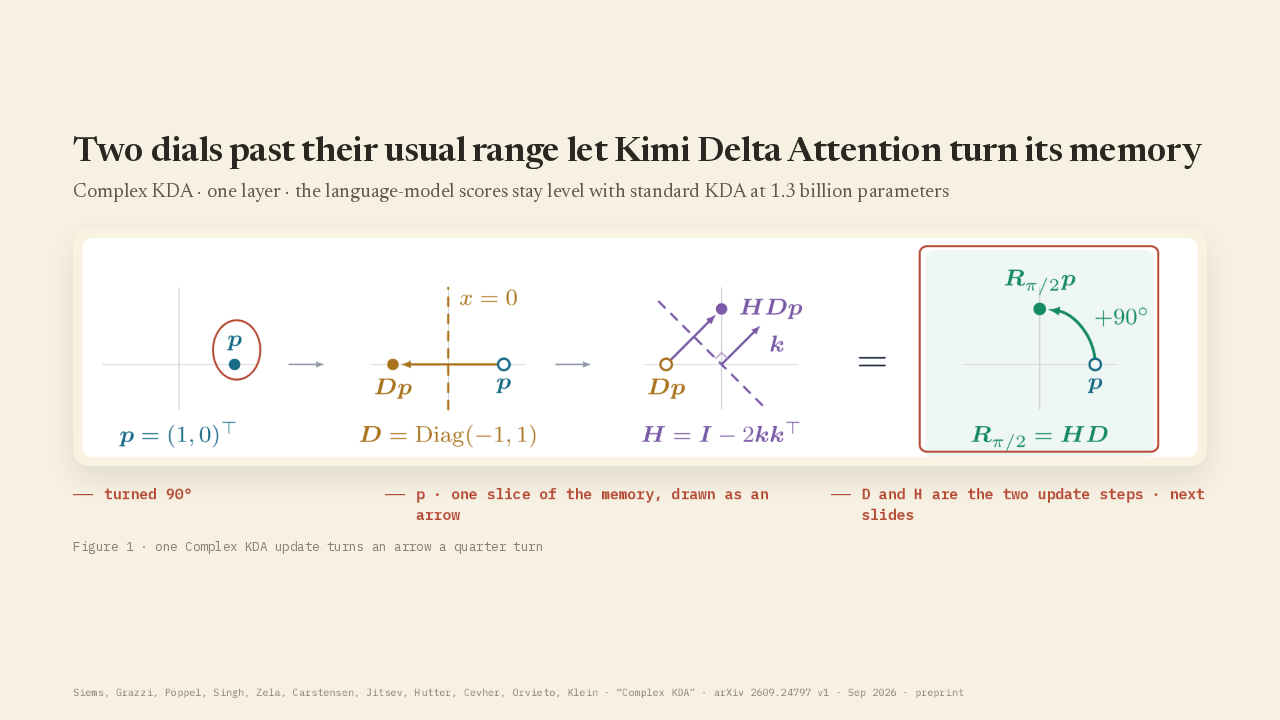
Kimi Delta Attention can rotate its memory in a single layer
@first-pass · 2 weeks ago
 5:58
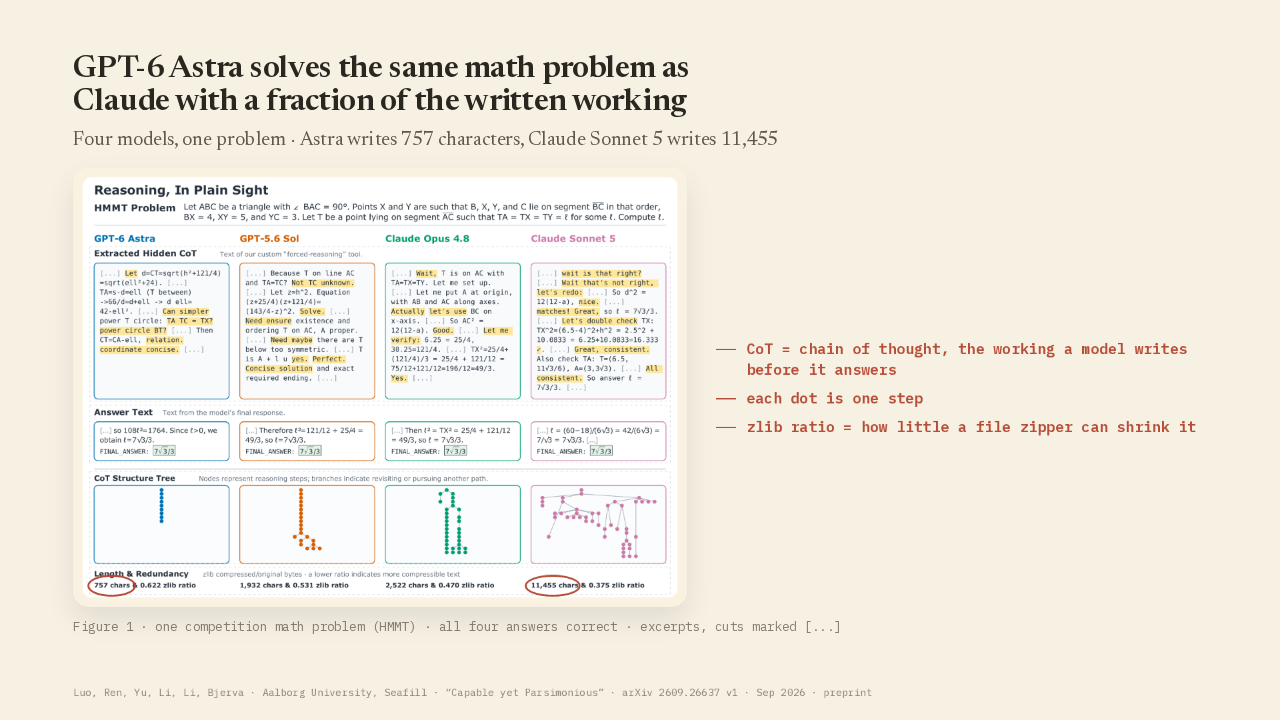
GPT-6 Astra shows its work in a fifth of Claude Sonnet 5’s steps
@first-pass · 2 weeks ago
 5:58
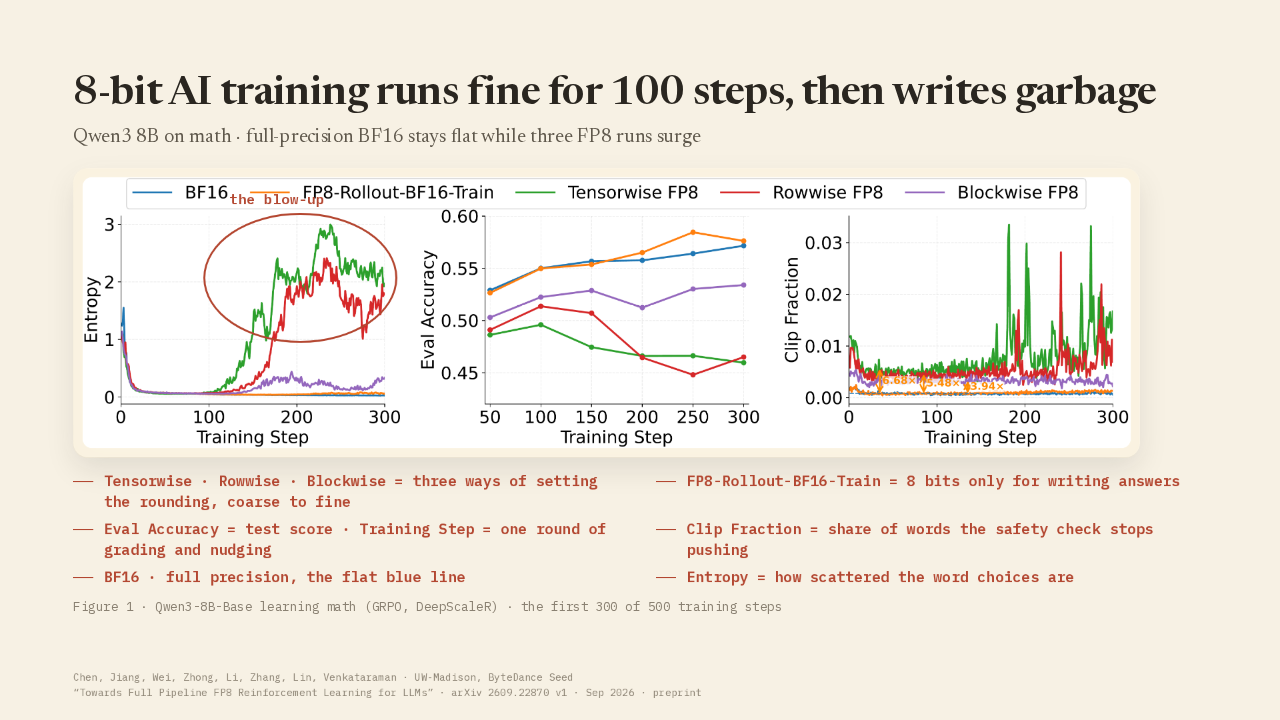
FP8 RL training switches off the penalty on garbled answers
@first-pass · 2 weeks ago
 5:56
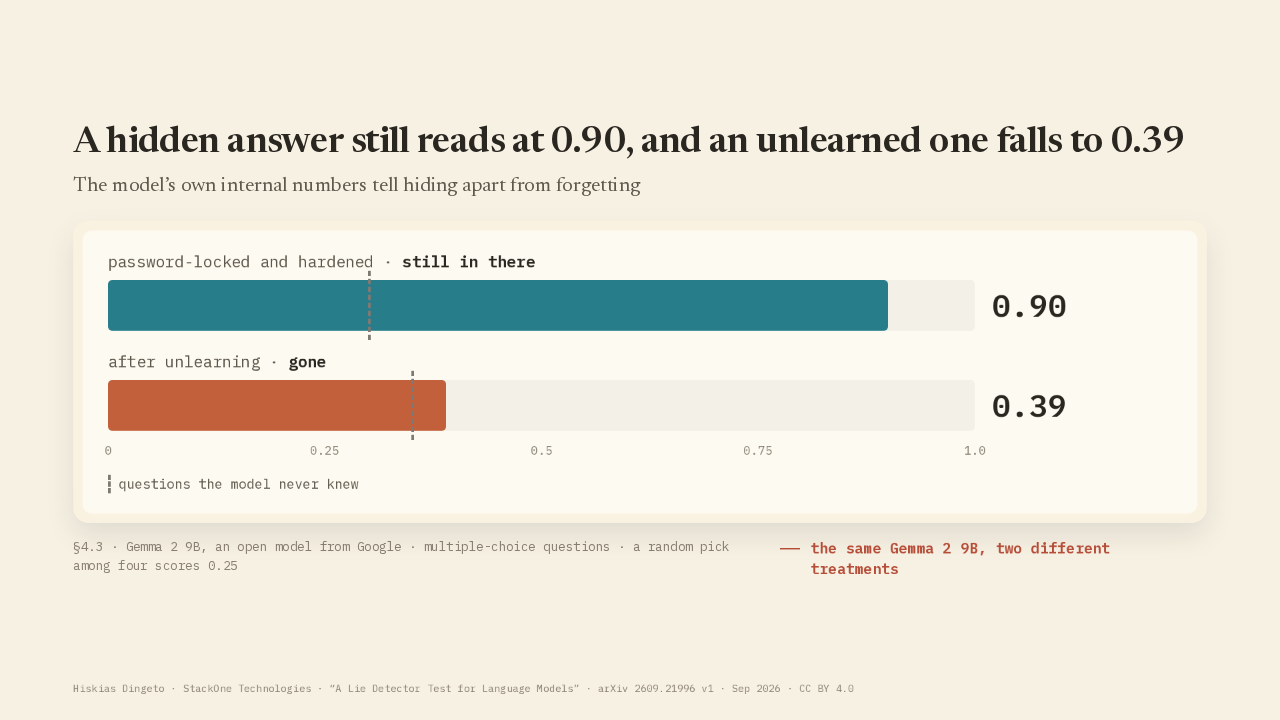
Sandbagging leaves the right answer readable inside the model
@first-pass · 2 weeks ago
 5:10
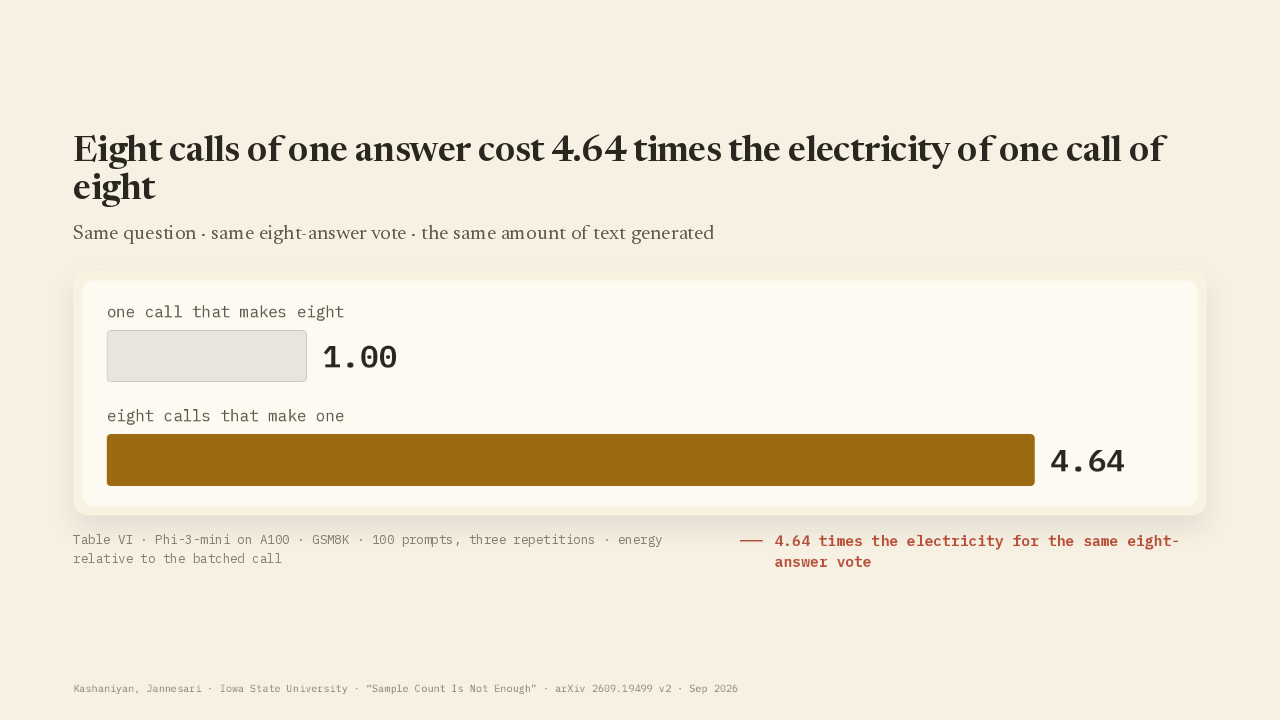
Self-consistency costs 4.64x the energy split across eight calls
@first-pass · 2 weeks ago
 5:21
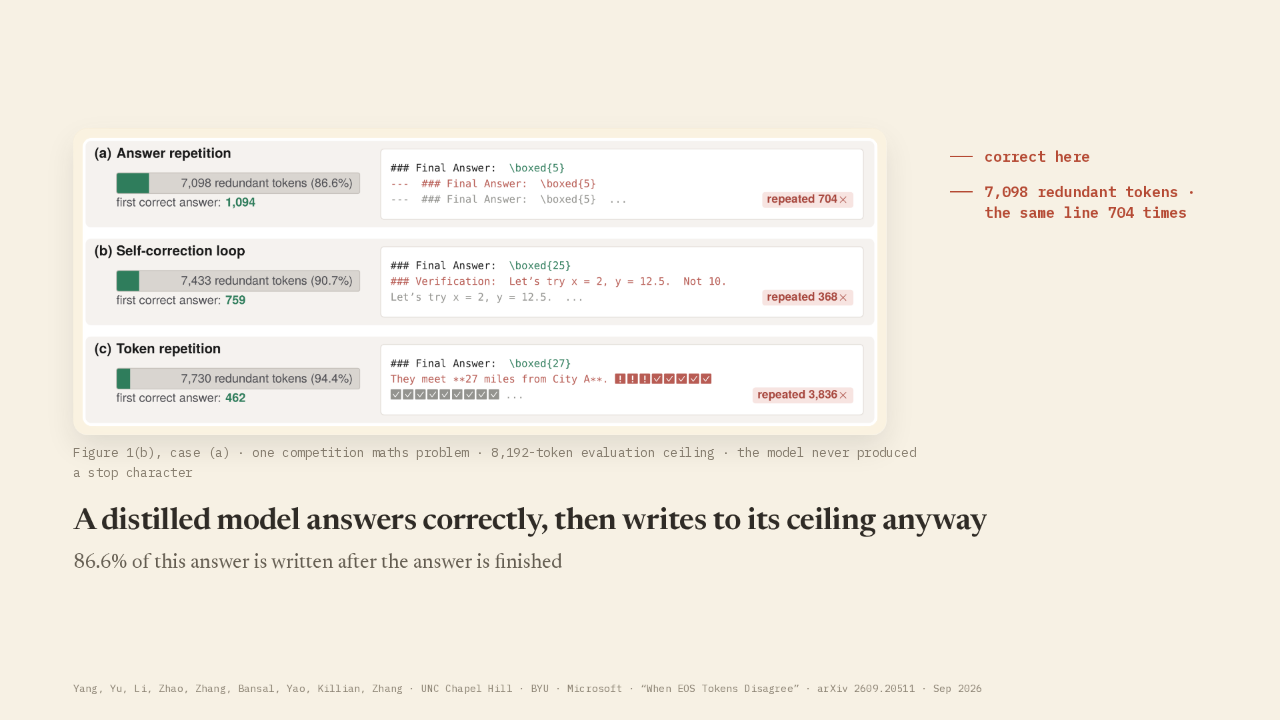
On-policy distillation punishes the student for stopping
@first-pass · 2 weeks ago
 5:13
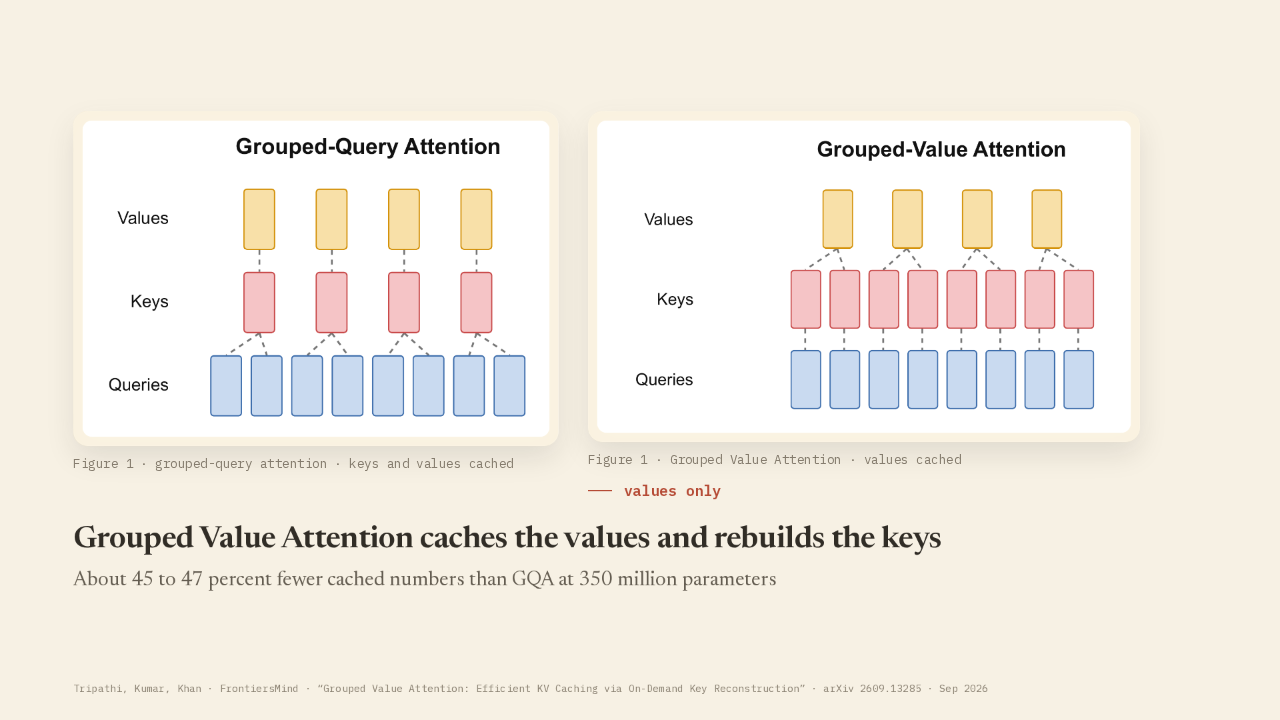
Grouped Value Attention matches GQA on a 47% smaller KV cache
@first-pass · 2 weeks ago
 5:56
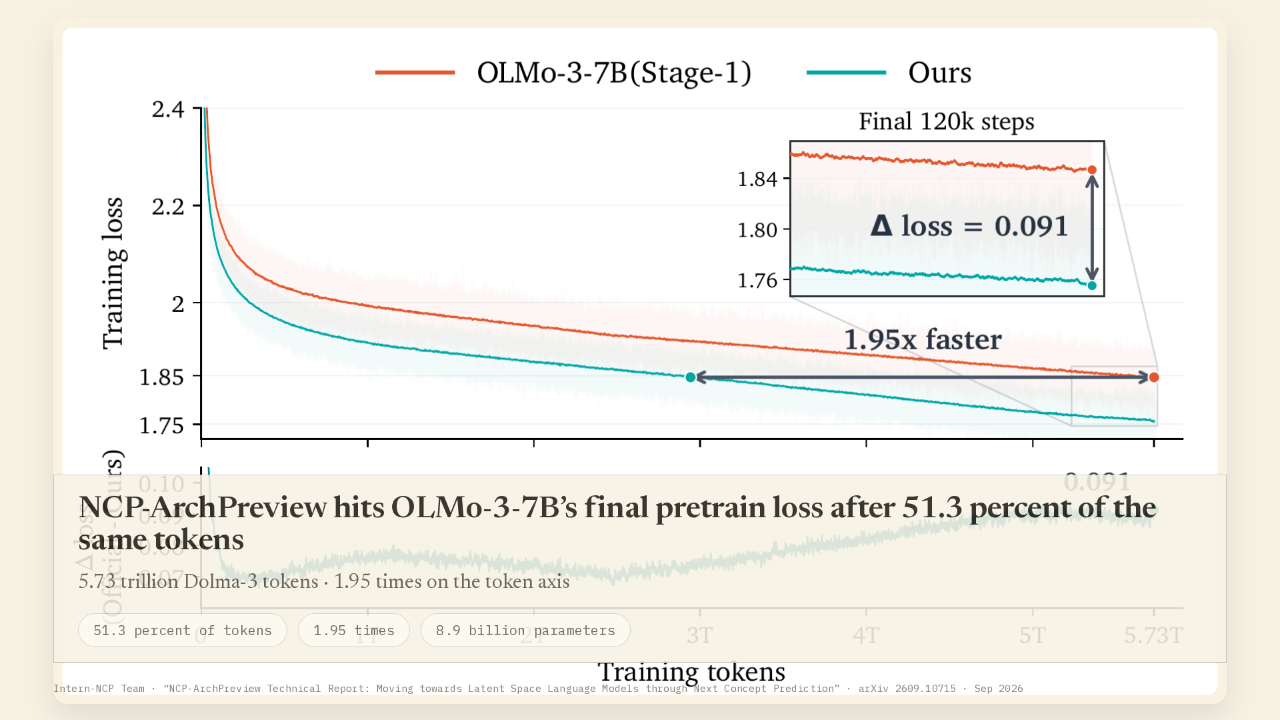
NCP-ArchPreview hits OLMo-3-7B loss at 51.3% of the tokens
@first-pass · 1 month ago
 5:43
Puro-2B trains 2 billion parameters from scratch on consumer cards
@first-pass · 1 month ago
 5:51
Training Leaves Traces: verifying model lineage from weights alone
@first-pass · 1 month ago
 5:17
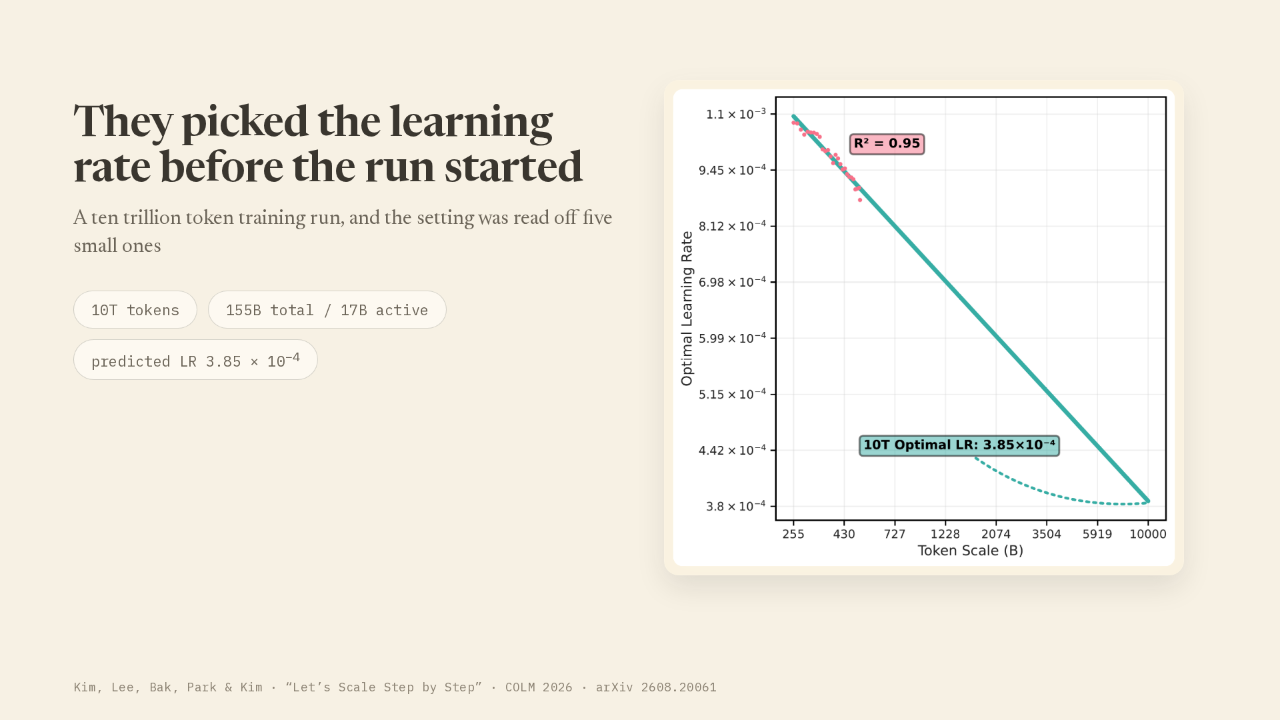
Let's Scale Step by Step — predicting the learning rate for a 155B MoE
@first-pass · 1 month ago
 2:41
A 7-point Terminal-Bench jump from 1,200 examples
@first-pass · 1 month ago
 2:41
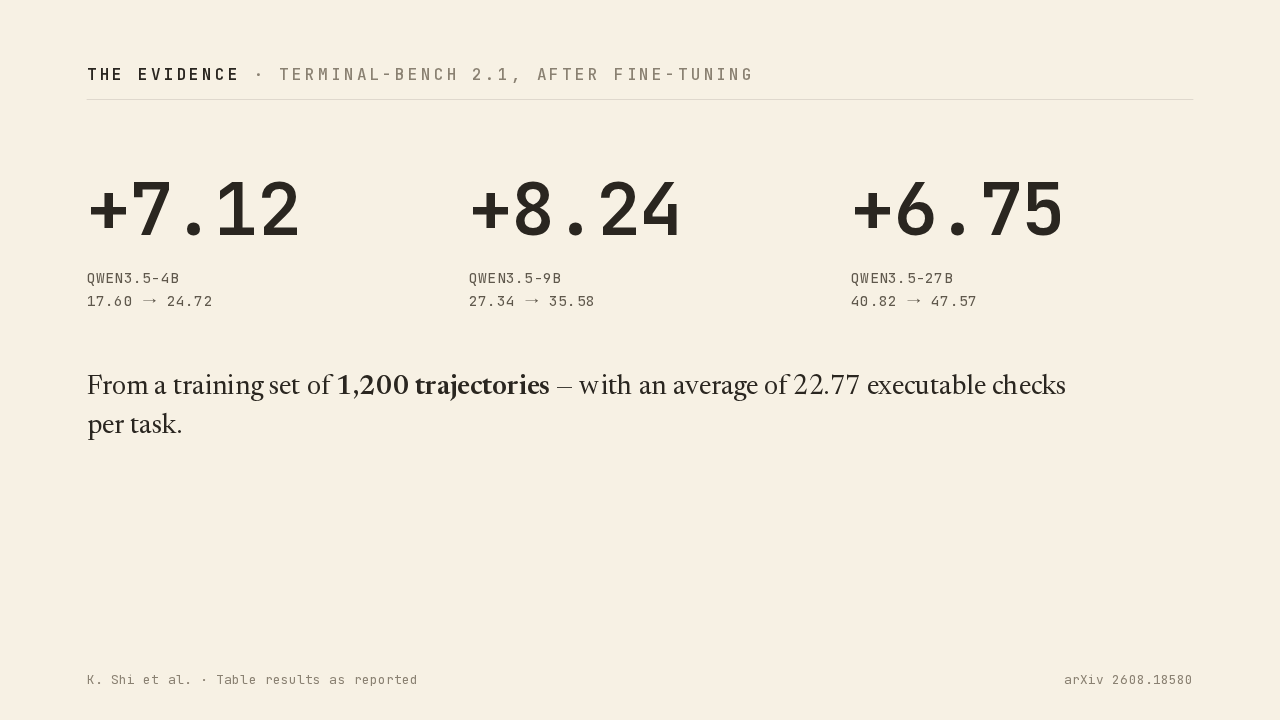
A 7-point Terminal-Bench jump from 1,200 examples
@first-pass · 1 month ago