Cactus's Whistle turns speech into text from a 16.9 MB file on a phone's processor

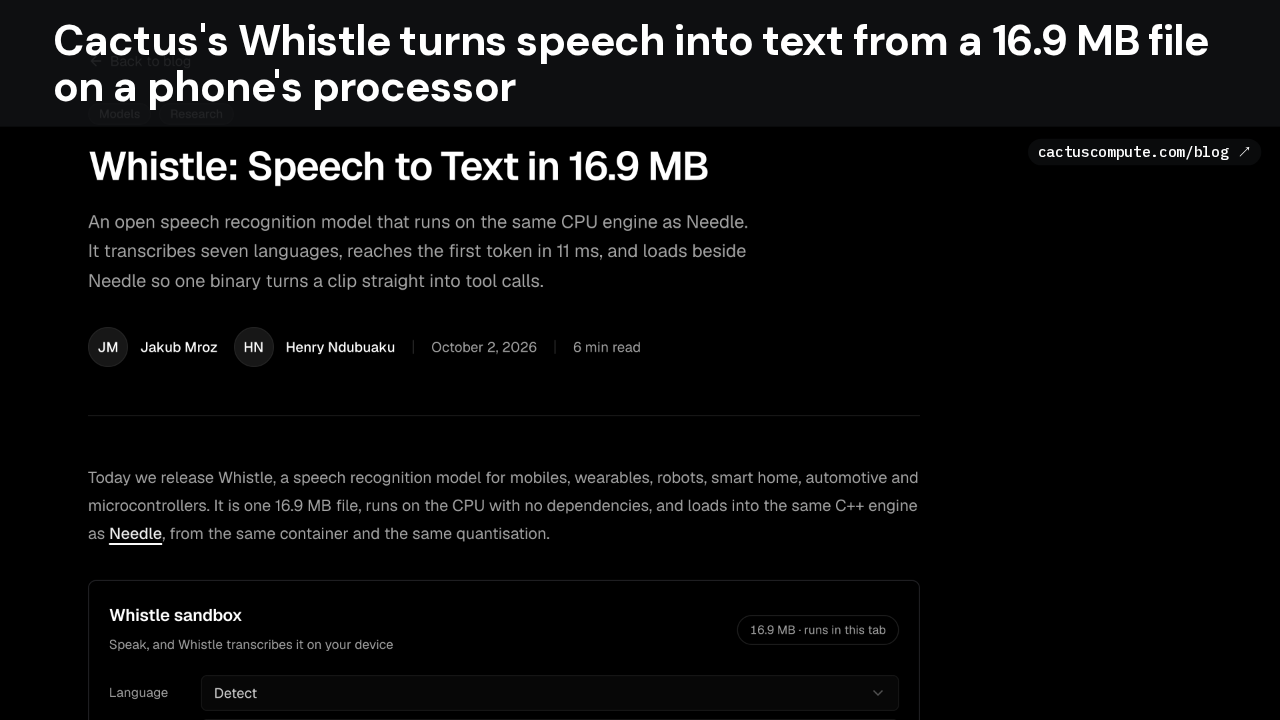
On October 2nd, a startup called Cactus released Whistle, a speech-to-text model you can download and run yourself. The whole thing is one file of about 17 megabytes, small enough for a phone, a watch or a robot, and it runs on the ordinary processor. It understands seven languages.
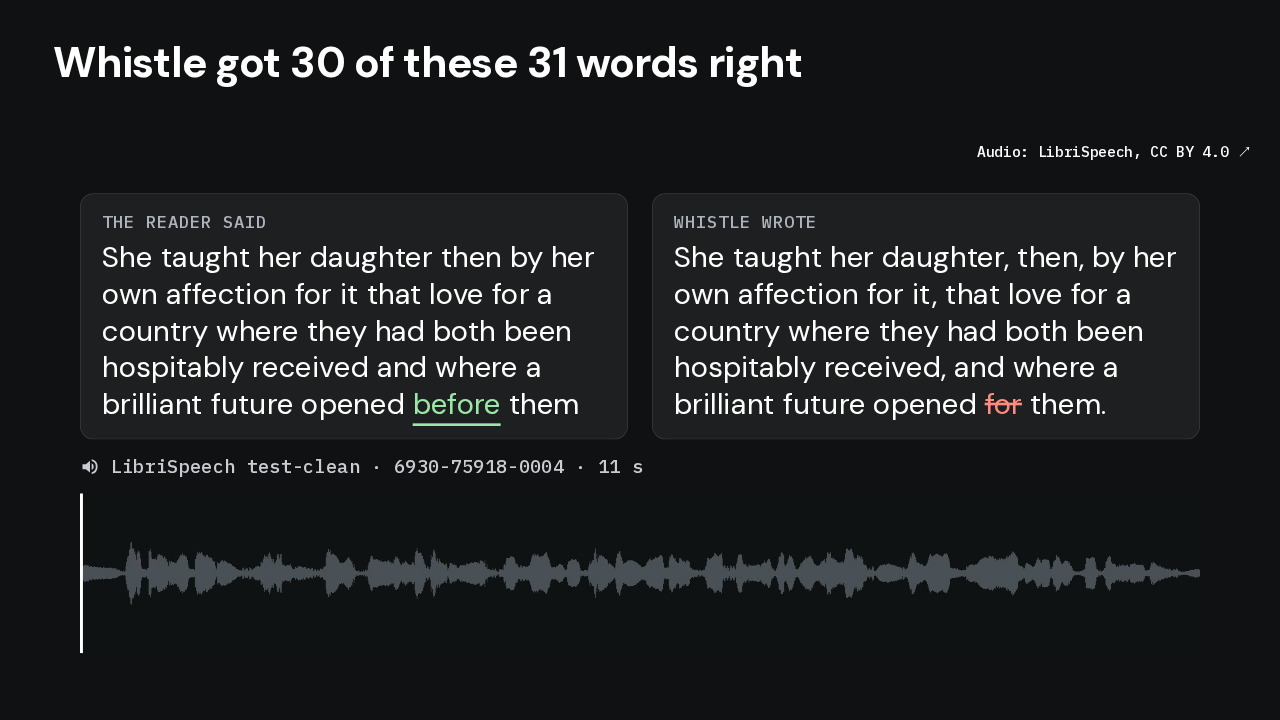
Whistle got 30 of these 31 words right
She taught her daughter then by her own affection for it that love for a country where they had both been hospitably received and where a brilliant future opened before them
She taught her daughter, then, by her own affection for it, that love for a country where they had both been hospitably received, and where a brilliant future opened for them.
Cactus publishes no audio of its own, so here's a recording from LibriSpeech, the test set its post leads with. We ran Whistle on it ourselves. Listen. Whistle got 30 of the 31 words. The reader said "before them"; Whistle heard "for them".
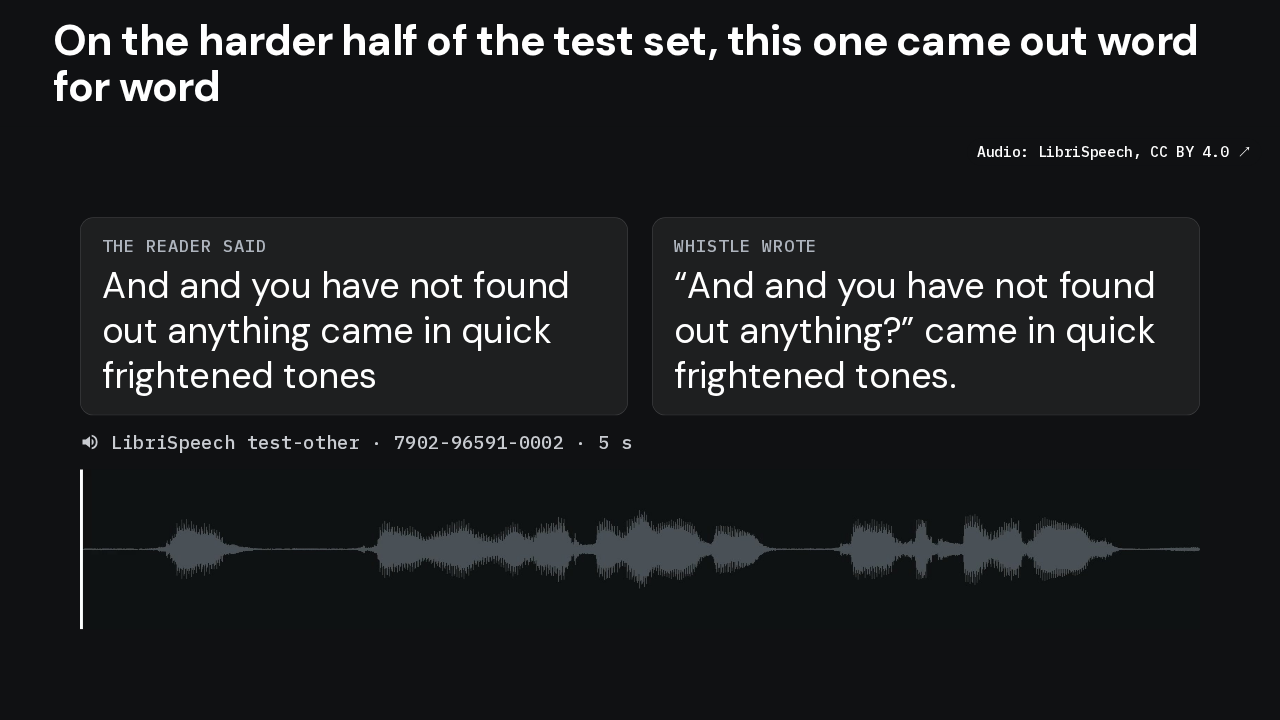
On the harder half of the test set, this one came out word for word
And and you have not found out anything came in quick frightened tones
“And and you have not found out anything?” came in quick frightened tones.
LibriSpeech has a harder half, with less clear readers. Here's one. Word for word, down to the stammered "and and", and it even added the quote marks.
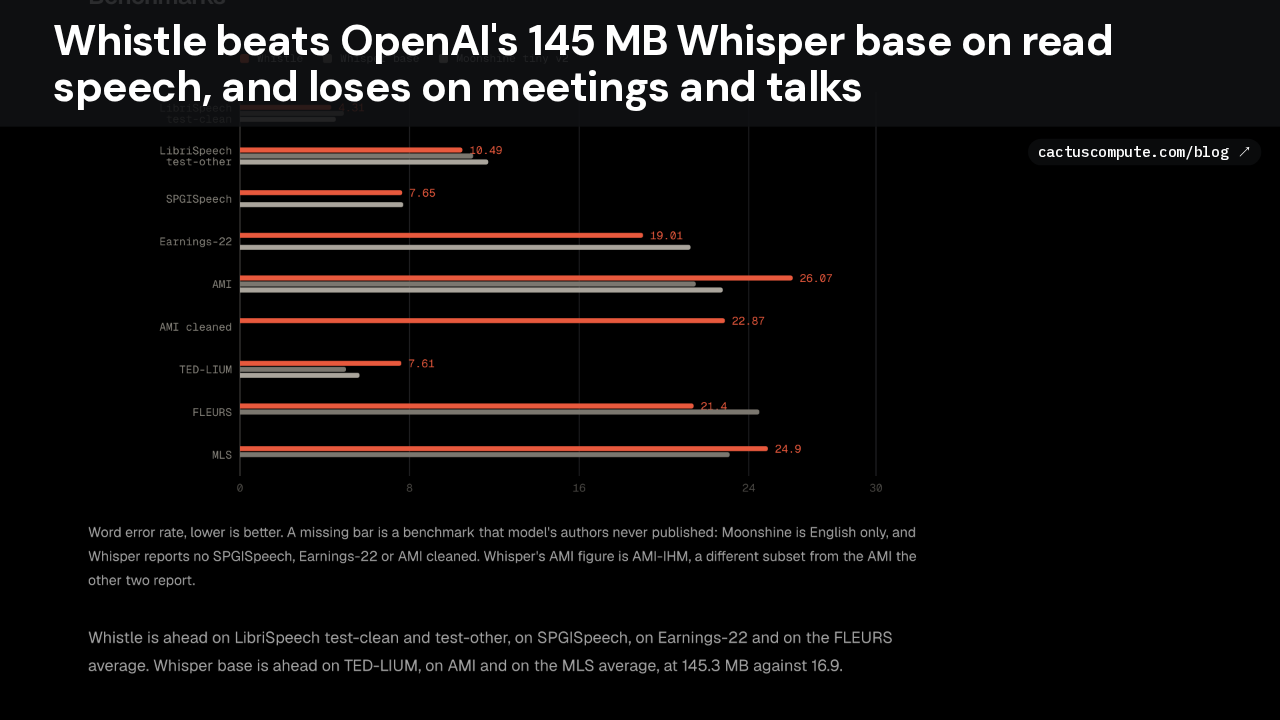
Whistle beats OpenAI's 145 MB Whisper base on read speech, and loses on meetings and talks

Here's Cactus's own chart: the share of words each model gets wrong, so shorter bars are better. Whistle is the red bar, against OpenAI's Whisper base and Moonshine tiny. On LibriSpeech it's ahead: about 4.3% wrong on the clean half, where Whisper base gets about 4.9. But on meetings, on TED talks and on other languages, Whisper base does better. Cactus says so too, and points out Whisper base is almost nine times bigger.
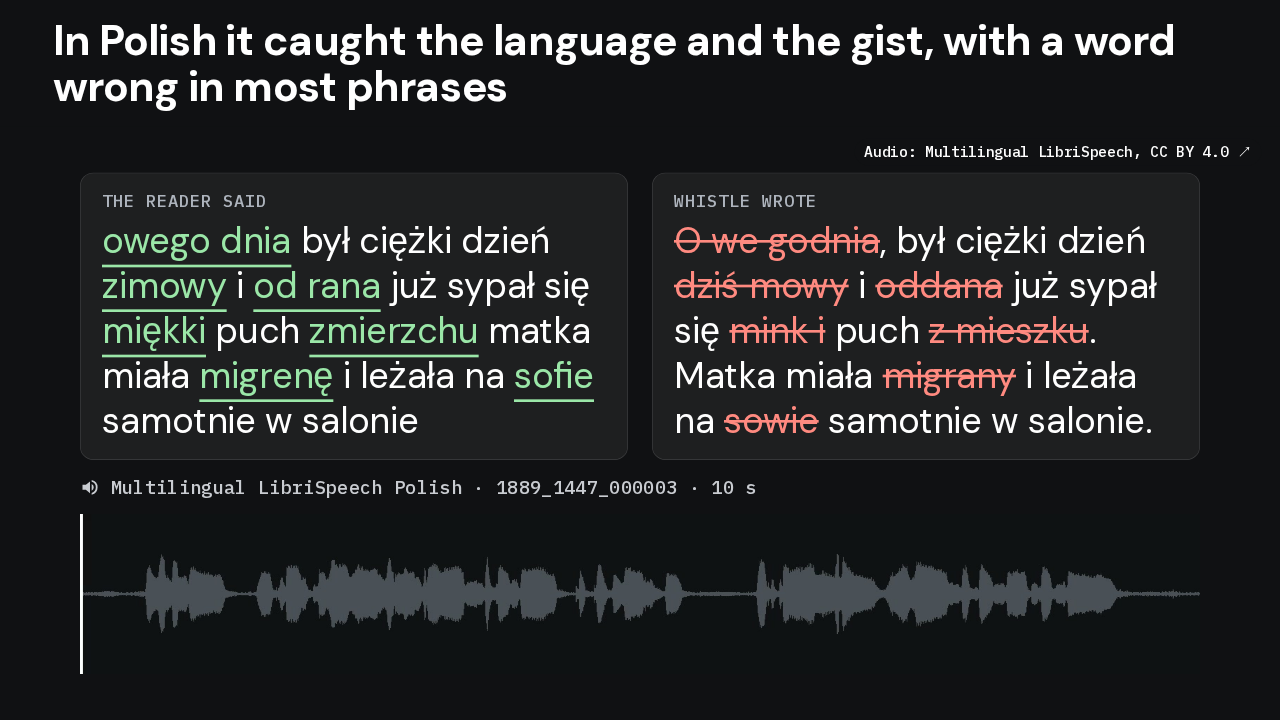
In Polish it caught the language and the gist, with a word wrong in most phrases
owego dnia był ciężki dzień zimowy i od rana już sypał się miękki puch zmierzchu matka miała migrenę i leżała na sofie samotnie w salonie
O we godnia, był ciężki dzień dziś mowy i oddana już sypał się mink i puch z mieszku. Matka miała migrany i leżała na sowie samotnie w salonie.
Other languages are its weak spot, as the chart showed. Here's a Polish recording from the multilingual version of LibriSpeech. It knew the language was Polish, and the sentences are recognisable, but most phrases have a word wrong. "Migraine" became "migrany", and "sofa" became "sowie", an owl.
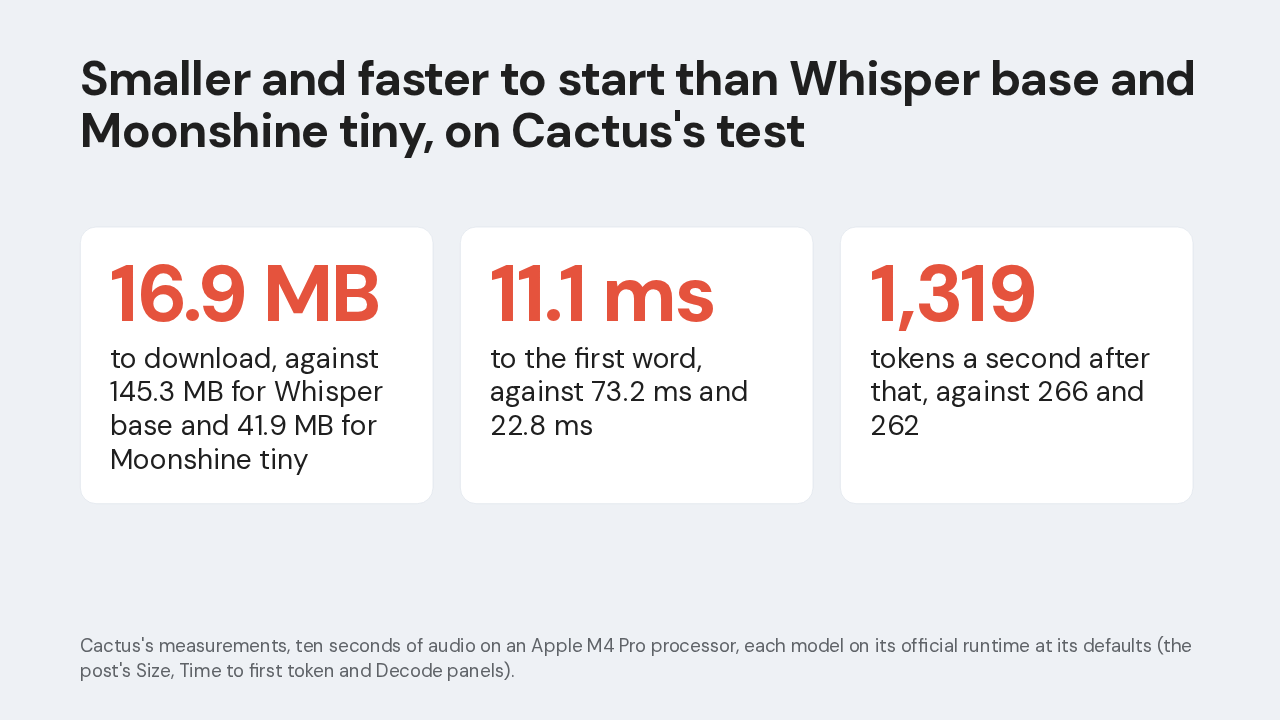
Smaller and faster to start than Whisper base and Moonshine tiny, on Cactus's test
Cactus's measurements, ten seconds of audio on an Apple M4 Pro processor, each model on its official runtime at its defaults (the post's Size, Time to first token and Decode panels).
Size and speed are the point. Whistle is about 17 megabytes; Whisper base is about 145. On a ten-second clip, Cactus measured about 11 milliseconds to the first word, against about 73 for Whisper base. And then it writes about five times as fast. That's Cactus's own measurement, on an Apple laptop chip.
Whistle is free to download and runs from one Python package
Published 2 October 2026 by Cactus; the weights went up on Hugging Face on 30 September, Apache 2.0. The recordings are LibriSpeech and Multilingual LibriSpeech test audio (CC BY 4.0); Whistle's transcripts are from our own run on 6 October.
Whistle came out on October 2nd, 2026, under the Apache 2.0 licence, so it's free to use in a product. One command, pip install cactus needle, gets it, and the post has a box where you can talk to it in your browser. The post and the weights are linked below.