ElevenLabs' Eleven v4 reads a line with the feeling you ask for in brackets

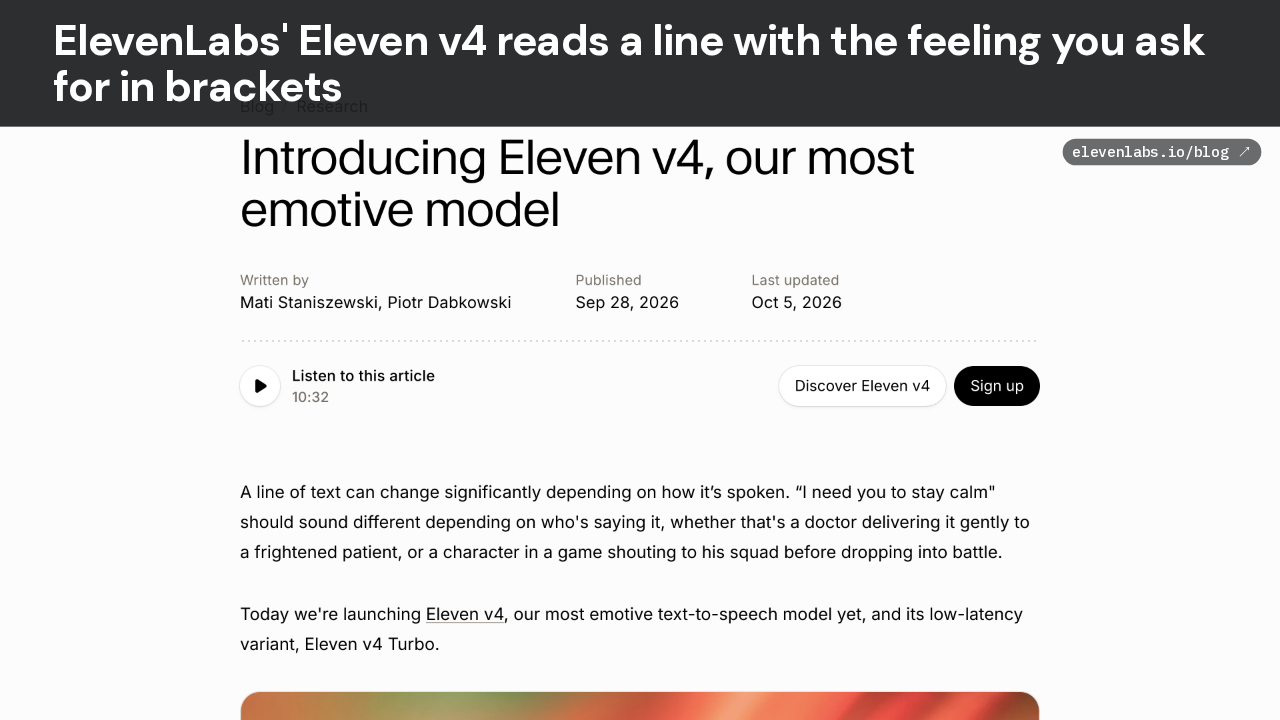
On September 28th, ElevenLabs released Eleven v4, its new text-to-speech model, and a faster version called v4 Turbo. The pitch is delivery: the same words, said the way the moment needs. Here's how it sounds, in ElevenLabs' own samples.
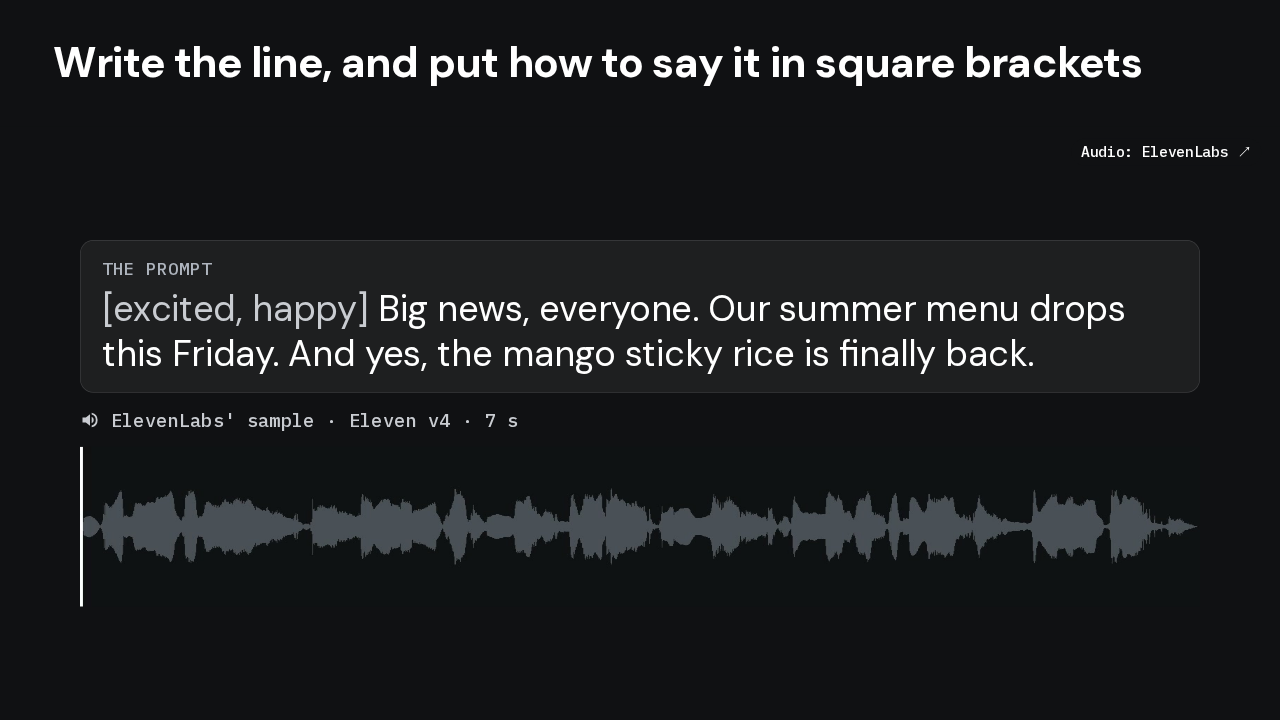
Write the line, and put how to say it in square brackets
[excited, happy] Big news, everyone. Our summer menu drops this Friday. And yes, the mango sticky rice is finally back.
This prompt asks for excited and happy, in square brackets, before the words. Listen. That's the file from ElevenLabs' launch post, untouched.
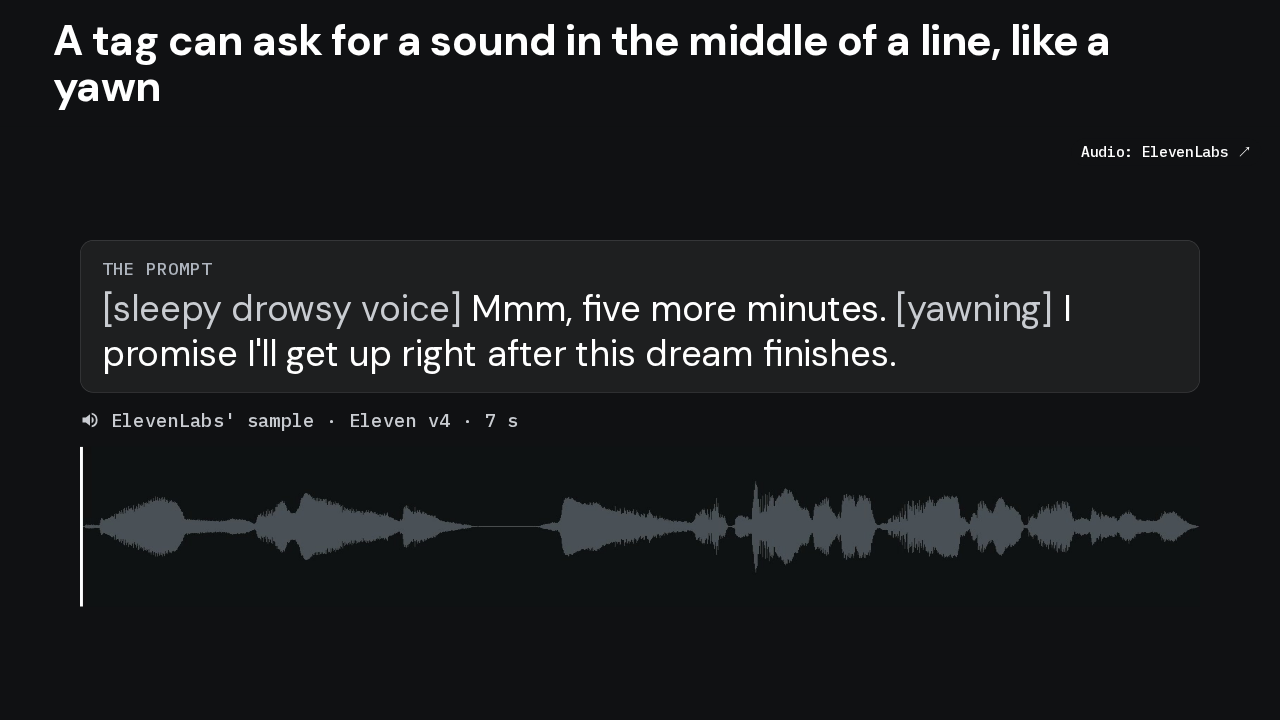
A tag can ask for a sound in the middle of a line, like a yawn
[sleepy drowsy voice] Mmm, five more minutes. [yawning] I promise I'll get up right after this dream finishes.
Tags can go anywhere in the line. This one starts sleepy, and asks for a yawn halfway through. ElevenLabs lists others, like laughs, said angrily in a French accent, and light rain.
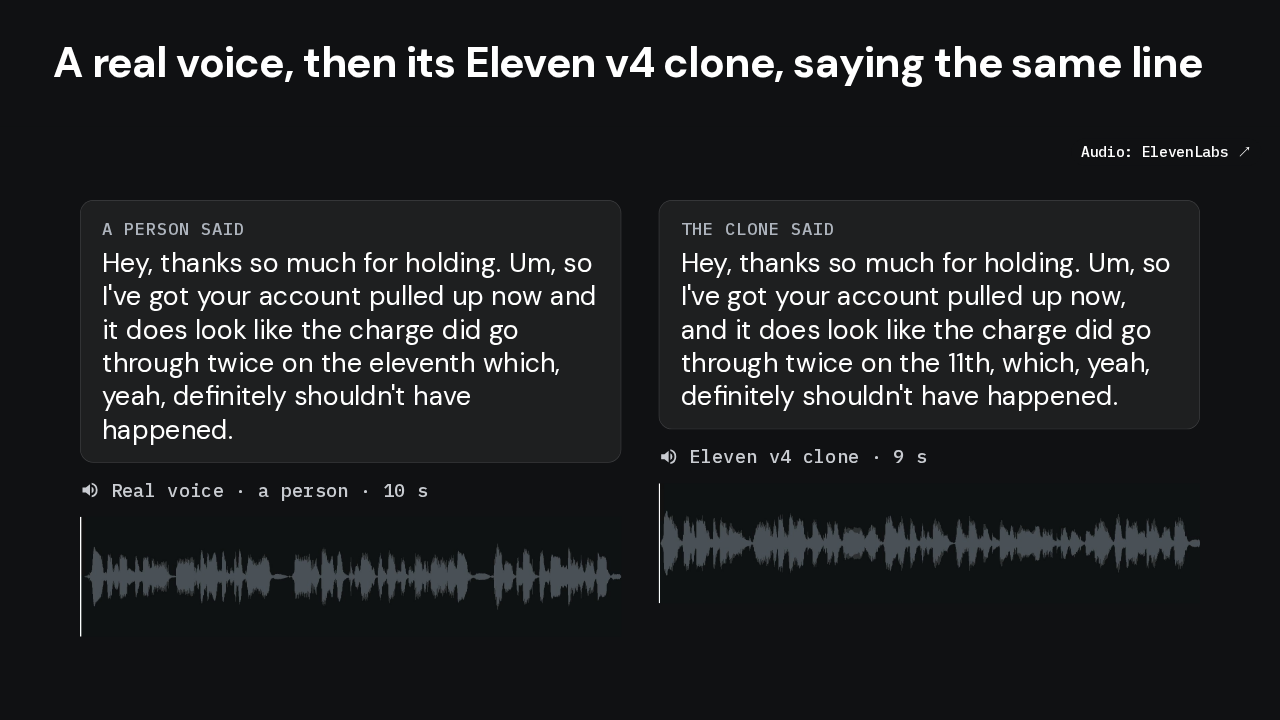
A real voice, then its Eleven v4 clone, saying the same line
Hey, thanks so much for holding. Um, so I've got your account pulled up now and it does look like the charge did go through twice on the eleventh which, yeah, definitely shouldn't have happened.
Hey, thanks so much for holding. Um, so I've got your account pulled up now, and it does look like the charge did go through twice on the 11th, which, yeah, definitely shouldn't have happened.
Cloning a voice now takes just 10 seconds of someone's audio, ElevenLabs says. First, a real person. And here's the Eleven v4 clone of that voice, saying the same thing. Both recordings are from ElevenLabs' post, side by side, the way it published them.
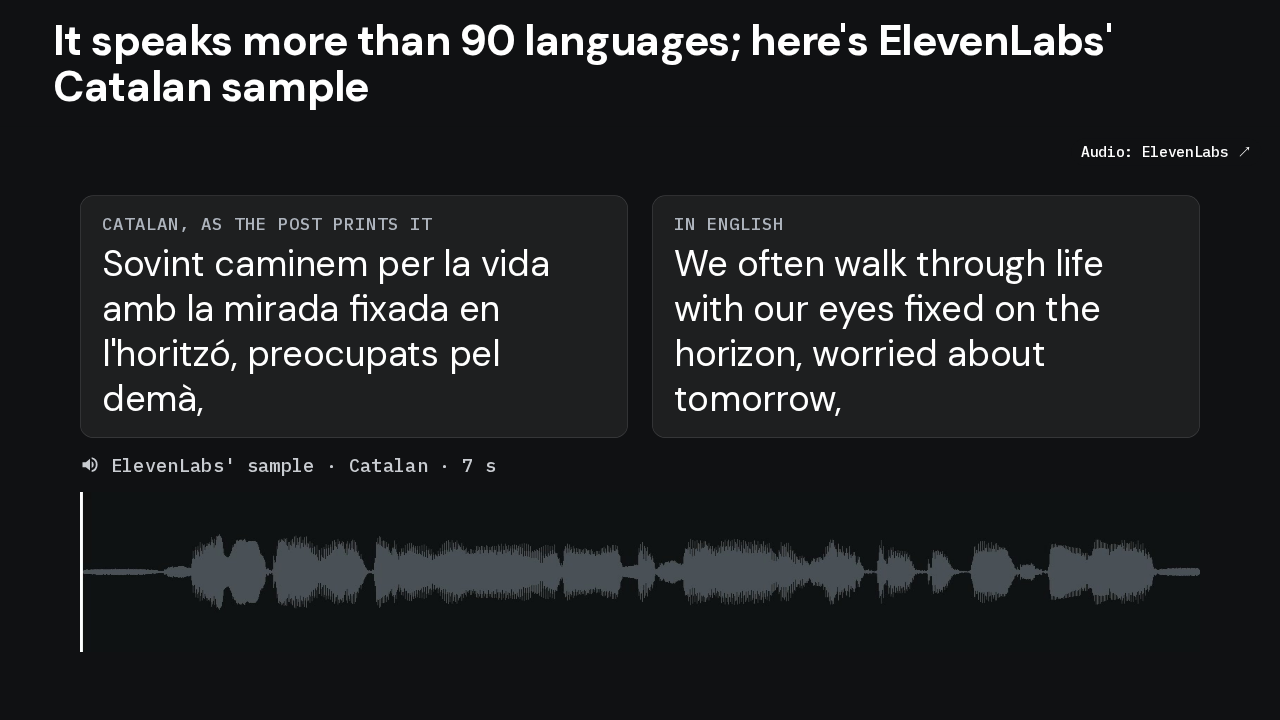
It speaks more than 90 languages; here's ElevenLabs' Catalan sample
Sovint caminem per la vida amb la mirada fixada en l'horitzó, preocupats pel demà,
We often walk through life with our eyes fixed on the horizon, worried about tomorrow,
Both models speak more than 90 languages, up from more than 70 in v3. This is ElevenLabs' Catalan sample. In English: we often walk through life with our eyes fixed on the horizon, worried about tomorrow.
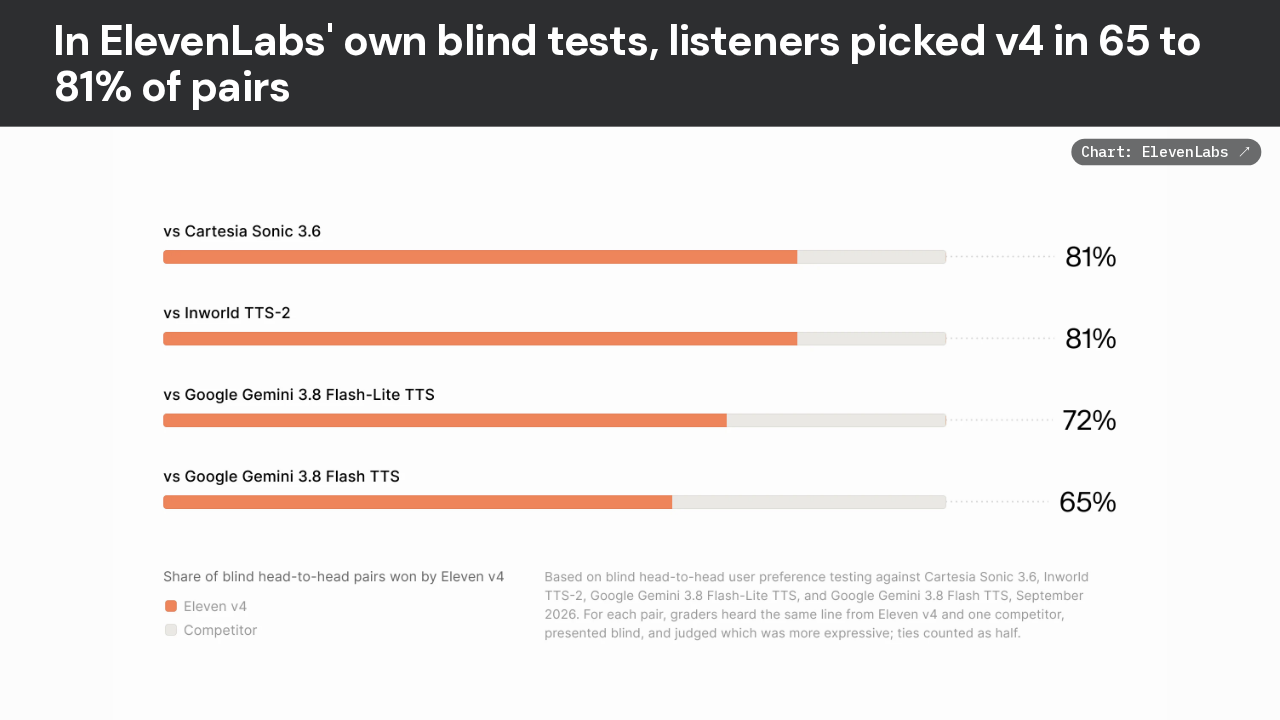
In ElevenLabs' own blind tests, listeners picked v4 in 65 to 81% of pairs

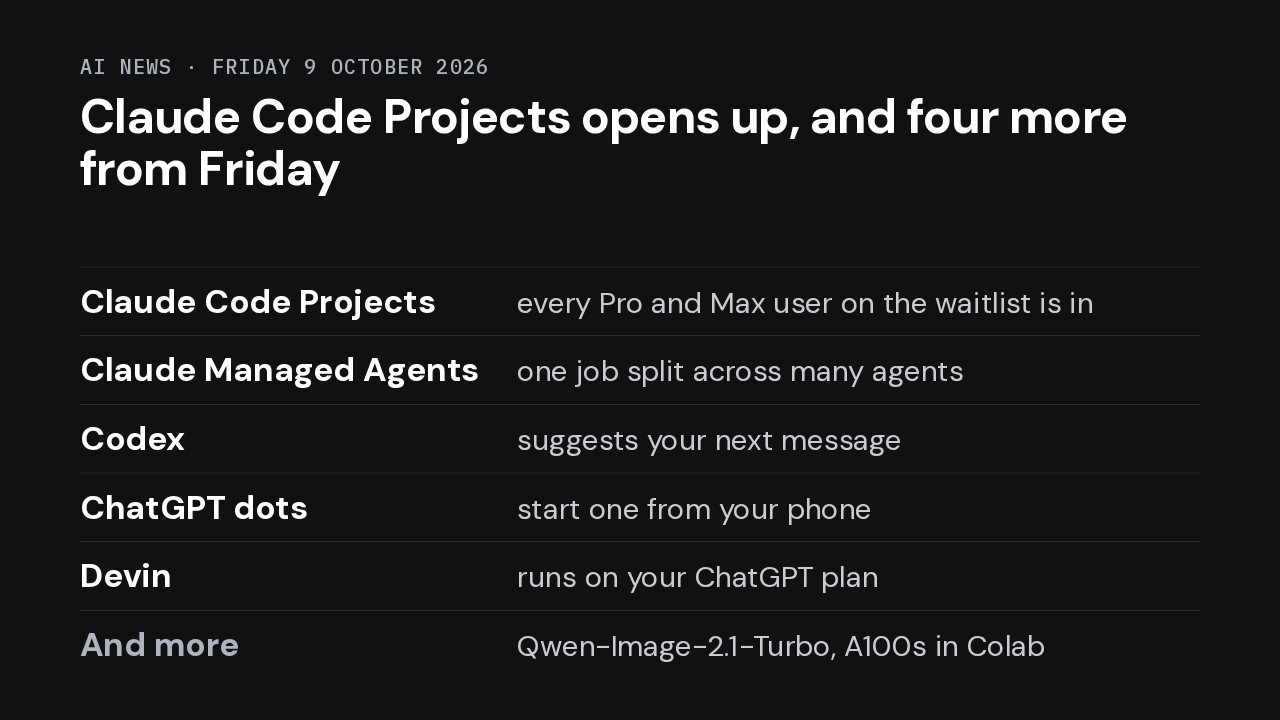
How does it compare? ElevenLabs ran blind tests: listeners heard the same line from v4 and from a rival, without knowing which was which, and picked the more expressive one. Against Cartesia's Sonic 3.6, v4 won 81% of pairs. Against Inworld's model, also 81%. Against Google's Gemini Flash-Lite voice, 72%. And against Gemini Flash, its closest rival here, 65%. These are ElevenLabs' tests, not an independent benchmark.
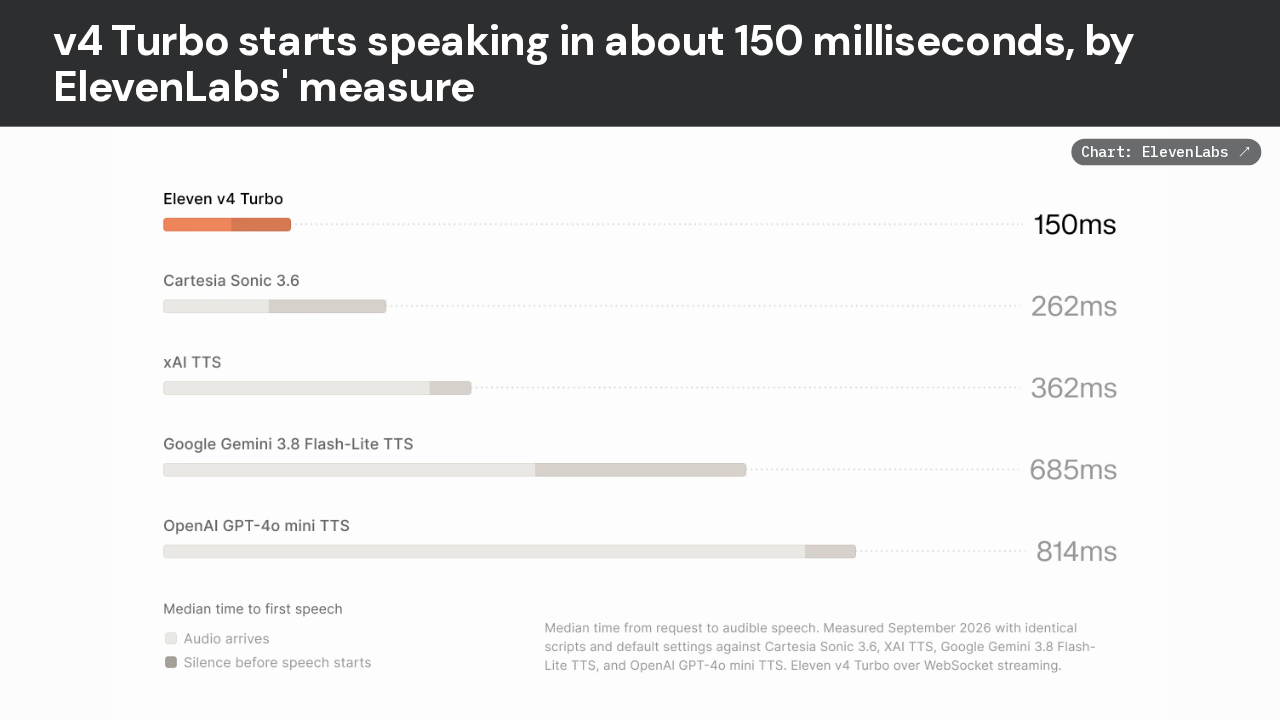
v4 Turbo starts speaking in about 150 milliseconds, by ElevenLabs' measure

The Turbo version is built for voice agents, where every pause shows. ElevenLabs measured about 150 milliseconds from request to the first audible word, against about 260 for Cartesia and 360 for xAI. OpenAI's GPT-4o mini voice took more than 800. ElevenLabs removed network time for every system before comparing.
Eleven v4 and v4 Turbo are in ElevenLabs' apps and API now
Published 28 September 2026 by ElevenLabs. Every sample is ElevenLabs' own, from its launch post, cut short; every number is from ElevenLabs' own tests.
Eleven v4 came out on September 28th, 2026. Both models are in ElevenLabs' own apps and its API now, as eleven v4 and eleven v4 turbo. Professional voice clones, missing from v3, are back. The launch post, with every sample, is linked below.