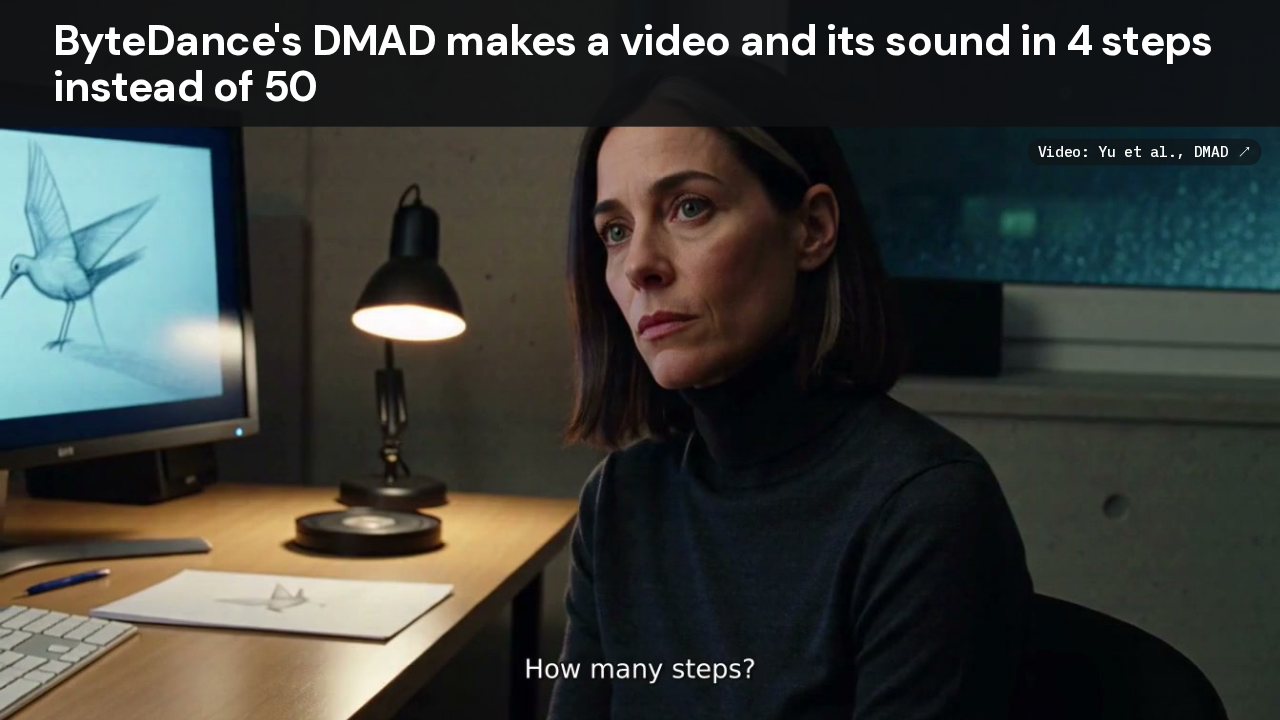
ByteDance's DMAD makes a video and its sound in 4 steps instead of 50
ByteDance and Texas A&M trained DMAD to make the same video in four steps that MiniMax's H3 model takes fifty to make. Every shot in this trailer came out of those four steps, with its dialogue and music generated alongside the picture.
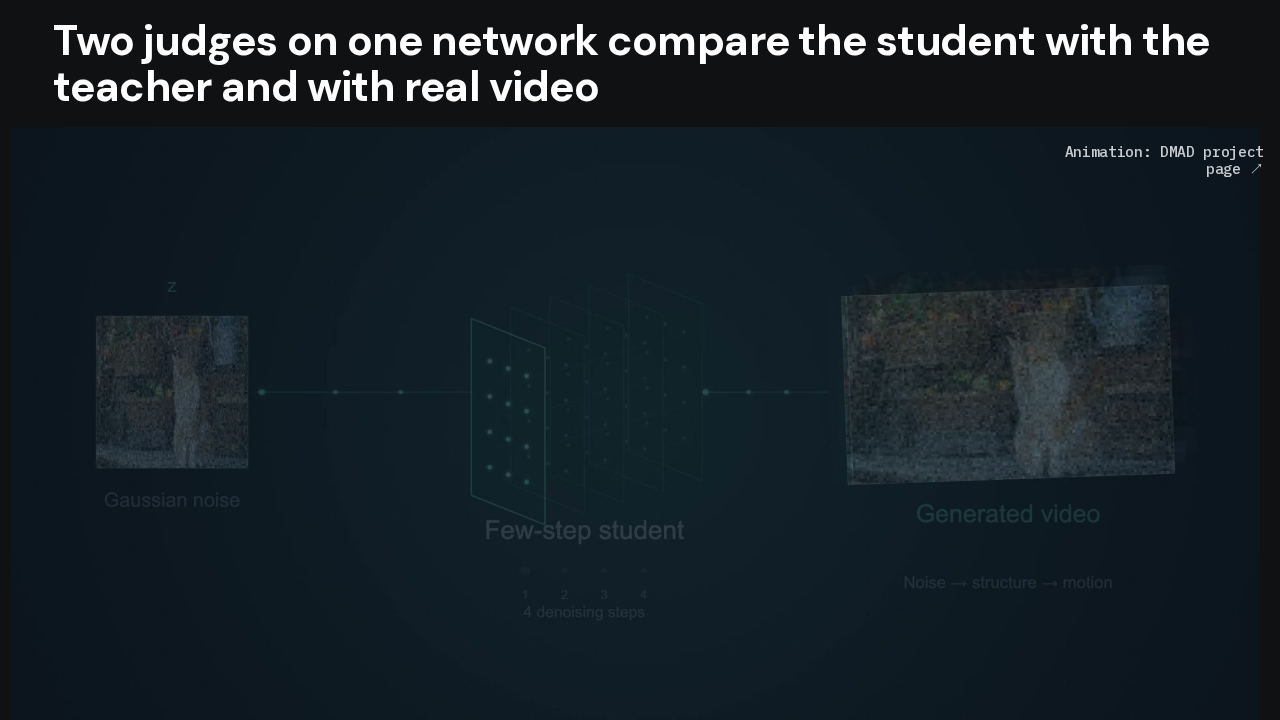
Two judges on one network compare the student with the teacher and with real video
Here's how it learns. A four-step student turns noise into a video. That video, the slow teacher's, and a real clip all get the same amount of noise. Then one network with two heads judges them. One head tells the student from the teacher, the other tells it from real video, and the student learns from both. The older method, DMD, had to train a whole second model to keep track of the student. DMAD replaces it with these two judges.
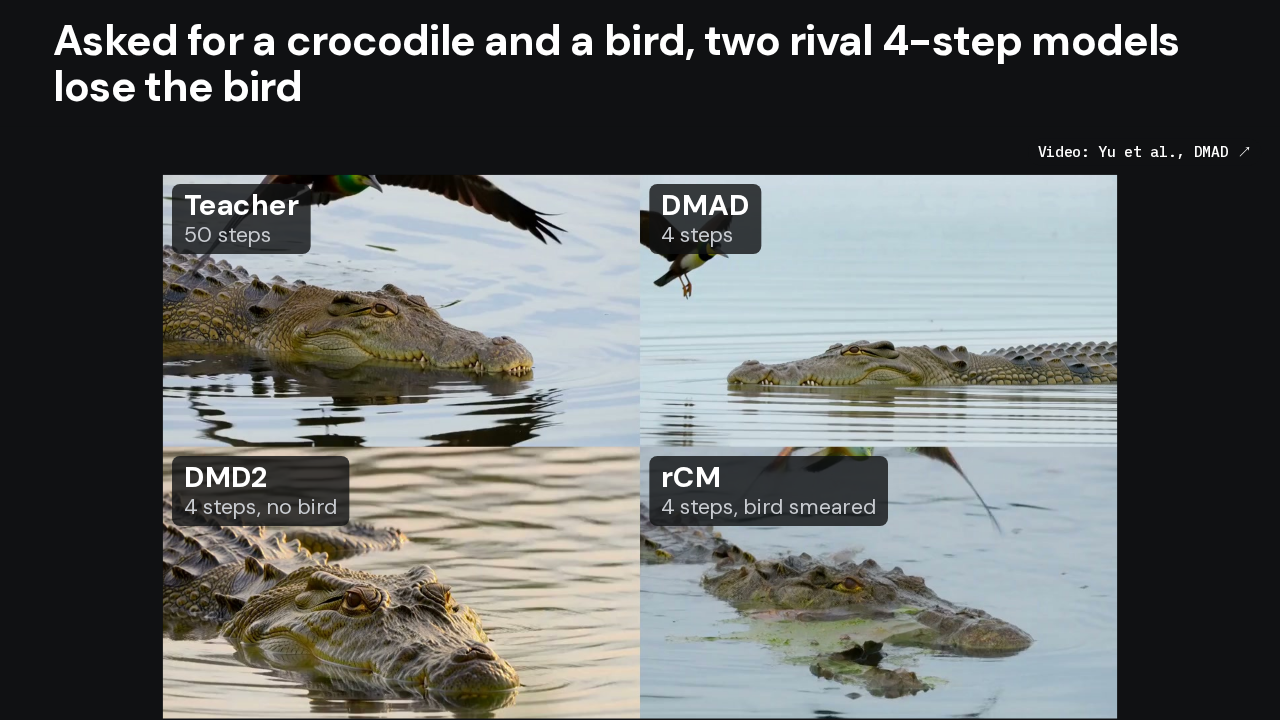
Asked for a crocodile and a bird, two rival 4-step models lose the bird
Here's one prompt four ways: a crocodile swimming while a bird flies above it. The fifty-step teacher gets both, and so does DMAD in four steps. DMD2, an earlier four-step method, drops the bird entirely. And rCM, another, smears it into a blur over green slime.
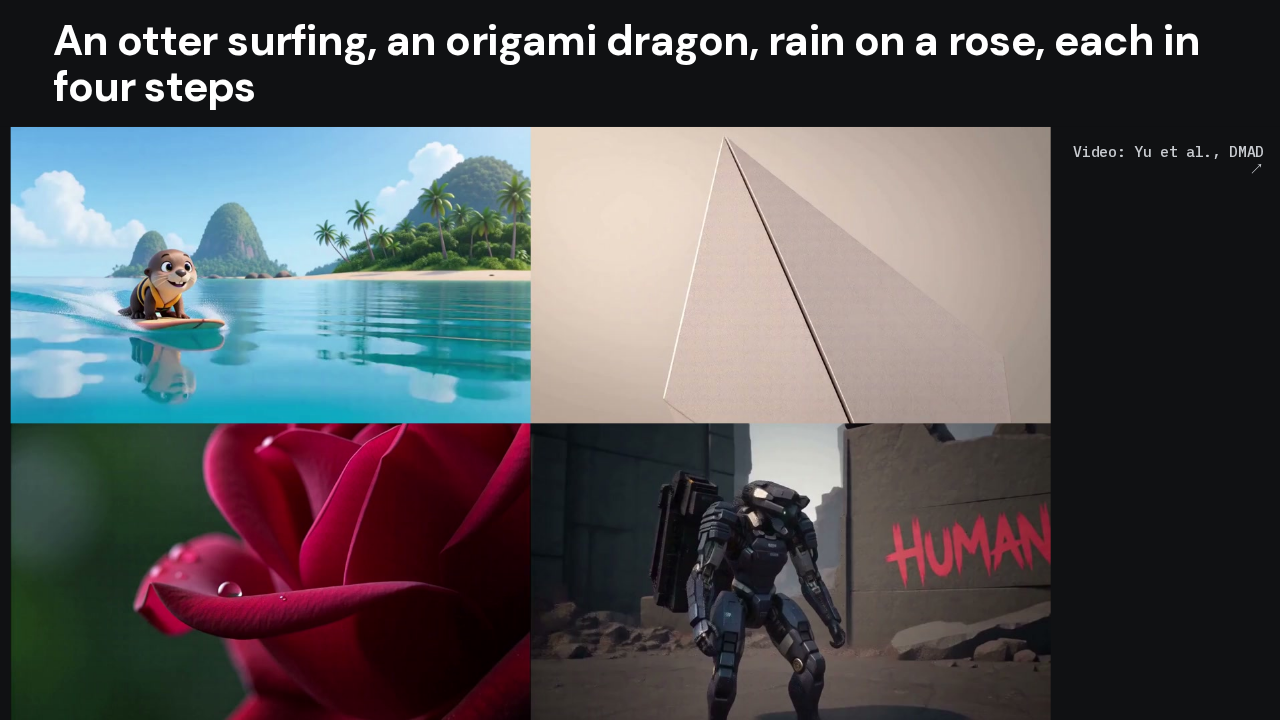
An otter surfing, an origami dragon, rain on a rose, each in four steps
A few more from the gallery: an otter surfing, an origami dragon unfolding, a raindrop on a rose, a robot in the ruins. Each one has its own sound on the page, the water, the paper, the rain.
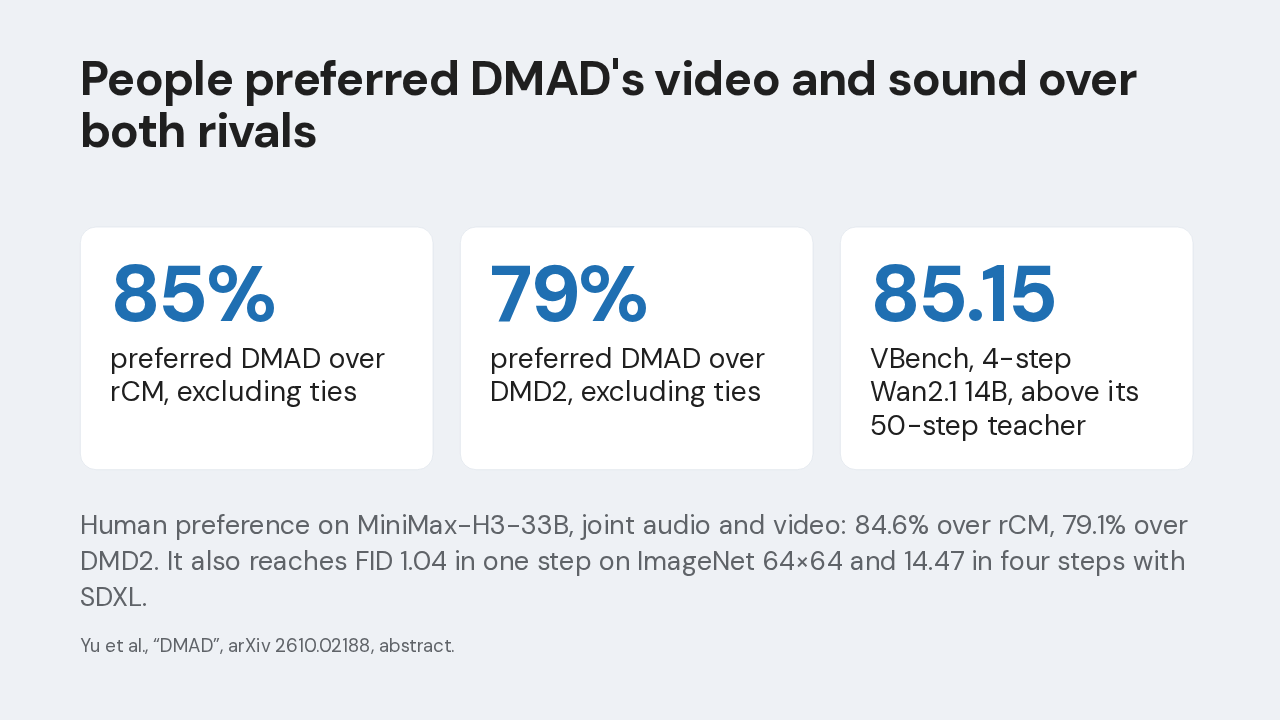
People preferred DMAD's video and sound over both rivals
Human preference on MiniMax-H3-33B, joint audio and video: 84.6% over rCM, 79.1% over DMD2. It also reaches FID 1.04 in one step on ImageNet 64×64 and 14.47 in four steps with SDXL.
Yu et al., “DMAD”, arXiv 2610.02188, abstract.
In a human study on MiniMax's H3, people preferred DMAD's clips over rCM's about eighty-five percent of the time, and over DMD2 almost eighty percent, leaving out ties. On WAN's fourteen-billion-parameter model, its four-step version even scores above the fifty-step original on VBench.
The four-step H3 model is out, and runs on a 24 GB graphics card
Posted to arXiv on 1 October 2026 by ByteDance and Texas A&M. Code under Apache 2.0, two LoRA students on Hugging Face; a low-memory mode fits a 24 GB GPU.
The paper went up on October 1st, and the four-step H3 students are already on Hugging Face, with code that has a low-memory mode for a twenty-four gigabyte graphics card. The same ByteDance team posted PDMD a few days earlier, another way to the same four steps. The paper and the project page are linked below.