A hand-built speech-to-text engine, proven correct against the reference

2 months ago

He checked his rewrite against the original, layer by layer. In the middle of the network the numbers were off by two thousand. The transcript came out word for word identical.

Ask

Ask about this presentation

Answers are generated from this presentation.

Chapters

  1. 0:00A hand-built speech-to-text engine, proven correct against the reference
  2. 0:11One engine. 16+ model families. Your machine.
  3. 0:24He was shipping models he could not vouch for.
  4. 0:40Same file. Two implementations. Eighteen checkpoints.
  5. 1:23It lands on NVIDIA's own number.
  6. 1:39When the reference writes a transcript, only an exact match passes.
  7. 1:50Slide 7
Show transcript

A hand-built speech-to-text engine, proven correct against the reference

A from-scratch speech engine, checked against the reference tensor by tensor
C/C++ ggml MIT v0.1.3

He checked his rewrite against the original, layer by layer. In the middle of the network the numbers were off by two thousand. The transcript came out word for word identical.

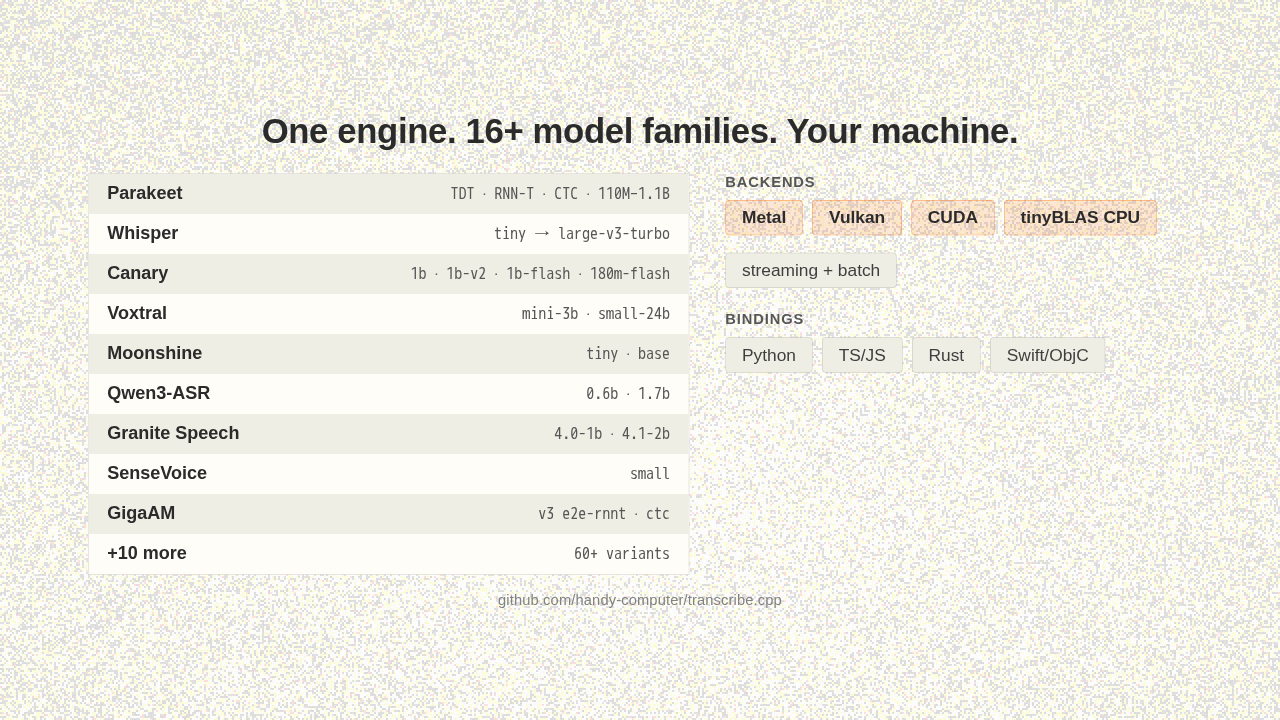
One engine. 16+ model families. Your machine.

ParakeetTDT · RNN-T · CTC · 110M–1.1B
Whispertiny → large-v3-turbo
Canary1b · 1b-v2 · 1b-flash · 180m-flash
Voxtralmini-3b · small-24b
Moonshinetiny · base
Qwen3-ASR0.6b · 1.7b
Granite Speech4.0-1b · 4.1-2b
SenseVoicesmall
GigaAMv3 e2e-rnnt · ctc
+10 more60+ variants
Backends
Metal Vulkan CUDA tinyBLAS CPU
streaming + batch
Bindings
Python TS/JS Rust Swift/ObjC
github.com/handy-computer/transcribe.cpp

The project is transcribe dot c p p. You point it at an audio file. It writes out the text, on your own machine. One engine covers sixteen plus model families and sixty odd variants. One person wrote it.

He was shipping models he could not vouch for.

The Handy product site: speak into any text field
handy.computer · github.com/cjpais/Handy · MIT · 26.9k stars

He also maintains Handy, a free dictation app with twenty-seven thousand stars. Shipping it meant handing users model files he found online. He could not tell whether they ran faithfully. So he checks every model this project publishes against its reference.

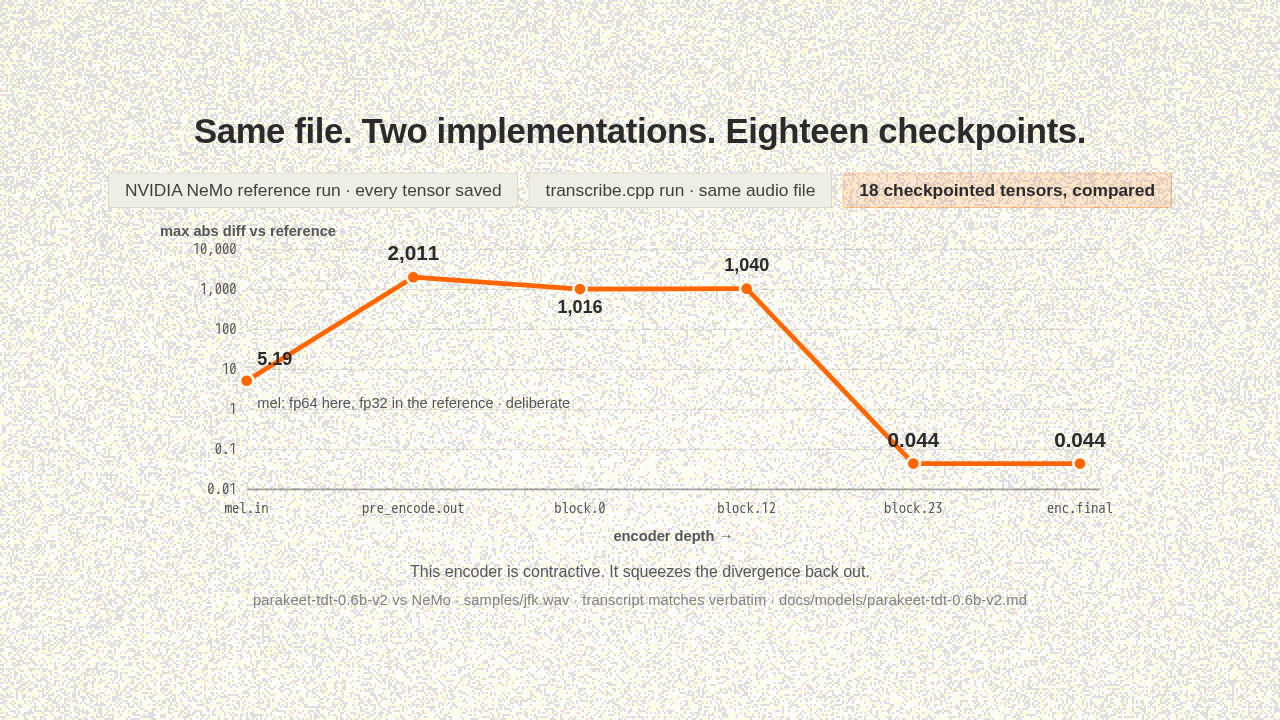
Same file. Two implementations. Eighteen checkpoints.

NVIDIA NeMo reference run · every tensor saved transcribe.cpp run · same audio file 18 checkpointed tensors, compared
10,000 1,000 100 10 1 0.1 0.01 max abs diff vs reference mel.in pre_encode.out block.0 block.12 block.23 enc.final encoder depth →
mel: fp64 here, fp32 in the reference · deliberate
5.19 2,011
1,016 1,040
0.044 0.044
This encoder is contractive. It squeezes the divergence back out.
parakeet-tdt-0.6b-v2 vs NeMo · samples/jfk.wav · transcript matches verbatim · docs/models/parakeet-tdt-0.6b-v2.md

He ran one audio file through NVIDIA's code. He saved every tensor. Then he ran the same file through his rewrite. He compared the two at eighteen checkpoints. They do not track. His code computes the spectrogram in double precision. The reference uses single. He chose double on purpose, for this model's transform. The gap enters at the mel, at about five. The pre-encoder amplifies it to two thousand and eleven. Twelve blocks deep it is still around a thousand. Then by block twenty-three it is four hundredths. It is not smaller. It is gone from the encoder's output. This encoder is contractive. It squeezes the divergence back out. And the words that come out the other end are identical.

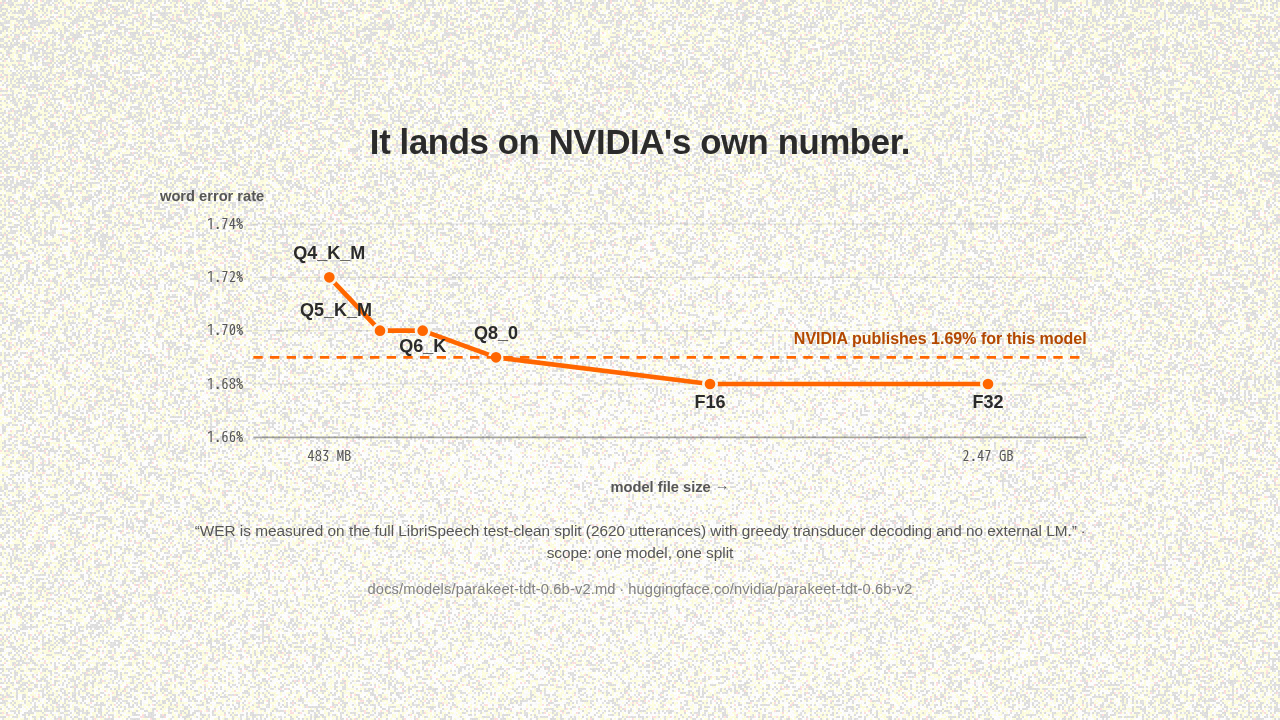
It lands on NVIDIA's own number.

1.74% 1.72% 1.70% 1.68% 1.66% word error rate 483 MB 2.47 GB model file size →
Q4_K_M Q5_K_M Q6_K Q8_0 F16 F32
NVIDIA publishes 1.69% for this model
“WER is measured on the full LibriSpeech test-clean split (2620 utterances) with greedy transducer decoding and no external LM.” · scope: one model, one split
docs/models/parakeet-tdt-0.6b-v2.md · huggingface.co/nvidia/parakeet-tdt-0.6b-v2

One matching transcript does not prove it is accurate. So he measured it on the full test-clean split. It scores one point six eight percent word error. NVIDIA publishes one point six nine for the same model on the same split. It lands on the reference within rounding.

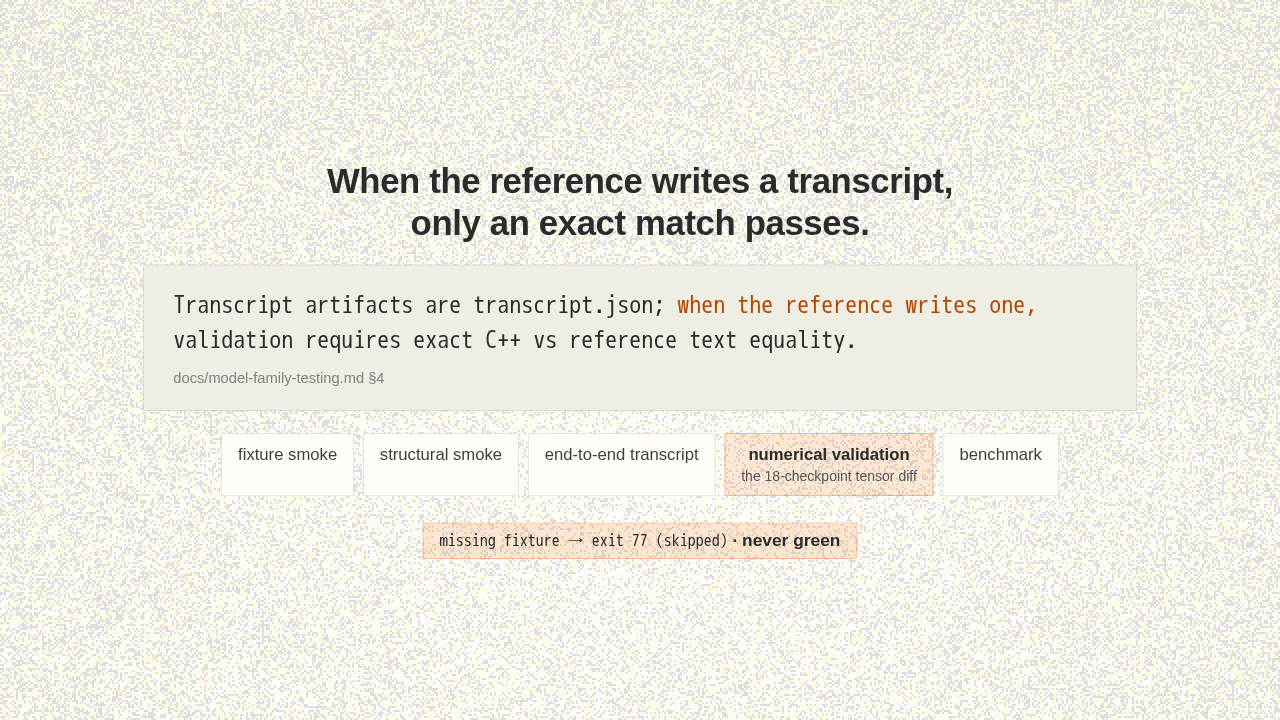
When the reference writes a transcript, only an exact match passes.

Transcript artifacts are transcript.json; when the reference writes one, validation requires exact C++ vs reference text equality.
docs/model-family-testing.md §4
fixture smoke
structural smoke
end-to-end transcript
numerical validationthe 18-checkpoint tensor diff
benchmark
missing fixture → exit 77 (skipped) · never green

When the reference writes out its own transcript, the two must match exactly, character for character. And a missing reference file returns exit code seventy-seven, never green.

Slide 7

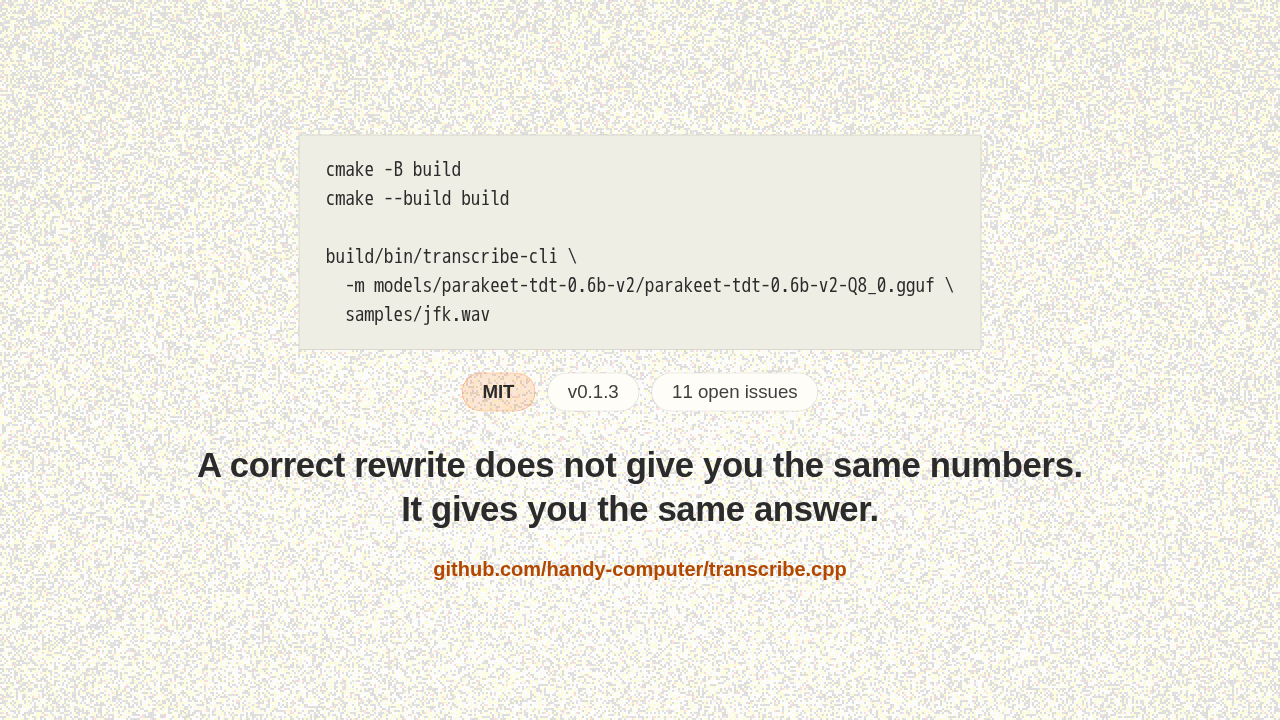
cmake -B build
cmake --build build

build/bin/transcribe-cli \
  -m models/parakeet-tdt-0.6b-v2/parakeet-tdt-0.6b-v2-Q8_0.gguf \
  samples/jfk.wav
MIT v0.1.3 11 open issues
A correct rewrite does not give you the same numbers.
It gives you the same answer.
github.com/handy-computer/transcribe.cpp

It is version zero point one point three. The author says there are rough edges he cannot find alone. The part worth keeping is not the speech engine. It is that a correct rewrite does not give you the same numbers. It gives you the same answer.