Slide 1
OpenAI shipped a new frontier family today. Sol, Terra, and Luna. The headline isn't that it's smarter. On the broad intelligence evals it lands just behind the best. What it's selling instead is price.
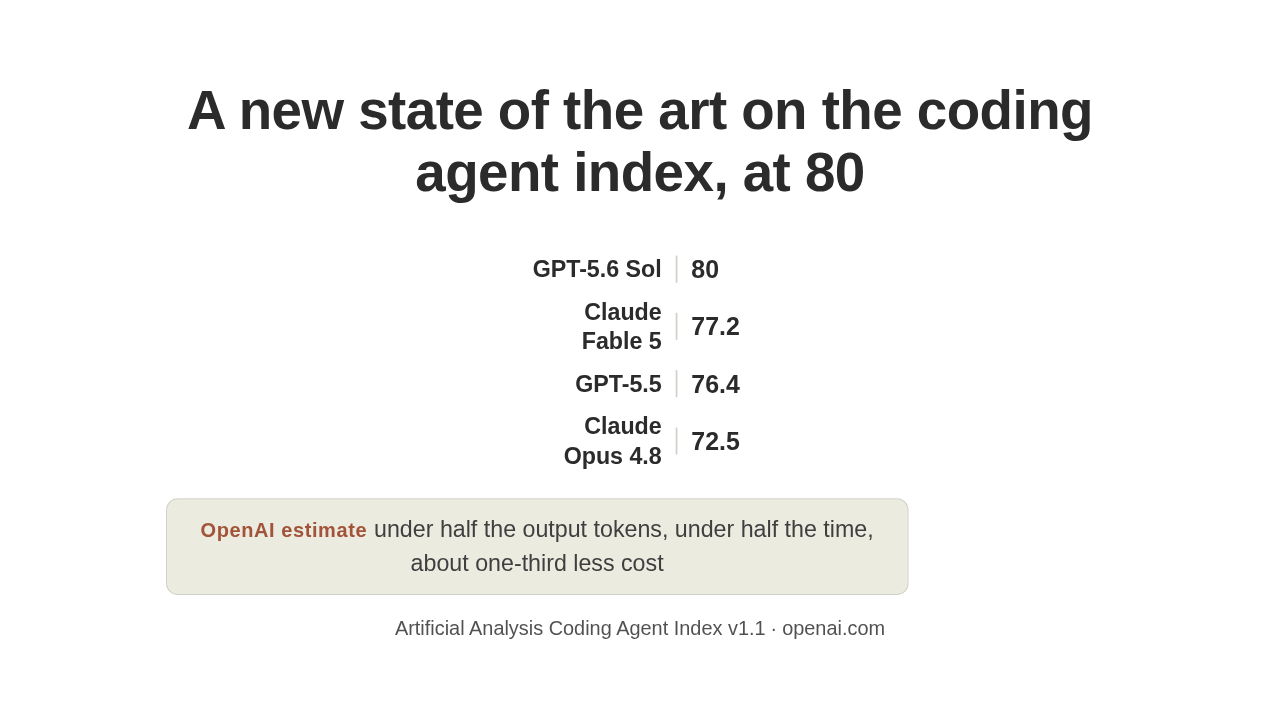
A new state of the art on the coding agent index, at 80
Three tiers. Flagship Sol, mid-range Terra, and cheap, fast Luna, live now in ChatGPT, Codex, and the API. OpenAI leads with coding. On the Coding Agent Index, Sol tops the field at eighty, just past Fable 5's seventy-seven point two.
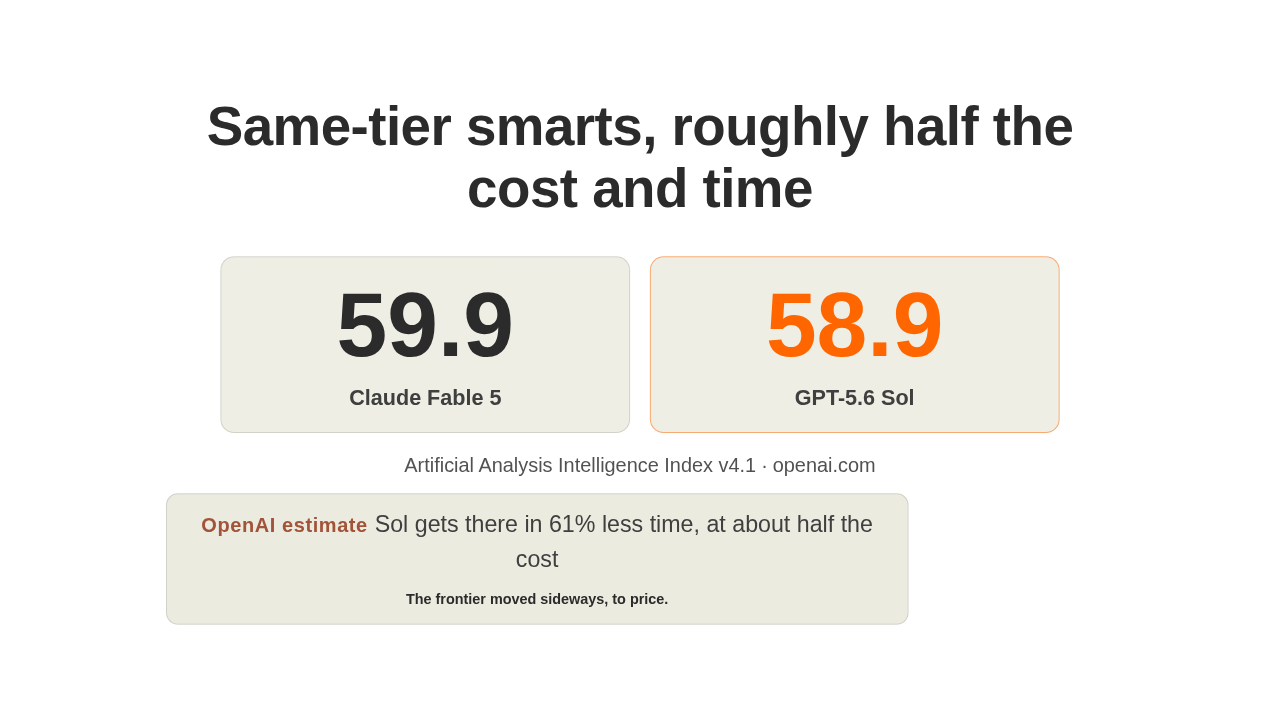
Same-tier smarts, roughly half the cost and time
On the broad Intelligence Index, Sol scores fifty-eight point nine to Fable 5's fifty-nine point nine. But OpenAI says Sol gets there in sixty-one percent less time, at about half the estimated cost. The frontier didn't move up. It moved sideways, to price.
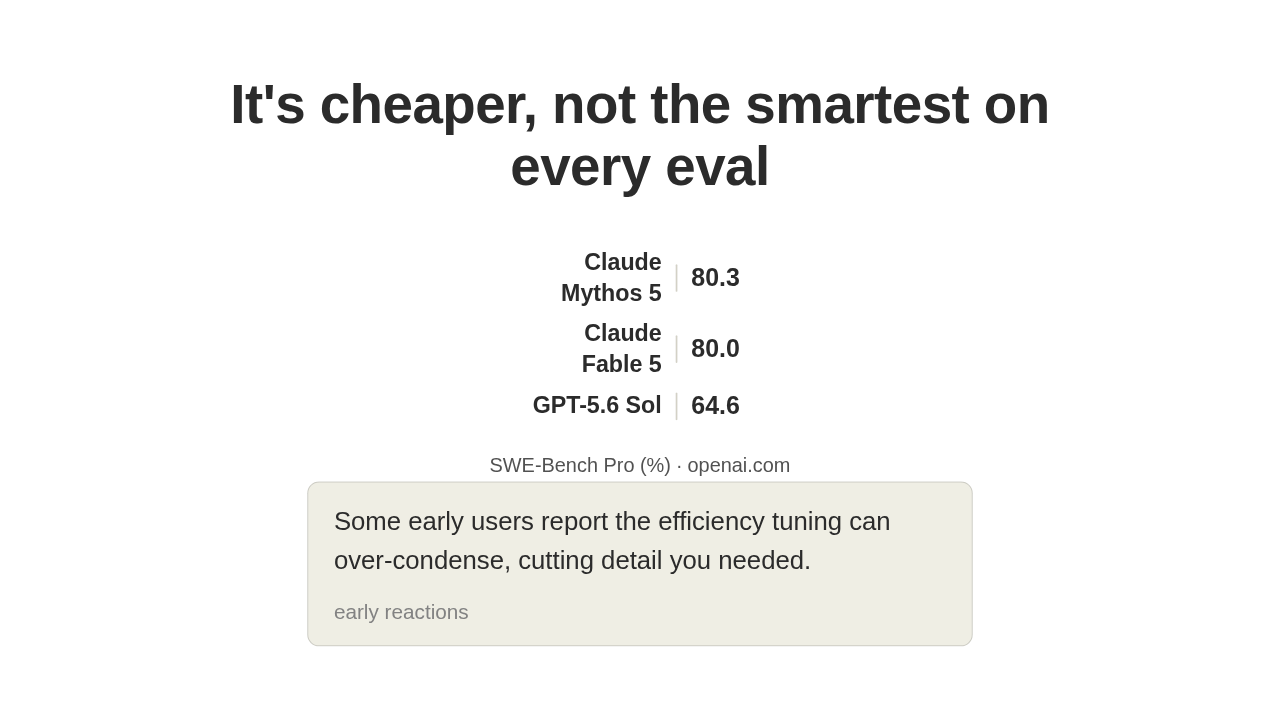
It's cheaper, not the smartest on every eval
The catch. This is efficiency, not a clean sweep. On SWE-Bench Pro, Sol scores sixty-four point six percent, behind Claude Mythos 5 at eighty point three and Fable 5 at eighty. And some early users report the efficiency tuning can over-condense, cutting detail you needed.
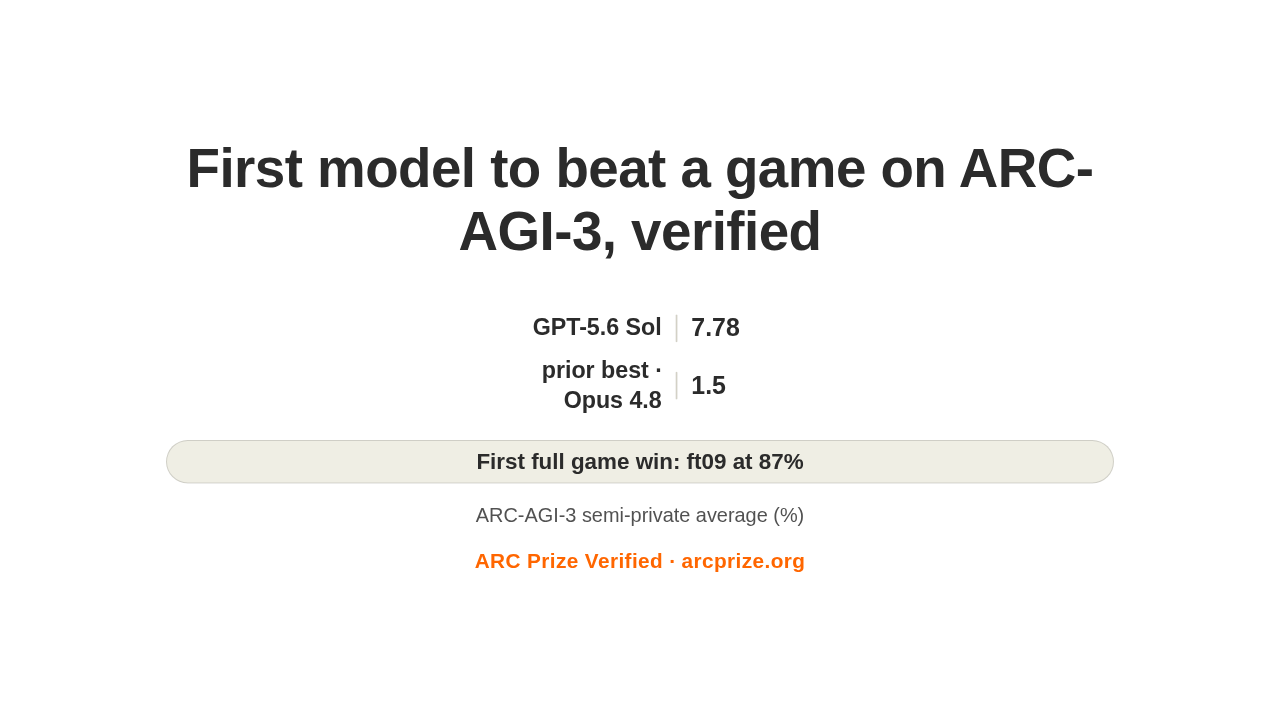
First model to beat a game on ARC-AGI-3, verified
There is one real first. Sol is the first model ever to beat a full game on ARC-AGI-3, a benchmark built to resist memorization. It won the ft09 game at eighty-seven percent, and averaged about seven point eight overall, against a prior best near one and a half. And this one isn't OpenAI's scorecard. The ARC Prize Foundation verified it independently.
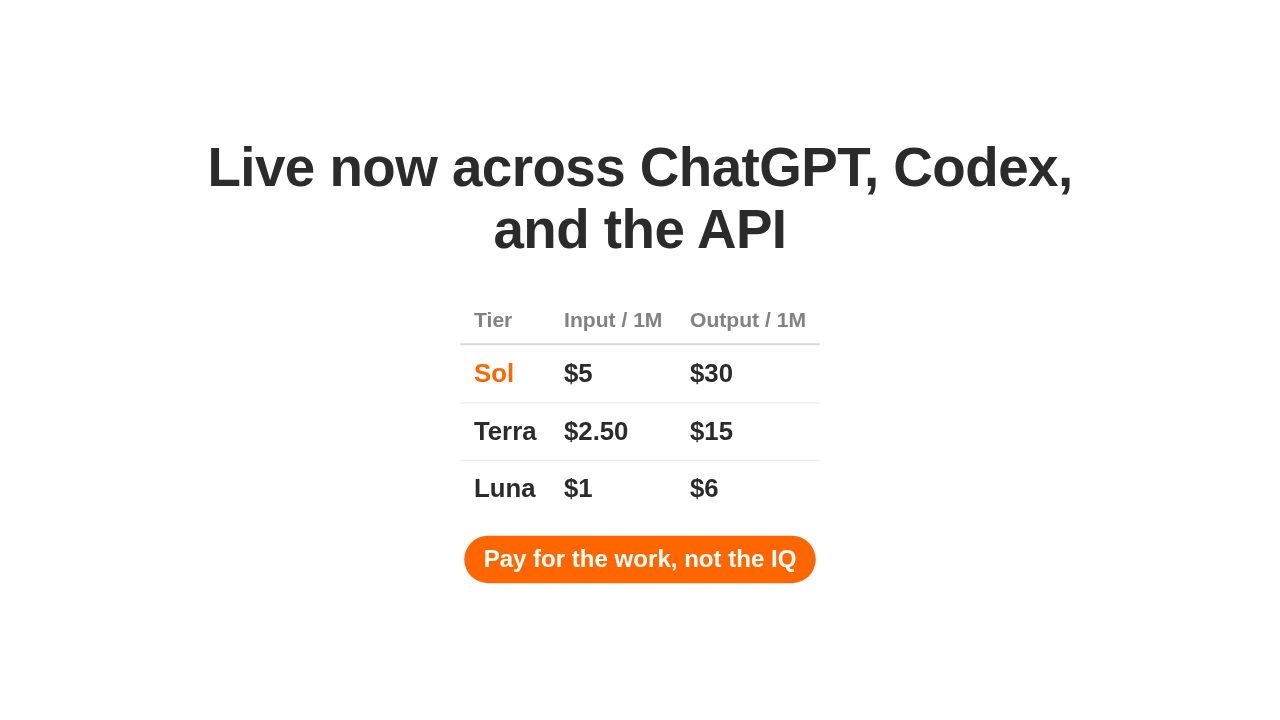
Live now across ChatGPT, Codex, and the API
| Tier | Input / 1M | Output / 1M |
|---|---|---|
| Sol | $5 | $30 |
| Terra | $2.50 | $15 |
| Luna | $1 | $6 |
The whole family is live now. Per million tokens, Sol is five dollars in, thirty out. Terra, two-fifty and fifteen. Luna, a dollar and six. So the pitch is simple. Pick the tier that fits the job. Pay for the work, not the IQ.
The race is turning from smartest to cheapest
The takeaway. The frontier race is quietly turning from smartest to cheapest per unit of work. Whether the rivals answer on price is the next question.