Slide 1

Seven hundred and forty-four billion parameters. Running on a computer with about twenty-five gigabytes of memory. That is the whole claim.
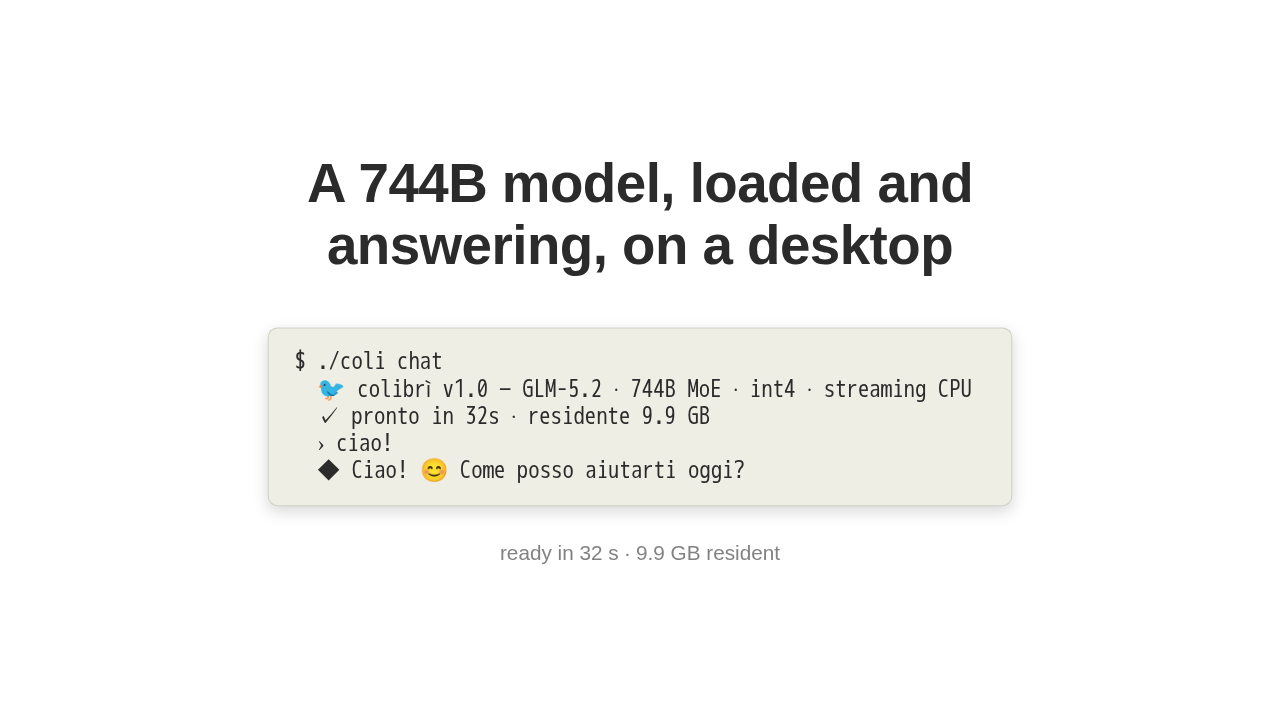
A 744B model, loaded and answering, on a desktop
$ ./coli chat
  🐦 colibrì v1.0 — GLM-5.2 · 744B MoE · int4 · streaming CPU
  ✓ pronto in 32s · residente 9.9 GB
  › ciao!
  ◆ Ciao! 😊 Come posso aiutarti oggi?
It's called colibrì. A from-scratch inference engine, written in plain C, no dependencies. It runs that same 744-billion-parameter model on an ordinary desktop. Ready in thirty-two seconds, under ten gigabytes held, and answering.
Slide 3
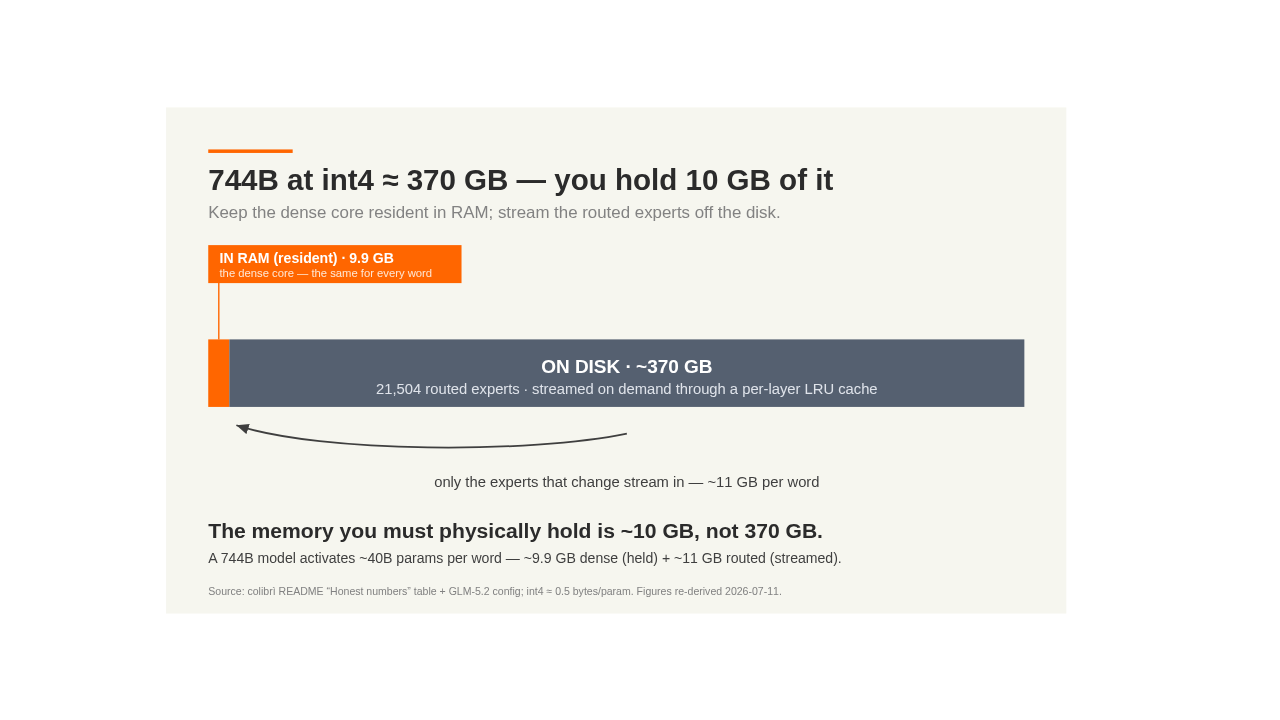
Here is the trick. At four bits, the full model is about three hundred and seventy gigabytes. But a mixture-of-experts model only uses part of itself per word. The dense core never changes, so colibrì holds it in memory, under ten gigabytes, and streams the changing experts off the disk. Ten gigabytes held. Not three hundred and seventy.
Slide 4
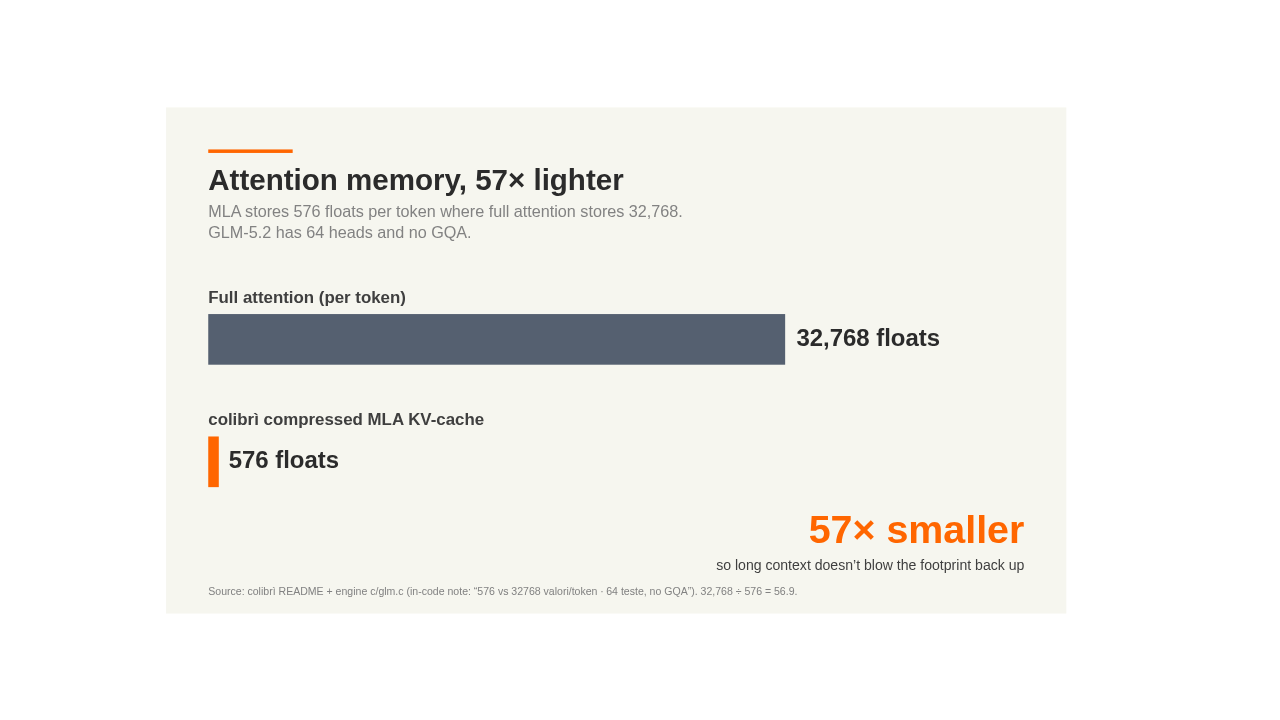
There's a second squeeze, on attention. Normally this model stores thirty-two thousand values per token. colibrì's compressed attention stores five hundred and seventy-six. About fifty-seven times smaller. Long context doesn't blow the footprint back up.
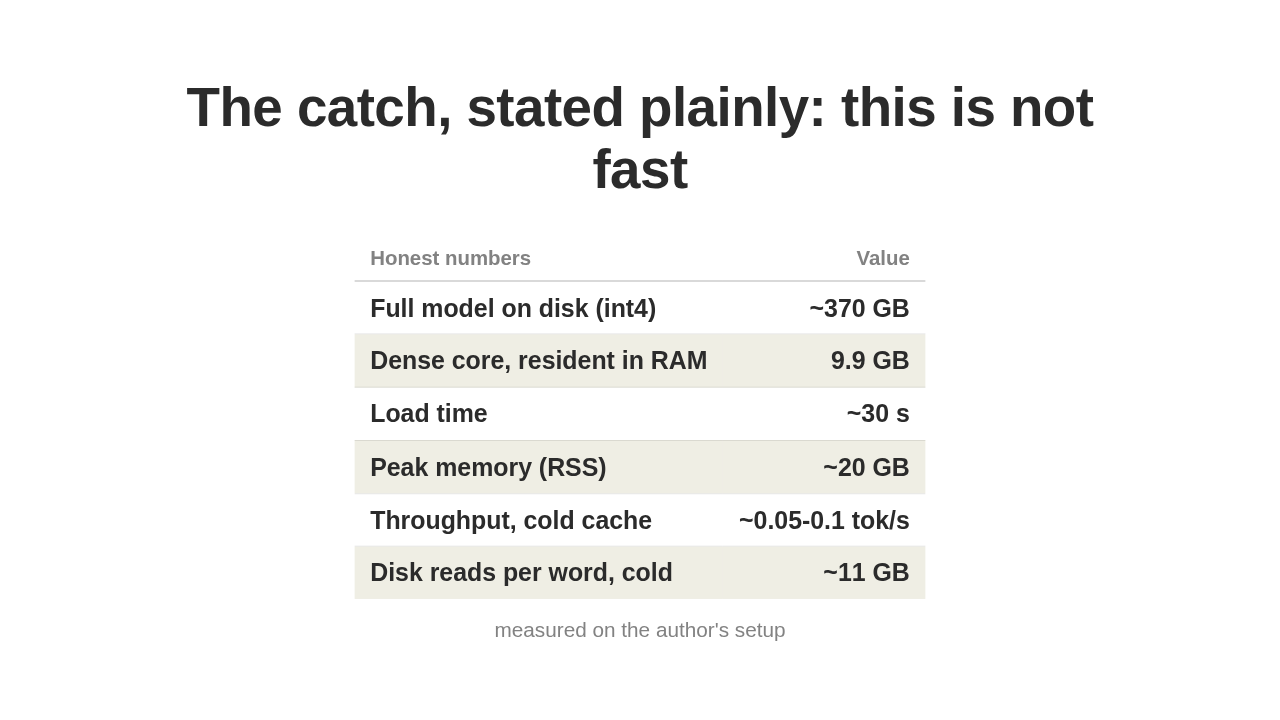
The catch, stated plainly: this is not fast
| Honest numbers | Value |
|---|---|
| Full model on disk (int4) | ~370 GB |
| Dense core, resident in RAM | 9.9 GB |
| Load time | ~30 s |
| Peak memory (RSS) | ~20 GB |
| Throughput, cold cache | ~0.05-0.1 tok/s |
| Disk reads per word, cold | ~11 GB |
Now the catch. Cold, every word means about eleven gigabytes of random disk reads. On the author's own machine, that's a fraction of a token per second until the cache warms. It is, plainly, not fast. But you can run it at all, on hardware you own, offline.
Slide 6
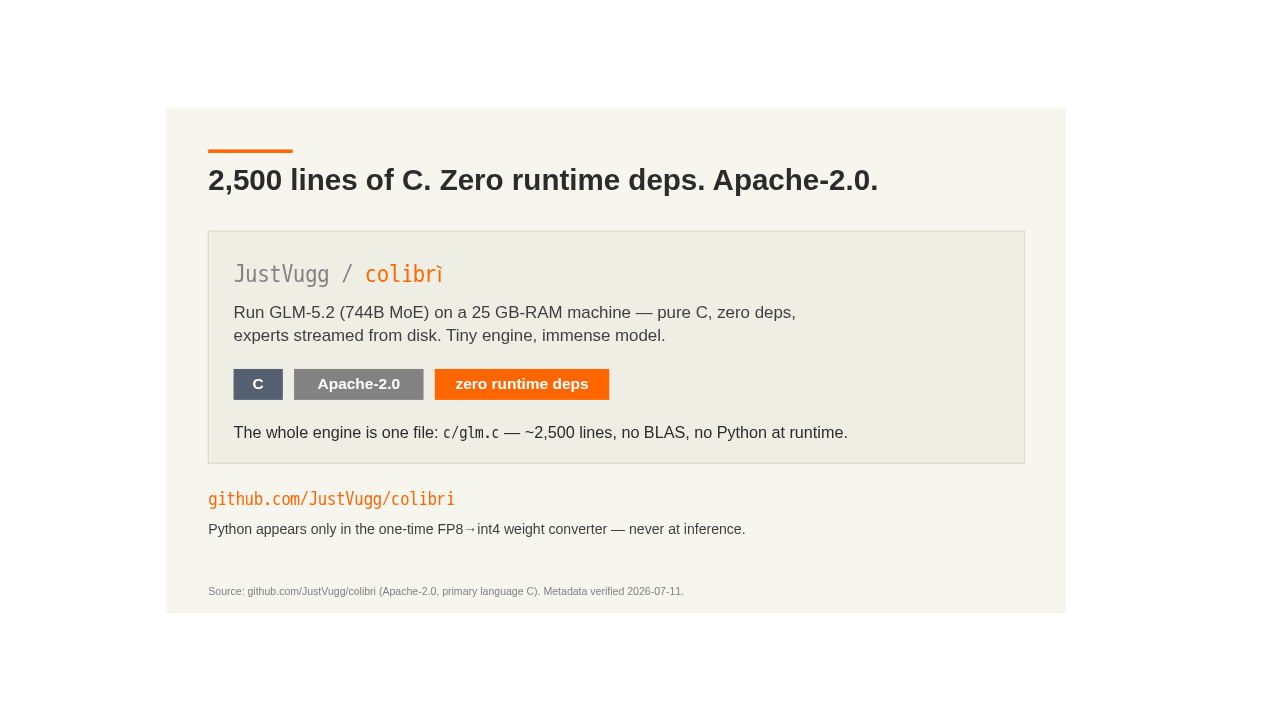
The whole engine is a single C file. Around two and a half thousand lines, no math library, no Python at inference. It's Apache-licensed, and on GitHub.
Slide 7
Slowly, but for real.
So that's the takeaway. A frontier-class model you can actually run yourself, on a machine you already own. Slowly. But for real.