llama.cpp v0.7.0 runs MoE models up to 2.2x faster when the experts don't fit in VRAM


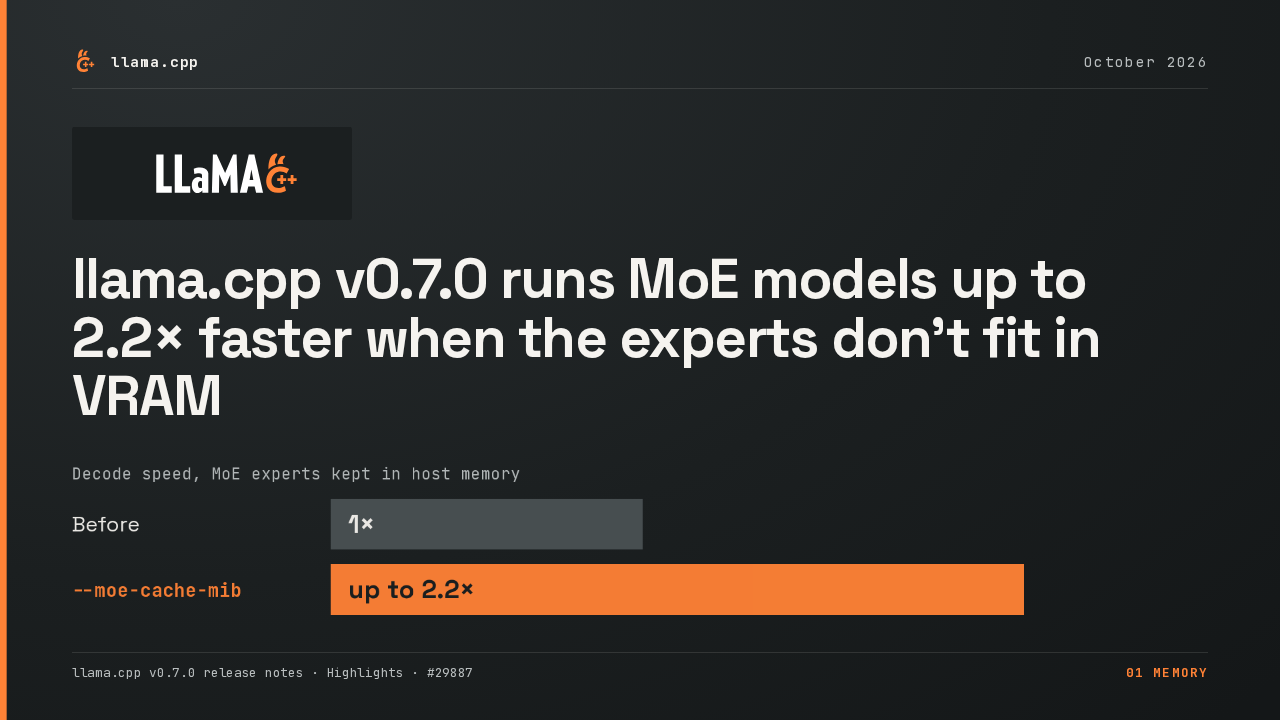
llama.cpp v0.7.0 runs MoE models up to 2.2× faster when the experts don’t fit in VRAM
--moe-cache-mibllama.cpp can now keep a mixture-of-experts model's experts in system memory and run them on the GPU from a cache. When the experts don't fit in VRAM, decoding gets up to 2.2 times faster.
The expert cache is shared across several GPUs
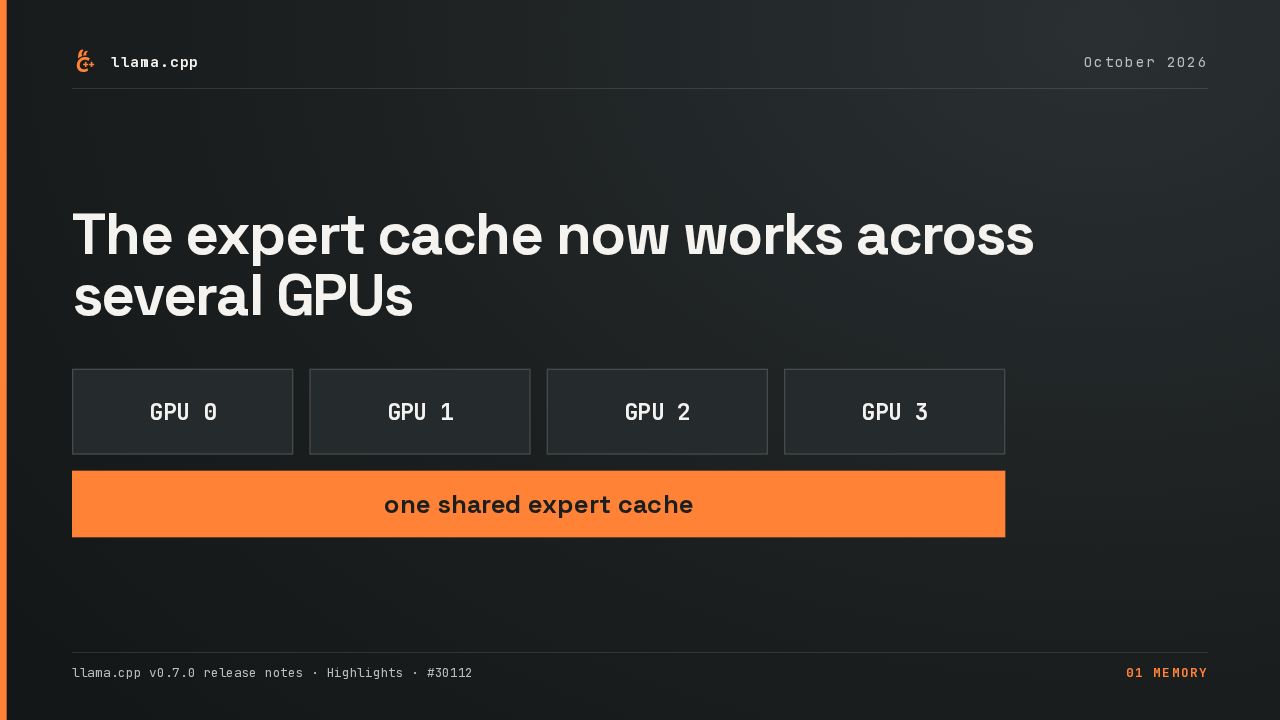
The expert cache now works across several GPUs
Rigs with more than one GPU can now use the expert cache too, shared across every card. You switch it on with the moe-cache-mib flag and give it a size in mebibytes.
Embedding models use up to 10x less VRAM
Embedding models use up to 10× less VRAM
With pooling on, llama.cpp skips the LM head and the logits buffer
Embedding models got lighter. When pooling is on, llama.cpp now skips the language model head and its logits buffer, which cuts the VRAM they need by up to ten times.
02 Speculative decoding
Speculative decoding, where a small draft model guesses tokens for the big model to check.
LiliCorr picks draft tokens with a small transformer
Candidate selection built on top of DFlash, with draft model conversion included
LiliCorr is a new speculative decoding method. A small draft transformer, built on top of DFlash, selects the candidate tokens, and llama.cpp can now convert and run those draft models.
GLM5-Next drafts its own tokens with MTP
Multi-token prediction, plus an optimized sparse attention path
GLM5-Next gets multi-token prediction, so the model drafts its own next tokens. Its sparse attention also runs on a new, optimized path.
Draft fixes, a draft batch option and multimodal MTP
Speculative decoding fixes and a VRAM saver
- Fixed draft sampling and rejection handling
--spec-draft-n-ubatchsizes the draft batch to save VRAM- MTP drafts handle multimodal input
Draft sampling and token rejection are fixed, a new option sizes the draft model's batch on its own to save VRAM, and multi-token prediction drafts now handle images and other multimodal input.
03 New models
New models you can run today.
K2 Horizon runs in dense and MoVA variants
Conversion, tokenizer, chat template, and -sm tensor to split it across GPUs
K2 Horizon now runs in both its dense and MoVA variants. Conversion, the tokenizer and the chat template are all supported, and tensor splitting spreads one model across several GPUs.
Prism Bonsai 2 27B, a ternary model
Prism Bonsai 2 27B runs in llama.cpp
Prism Bonsai 2 is a 27 billion parameter ternary model. Each of its weights is one of three values, and llama.cpp can now load and run it.
MiniCPM-V 4.7 and two new Nemotron models
- MiniCPM-V 4.7 multimodal
- Nemotron Super 3.5 VL vision and language
- Nemotron Bolt 74B A9B 9B active
MiniCPM-V 4.7 and Nemotron Super 3.5 VL both take images as input. Nemotron Bolt also lands, a 74 billion parameter model with 9 billion parameters active.
EmbeddingGemma-2 embeds text, images and audio
EmbeddingGemma-2 puts text, images and audio into one embedding model. A local search index can now hold all three kinds of content in the same vector space.
Five decision models join the server
Five decision models run on the server
- LiquidAI d1-3B · d1-omni-600M
- vLLM decision 2 · d3
- pplx-decider
LiquidAI's d1-3B and d1-omni, vLLM decision 2 and d3, and pplx-decider all run now. The server's system one endpoint serves every one of them.
04 Server and web UI
The server and its web interface.
The web UI gets a Models Manager
- One table of every served model, quants expandable
- Search, filters, sorting and favorites
- Load, unload, delete, and resumable downloads
The web interface gets a Models Manager, one searchable table of every model the server can serve. Each row loads, unloads or deletes a model, and downloads resume where they stopped.
Saved slots keep more of your session
- Rerank and embedding requests stay out of the prompt cache
- Slot files keep context checkpoints and draft state
- Off-by-two fix stops discarding restored states
Rerank and embedding requests no longer fill the prompt cache, saved slots keep their context checkpoints and draft model state, and an off-by-two bug that threw away restored sessions is fixed.
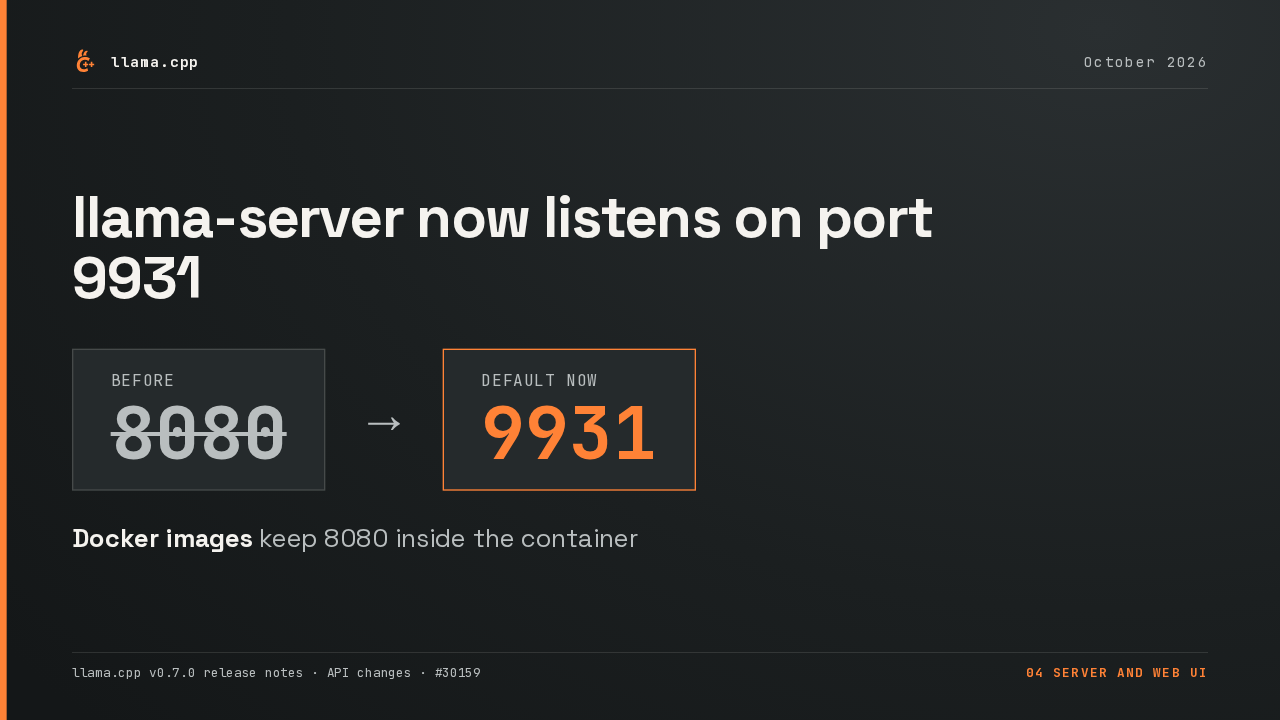
llama-server now listens on port 9931
Docker images keep 8080 inside the container
llama-server now listens on port 9931 by default. Scripts and clients pointed at 8080 need the new port. Docker images still use 8080 inside the container.
API changes are listed in the v0.7.0 release notes
Building on llama.h or the server’s chat code?
The llama.cpp v0.7.0 release notes list every API change
Developers who build on the library or the server's chat code have API changes to check. The release notes for this version, under API changes, list each one.