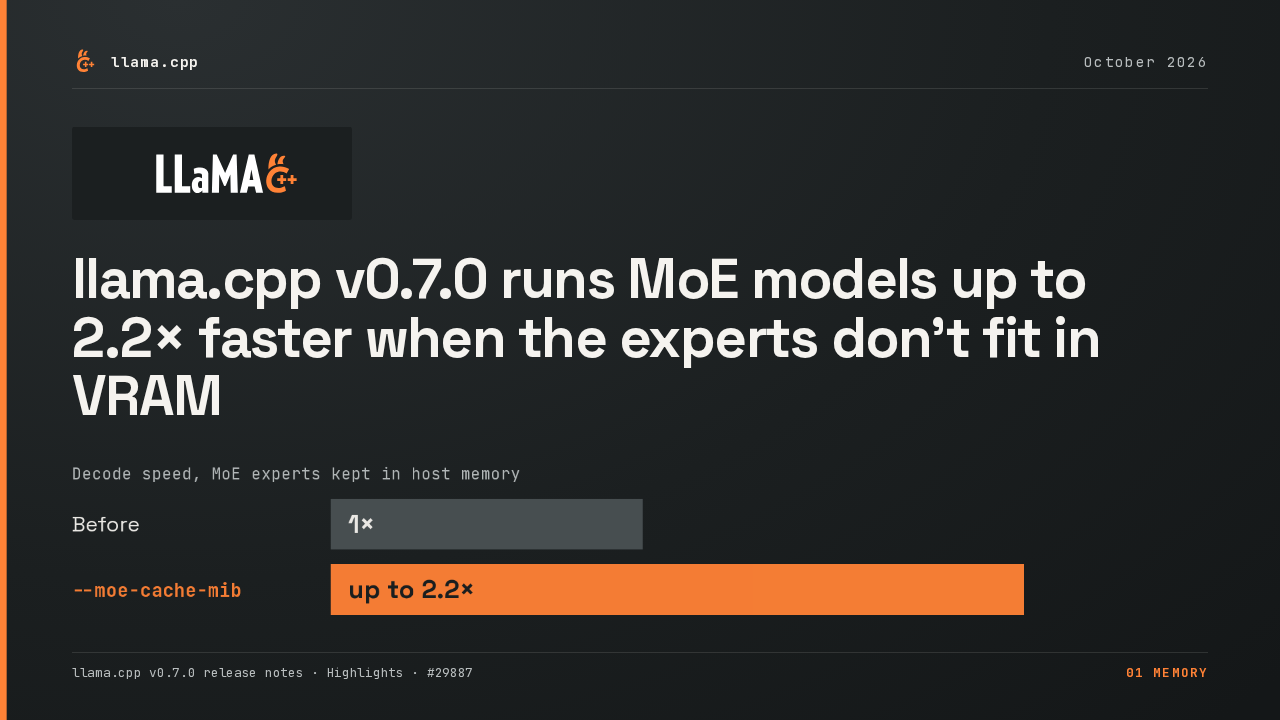
llama.cpp v0.9.0 processes prompts nearly 3× faster on Gemma 4 E2B
59 minutes ago
llama.cpp v0.9.0 processes prompts nearly three times faster on Gemma 4 E2B and on long parallel requests, adds Nemotron 3.5 Transcribe, Chatterbox TTS and Pocket TTS voices, runs Mistral Large 4, Clover and Metis-1.6, adds the FP8 E4M3 weight type, and splits one model across machines over NCCL. Release notes: https://github.com/ggml-org/llama.cpp/releases/tag/v0.9.0 Commits: https://github.com/ggml-org/llama.cpp/commits/v0.9.0
Ask about this presentation
Chapters
 0:00llama.cpp v0.9.0 processes prompts nearly 3× faster on Gemma 4 E2B
 0:1501 Faster prompts
 0:17Gemma 4's upper layers skip the prompt
 0:31Parallel requests with long prompts run about 3× faster
 0:47Faster MoE prompts on CUDA, faster MXFP4 on Metal
 1:0302 Speech in and out
 1:04Nemotron 3.5 Transcribe turns recordings into text with speaker labels
 1:21Chatterbox joins the TTS models, and voices come built in
 1:3703 New models
 1:38Mistral Large 4 and Clover run in llama.cpp
 1:53Metis-1.6 runs through its layers twice
 2:0904 New formats, more machines
 2:12FP8 E4M3 is a new weight type in llama.cpp
 2:29Two DGX Spark machines run one model almost twice as fast
 2:4505 The web UI
 2:46The web UI follows the chat and groups MCP tools
 2:59llama.cpp is a top open source project in GitHub's Octoverse for a third year
 3:11Running Gemma 4 E2B or E4B? Update today
Show transcriptHide transcript
llama.cpp v0.9.0 processes Gemma 4 E2B prompts almost three times faster. On an M4 Pro that is 4,600 tokens a second instead of 1,600, so long prompts finish in a third of the time.
Slide text
 llama.cppNovember 2026
 Gemma 4 E2B Q4_0 · M4 Pro, Metal · prompt tokens per secondBefore1,614v0.9.04,603llama.cpp v0.9.0 release notes · Core changes · #3135601 Faster prompts
First, speed.
Slide text
llama.cppNovember 202601Faster promptsllama.cpp v0.9.0 release notes01 Faster promptsThe upper layers of Gemma 4 reuse earlier layers' cache, so they now skip the prompt tokens. E4B gets about 60 percent faster, 26B gains nothing, and the speedup needs the unified KV cache.
Slide text
llama.cppNovember 2026Gemma 4’s upper layers now skip the prompt
- E4B about 1.6× faster prompts
- 26B no gain, every layer fills the cache
- Generation same speed as before
llama.cpp v0.9.0 release notes · Core changes · #3135601 Faster promptsThe unified KV cache used to slow down when several requests shared it. Now, four requests of 100,000 tokens each on Gemma 4 26B process almost three times faster on an RTX Pro 6000.
Slide text
llama.cppNovember 2026Parallel long prompts run about 3× faster on CUDA
Gemma 4 26B A4B Q8_0 · 4 requests of 100K tokens · RTX Pro 6000 · prompt tokens per secondBefore2,982v0.9.08,626llama.cpp v0.9.0 release notes · Highlights · #2951001 Faster promptsMixture-of-experts models process prompts up to 17 percent faster on CUDA. MXFP4 models generate about a sixth faster on Apple's Metal, and Intel GPUs get flash attention with a quantized KV cache.
Slide text
llama.cppNovember 2026Faster MoE on CUDA, faster MXFP4 on Metal
- CUDA MoE prompts up to 17% faster on DGX Spark
- Metal MXFP4 generation 17% faster on M3 Ultra
- SYCL flash attention with a quantized KV cache
llama.cpp v0.9.0 release notes · ggml changes · #31188 #31075 #3112501 Faster promptsNext, speech.
Slide text
llama.cppNovember 202602Speech in and outllama.cpp v0.9.0 release notes02 Speech in and outNVIDIA's Nemotron 3.5 Transcribe now runs in llama.cpp. It transcribes recordings in 40 languages and labels each speaker. Word timestamps and streaming aren't supported yet, and llama-server needs reasoning turned off.
Slide text
llama.cppNovember 2026Nemotron 3.5 Transcribe writes down who said what
40 languages Speaker labels OfflineNot yet word timestamps, streaming
llama.cpp v0.9.0 release notes · Multi-modality changes · #3147102 Speech in and outChatterbox is a new text-to-speech model in llama.cpp. Pocket TTS now speaks in ready-made voices instead of cloning one from a recording, and llama-server lists a model's voices and accepts one by name.
Slide text
llama.cppNovember 2026Chatterbox joins, and voices come built in
- Chatterbox a new text-to-speech model
- Pocket TTS ready-made voices, no cloning
- llama-server lists the voices, takes one by name
llama.cpp v0.9.0 release notes · Multi-modality changes · #30993 #3142902 Speech in and outNew models you can run.
Slide text
llama.cppNovember 202603New modelsllama.cpp v0.9.0 release notes03 New modelsMistral Large 4 now runs locally. So does Clover, a diffusion model from DiffuSpace, though only in ordinary token-by-token mode for now. Limite 1B Violetto, a small math model, arrives too.
Slide text
llama.cppNovember 2026- Mistral Large 4
- Clover-35B-A3B-Preview a diffusion model, one token at a time
- Limite 1B Violetto a small math model
llama.cpp v0.9.0 release notes · New models · #31376 #31306 #2943303 New modelsMetis-1.6 is a new family trained from scratch. Praxis and Logos mix Mamba-2 and attention layers and run the whole stack twice. Praxis generates about 250 tokens a second on an RTX 5070 Ti.
Slide text
llama.cppNovember 2026- Praxis about 2.9B parameters
- Logos about 10.2B parameters
- Mamba-2 and attention with a mixture of experts
llama.cpp v0.9.0 release notes · New models · #3113403 New modelsThen a new number format, and more machines.
Slide text
llama.cppNovember 202604New formats, more machinesllama.cpp v0.9.0 release notes04 New formats, more machinesllama.cpp now stores weights as FP8 E4M3, the 8-bit float format most used for inference. FP8 on CUDA and Vulkan, and an FP8 KV cache, are still open pull requests, so GPU users wait.
Slide text
llama.cppNovember 2026FP8 E4M3 is a new weight type
The 8-bit float format most used for inference
Still in open pull requests CUDA, Vulkan, FP8 KV cache
llama.cpp v0.9.0 release notes · Highlights · #2751204 New formats, more machinesTensor parallelism now spans several machines, over NVIDIA's NCCL library. Splitting Qwen 3.8 27B across two DGX Spark machines lifts generation from about 13 to 24 tokens a second.
Slide text
llama.cppNovember 2026Two DGX Sparks run one model almost twice as fast
Qwen3.8 27B Q4_K_M · tensor parallel over NCCL · generated tokens per secondOne node13.0Two nodes23.5llama.cpp v0.9.0 release notes · Changelog · #2896704 New formats, more machinesAnd the web interface.
Slide text
llama.cppNovember 202605The web UIllama.cpp v0.9.0 release notes05 The web UIIn the web interface, tool settings get a checkbox per MCP group. A streaming reply stays at the bottom until you scroll up, and a tool call that never returns shows as interrupted.
Slide text
llama.cppNovember 2026- MCP tools a checkbox per group
- Long chats stay at the bottom until you scroll up
- Tool calls marked interrupted when they never return
llama.cpp v0.9.0 release notes · UI changes · #31303 #31311 #3131405 The web UIGitHub's Octoverse report features llama.cpp for the third year in a row. This year it names the project one of the top open source projects on GitHub in 2026.
Slide text
llama.cppNovember 2026A top open source project, a third year running
 llama.cpp v0.9.0 release notes · Highlights · GitHub Octoverse 2026llama.cpp v0.9.0
If you run the small Gemma 4 models on a laptop, I'd update today, since the speedup costs you nothing. If you build on the library, the release notes list every API change.
Slide text
llama.cppNovember 2026
Building on the library? The llama.cpp v0.9.0 release notes list every API change
github.com/ggml-org/llama.cpp · releases/tag/v0.9.0llama.cpp v0.9.0