llama.cpp v0.8.0 adds realtime voice chat and text-to-speech to llama-server
1 hour ago
llama.cpp v0.8.0 adds real-time voice chat to llama-server on the OpenAI realtime protocol, a TTS endpoint, and LiquidAI's LFM3 audio and omni models that call tools from speech. The web UI downloads models from Hugging Face and compacts long chats; DeepSeek V4.1 Flash, Muse Spark Open and Kolibri-1 also run now. Release notes: https://github.com/ggml-org/llama.cpp/releases/tag/v0.8.0 Commits: https://github.com/ggml-org/llama.cpp/commits/v0.8.0
Ask about this presentation
Chapters
 0:00llama.cpp v0.8.0 adds realtime voice chat and text-to-speech to llama-server
 0:1401 Voice and speech
 0:16LiquidAI's LFM3 models hear, see and speak
 0:33LFM3 calls your tools from a spoken request
 0:47POST /tts turns text into a WAV file
 1:0302 The web UI
 1:05Find and download models from Hugging Face inside the web UI
 1:19/compact summarizes a long chat to free up context
 1:34Search, reasoning effort and OGG audio in the web UI
 1:4703 New models
 1:48DeepSeek V4.1 Flash and Muse Spark Open run in llama.cpp
 2:00Models that decide, embed and read documents
 2:1404 Speed, access and safety
 2:17The MoE expert cache splits into a stable half and a recent half
 2:30llama-server --connect reaches your server from outside your network
 2:46The new ggml speeds up CUDA, Intel and OpenCL backends
 3:01Deep grammars, deep JSON and the DRY sampler can't exhaust the server
 3:17For a local voice assistant, start with LFM3-Omni-2B on llama-server
Show transcriptHide transcript
llama-server can now hold a spoken conversation. A new real-time endpoint speaks the OpenAI real-time protocol, so your voice streams in and the model's answer streams back as speech and text.
Slide text
 llama.cppOctober 2026

/v1/realtimeOpenAI realtime protocol, speech in and outPOST /ttstext in, WAV outllama.cpp v0.8.0 release notes · Server changes · #31269 #2660301 Voice and speechFirst, the new voice features.
Slide text
llama.cppOctober 202601Voice and speechllama.cpp v0.8.0 release notes01 Voice and speechVoice chat runs on LiquidAI's new LFM3 models. The Audio and Omni versions listen and talk back from one model of 2 billion parameters, and Omni also watches video. Live transcription is on the Audio model only.
Slide text
llama.cppOctober 2026LiquidAI’s LFM3 models hear, see and speak
LFM3-1.7B textLFM3-VL-2B images and videoLFM3-Audio-2B speech in, speech outLFM3-Omni-2B speech, images and video in, speech outllama.cpp v0.8.0 release notes · Highlights · #31252 #31257 #3128301 Voice and speechSpoken requests can trigger tool calls. Asked out loud to set the volume to 30, the model calls the set volume function and starts its spoken answer within a third of a second.
Slide text
llama.cppOctober 2026$ python examples/realtime_client.py --tools --out answer.wav set_volume.wav [call set_volume({"volume":30}) -> {"volume": 30}] The volume has been set to thirty. first output 277 ms after the end of the input
llama.cpp v0.8.0 release notes · Changelog · #3128701 Voice and speechPlain text-to-speech gets its own TTS endpoint. Post text and an optional speaker recording, and get a WAV file back. An OpenAI-compatible version is still to come. Soprano is a new speech model too.
Slide text
llama.cppOctober 2026The new TTS endpoint turns text into a WAV file
$ curl -X POST http://127.0.0.1:9931/tts \
    -F "input=Hello, this is a test." \
    -F "speaker_ref=@speaker-reference.wav" \
    -o output.wav
Soprano TTS joins the supported speech models
llama.cpp v0.8.0 release notes · Server changes · #26603 #2860701 Voice and speechNext, the web interface.
Slide text
llama.cppOctober 202602The web UIllama.cpp v0.8.0 release notes02 The web UIThe web interface can now browse Hugging Face and download models without a terminal. Each quantization notes whether it fits in your memory, and the matching draft model for speculative decoding downloads with it.
Slide text
llama.cppOctober 2026Download models from Hugging Face inside the web UI
- Search GGUF models and filter by size
- Each quant notes whether it fits in memory
- The matching draft model downloads alongside
llama.cpp v0.8.0 release notes · UI changes · #2958402 The web UILong chats can now be compacted. Type /compact and the model summarizes the conversation so far, and later turns continue from that summary. Automatic compaction near the context limit is still to come.
Slide text
llama.cppOctober 2026/compactfrees up context in a long chatLater turns continue from the summary
 llama.cpp v0.8.0 release notes · UI changes · #2740102 The web UI
A new search dialog finds any conversation or message. The reasoning menu now lists the effort levels the model's chat template defines, and OGG voice notes attach as audio.
Slide text
llama.cppOctober 2026Search, reasoning effort and OGG audio
- Search across conversations and messages
- Reasoning menu built from the model’s own effort levels
- OGG audio attachments, converted to WAV
llama.cpp v0.8.0 release notes · UI changes · #31173 #31273 #3123702 The web UINew models you can run.
Slide text
llama.cppOctober 202603New modelsllama.cpp v0.8.0 release notes03 New modelsDeepSeek V4.1 Flash now runs in llama.cpp. So does Muse Spark Open, which takes text, images and audio, and so does Kolibri-1 from Aleph Alpha.
Slide text
llama.cppOctober 2026- DeepSeek V4.1 Flash
- Muse Spark Open text, vision and audio
- Kolibri-1 from Aleph Alpha
llama.cpp v0.8.0 release notes · New models · #31086 #30616 #3067303 New modelsLiquidAI's d1 decision models and Granite Switch Decision arrive too. Nemotron 3.5 Embed builds search embeddings, and MiniCPM-OCR reads the text in document images.
Slide text
llama.cppOctober 2026- Decision LiquidAI d1-2B and d1-omni-2B, Granite Switch Decision
- Embeddings Nemotron-3.5-Embed
- OCR MiniCPM-OCR 1.0
llama.cpp v0.8.0 release notes · New models · #31275 #30676 #30877 #3097903 New modelsThen speed, remote access and safety.
Slide text
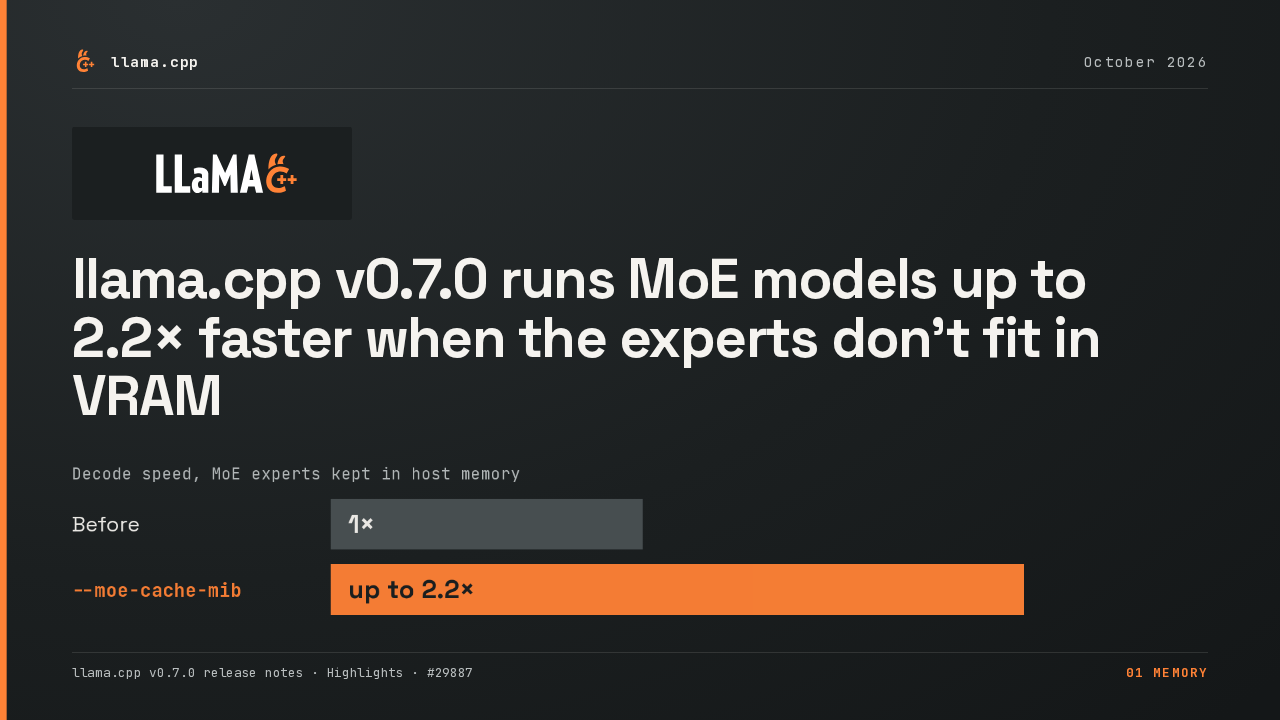
llama.cppOctober 202604Speed, access and safetyllama.cpp v0.8.0 release notes04 Speed, access and safetyMixture-of-experts models that keep experts in system memory get a smarter expert cache. It splits in two, and regular experts sit in a stable half where a burst of rare ones can't push them out.
Slide text
llama.cppOctober 2026The MoE expert cache splits in two
Stable half experts used again and againRecent half experts seen once so farllama.cpp v0.8.0 release notes · Core changes · #3063704 Speed, access and safetyA new connect flag reaches llama-server from outside your home network. The link is peer to peer over WebRTC, encrypted end to end, and needs a separate program, llama-connect, which has no Intel Mac build yet.
Slide text
llama.cppOctober 2026--connectreaches your server from outside your network- Peer to peer over WebRTC, without a central server
- Encrypted end to end
- llama-connect a separate binary, no Intel Mac build yet
llama.cpp v0.8.0 release notes · Server changes · #2827704 Speed, access and safetyUnderneath, ggml moved to a new version with faster backends. CUDA launches its graphs in chunks, Intel GPUs replay recorded graphs, and OpenCL devices can now run Q2_K and Q3_K quantized weights.
Slide text
llama.cppOctober 2026The new ggml speeds up CUDA, Intel and OpenCL
- CUDA chunked graph launches, fused MoE top-k
- SYCL graph record and replay on Intel GPUs
- OpenCL Q2_K and Q3_K weights
llama.cpp v0.8.0 release notes · ggml changes04 Speed, access and safetySeveral fixes stop one request from taking a server down. Grammars get a recursion limit, JSON nested past 128 levels is refused, and the DRY sampler caps its sequence breakers so it can't exhaust memory.
Slide text
llama.cppOctober 2026Runaway grammars and deep JSON get stopped early
- Grammars recursion depth capped against stack overflows
- JSON nested past 128 levels is refused
- DRY sampler sequence breakers capped at 64
llama.cpp v0.8.0 release notes · Core changes · #29755 #30242 #3103504 Speed, access and safetyFor a voice assistant on my own machine, I'd start with LFM3 Omni on llama-server: one small model hears you, calls your tools and talks back. If you build on the library, the release notes list every API change.
Slide text
llama.cppOctober 2026
Building on the library? The llama.cpp v0.8.0 release notes list every API change
github.com/ggml-org/llama.cpp · releases/tag/v0.8.0llama.cpp v0.8.0