Transformers adds Reflection AI’s Beam and loads models on PyTorch 2.7 again
3 weeks ago
Transformers v5.20.1 and v5.20.2: Reflection AI's Beam model, from_pretrained working again on PyTorch 2.7, generate fixes for vision-language and encoder-decoder models, and real expert gradients in bfloat16 MoE training. https://github.com/huggingface/transformers/releases/tag/v5.20.1 https://github.com/huggingface/transformers/releases/tag/v5.20.2 https://huggingface.co/docs/transformers/main/en/model_doc/beam
Ask about this presentation
Chapters
Show transcriptHide transcript
Transformers now runs Beam, the first open-weight model from Reflection AI. It's a mixture of experts with 501 billion parameters, 23 billion of them active per token, built for coding, reasoning and agent work.
Slide text
Transformers01 02 03 New modelhuggingface/transformers · release v5.20.1 · PR #49664Transformers now runs Beam, Reflection AI’s open-weight model
501B parameters 23B active per token Coding and agents
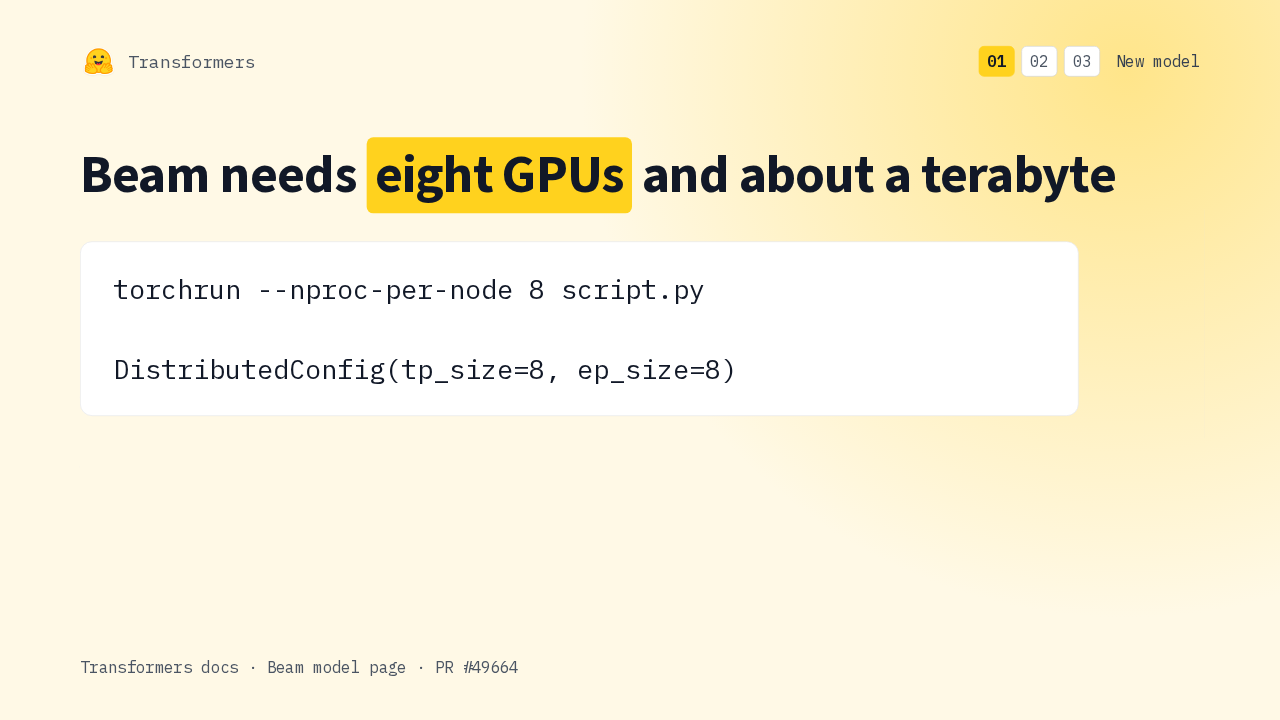
The BF16 checkpoint is about a terabyte. The examples shard it across eight GPUs with expert parallelism, which puts whole experts on each device. That beats device_map auto, which can run out of memory while loading.
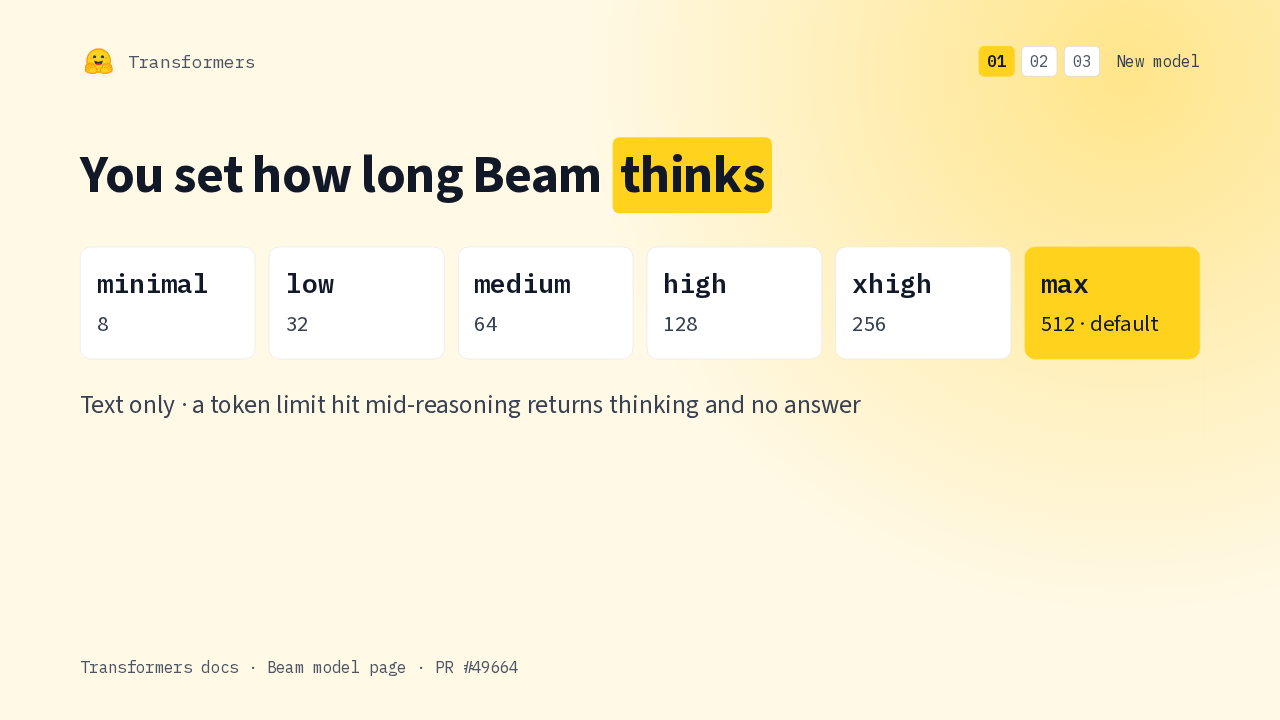
Beam reasons before every answer, and a reasoning effort setting in the chat template controls how much. It runs from minimal up to max, the default. If the token limit runs out mid-reasoning, you get thinking and no answer.
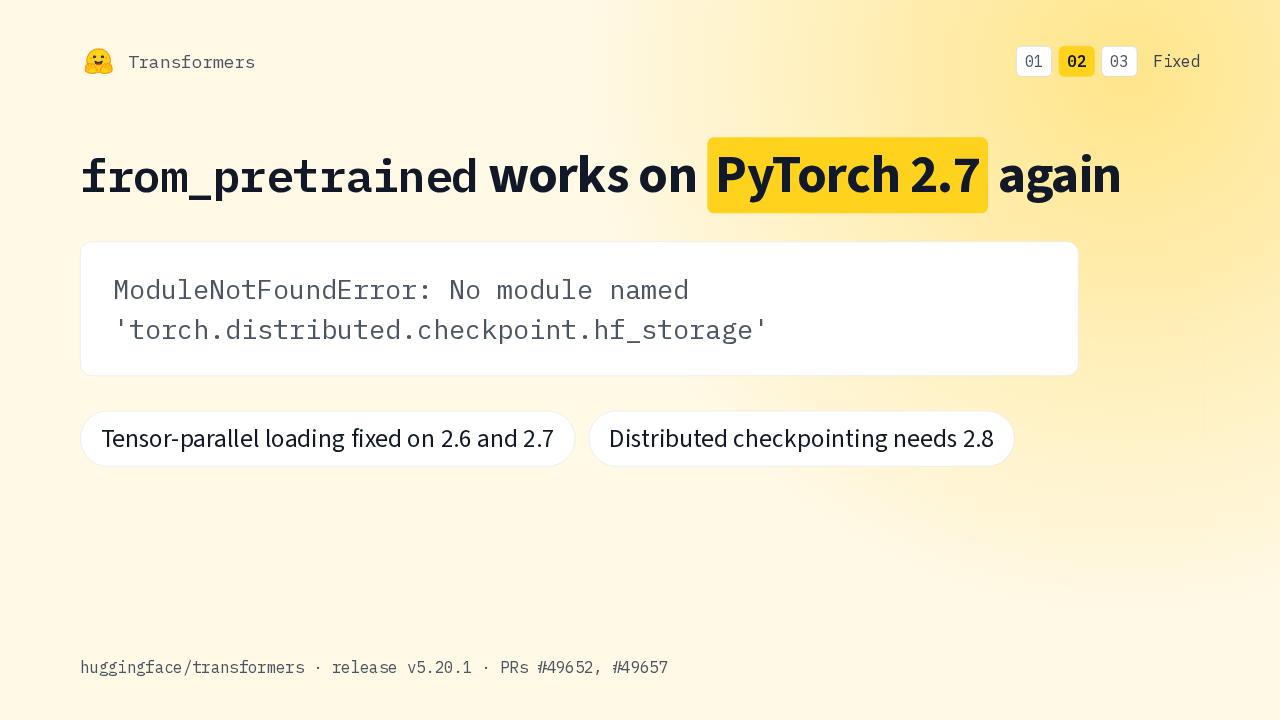
On PyTorch 2.7, every from_pretrained call in 5.20.0 failed with this missing module error. Loading works again, and so does tensor-parallel loading on 2.6 and 2.7. Distributed checkpointing now needs PyTorch 2.8.
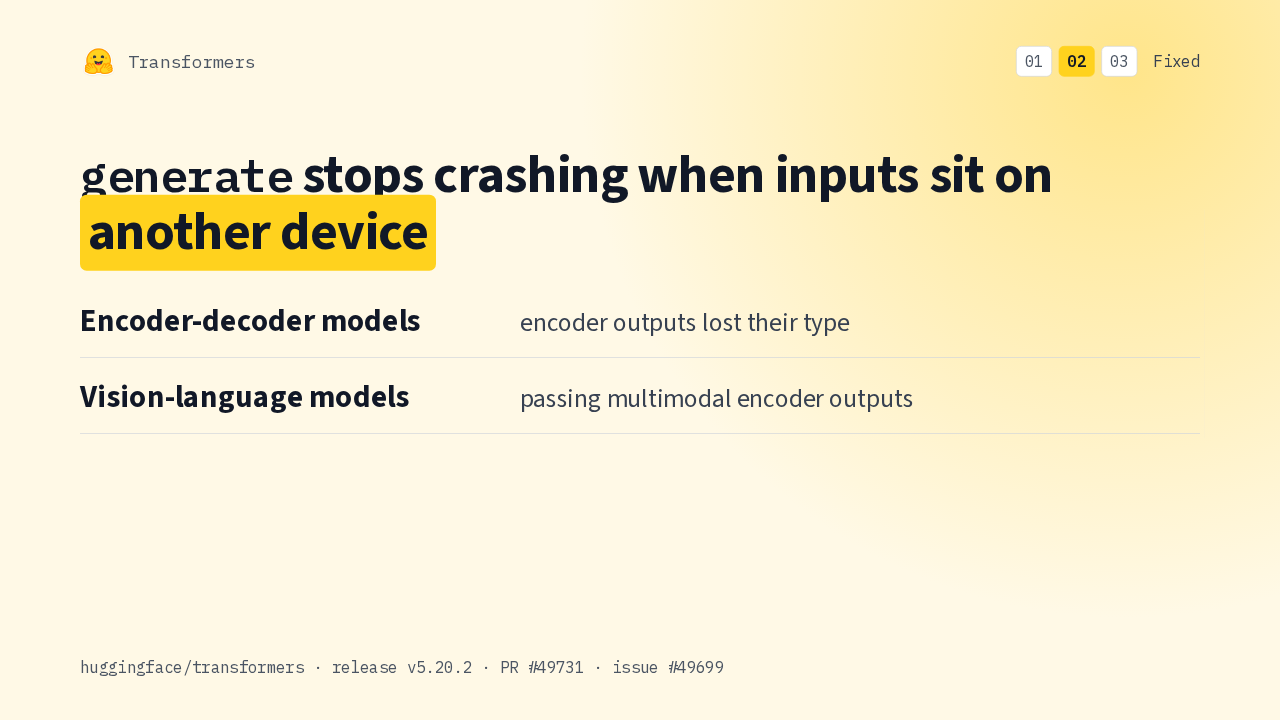
Since 5.20.0, generate crashed for encoder-decoder models and some vision-language models whenever the input IDs sat on a different device from the model. It was rebuilding their encoder outputs as plain dictionaries. It keeps their type now.
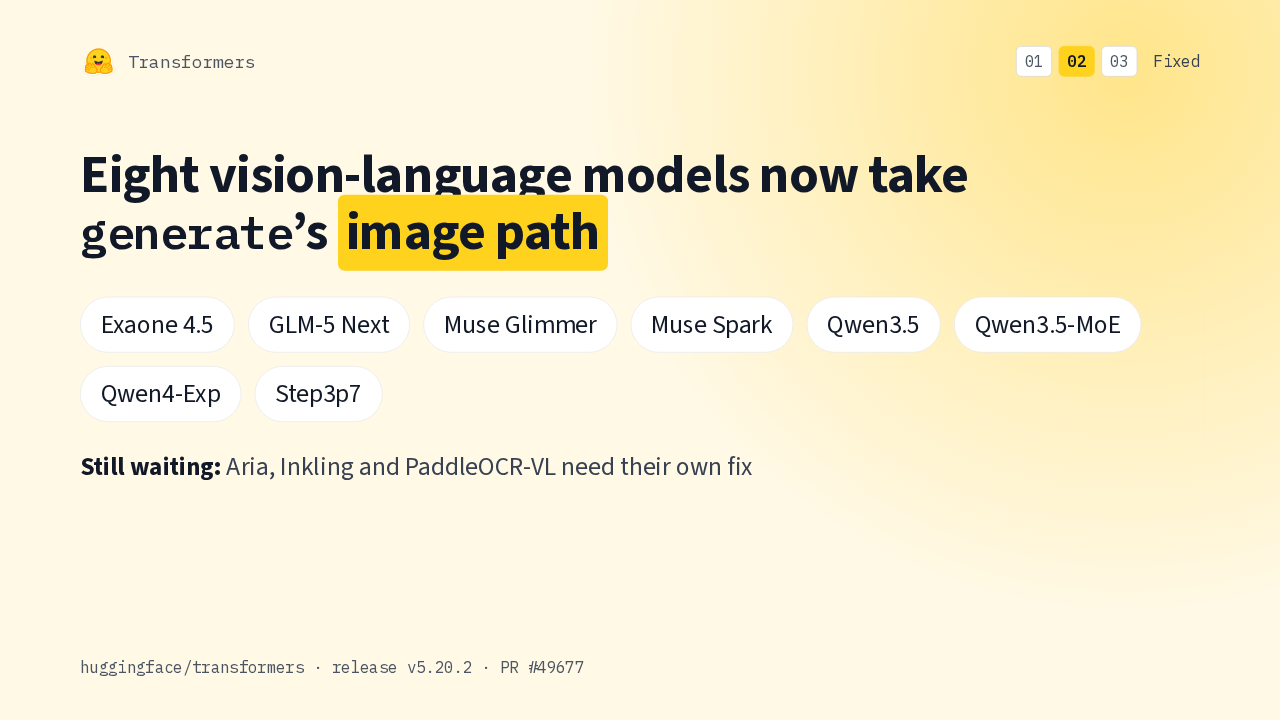
Eight vision-language models, including Qwen3.5 and Muse Spark, declared text as their only input, so generate treated them as text-only. They take the multimodal path now. Aria, Inkling and PaddleOCR-VL have the same bug and still need their own fix.
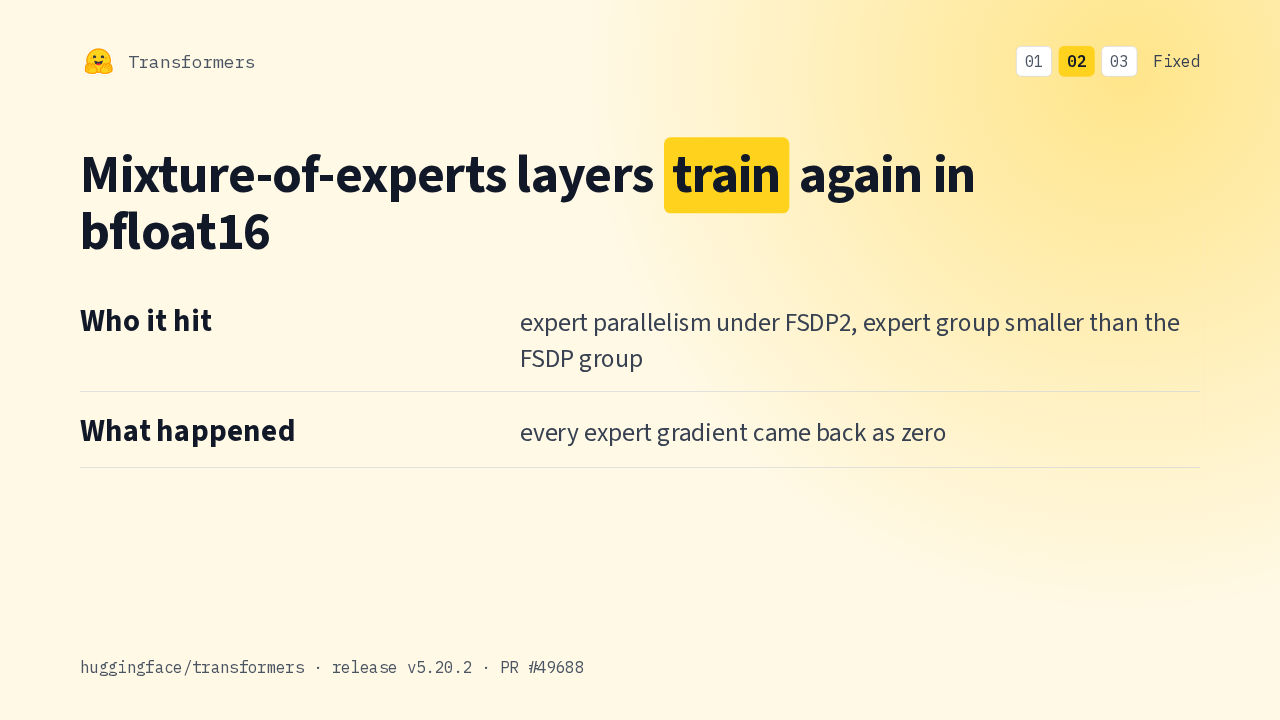
With expert parallelism under FSDP2, and an expert group smaller than the FSDP group, bfloat16 expert gradients came back as zero, so the experts never learned. They get real gradients now.
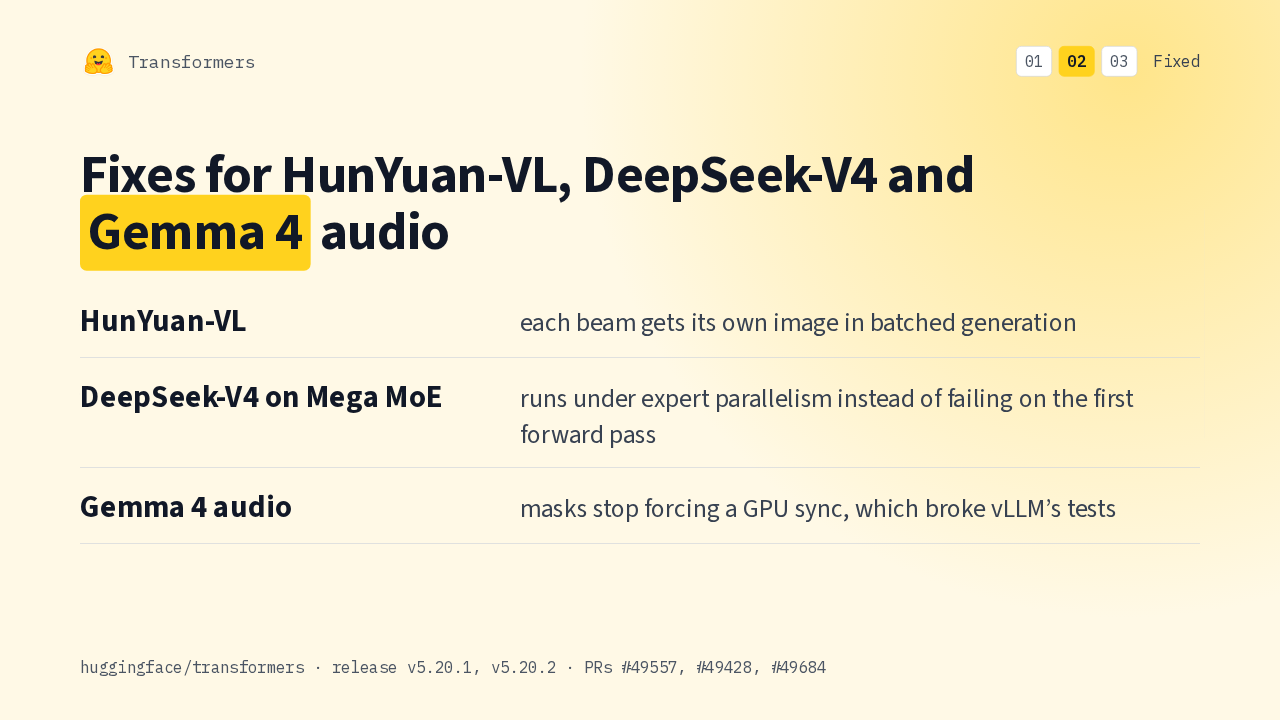
HunYuan-VL gives each beam its own image in batched generation. DeepSeek V4 with the DeepGEMM Mega MoE kernel runs under expert parallelism instead of failing on its first forward pass. And Gemma 4 audio stops forcing a GPU sync on every mask.
The full list of fixes is in the release notes for 5.20.1 and 5.20.2 on GitHub. Which PyTorch version is your training setup pinned to?
Up next
 3:39
Transformers runs Mistral Large 4 and trains LoRA on FP8 checkpoints
@hugging-face
1 week ago
 2:43
huggingface_hub v2.4.0 copies files into Buckets and flags outdated CLI extensions
@hugging-face
1 week ago
 3:05
huggingface_hub v2.3.0 lists an 800,000-file dataset in 20 seconds, down from 13 minutes
@hugging-face
3 weeks ago
 3:46
Transformers v5.20.0 runs Meta's Muse Spark Open, and here is the hardware it needs
@hugging-face
1 month ago
 3:18
huggingface_hub 2.2.0: hf jobs stats prints a snapshot, and parallel downloads always use hf_xet
@hugging-face
1 month ago
 3:12
Transformers v5.19.0: EmbeddingGemma 2 and token-dispatch expert parallelism
@hugging-face
1 month ago
 2:53
huggingface_hub's HfFileSystem now downloads a 2 GB bucket file in seconds
@hugging-face
1 month ago
 3:12
Transformers v5.18.0: streaming speaker diarization, GGUF mixture-of-experts, FSDP2 with expert parallelism
@hugging-face
1 month ago
 2:12
What huggingface_hub 2.0 changes, and why transformers keeps you on 1.x for now
@hugging-face
1 month ago