EmbeddingGemma 2 arrives

Transformers v5.19.0 adds EmbeddingGemma 2
Transformers v5.19.0 adds EmbeddingGemma 2. It's a multimodal embedding model from Google, built on the Gemma 4 architecture.
One vector space for every input
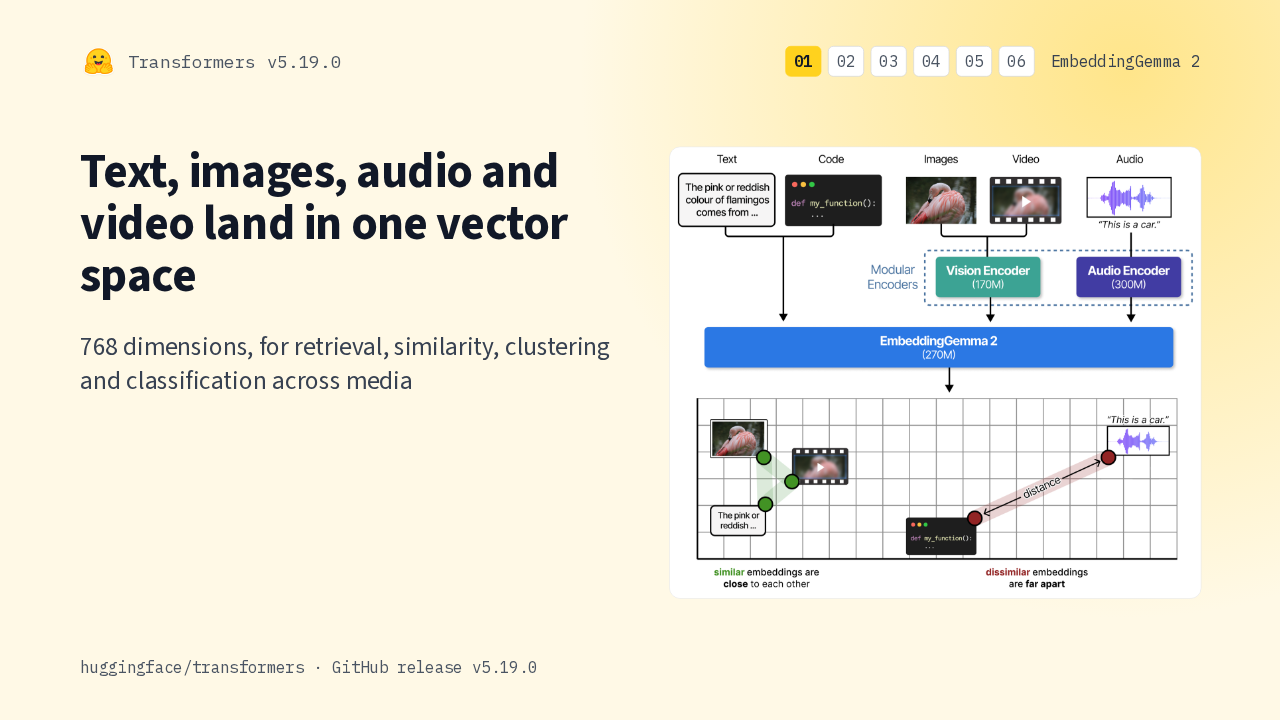
Transformers v5.19.0Text, images, audio and video land in one vector space
768 dimensions, for retrieval, similarity, clustering and classification across media

It encodes text, images, audio and video, one at a time or mixed in a single input, into one shared space. So a text query and a photo can be compared directly.
Shorter embeddings
Transformers v5.19.0Cut each embedding from 768 to 512, 256 or 128 dimensions
Matryoshka Representation Learning: truncate, re-normalize, minimal quality loss
Embeddings come out at 768 dimensions. Because it's trained with Matryoshka Representation Learning, you can keep just the first 512, 256 or 128, and the docs report minimal quality loss.
Load only the towers you need
Transformers v5.19.0Text-only? Leave the vision and audio towers unloaded
Less memory for single-modality deployments. Image and video token budgets are tunable too.
Embedding only text? You can disable the vision or audio tower at load time to save memory. The token budget per image or video frame is configurable as well.
Expert parallelism
Transformers v5.19.0Expert parallelism.
Token dispatch
Transformers v5.19.0Expert-parallel size no longer has to equal tensor-parallel size
Token dispatch: each GPU keeps its own tokens and sends only the routed ones to the experts that own them.
Expert parallelism gets a second mode, token dispatch. Each rank keeps its own tokens and sends only routed tokens to the experts' owners, so expert and tensor parallel sizes become independent.
Default for Qwen3 MoE
Transformers v5.19.0Token dispatch is now the default for Qwen3 MoE and Mellum
The older masked expert parallelism stays available through the expert-parallel plan.
Token dispatch is now the default for Qwen3 MoE and Mellum. The older masked mode, where every rank sees every token, is still there if your plan selects it.
Trainer and PEFT
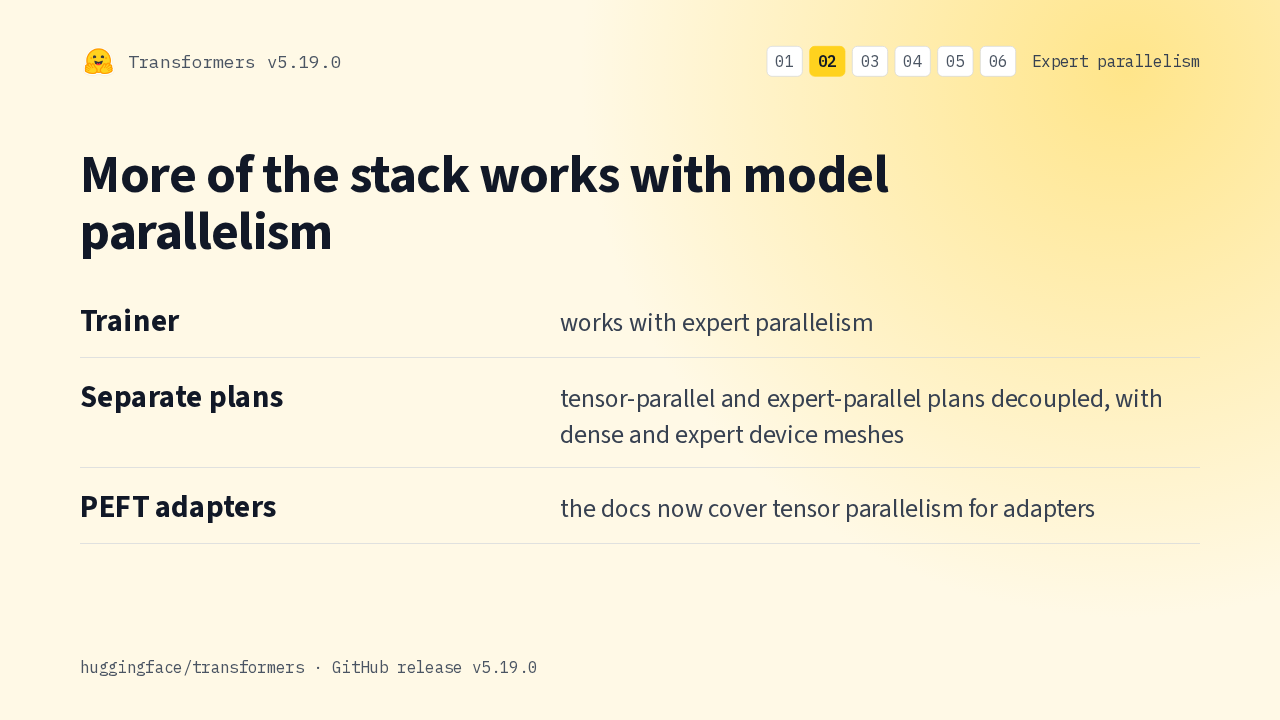
Transformers v5.19.0More of the stack works with model parallelism
The Trainer now works with expert parallelism. Tensor and expert parallel plans are decoupled, each with its own device mesh. And the docs now cover tensor parallelism for PEFT adapters.
Continuous batching
Transformers v5.19.0Continuous batching.
Regular attention runs continuous batching
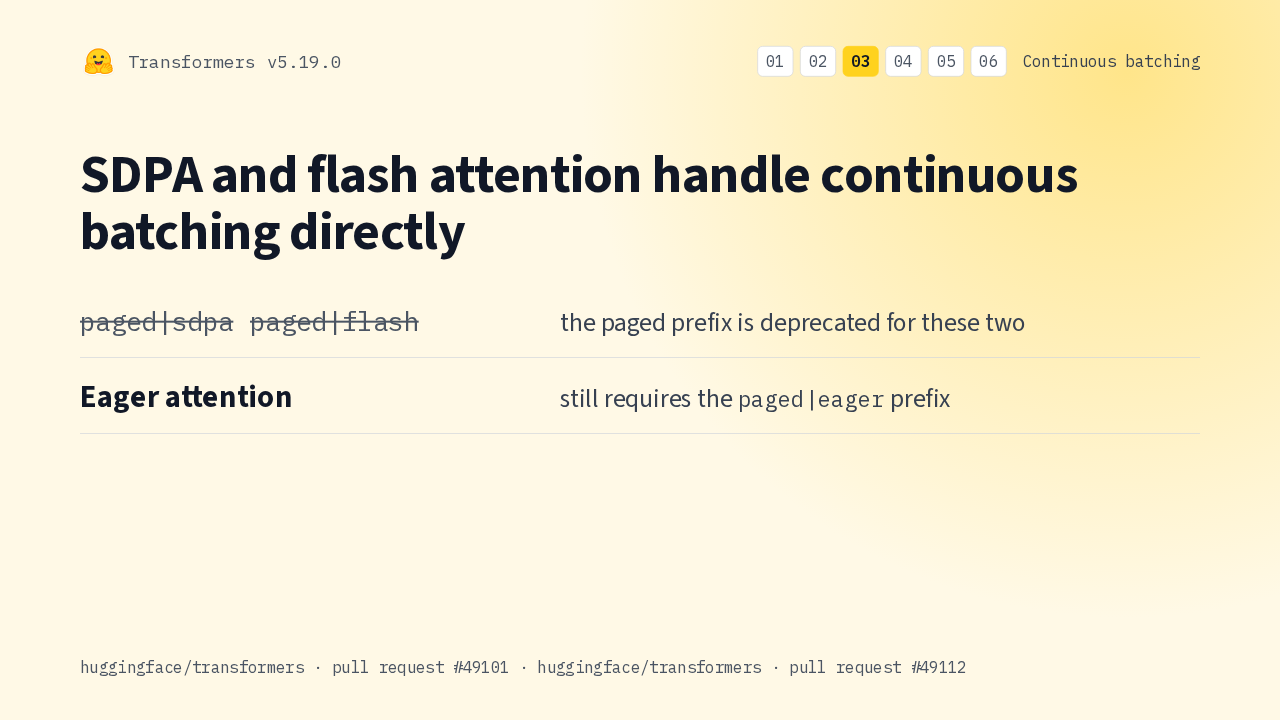
Transformers v5.19.0SDPA and flash attention handle continuous batching directly
paged|eager prefixThe standard SDPA and flash attention functions now support continuous batching themselves. So the paged prefix on those two is deprecated. Eager attention still needs its paged prefix.
Fused cache update
Transformers v5.19.0One cache update call for both continuous-batching paths
The index path and the block-table path now share a single update. Custom code that called them separately is affected.
Inside continuous batching, the index path and block table path now update the cache in one fused call. Custom code that called those update paths separately will need changes.
Cache
Transformers v5.19.0The cache.
Per-layer cache config
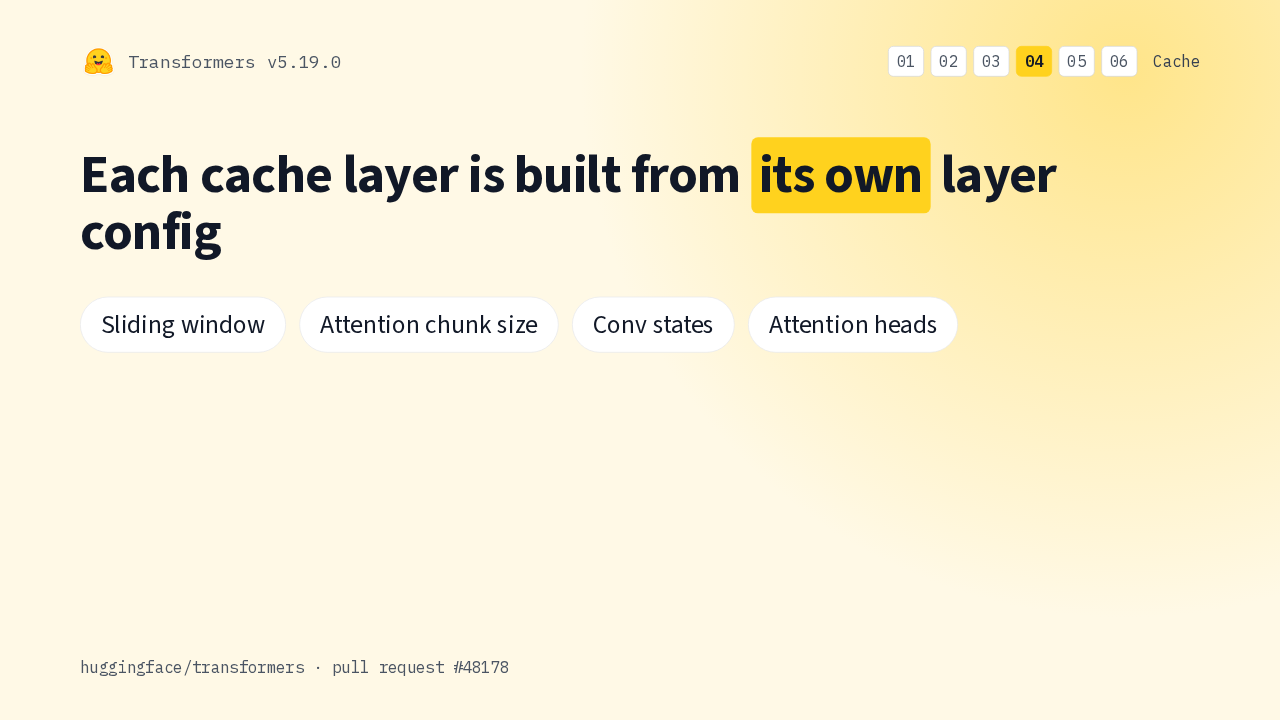
Transformers v5.19.0Each cache layer is built from its own layer config
DynamicCache and StaticCache used to reuse one set of settings for every layer. Now each layer reads its own sliding window, chunk size, conv states and head counts, which suits models with mixed layers.
Quantized cache fixes
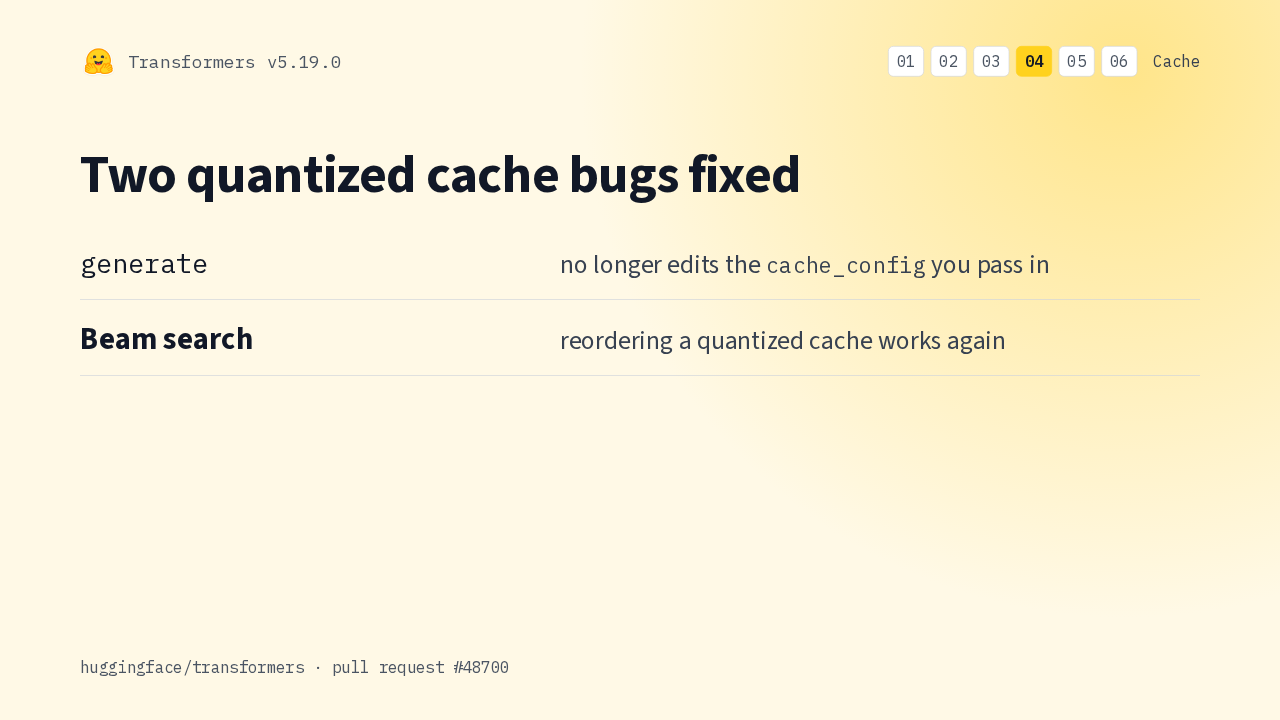
Transformers v5.19.0Two quantized cache bugs fixed
generateno longer edits the cache_config you pass inGenerate used to edit the cache config you passed, so a second model could inherit the first one's settings. And beam search now reorders quantized cache states correctly.
Changed outputs
Transformers v5.19.0Outputs that change.
Router logits from every MoE model
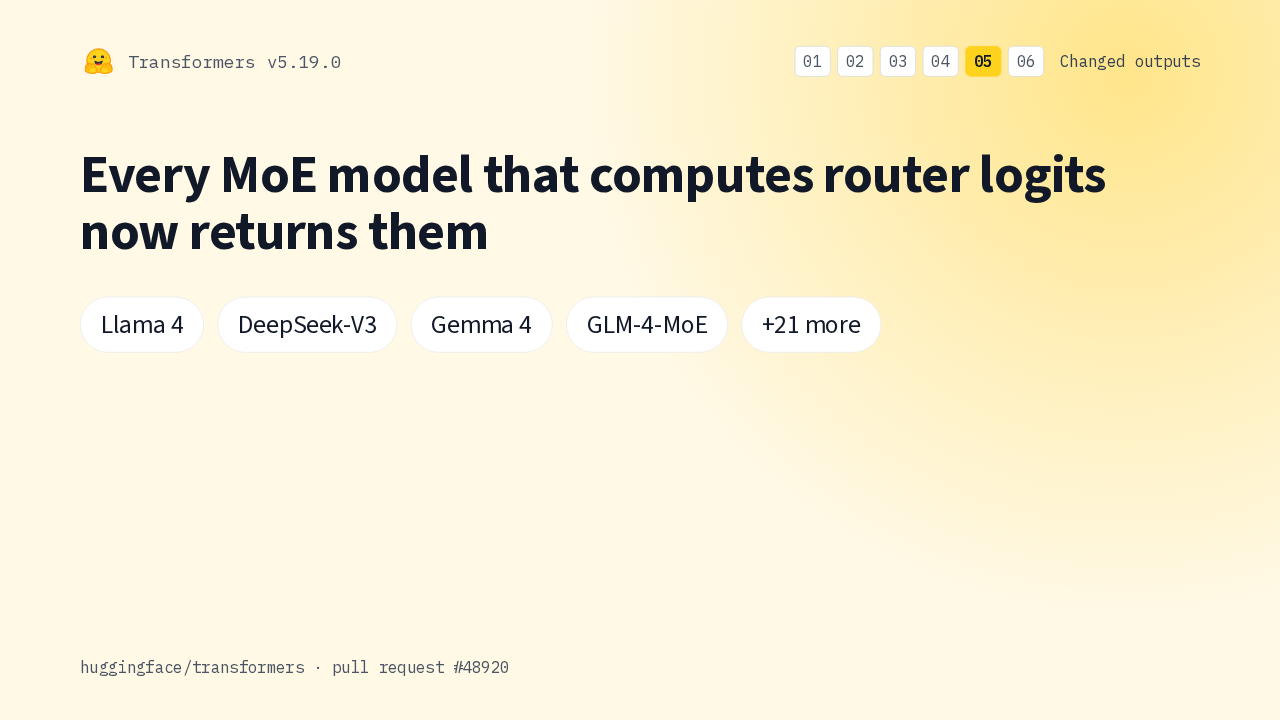
Transformers v5.19.0Every MoE model that computes router logits now returns them
Ask for router logits, and every mixture of experts model whose router computes them now returns them, the way Qwen3 MoE already did. With the flag off, the defaults are unchanged.
OWLv2 query by objectness
Transformers v5.19.0OWLv2 picks its image query by objectness
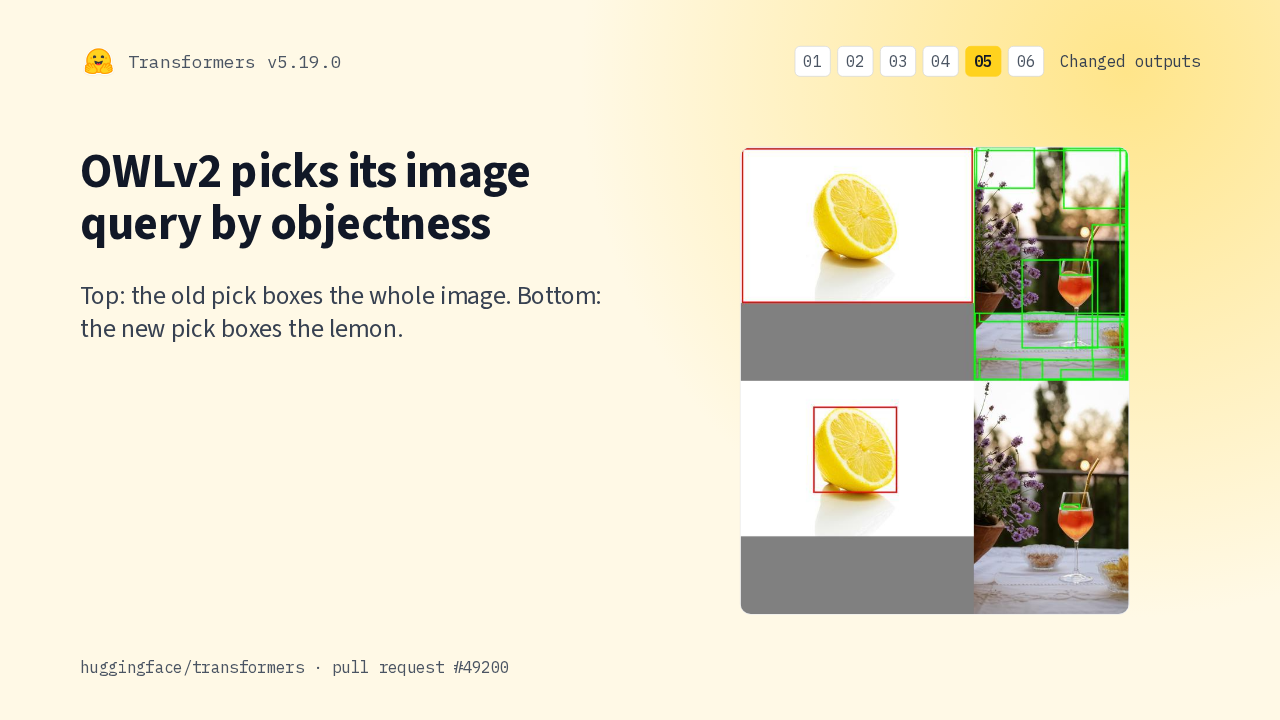
Top: the old pick boxes the whole image. Bottom: the new pick boxes the lemon.

OWLv2 image-guided detection now picks the query box with the highest objectness, as the original OWLv2 notebook does. Here, the old pick boxed the whole lemon photo. Expect detections to differ from earlier releases.
Fixes you may have hit
Transformers v5.19.0Three fixes you may have hit
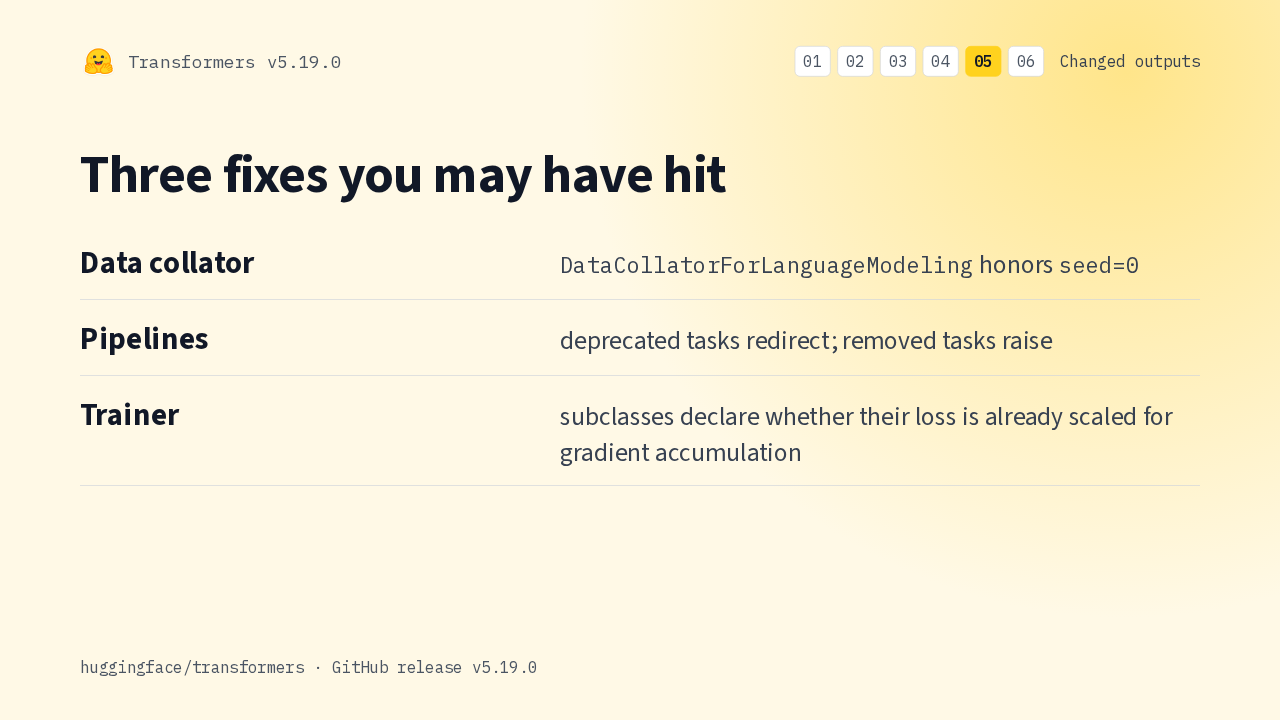
DataCollatorForLanguageModeling honors seed=0The language modeling data collator no longer ignores a seed of zero. Deprecated pipeline tasks now redirect. And Trainer subclasses can declare whether their loss is already scaled for gradient accumulation.
Release notes
Transformers v5.19.0The full list is in the v5.19.0 release notes
github.com/huggingface/transformers › Releases › v5.19.0
The full list of changes is in the Transformers v5.19.0 release notes on GitHub. That's Transformers 5.19: EmbeddingGemma 2, and token dispatch for expert parallelism.