Transformers v5.18.0 learns who spoke when

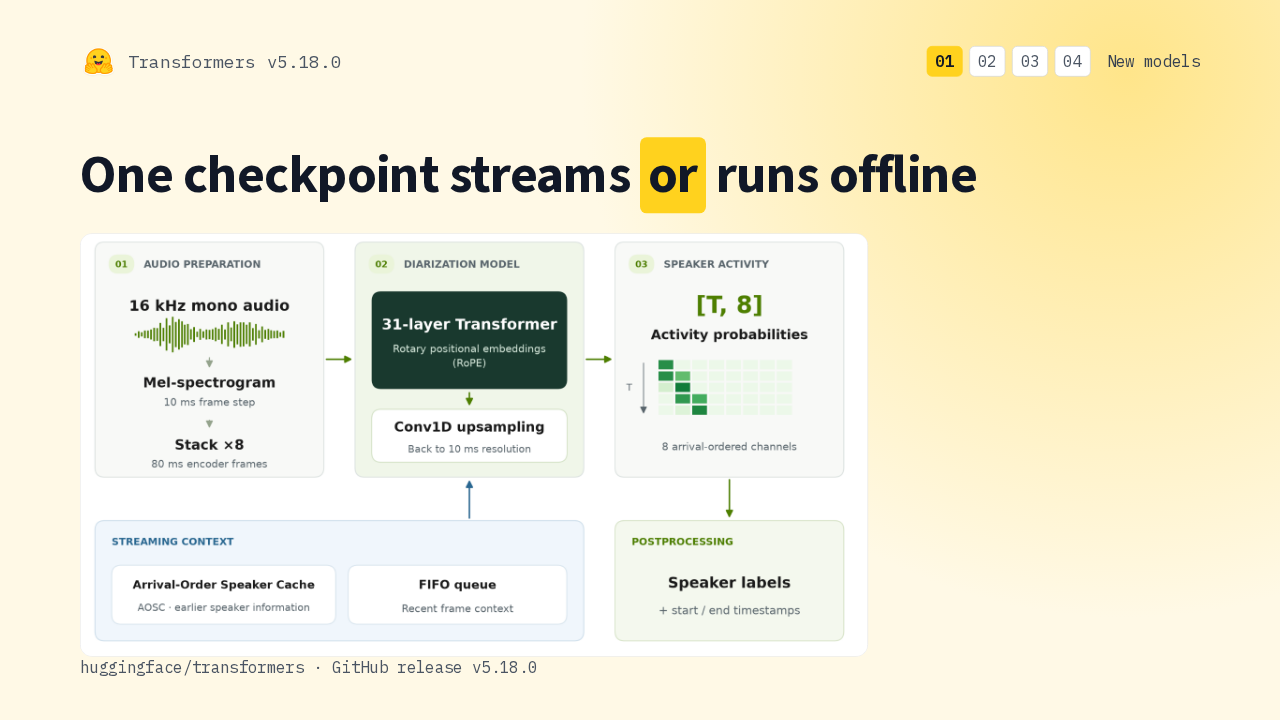
Transformers 5.18 adds Nemotron 3 Diarization, an open-weight model that works out who spoke when. It tracks up to eight speakers, labeled in the order they first speak.
One checkpoint, streaming or offline
Transformers v5.18.0One checkpoint streams or runs offline

One checkpoint streams with a buffer as short as 80 milliseconds, or takes about 30 seconds, like an offline run. Chunked inference puts no limit on audio length.
NemotronH Omni
Transformers v5.18.0NemotronH Omni reasons over text, images, video and sound
NVIDIA's NemotronH Omni pairs a hybrid Mamba-Transformer language model with a RADIO vision encoder and an optional Parakeet sound encoder, so one model reasons across text, images, video and audio.
HyperCLOVAX Vision V2
Transformers v5.18.0HyperCLOVAX Vision V2 thinks before it answers
NAVER's HyperCLOVAX Vision V2 takes text, images and video, and can reason step by step with built-in thinking tokens before it answers.
GTE
Transformers v5.18.0GTE puts RoPE in a BERT-style encoder
GTE is a BERT-style encoder that uses RoPE in place of absolute position embeddings. It's the architecture behind Alibaba's GTE checkpoints and Snowflake's Arctic Embed M version 2.
Running models
Transformers v5.18.0Running models.
GGUF mixture-of-experts
Transformers v5.18.0GGUF now loads mixture-of-experts models
Qwen3.5-35B-A3B, Q4_K_M, Apple Silicon: 59.9 tok/s in Transformers, 59.4 tok/s in llama.cpp
GGUF loading now handles mixture-of-experts models, though only Qwen 3.5 so far. On Apple Silicon, the 35-billion-parameter Qwen 3.5 generated text as fast as it does in llama.cpp.
transformers chat opens GGUF files
Transformers v5.18.0It already worked with transformers serve
The transformers chat command can now load a GGUF file from a model repo. The serve command already could; chat took only a plain model name.
Attention on more hardware
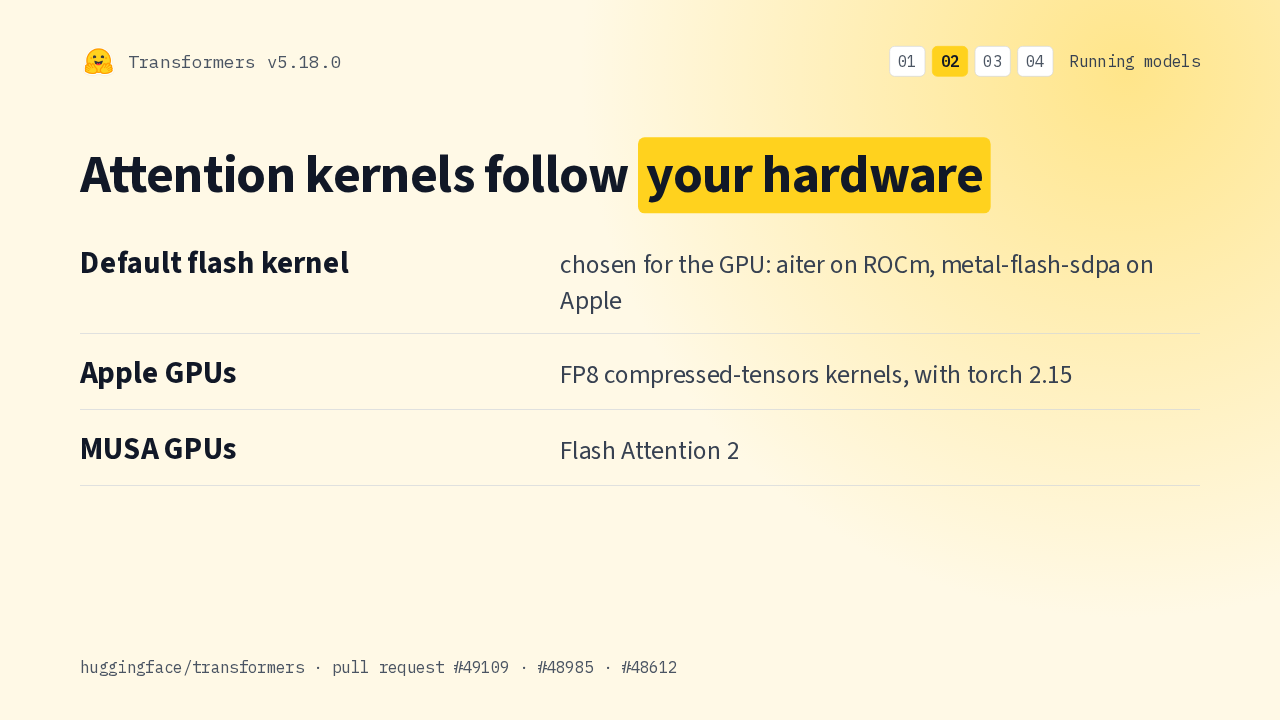
Transformers v5.18.0Attention kernels follow your hardware
When a requested flash kernel won't run, Transformers picks one that runs on your GPU. Apple GPUs get FP8 kernels with PyTorch 2.15. MUSA GPUs get Flash Attention 2.
ExecuTorch export to MLX
Transformers v5.18.0ExecuTorch export gains an MLX backend
For Apple Silicon GPUs. Static or dynamic shapes. The static cache is rejected.
The ExecuTorch exporter gains an MLX backend, for inference on Apple Silicon GPUs. It exports with static or dynamic shapes, It rejects the static cache and points you to the dynamic cache.
Training at scale
Transformers v5.18.0Training at scale.
FSDP2 with expert parallelism
Transformers v5.18.0FSDP2 and expert parallelism train together
The Trainer runs a 2-D (fsdp, tp) device mesh end to end
Expert parallelism shards only the experts, so every GPU still holds the whole dense part. The Trainer can now shard that too, with FSDP2 on a two-dimensional mesh. Before, that combination raised an error.
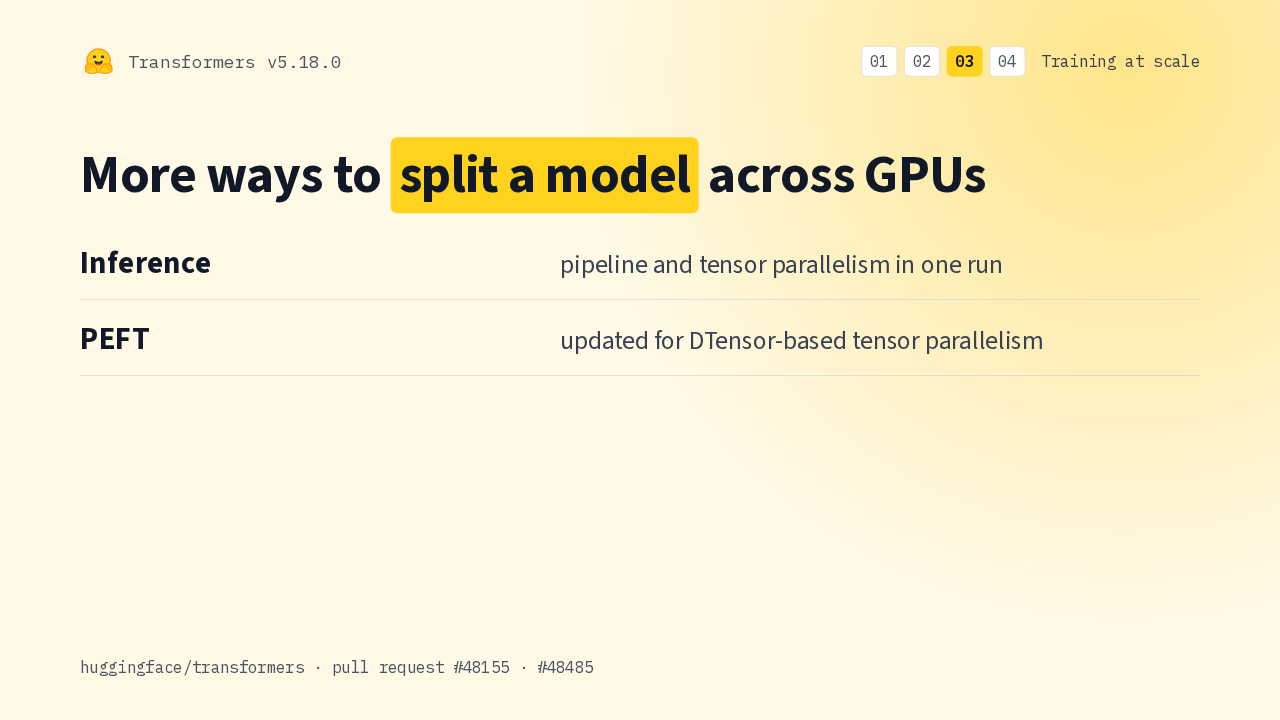
More ways to split a model
Transformers v5.18.0More ways to split a model across GPUs
Inference can now combine pipeline and tensor parallelism in one run. And the PEFT integration now works with DTensor-based tensor parallelism.
Before you upgrade
Transformers v5.18.0Before you upgrade.
huggingface_hub 2.0 allowed
Transformers v5.18.0Transformers now accepts huggingface_hub 2.0
Upper bound raised to <3.0. Lower bound stays at 1.31.0.
Transformers now allows version 2 of huggingface_hub. Its breaking changes don't affect Transformers, and the oldest supported version stays at 1.31.
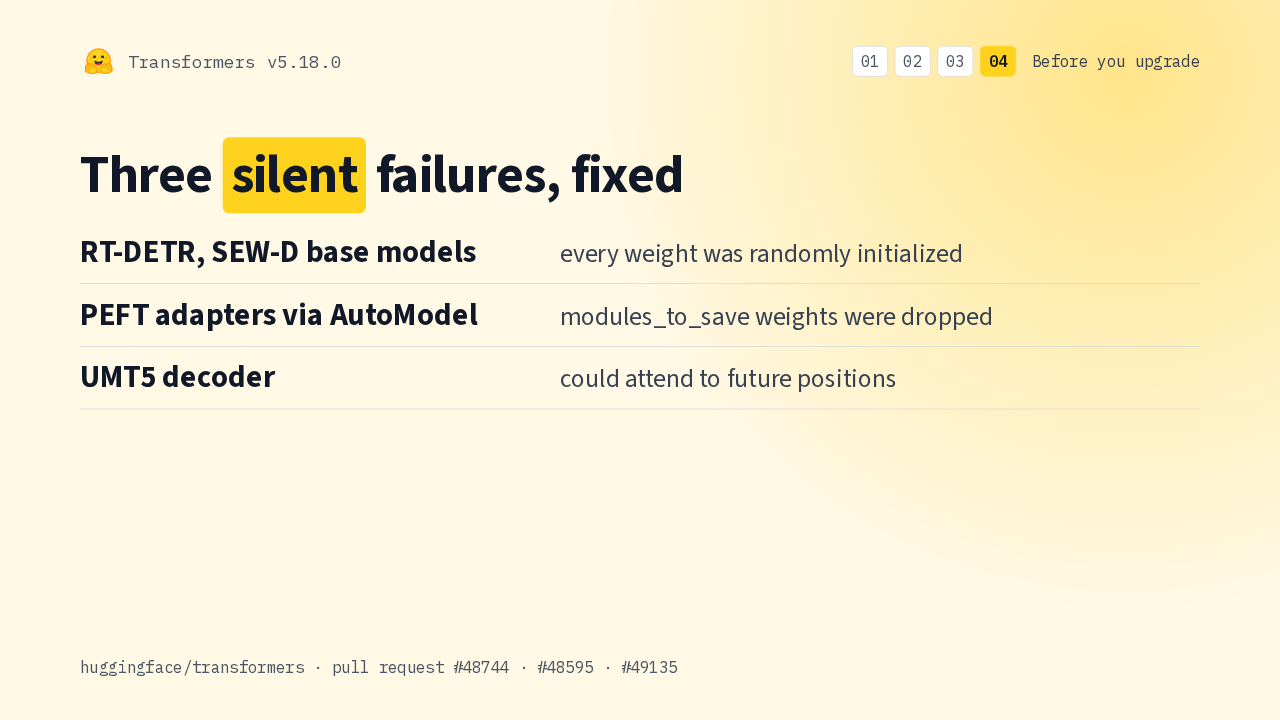
Silent bugs fixed
Transformers v5.18.0Three silent failures, fixed
Loading an RT-DETR or SEW-D base model left every weight random, with only a warning. PEFT adapters loaded through AutoModel dropped extra saved modules like a classifier head. The UMT5 decoder could see future tokens.
Marked breaking
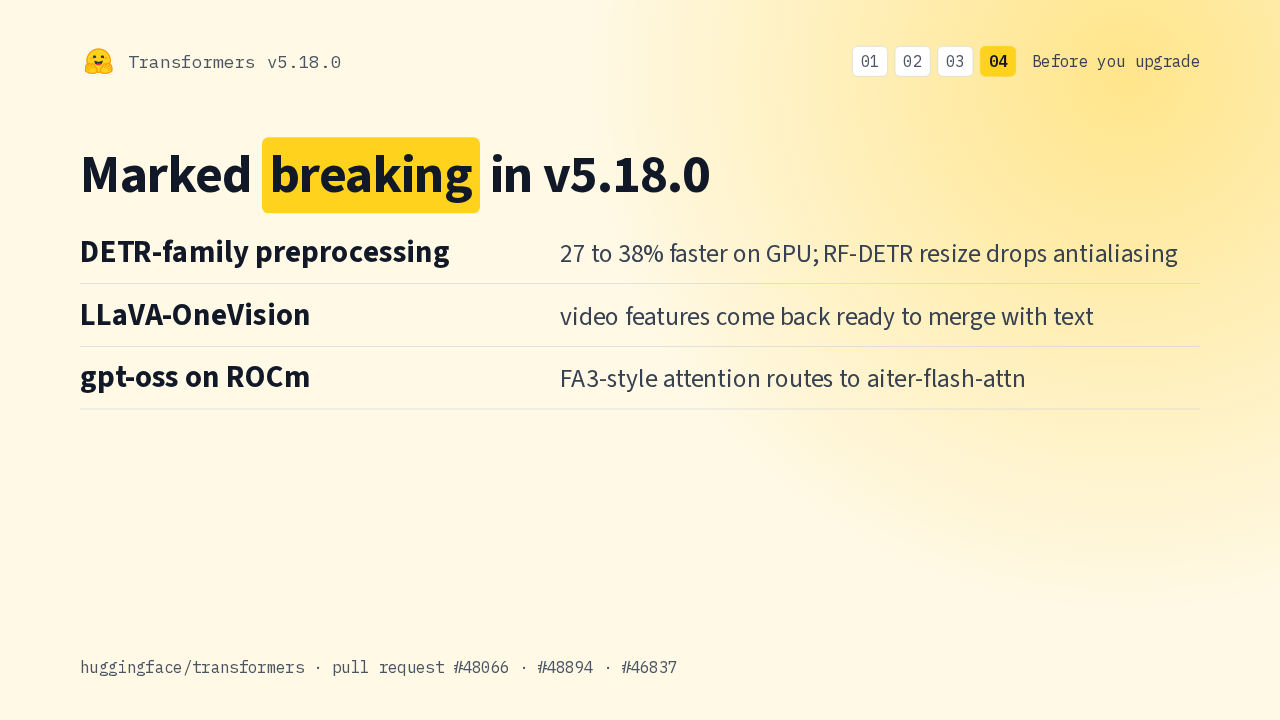
Transformers v5.18.0Marked breaking in v5.18.0
DETR-family preprocessing runs up to a third faster on GPU, and RF-DETR resizes without antialiasing. LLaVA-OneVision returns video features ready to merge with text. gpt-oss on ROCm moves to the aiter kernel.
use_mamba_kernels deprecated
Transformers v5.18.0use_mamba_kernels
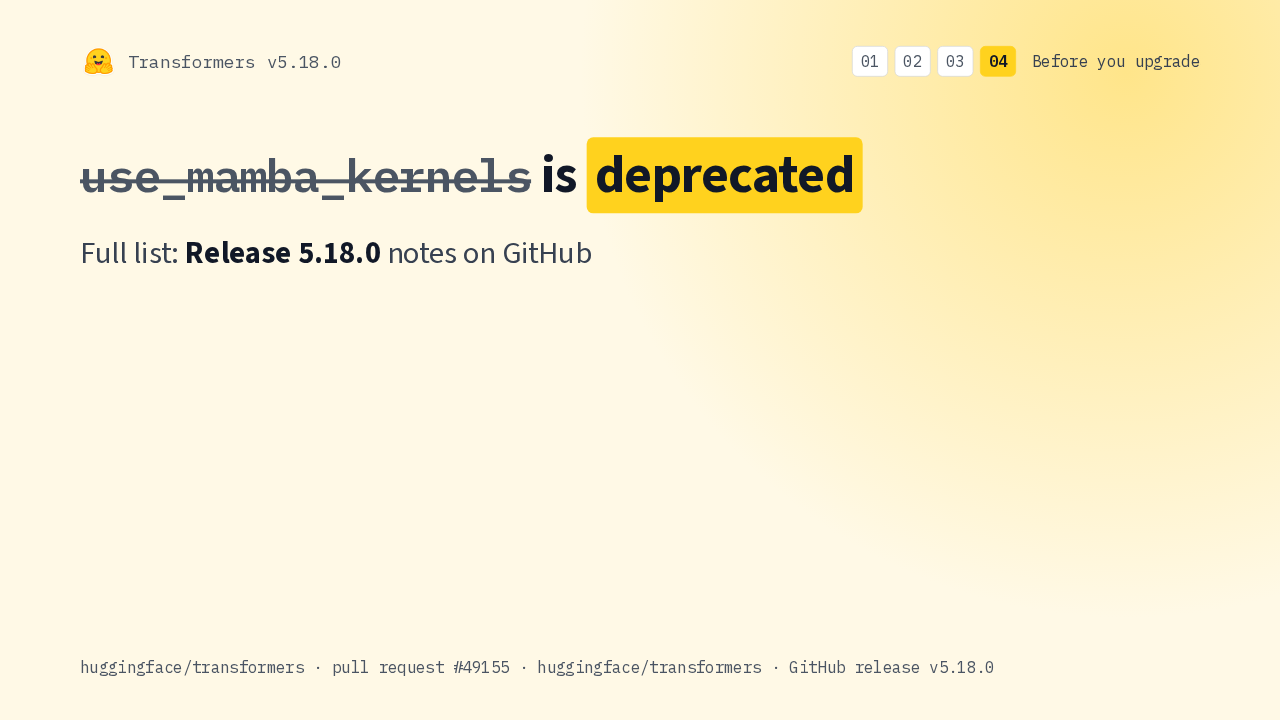
use_mamba_kernelsFull list: Release 5.18.0 notes on GitHub
The use_mamba_kernels flag has done nothing since 5.15, and now warns when set to false. Every other change is in the Release 5.18 notes on GitHub.