

Beam
 Transformers
 now runs Beam, Reflection AI’s open-weight model

Transformers now runs Beam, the first open-weight model from Reflection AI. It's a mixture of experts with 501 billion parameters, 23 billion of them active per token, built for coding, reasoning and agent work.
Beam hardware
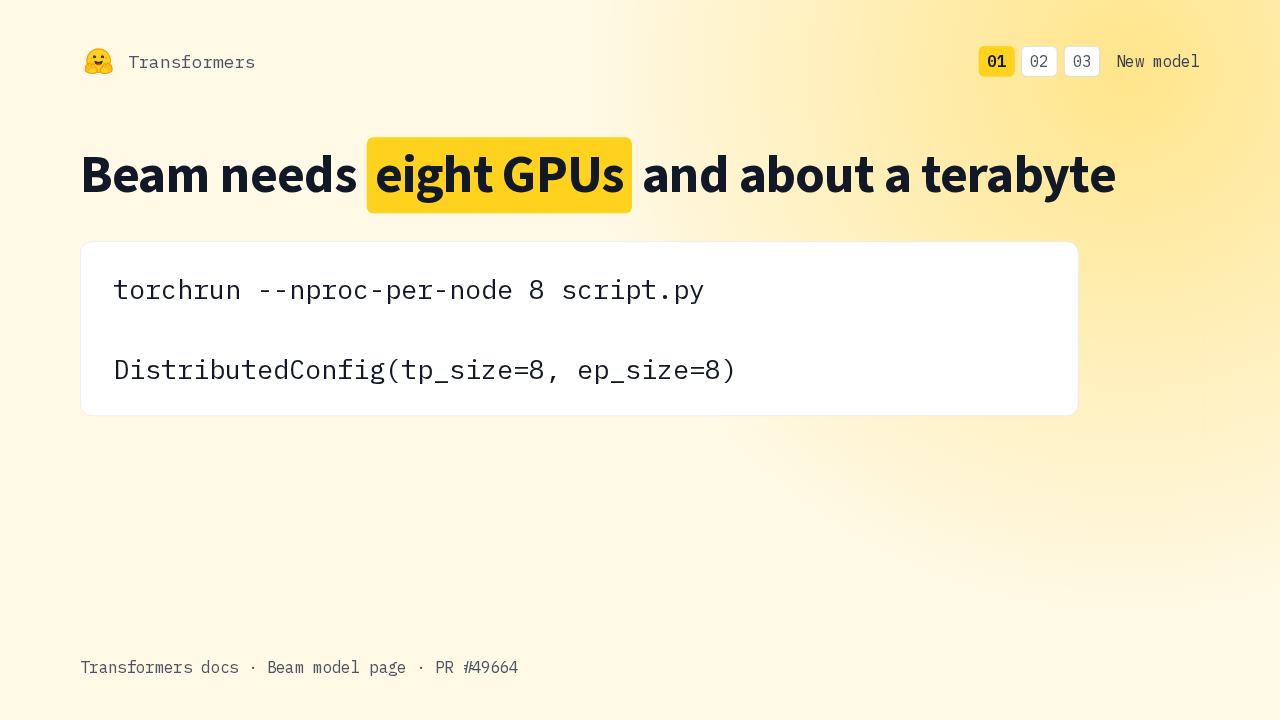
TransformersBeam needs eight GPUs and about a terabyte
torchrun --nproc-per-node 8 script.pyDistributedConfig(tp_size=8, ep_size=8)
The BF16 checkpoint is about a terabyte. The examples shard it across eight GPUs with expert parallelism, which puts whole experts on each device. That beats device_map auto, which can run out of memory while loading.
Reasoning effort
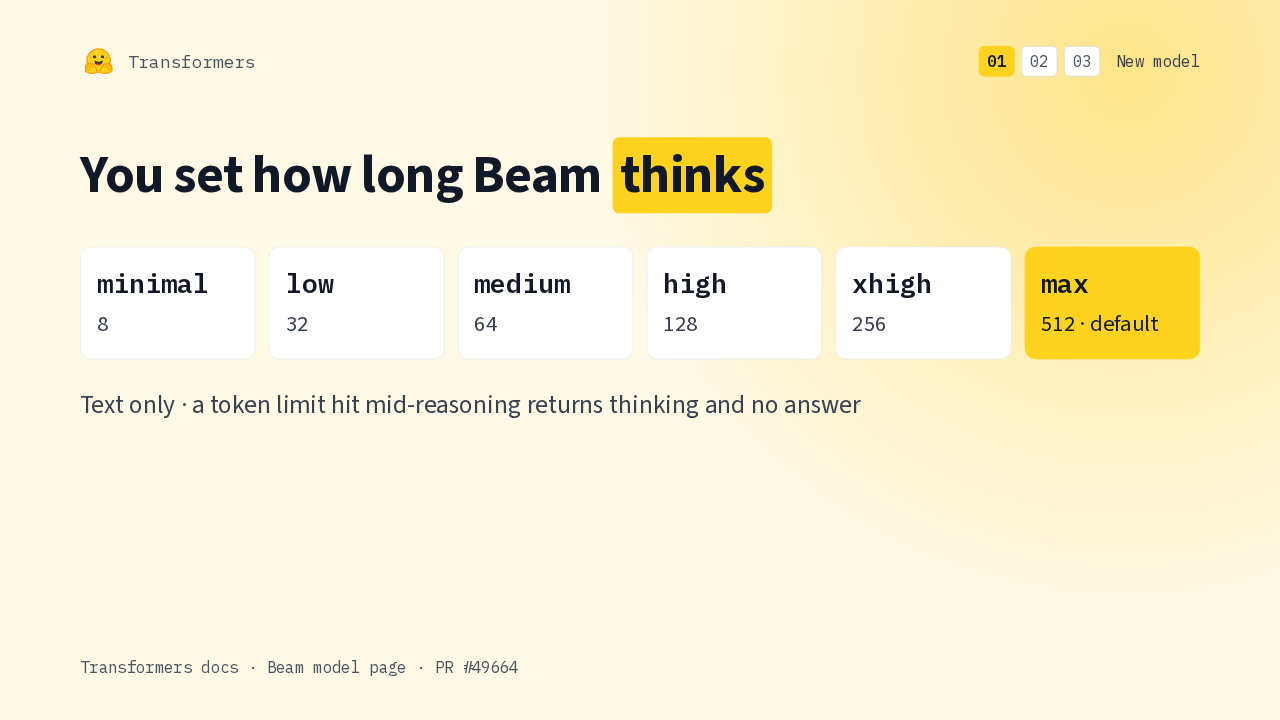
TransformersYou set how long Beam thinks
Text only · a token limit hit mid-reasoning returns thinking and no answer
Beam reasons before every answer, and a reasoning effort setting in the chat template controls how much. It runs from minimal up to max, the default. If the token limit runs out mid-reasoning, you get thinking and no answer.
PyTorch 2.7
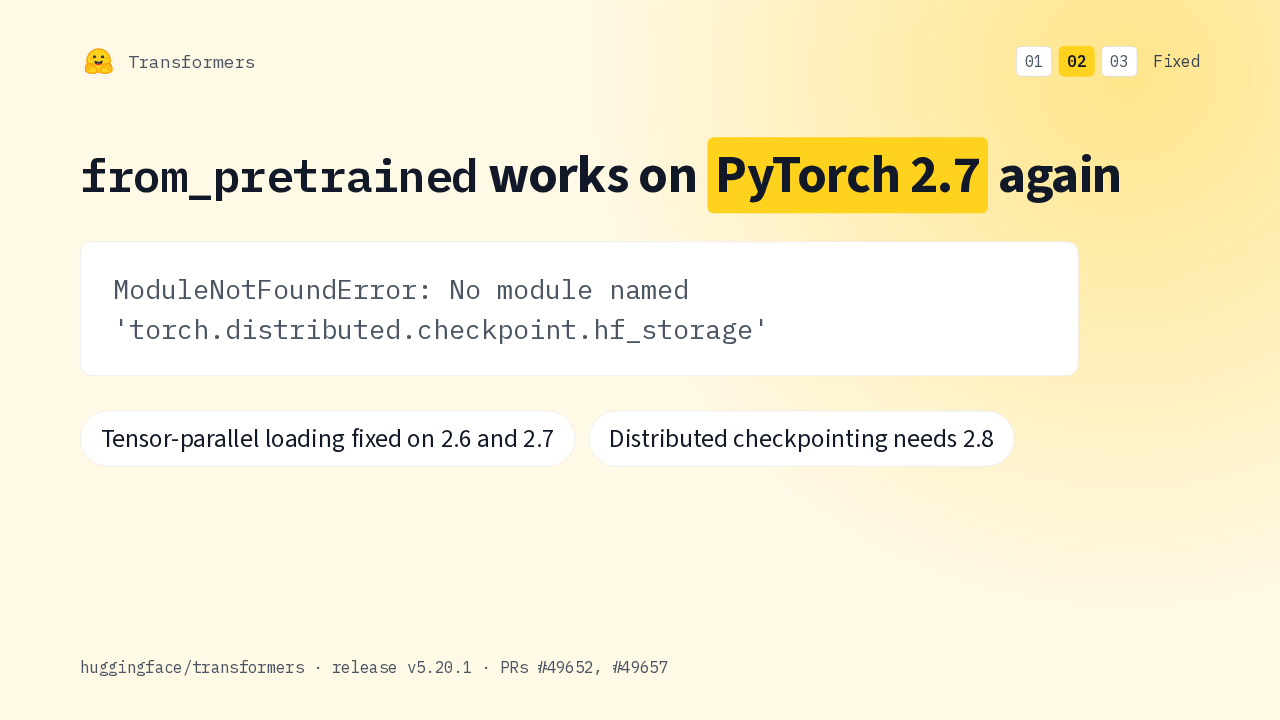
Transformersfrom_pretrained works on PyTorch 2.7 again
ModuleNotFoundError: No module named
'torch.distributed.checkpoint.hf_storage'On PyTorch 2.7, every from_pretrained call in 5.20.0 failed with this missing module error. Loading works again, and so does tensor-parallel loading on 2.6 and 2.7. Distributed checkpointing now needs PyTorch 2.8.
generate across devices
Transformersgenerate stops crashing when inputs sit on another device
Since 5.20.0, generate crashed for encoder-decoder models and some vision-language models whenever the input IDs sat on a different device from the model. It was rebuilding their encoder outputs as plain dictionaries. It keeps their type now.
Vision-language models
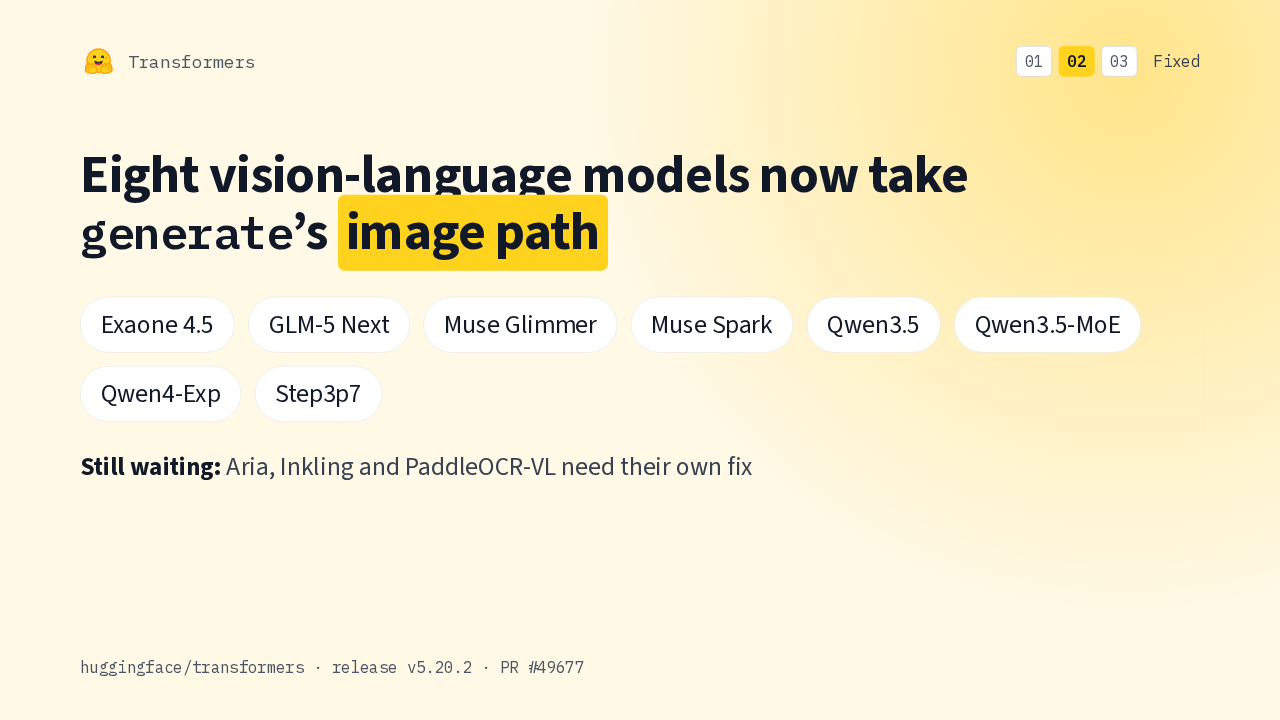
TransformersEight vision-language models now take generate’s image path
Still waiting: Aria, Inkling and PaddleOCR-VL need their own fix
Eight vision-language models, including Qwen3.5 and Muse Spark, declared text as their only input, so generate treated them as text-only. They take the multimodal path now. Aria, Inkling and PaddleOCR-VL have the same bug and still need their own fix.
Expert gradients
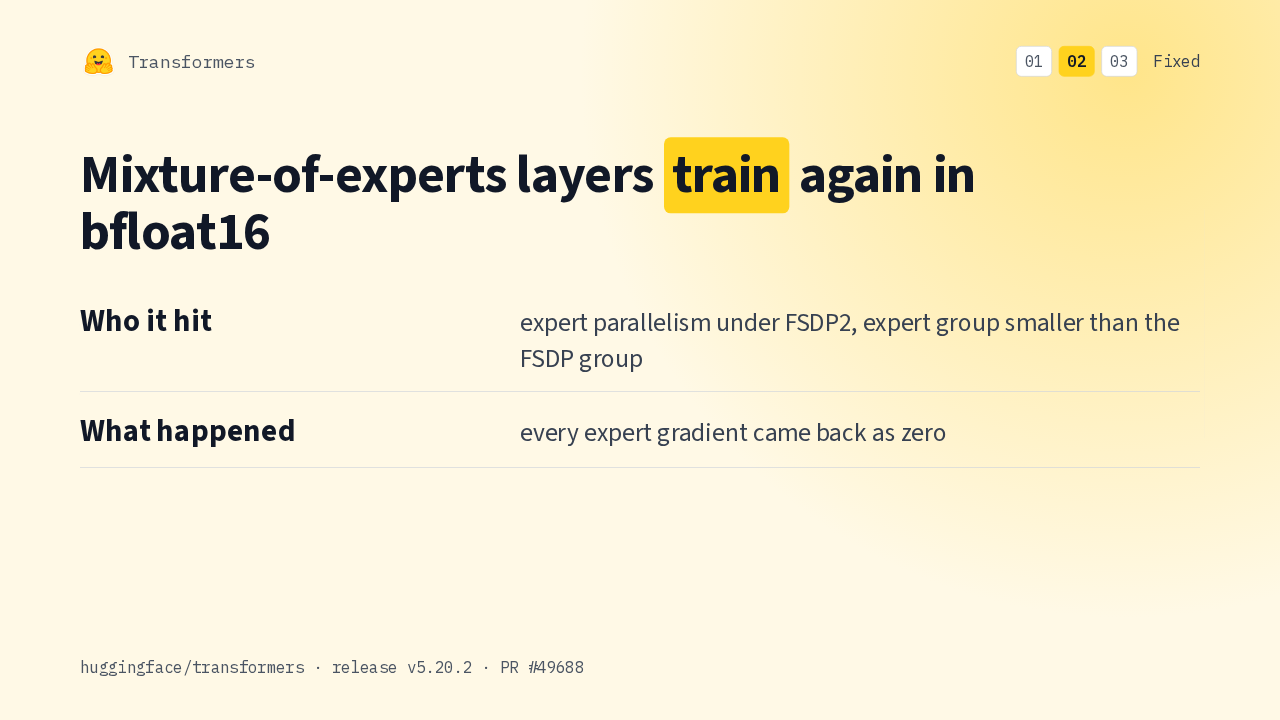
TransformersMixture-of-experts layers train again in bfloat16
With expert parallelism under FSDP2, and an expert group smaller than the FSDP group, bfloat16 expert gradients came back as zero, so the experts never learned. They get real gradients now.
Smaller fixes
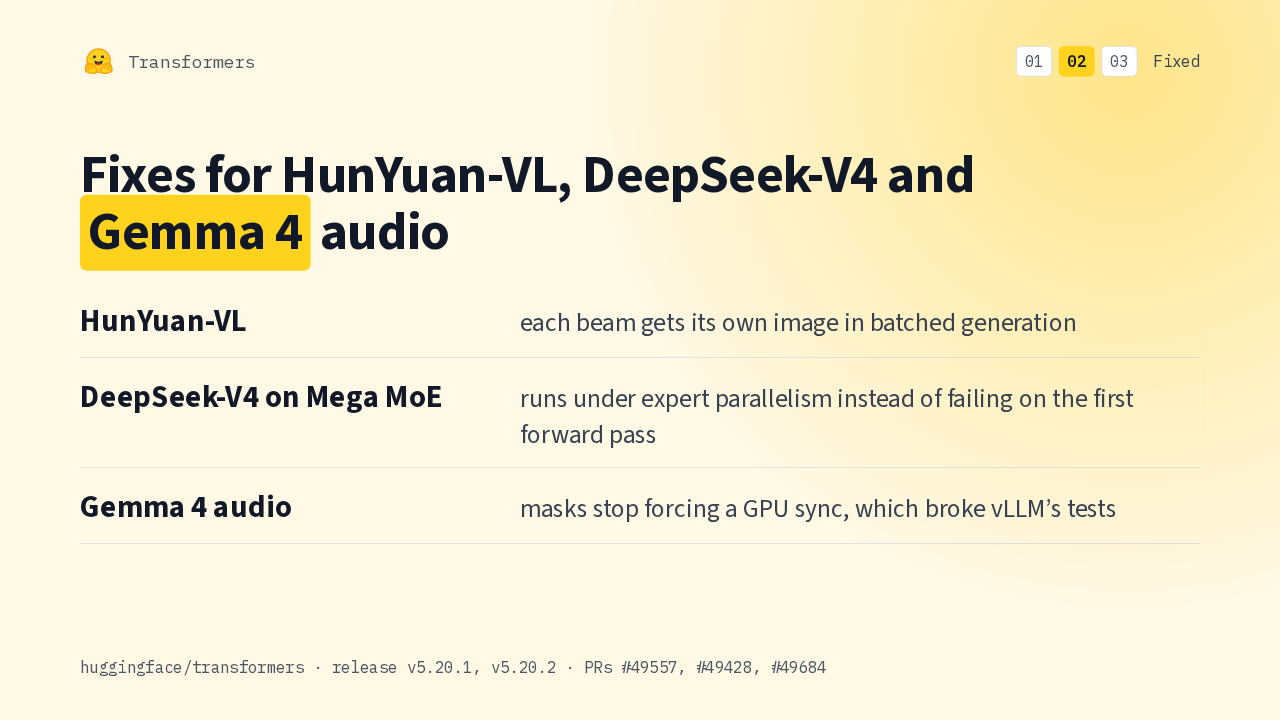
TransformersFixes for HunYuan-VL, DeepSeek-V4 and Gemma 4 audio
HunYuan-VL gives each beam its own image in batched generation. DeepSeek V4 with the DeepGEMM Mega MoE kernel runs under expert parallelism instead of failing on its first forward pass. And Gemma 4 audio stops forcing a GPU sync on every mask.
Release notes
TransformersWhich PyTorch version is your training setup pinned to?
Full list: the Transformers v5.20.1 and v5.20.2 release notes on GitHub
The full list of fixes is in the release notes for 5.20.1 and 5.20.2 on GitHub. Which PyTorch version is your training setup pinned to?