DwarfStar · run DeepSeek’s newest open model on your own machine
DwarfStar
The best AI models live in somebody else’s data center. You rent them by the word. DwarfStar is an engine that runs one of those models on your own computer. That model is two hundred and eighty four billion parameters, the numbers that make up an AI model.
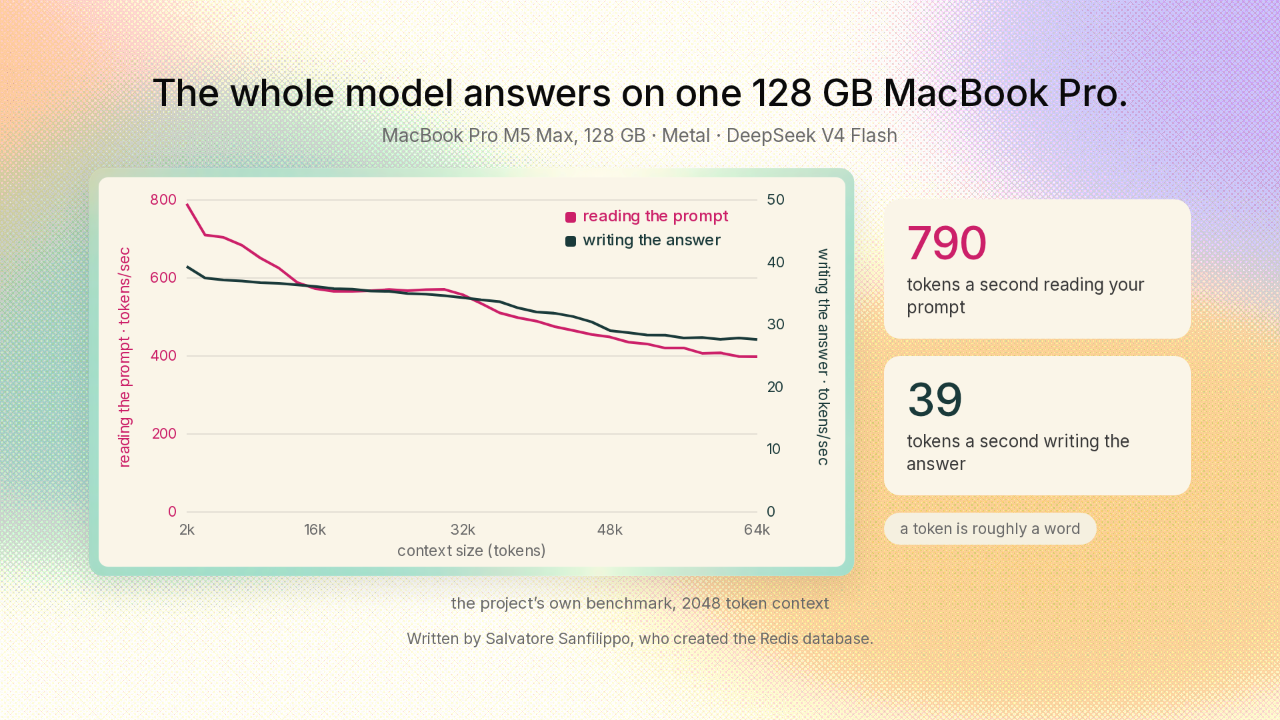
The whole model answers on one 128 GB MacBook Pro
The whole model answers on one 128 GB MacBook Pro.
That model comes from DeepSeek. DwarfStar is the program that runs it, built and tested for a short list of models. On a MacBook Pro with a hundred and twenty eight gigabytes of memory, the project measured DwarfStar reading a prompt at seven hundred and ninety words a second, and writing the answer at thirty nine words a second. Your words never leave your machine. There is no bill per question.
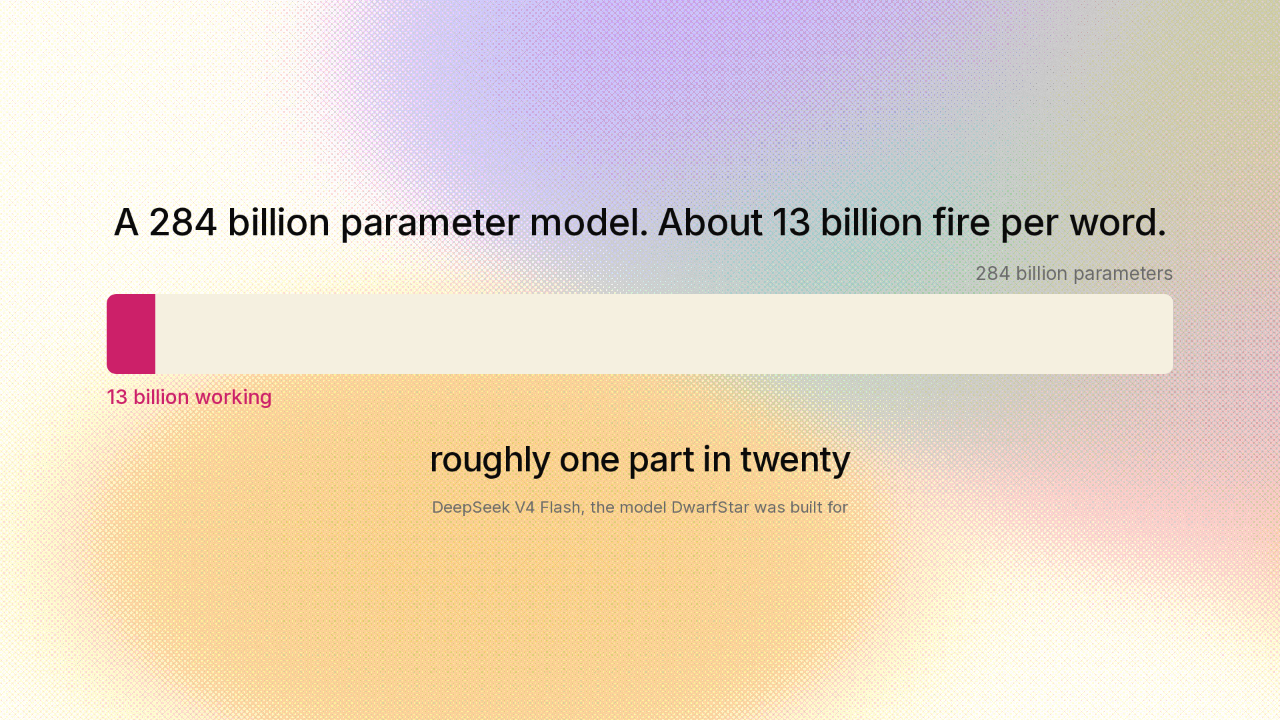
A 284 billion parameter model. About 13 billion fire per word.
Hundreds of separate specialists sit inside a model like this, called experts. Only a handful of them switch on for any given word. So of the two hundred and eighty four billion parameters, only about one in twenty does anything for the word you just typed. Picture a hospital with hundreds of specialists. Any one patient sees two or three. The experts that stay idle are almost all of the model’s size, and they are the part you get to move around.
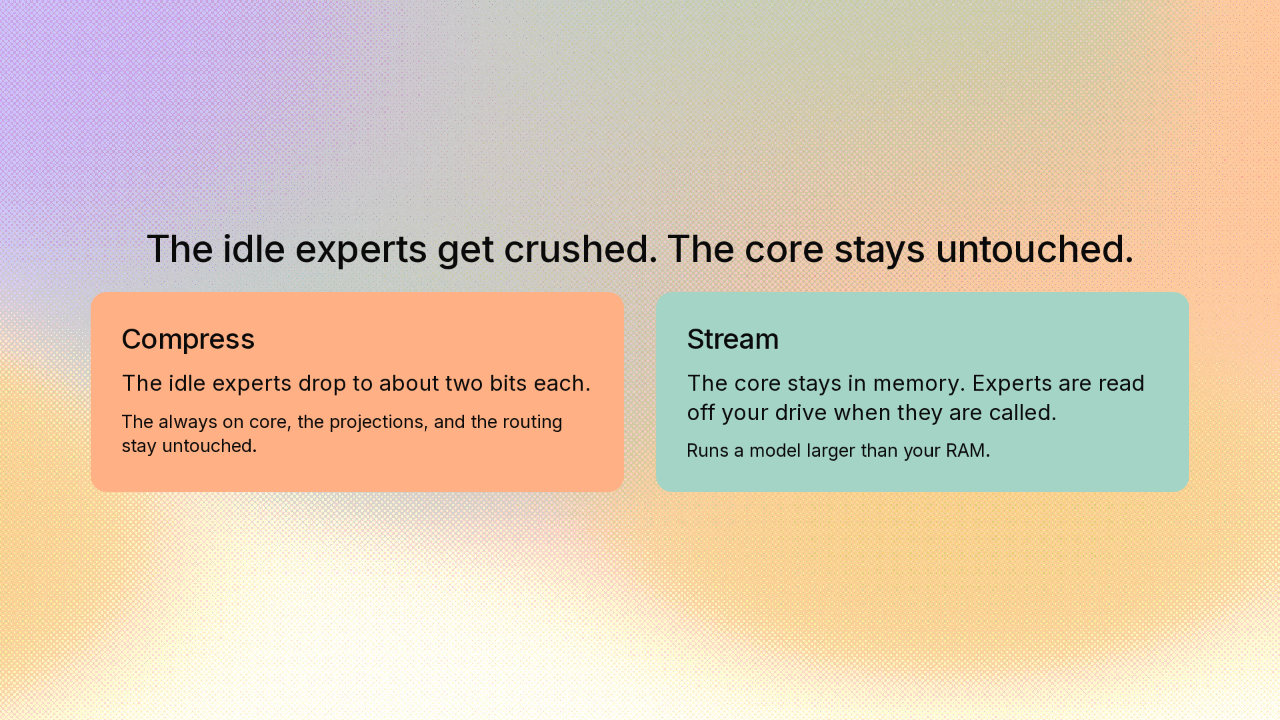
The idle experts get crushed. The core stays untouched.
First, DwarfStar crushes those idle experts. Every number inside them gets squeezed down to about two bits each. That is almost no space. The always on core keeps its full precision, and so does the part that picks the experts. That protects the quality. Second, DwarfStar can leave the experts on your drive. The core stays in memory. When a word needs an expert that is not loaded, DwarfStar reads it off your solid state drive right then. That runs a model too big for your memory.
Split across two machines, and their memory adds up
Split across two machines, and their memory adds up.
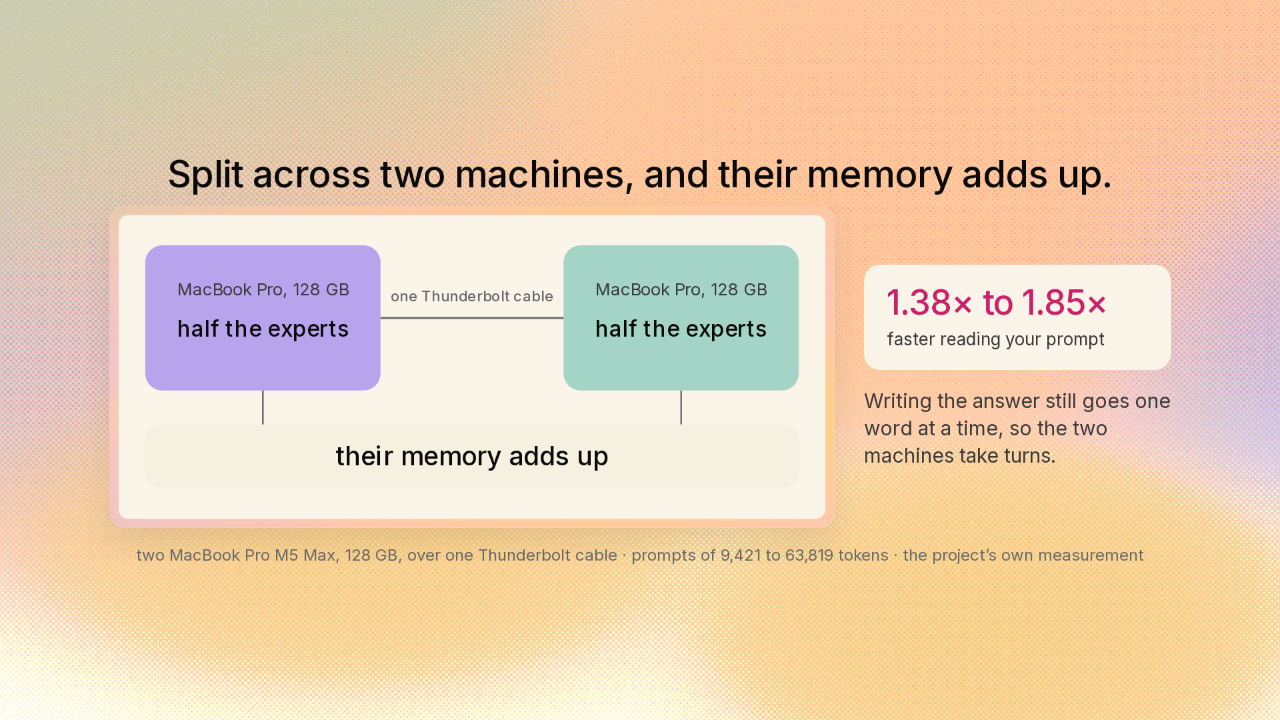
The third move splits the model across two computers. Half the experts live on each machine, so their memory adds up. A model neither computer could hold alone runs across the pair. Both machines also read your prompt at once, and the project measured that step at up to one point eight five times faster. Writing the answer works differently. Each word waits on the word before it, so the two machines have to take turns.
Both machines work on the same word at once
Both machines work on the same word at once.
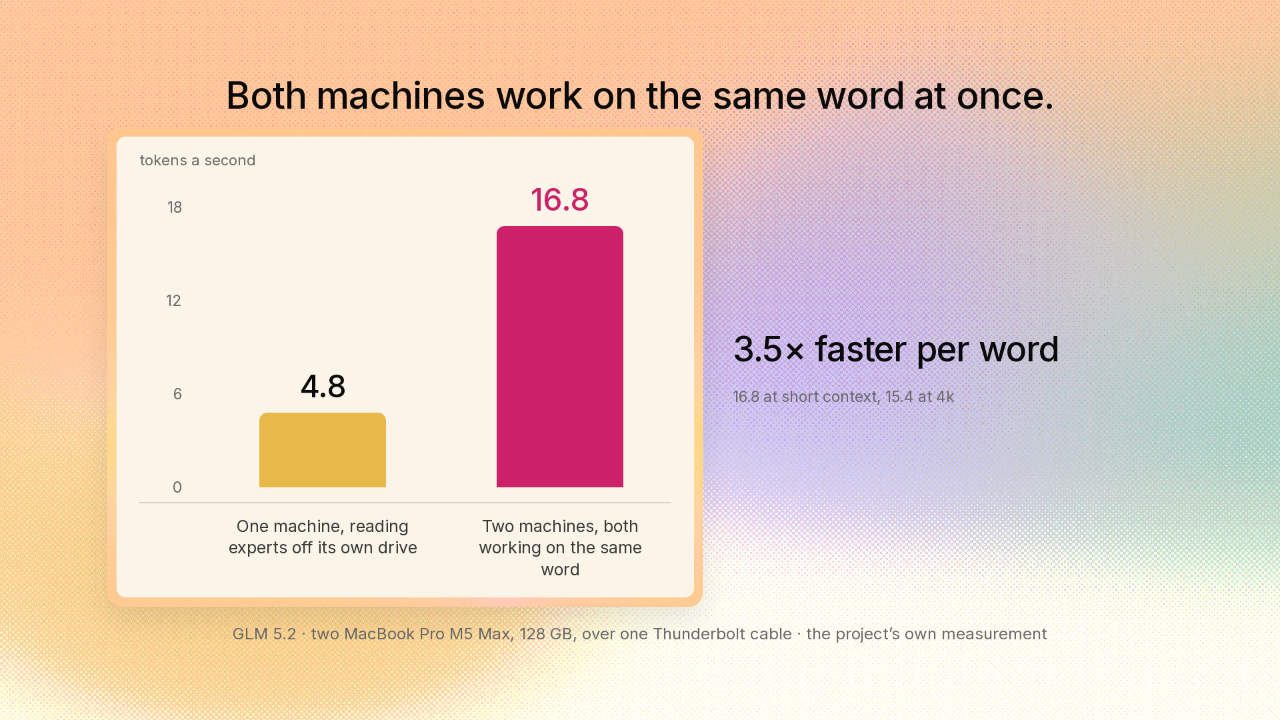
There is a second way to split, and here both machines work on the same word at the same time. Each machine holds half the experts, and they trade tiny messages over one cable. Another model DwarfStar runs, called GLM five point two, went from about four point eight words a second on one machine to about sixteen point eight words a second across two. A second machine buys more than room for a bigger model. It buys a faster answer.
DeepSeek’s larger model runs on one desktop computer
DeepSeek’s larger model runs on one desktop computer.
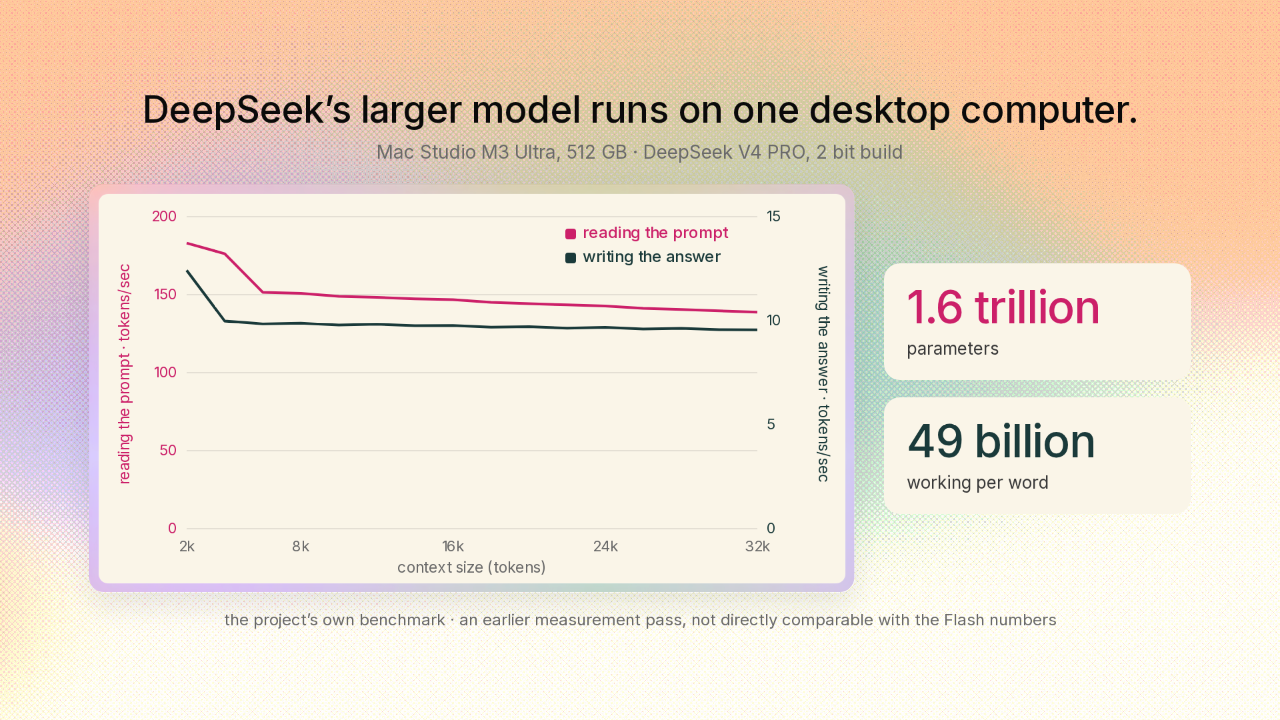
The same trick scales the other way. On a Mac Studio with five hundred and twelve gigabytes of memory, DwarfStar runs DeepSeek’s much bigger model. One point six trillion parameters, and about forty nine billion of them work on each word. Same engine, same idea, a bigger machine.
Free to build and run, on Apple, NVIDIA, and Strix Halo machines
Free to build and run, on Apple, NVIDIA, and Strix Halo machines.
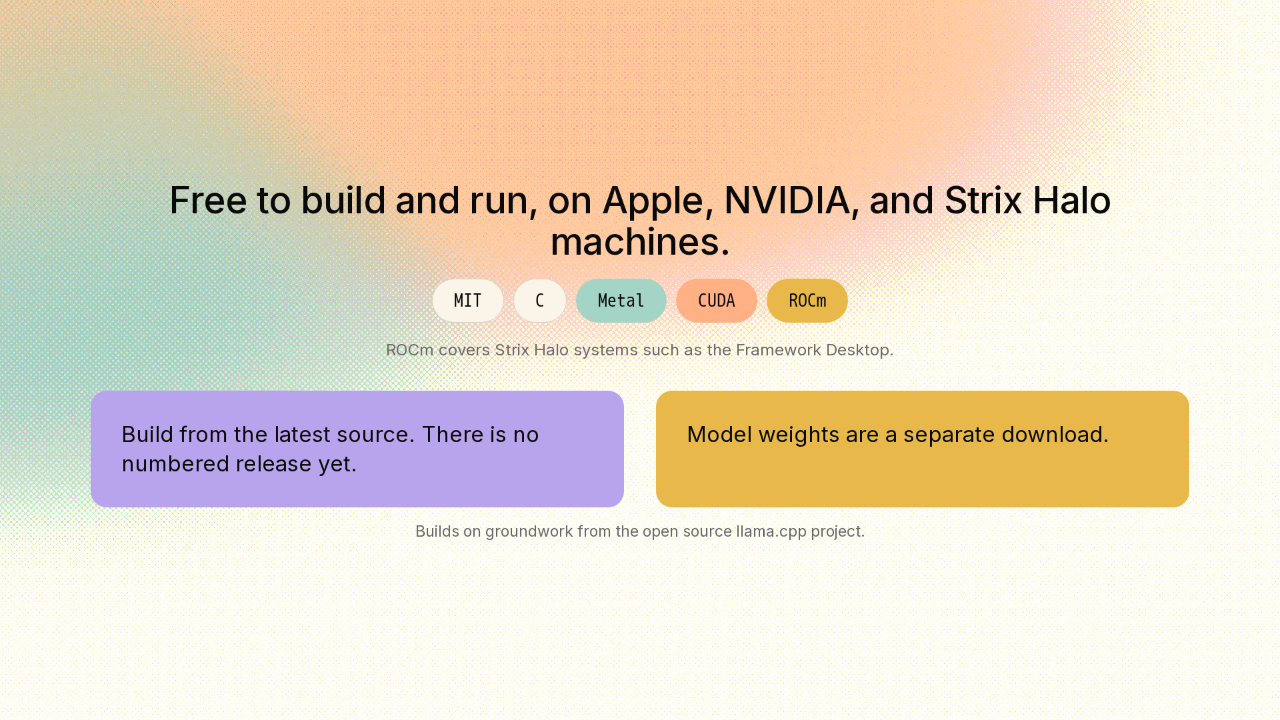
DwarfStar is one open codebase, free for anyone to use under the MIT license. It leans on the graphics chip inside Apple Macs, NVIDIA cards, and AMD’s Strix Halo desktops. The project is early and moving fast, so you build it from the latest code. The model files come as a separate download.
DwarfStar · a 284 billion parameter model on the machine on your desk

A 284 billion parameter model, on the machine on your desk.
Two hundred and eighty four billion parameters, on the machine on your desk. The frontier AI you have been renting can live on hardware you own, because a model that size is mostly idle experts you can crush, stream, or split. The link is on screen, and there is a new repo here tomorrow.