Four words, six pieces
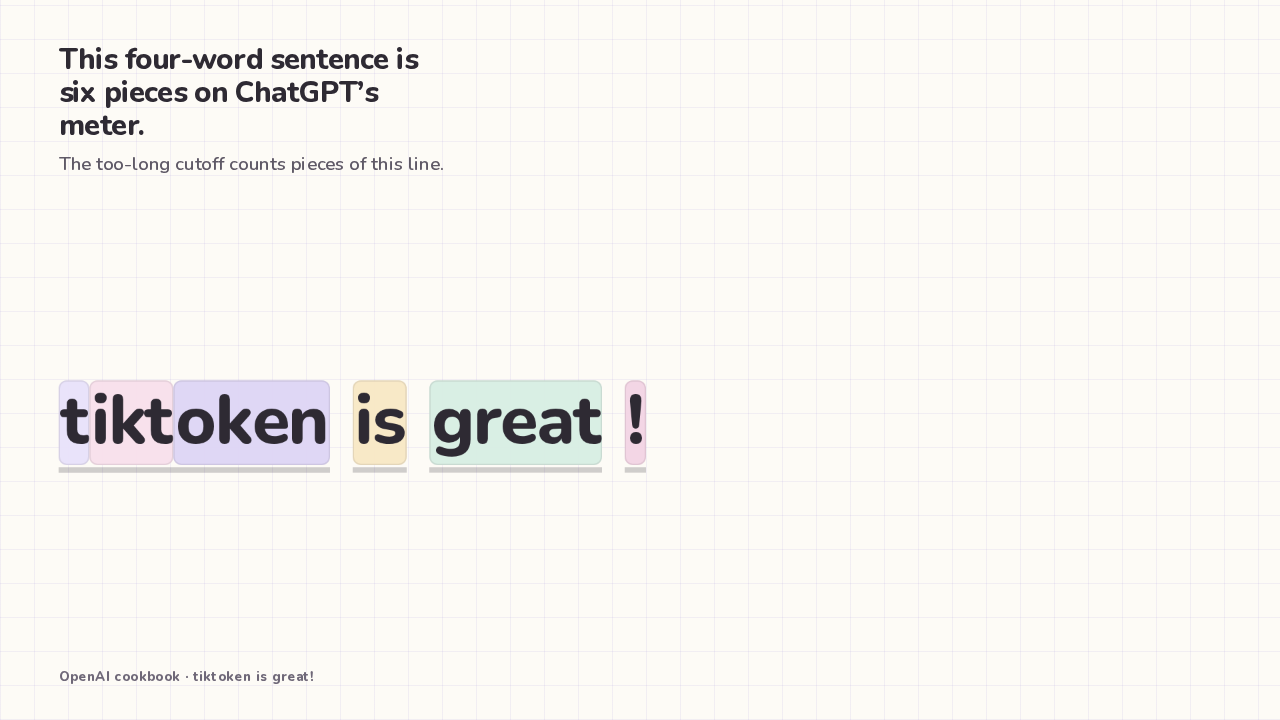
This four-word sentence is six pieces on ChatGPT’s meter.
The too-long cutoff counts pieces of this line.
Four words sit on the page. ChatGPT still meters six pieces. You have hit this wall. A short message trips a too-long cutoff. The cutoff is counting pieces of the line.
Six colored pieces
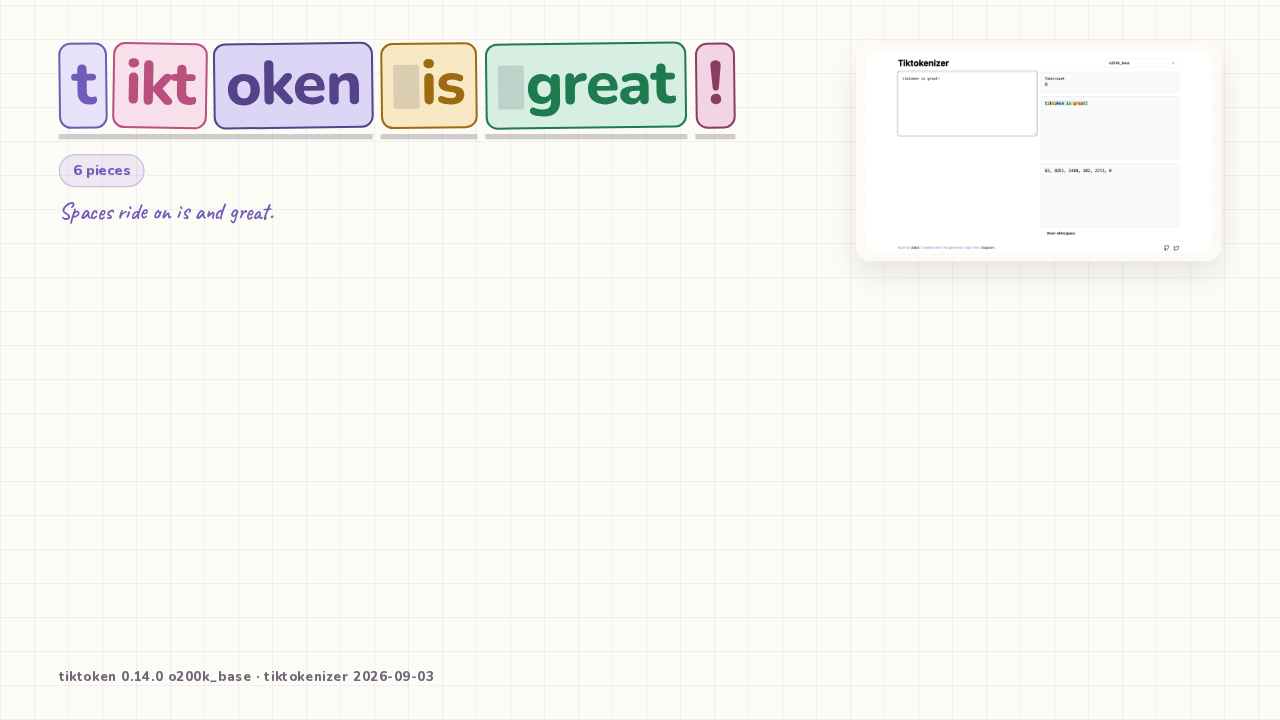
Spaces ride on is and great.

The cutter is called tiktoken. Tiktoken is OpenAI's cutter. Tiktoken turns this text into pieces before the model starts. Word-underlines sit under tiktoken, is, great, and the bang. The real cuts land inside the word tiktoken. Three pieces for one word. The space before is rides on the next piece. The space before great rides on the next piece too. The meter for this line is six pieces.
A necklace of numbered beads
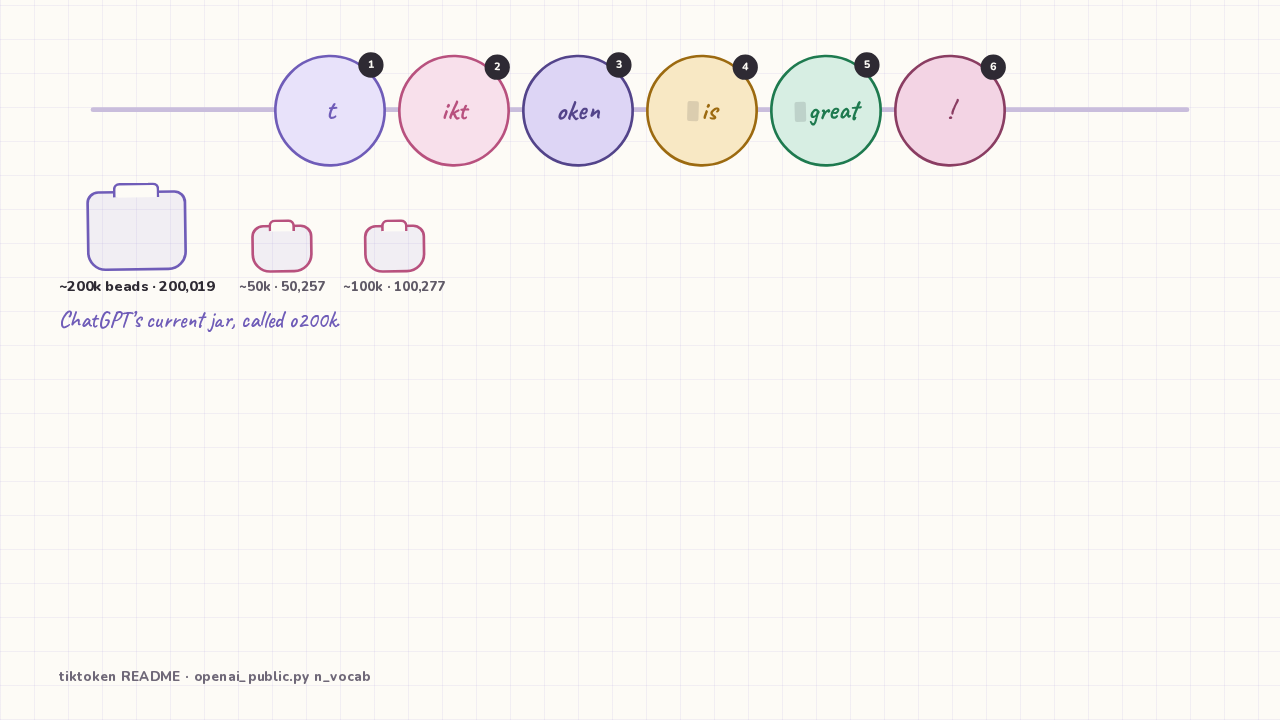
ChatGPT’s current jar, called o200k.
Spoken English is a string of letters. A cutter called tiktoken snips that string into colored beads. Each bead is a token. A token is a numbered bead from a finite jar. This gpt-4o jar is called o200k. gpt-4o is a current ChatGPT model. The jar holds about two hundred thousand beads. Older jars hold about fifty thousand beads, or about a hundred thousand. Common clumps already sit in the jar as one bead. The English ending ing is often one bead. Rare clumps get snipped smaller. A clump can fall to a single byte when the jar has no bigger bead. A byte is the smallest chunk of computer text. The model only ever sees the bead numbers. Byte pair encoding is the glue rule. The glue rule makes those numbers. OpenAI's own README says the glue rule is reversible. Glue the beads back. The original letters return. In English-heavy practice, each bead covers about four bytes of text. A 2016 paper by Sennrich, Haddow, and Birch taught the glue rule.
Letters plus an end-of-word mark
The glue rule starts with letters plus an end-of-word mark.
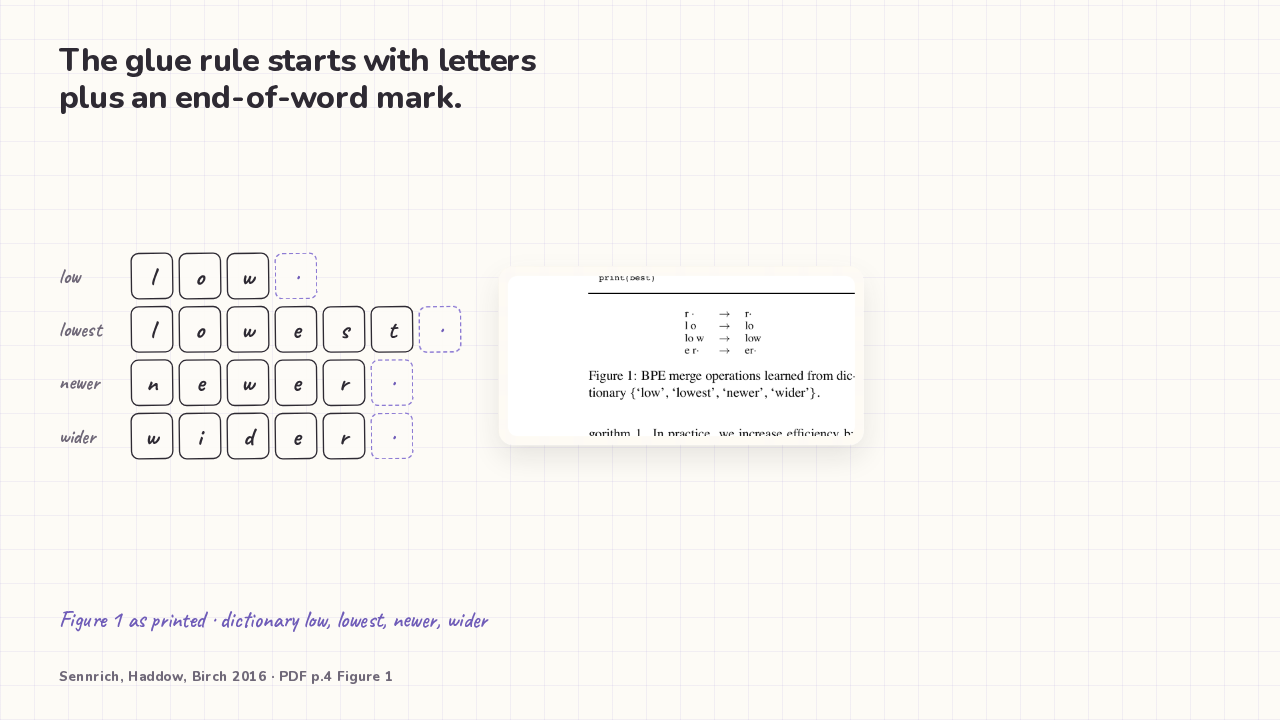
Figure 1 as printed · dictionary low, lowest, newer, wider
Byte pair encoding starts with letters. The printed figure adds an end-of-word mark on each word. That mark is the little dot. The toy list is four words: low, lowest, newer, and wider. The letters of low sit as l, o, w, and a dot. Lowest sits as l, o, w, e, s, t, and a dot. Newer sits as n, e, w, e, r, and a dot. Wider sits as w, i, d, e, r, and a dot. Every letter stays on the board. The glues land on top.
Glue the most common pair
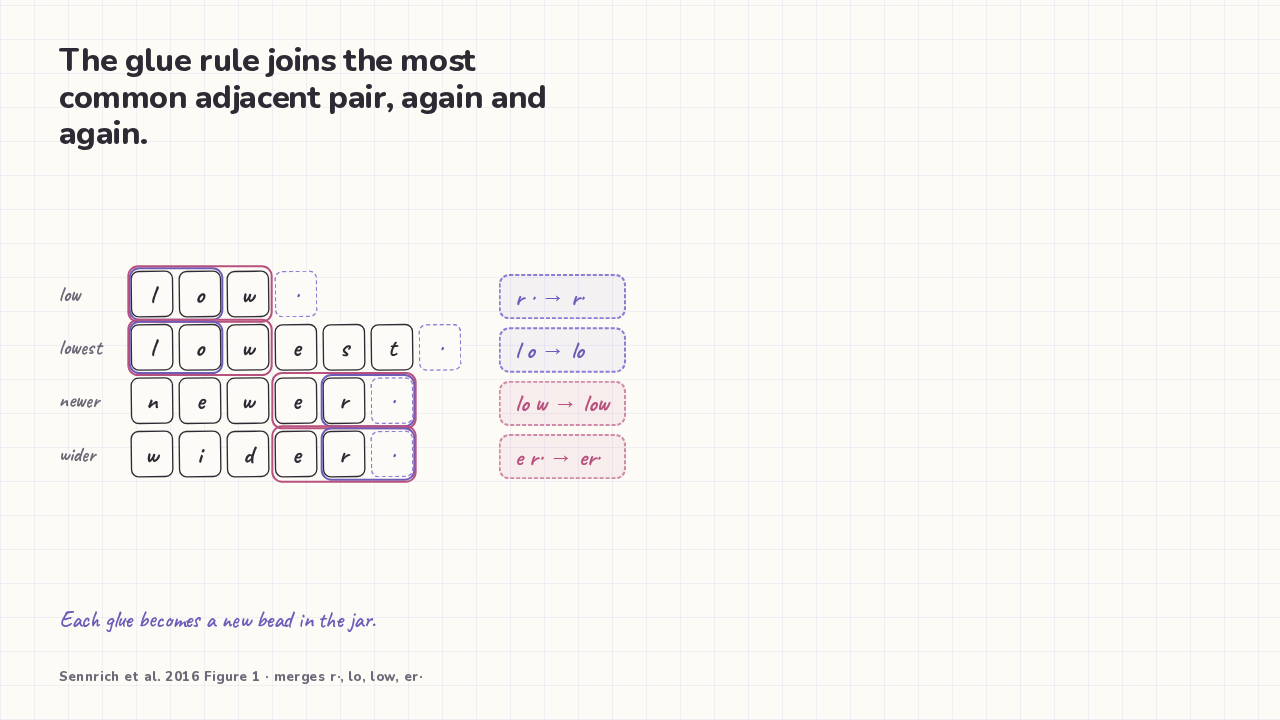
The glue rule joins the most common adjacent pair, again and again.
Each glue becomes a new bead in the jar.
The cutter counts every adjacent pair on this board. The most common pair becomes a new bead. That bead replaces every copy of the pair. On this printed figure, r and the end-dot glue first. Newer and wider both end in r-dot, so r-dot becomes a bead. Then l and o glue into lo. Low and lowest both start with lo. Then lo and w glue into low. Now low is a bead of its own. Then e and the r-dot glue into er-dot. Each new bead goes in the jar. The only knob is how many glues you allow. The paper stops adding beads when that merge count is reached.
An unseen word still reads
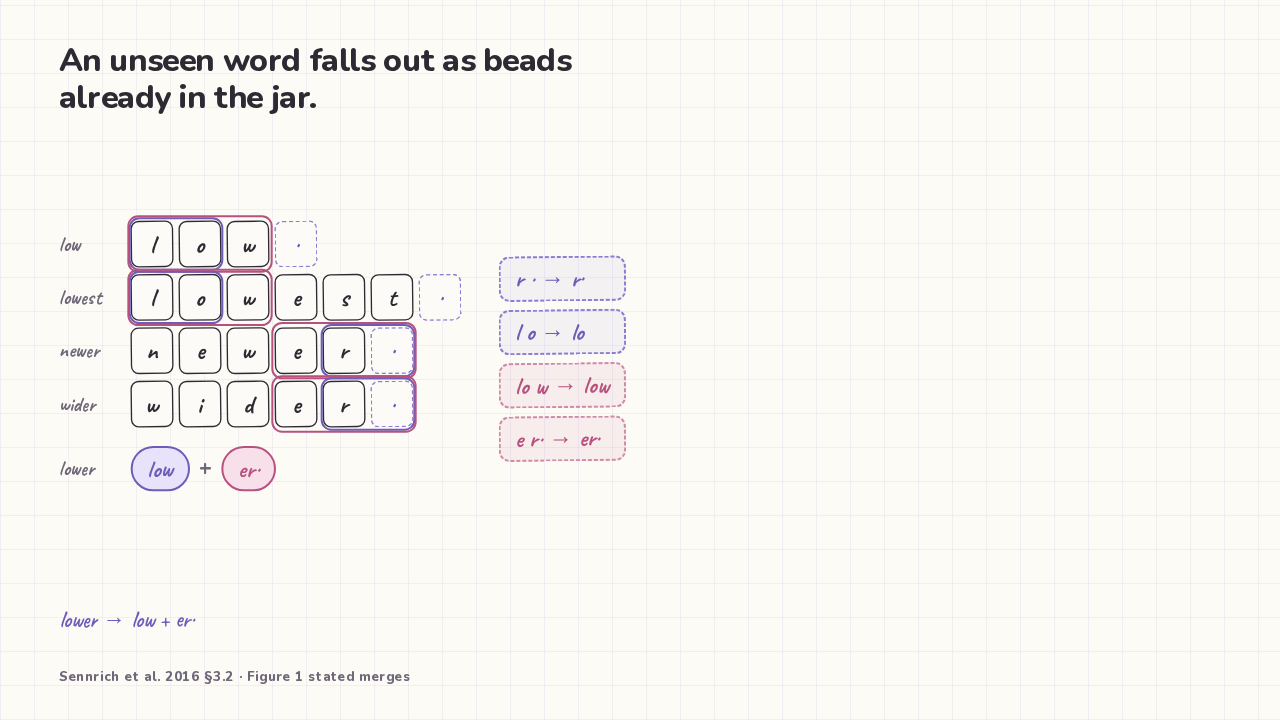
An unseen word falls out as beads already in the jar.
lower → low + er·
The word lower never sat in the toy list. The cutter still reads lower. The letters of lower are l, o, w, e, r, and a dot. The cutter already owns the bead low. The cutter already owns the bead er-dot. Lower falls out as those two beads. A closed jar covers words it has never stored. A finite list of beads still reads an open language.
tiktoken is three beads
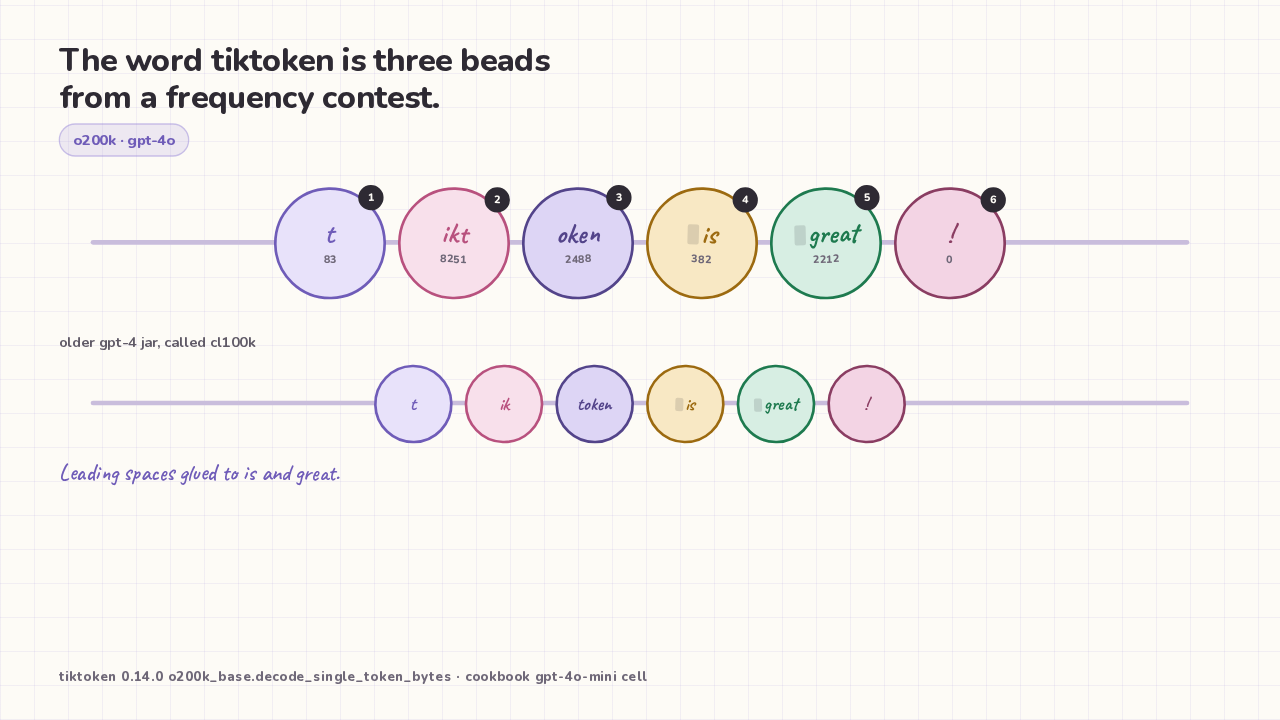
The word tiktoken is three beads from a frequency contest.
Leading spaces glued to is and great.
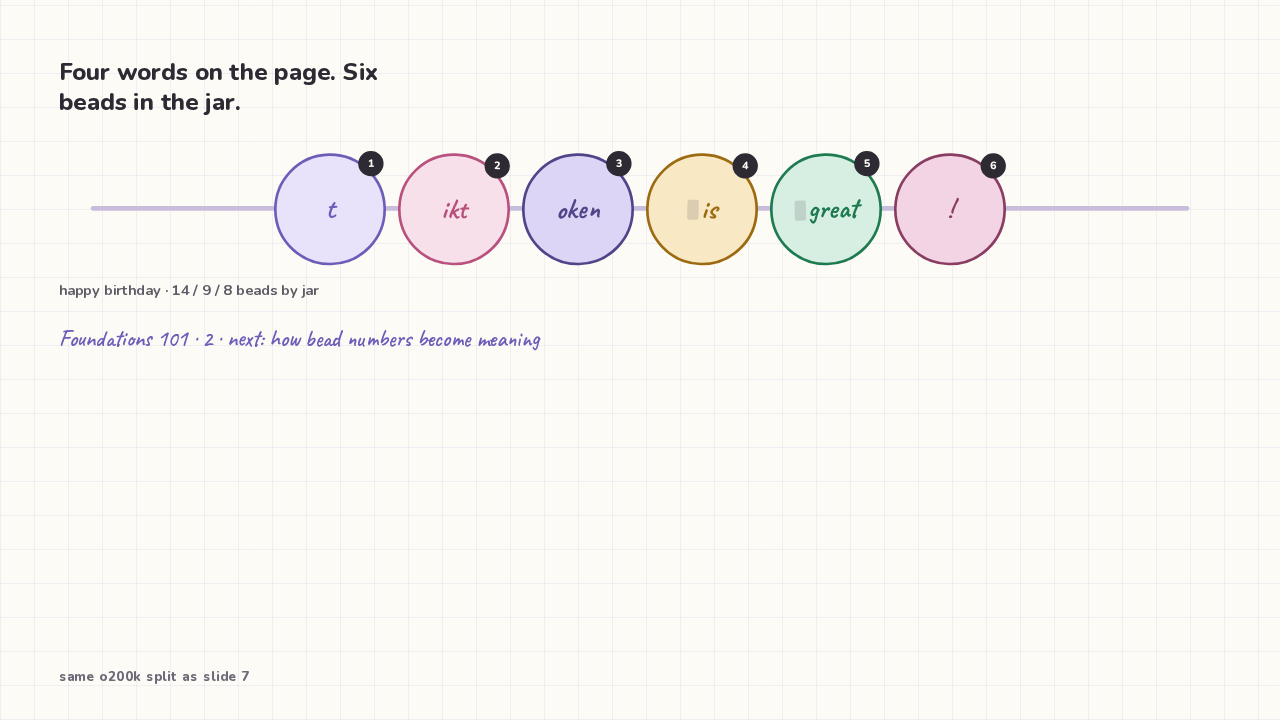
On this four-word sentence, the gpt-4o jar cuts the word tiktoken into three beads: t, ikt, and oken. Those pairs won the frequency contest. The space-is pair won too. So is carries its leading space as one bead. Great carries its leading space as one bead. The bang is its own bead. The meter for this line is six beads. The older gpt-4 jar, called cl100k, also bills six beads. gpt-4 is an older ChatGPT model. That older jar cuts tiktoken as t, ik, and token. Same count of six beads. Different beads.
A different jar, a different snip
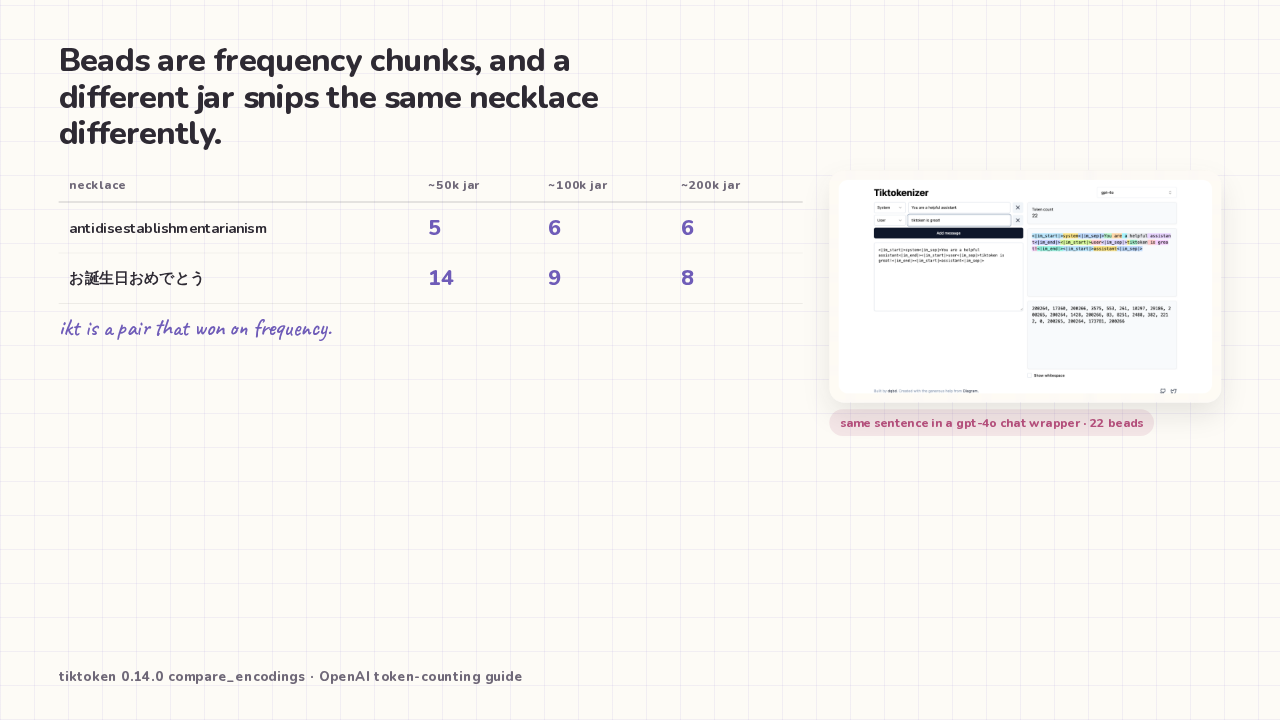
Beads are frequency chunks, and a different jar snips the same necklace differently.
| necklace | ~50k jar | ~100k jar | ~200k jar |
|---|---|---|---|
| antidisestablishmentarianism | 5 | 6 | 6 |
| お誕生日おめでとう | 14 | 9 | 8 |
ikt is a pair that won on frequency.

This picture is roughly right. Here is where the picture breaks. Ikt is a bead. That byte pair showed up often in the text used to fill the jar. Beads are frequency chunks. The same long English word, antidisestablishmentarianism, is five beads on the older fifty-thousand-bead jar. That word is six beads on the newer jars. The Japanese line for happy birthday is fourteen beads on the old jar. That same greeting is nine beads on the hundred-thousand-bead jar. That same greeting is eight beads on the newest jar. The README's about-four-bytes-per-token figure is English-heavy practice. The chat request also counts beads you never typed. Role markers, tool lists, and image tiles add beads. Role markers are labels like user and assistant that wrap a chat. The same six-piece sentence inside a gpt-4o chat wrapper bills twenty-two beads. Local tiktoken on the visible string misses those extras.
Four words. Six beads.
happy birthday · 14 / 9 / 8 beads by jar
Foundations 101 · 2 · next: how bead numbers become meaning
Four words sit on the page. tiktoken is great. The cutter snips that letter-string into numbered beads from a finite jar. Under the gpt-4o jar the necklace is six beads. The first three beads are t, ikt, and oken. The next bead is the word is, with its leading space. The next bead is the word great, with its leading space. The last bead is the bang. The snips come from a frequency contest. An unseen word falls out as beads already in the jar. The meter counts beads. The meter also counts beads you did not type. A different jar snips the same necklace differently. A Japanese birthday line can bill more beads than an English line of the same meaning. How those bead numbers become meaning is the next Foundations lesson.