SmallestLLMService

New in src/pipecat/services/smallest/llm.py
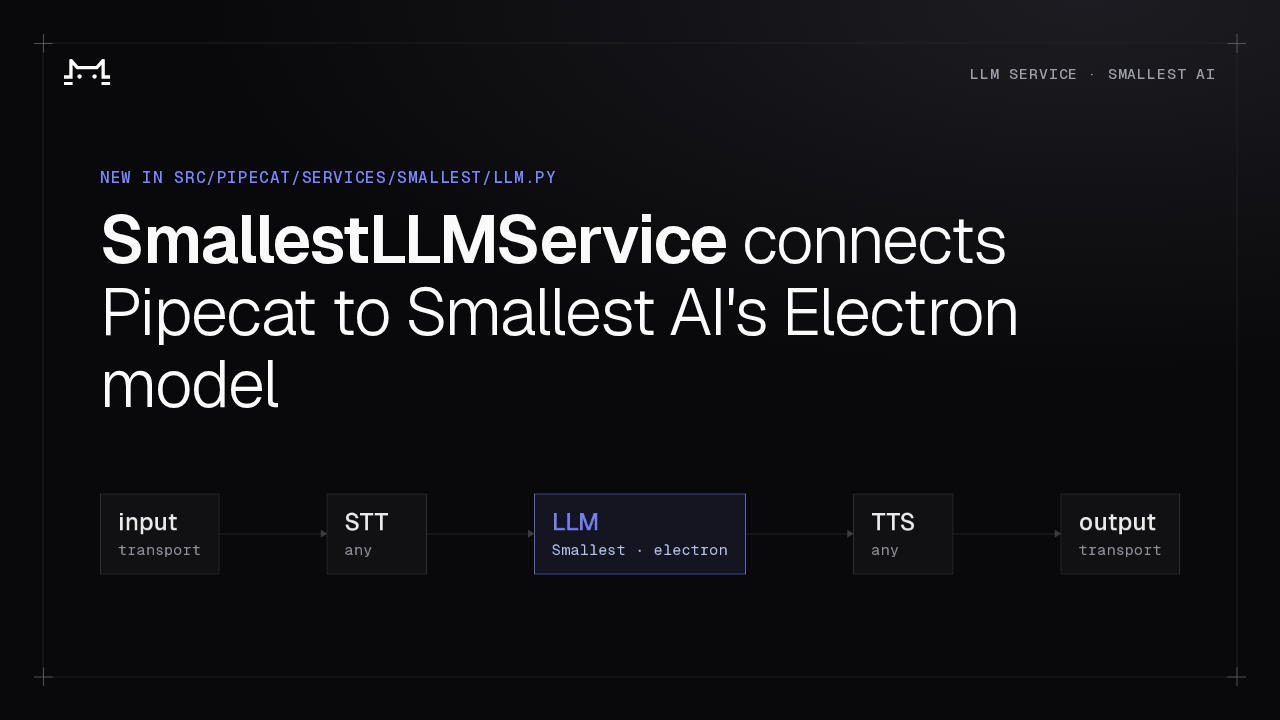
SmallestLLMService connects Pipecat to Smallest AI's Electron model
Pipecat has a new LLM service. SmallestLLMService connects a pipeline to Electron, Smallest AI's language model, through the OpenAI-compatible chat completions endpoint of the Waves API. It sits in the LLM slot like any other service, and electron is its default model.
A full Smallest stack
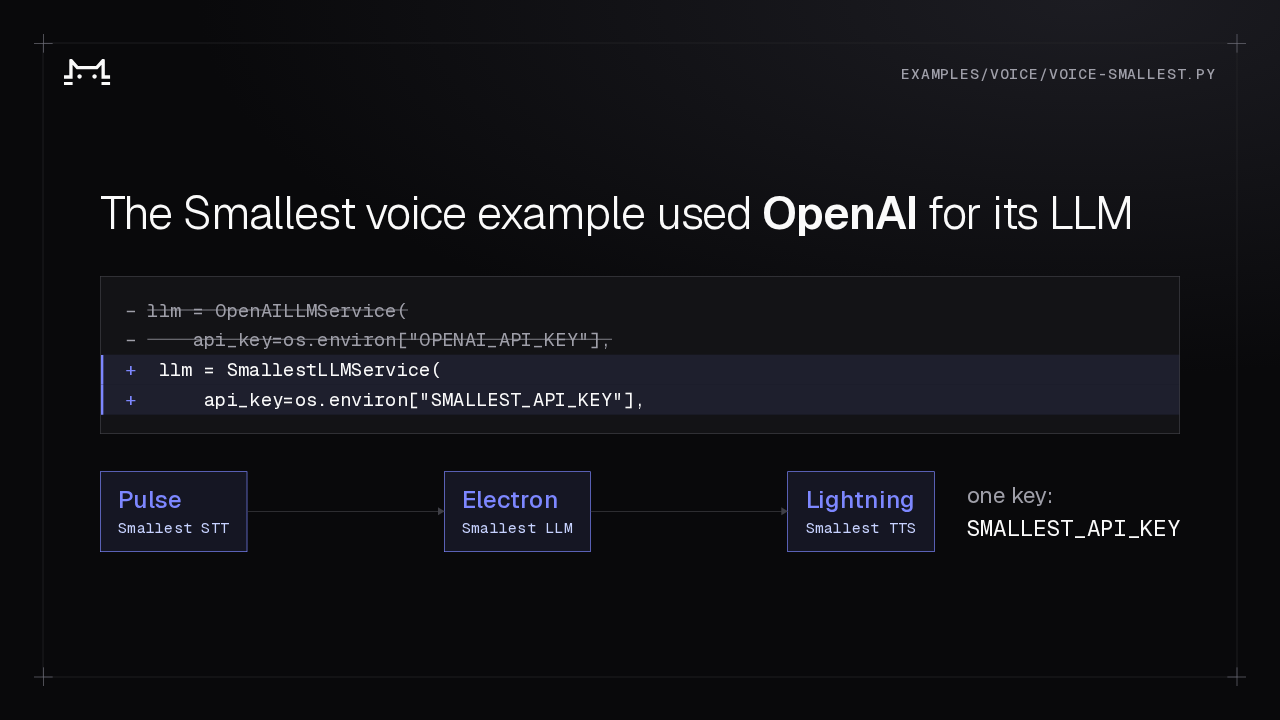
The Smallest voice example used OpenAI for its LLM
SMALLEST_API_KEY
Until now, the Smallest voice example used Smallest for speech-to-text and text-to-speech, and borrowed OpenAI for the language model, with a second API key. This pull request swaps that one service. The example now demonstrates a full Smallest AI stack: Pulse for speech-to-text, Electron for the LLM, and Lightning for text-to-speech, all on one Smallest API key.
A thin subclass
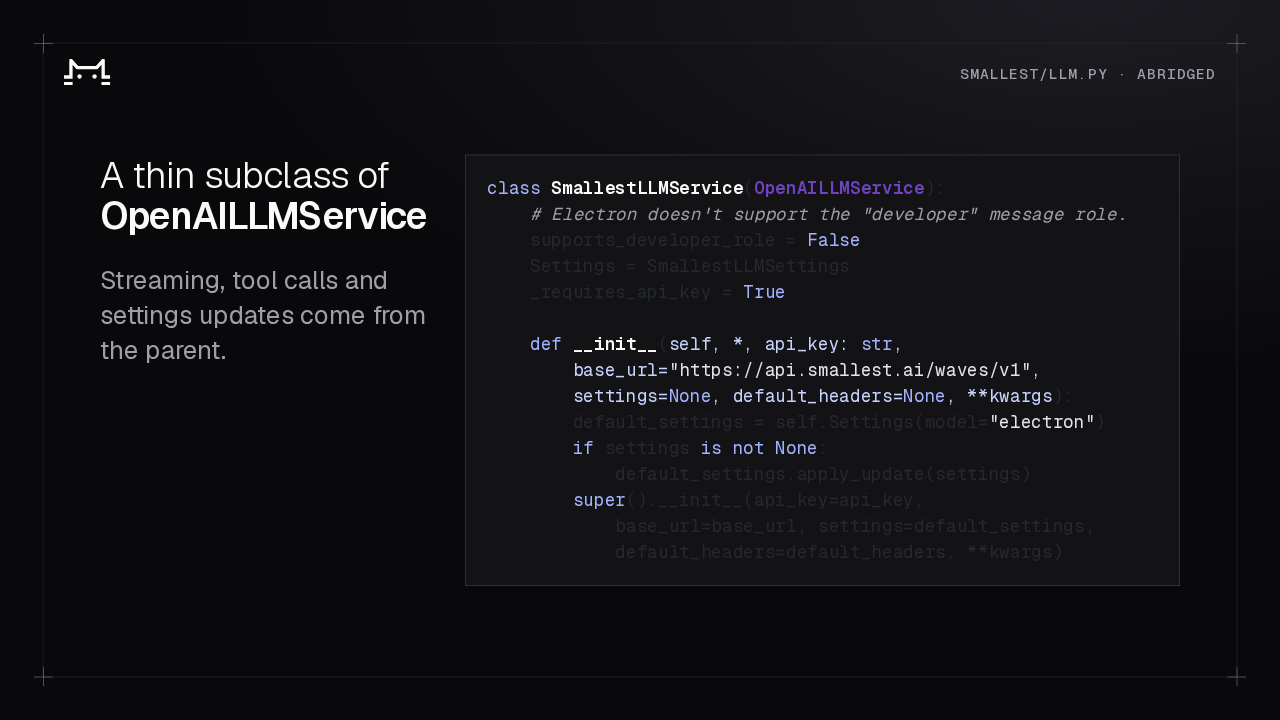
A thin subclass of OpenAILLMService
Streaming, tool calls and settings updates come from the parent.
class SmallestLLMService(OpenAILLMService):
    # Electron doesn't support the "developer" message role.
    supports_developer_role = False
    Settings = SmallestLLMSettings
    _requires_api_key = True

    def __init__(self, *, api_key: str,
        base_url="https://api.smallest.ai/waves/v1",
        settings=None, default_headers=None, **kwargs):
        default_settings = self.Settings(model="electron")
        if settings is not None:
            default_settings.apply_update(settings)
        super().__init__(api_key=api_key,
            base_url=base_url, settings=default_settings,
            default_headers=default_headers, **kwargs)
The class extends OpenAILLMService, so streaming, tool calls, and settings updates come from the parent. The constructor defaults the base URL to the Waves API. It starts from settings with the model set to electron, then applies whatever the caller passed on top. Everything else is inherited.
Developer messages become user messages
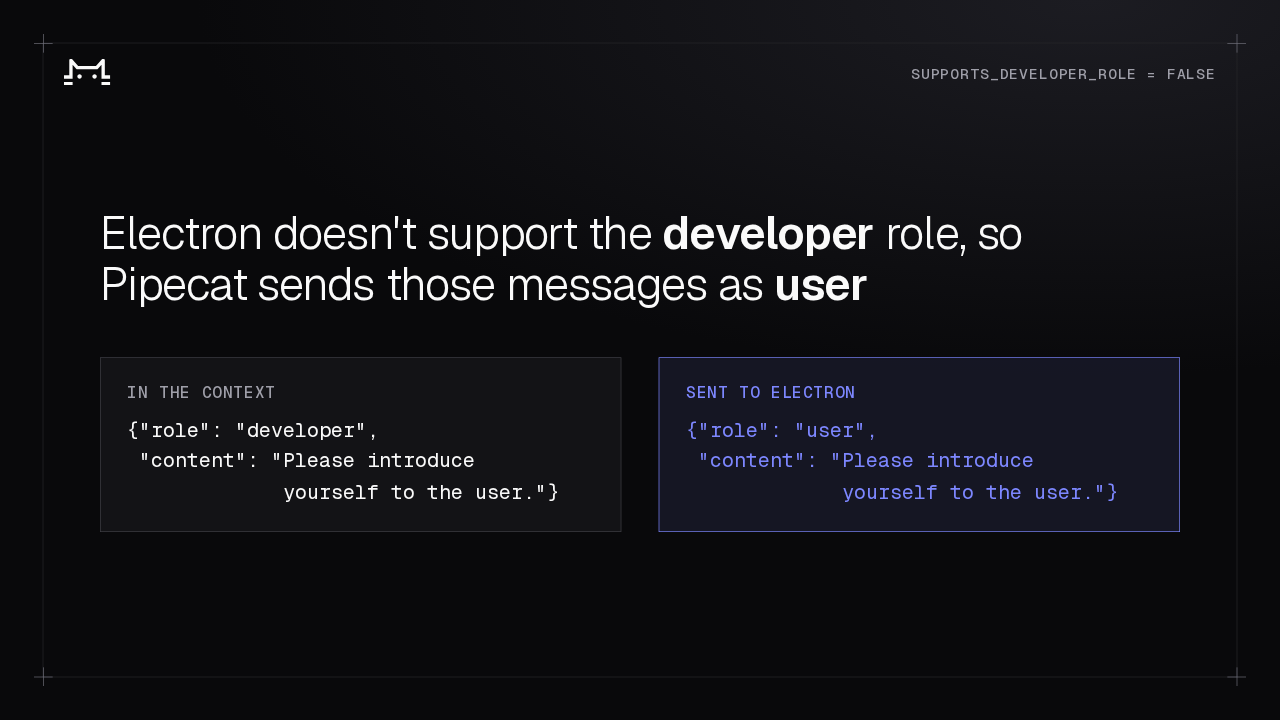
Electron doesn't support the developer role, so Pipecat sends those messages as user
In the context
Sent to Electron
Electron doesn't support the developer message role, so the service sets supports developer role to False, and the OpenAI base service passes that flag to the adapter when it builds the request. Developer messages go out as user messages. The new examples open with a developer message asking the bot to introduce itself, so with Electron that kickoff arrives as a user turn. A unit test pins the conversion.
Every request names Pipecat
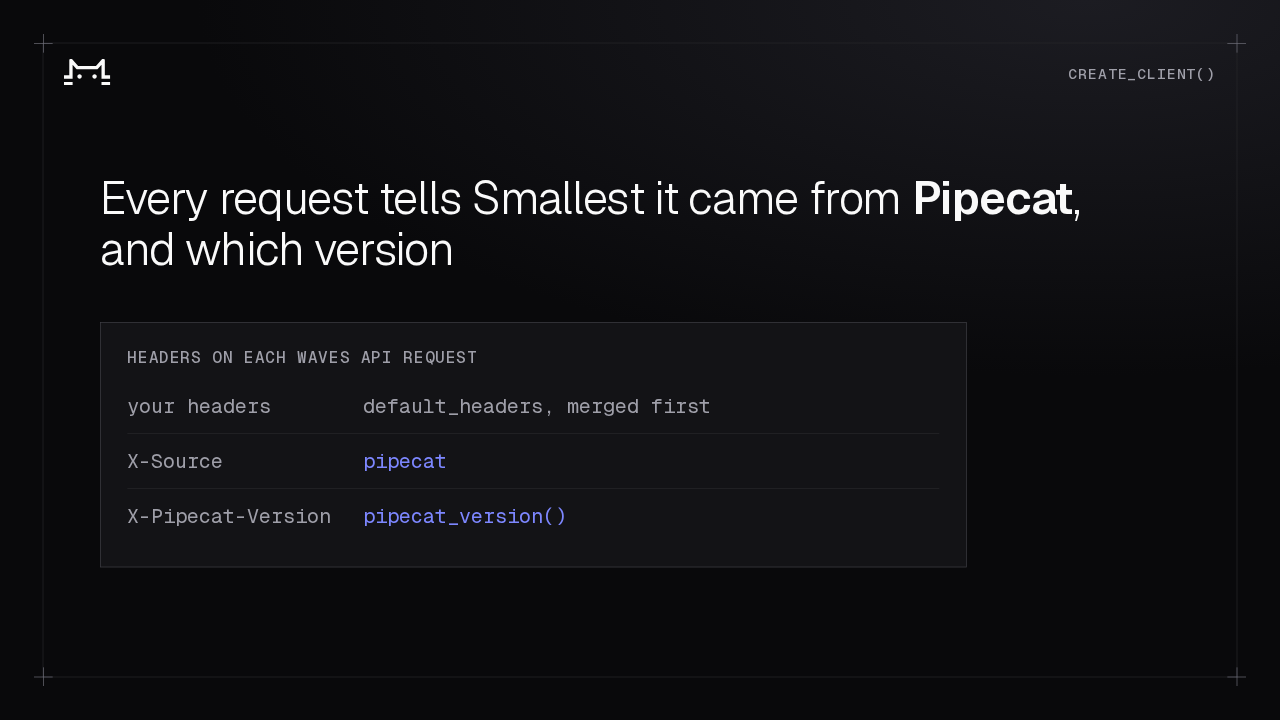
Every request tells Smallest it came from Pipecat, and which version
Headers on each Waves API request
Besides the constructor, the one method the class overrides is create client. It starts from any headers the caller passed in, then adds two of its own: X-Source, set to pipecat, and X-Pipecat-Version, set to the installed Pipecat version. They're applied last, so they always go out, even if a caller set the same names.
pipecat init offers Smallest
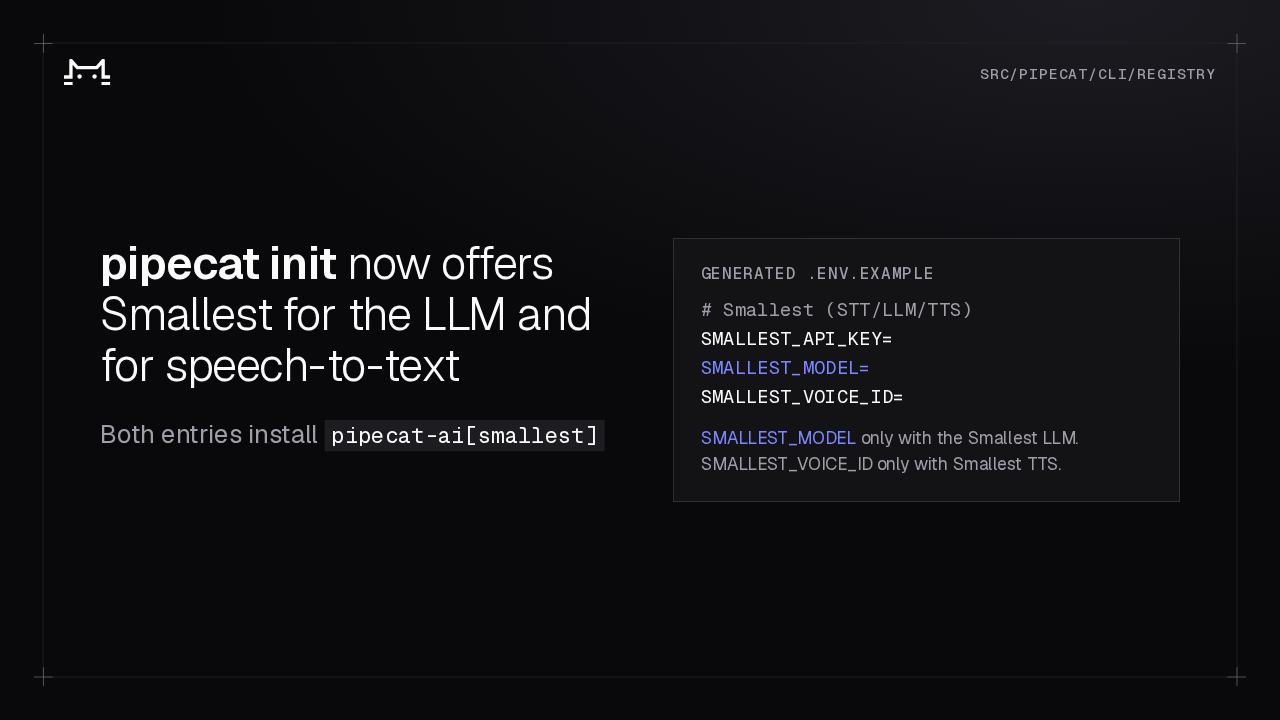
pipecat init now offers Smallest for the LLM and for speech-to-text
Both entries install pipecat-ai[smallest]
Generated .env.example
SMALLEST_MODEL only with the Smallest LLM.
SMALLEST_VOICE_ID only with Smallest TTS.
The CLI registry gains two entries. pipecat init offers Smallest as an LLM, and, also new here, as a speech-to-text service. The env template now writes one Smallest block whichever of the three services you pick: the API key every time, a model variable only when you choose the Smallest LLM, and the voice ID only with Smallest text-to-speech.
A spoken filler during tool calls
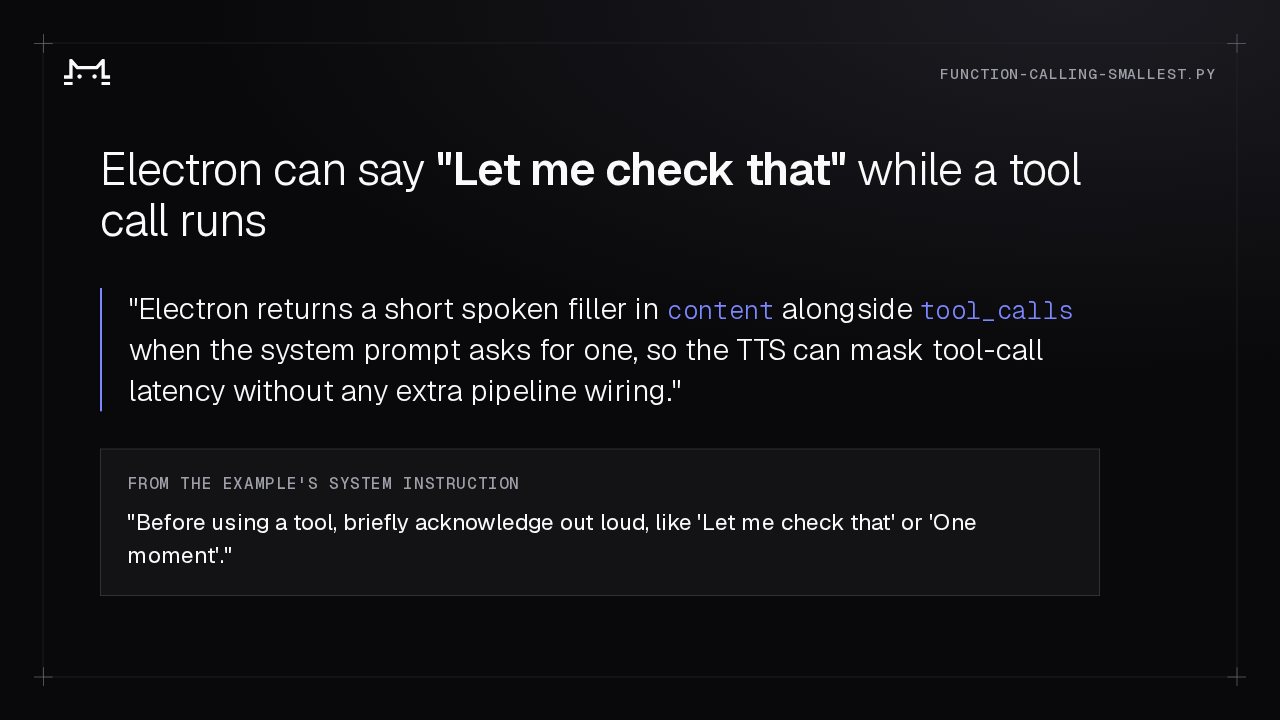
Electron can say "Let me check that" while a tool call runs
"Electron returns a short spoken filler in content alongside tool_calls when the system prompt asks for one, so the TTS can mask tool-call latency without any extra pipeline wiring."
From the example's system instruction
"Before using a tool, briefly acknowledge out loud, like 'Let me check that' or 'One moment'."
The new function-calling example relies on a behavior of Electron, explained in a comment there. When the system prompt asks for it, Electron returns a short spoken line in the content field alongside its tool calls. So the prompt tells the bot to say something like "let me check that" before using a tool. The text-to-speech service speaks it while the weather lookup runs, with no extra pipeline wiring.
Tests
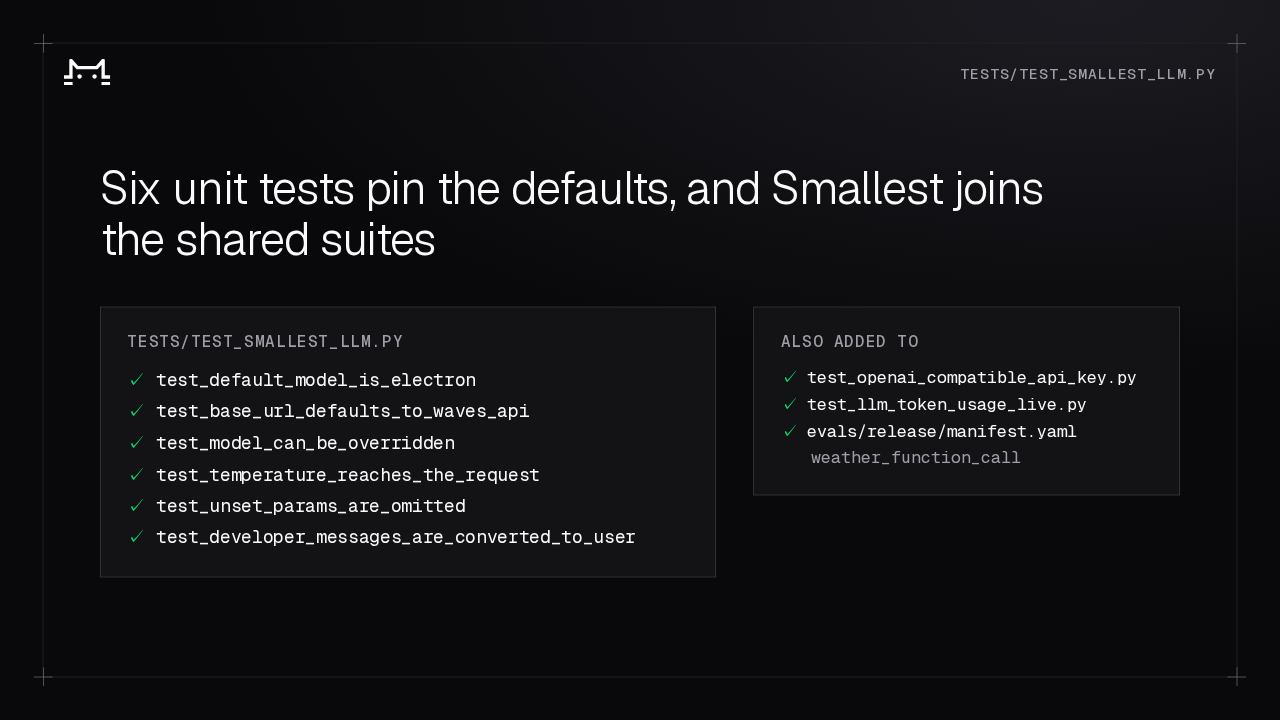
Six unit tests pin the defaults, and Smallest joins the shared suites
tests/test_smallest_llm.py
Also added to
weather_function_call
The new tests build the service with the client patched out and check the request it would send. Electron is the default model, the Waves API is the default base URL, a caller can override the model and the temperature, unset parameters stay off the wire, and developer messages become user messages. Smallest also joins the shared API key test, the live token usage test, and the release evals.
Evidence
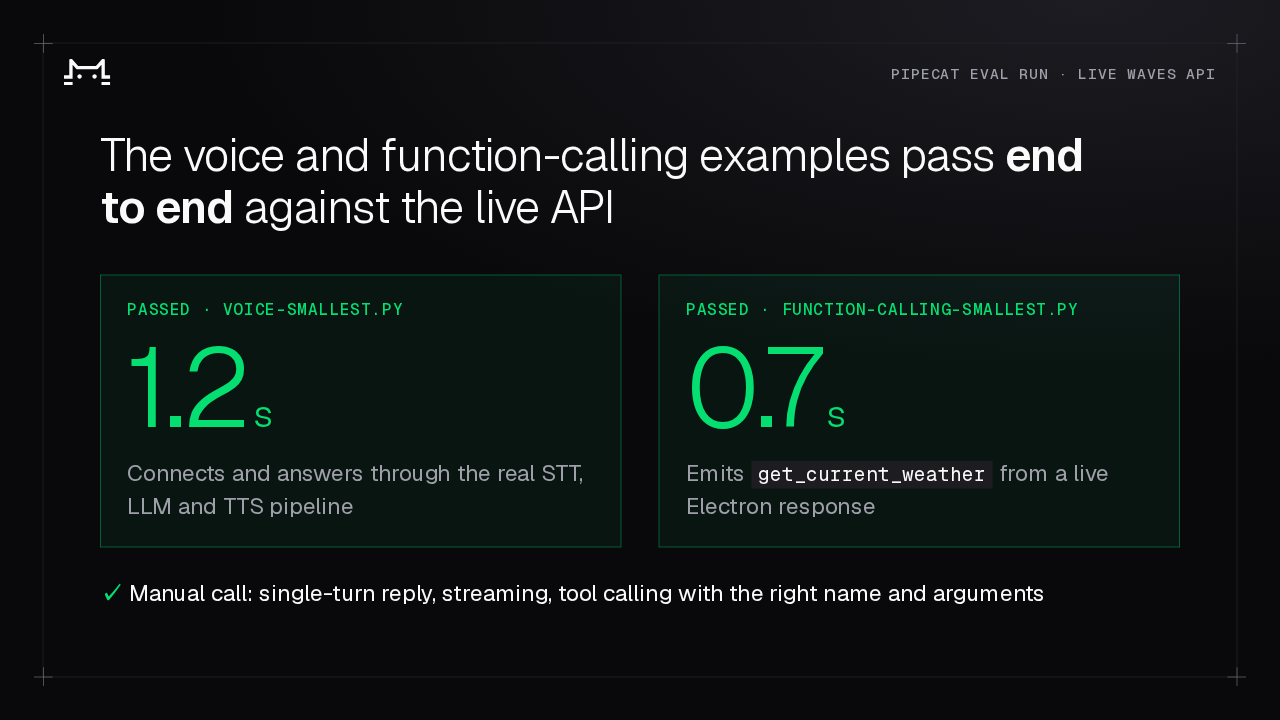
The voice and function-calling examples pass end to end against the live API
Passed · voice-smallest.py
Connects and answers through the real STT, LLM and TTS pipeline
Passed · function-calling-smallest.py
Emits get_current_weather from a live Electron response
✓ Manual call: single-turn reply, streaming, tool calling with the right name and arguments
Both examples ran through pipecat eval against the real API. The voice example connected and answered through the full speech-to-text, LLM, and text-to-speech pipeline, and passed in 1.2 seconds. The function-calling example got a get current weather call from a live Electron response, and passed in 0.7 seconds. A manual call also checked single-turn replies, streaming, and tool calling.
Try it
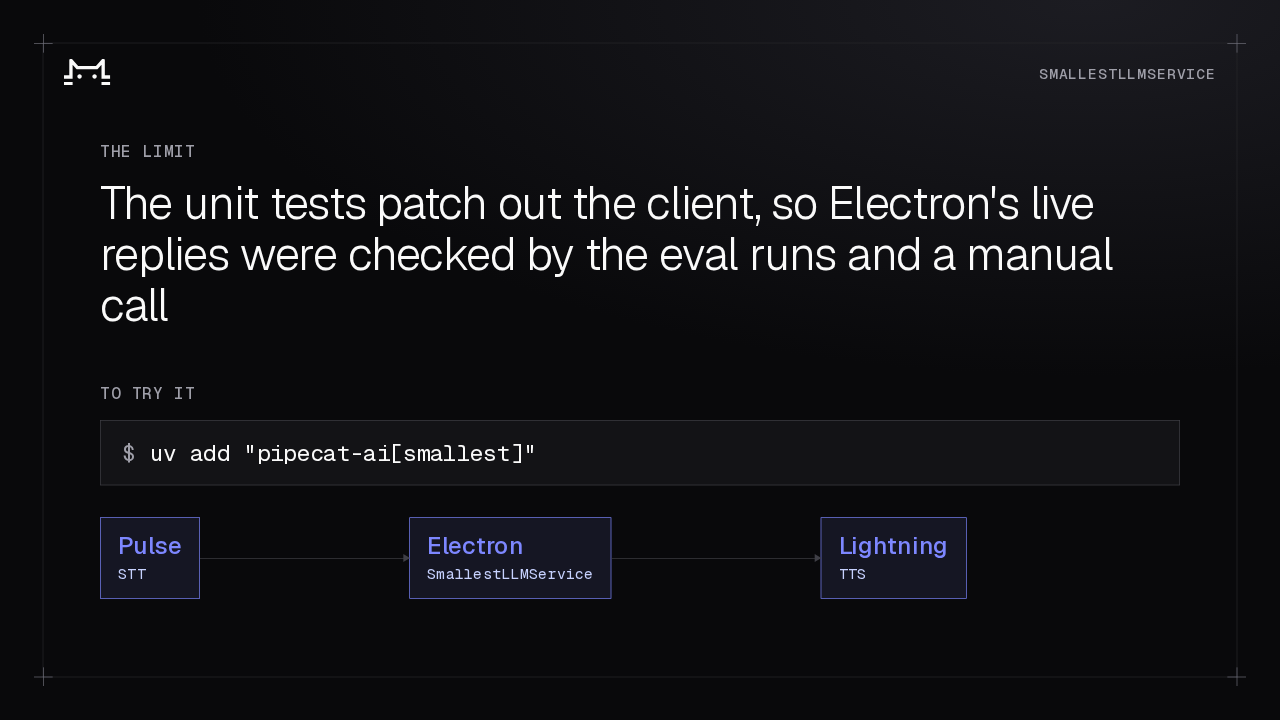
The limit
The unit tests patch out the client, so Electron's live replies were checked by the eval runs and a manual call
To try it
One limit to keep in mind. The unit tests patch out the client, so they check the request, not Electron's replies. Those were checked by the two eval runs and a manual call. To try it, install the smallest extra, set your Smallest API key, and put SmallestLLMService in the LLM slot. With Pulse and Lightning around it, a whole Pipecat pipeline now runs on Smallest AI.