Pipecat 1.14.0

Pipecat 1.14.0
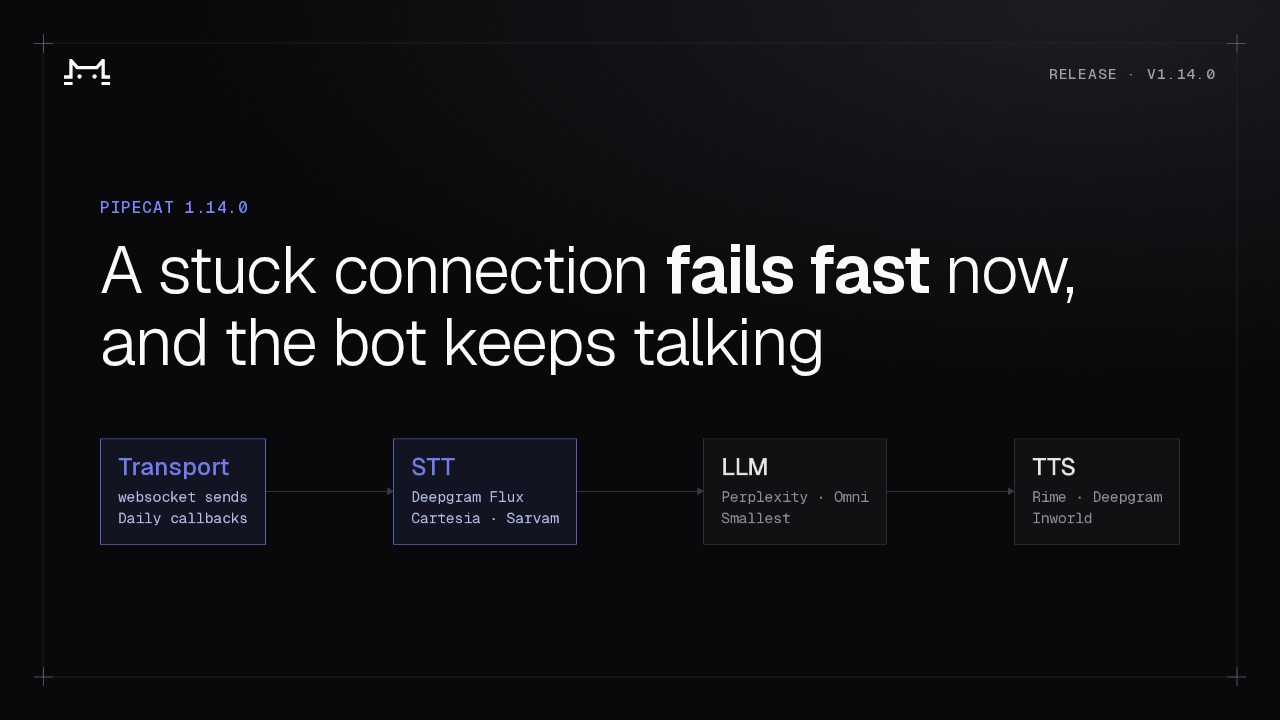
A stuck connection fails fast now, and the bot keeps talking
Daily callbacks
Cartesia · Sarvam
Smallest
Inworld
Pipecat 1.14.0 is mostly about connections that used to hang. A peer that stops reading or a session that drops mid-sentence could stall a bot. Now they fail fast, keep what the user said, and recover. There are new services too, and a short list of things to do before you upgrade.
Websocket sends time out
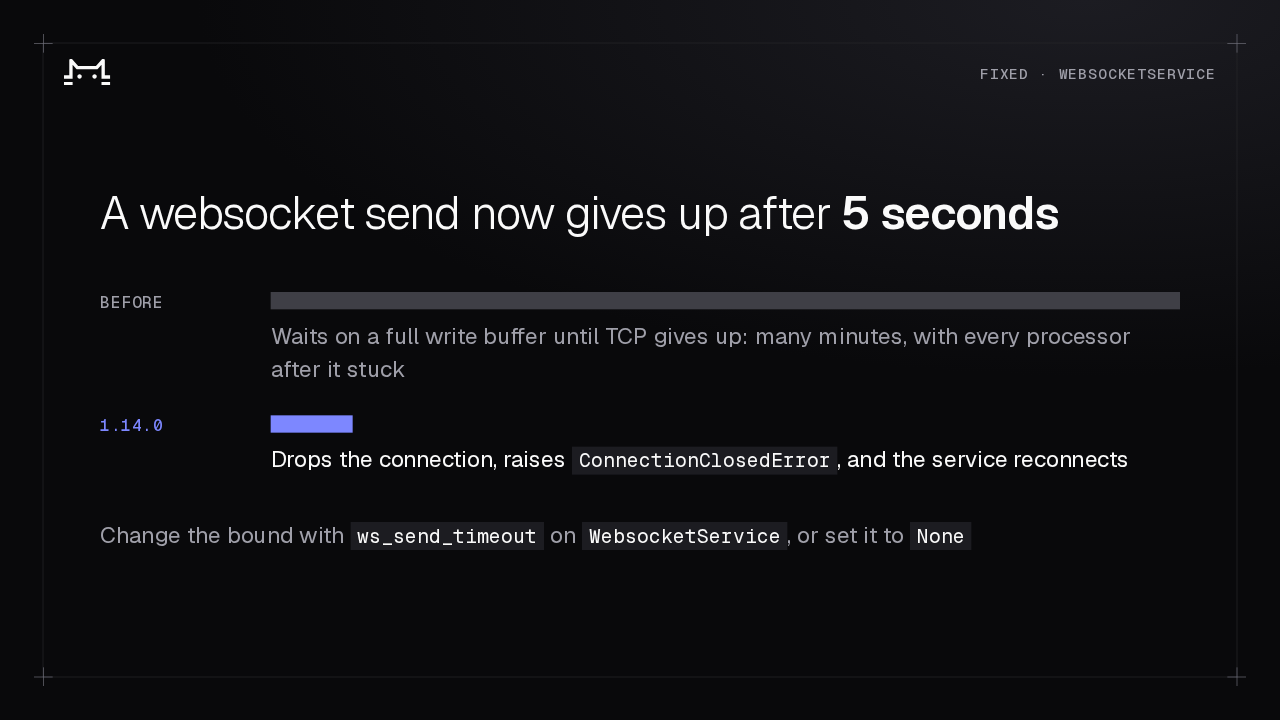
A websocket send now gives up after 5 seconds
Before
Waits on a full write buffer until TCP gives up: many minutes, with every processor after it stuck
1.14.0
Drops the connection, raises ConnectionClosedError, and the service reconnects
Change the bound with ws_send_timeout on WebsocketService, or set it to None
When a websocket peer stopped reading, a send could wait many minutes for TCP to give up while the whole pipeline behind it waited. Now each send is bounded at 5 seconds. One that runs over drops the connection, and the normal reconnect takes over. A send timeout setting on the websocket service changes the bound, and None turns it off.
Speech-to-text keeps the turn
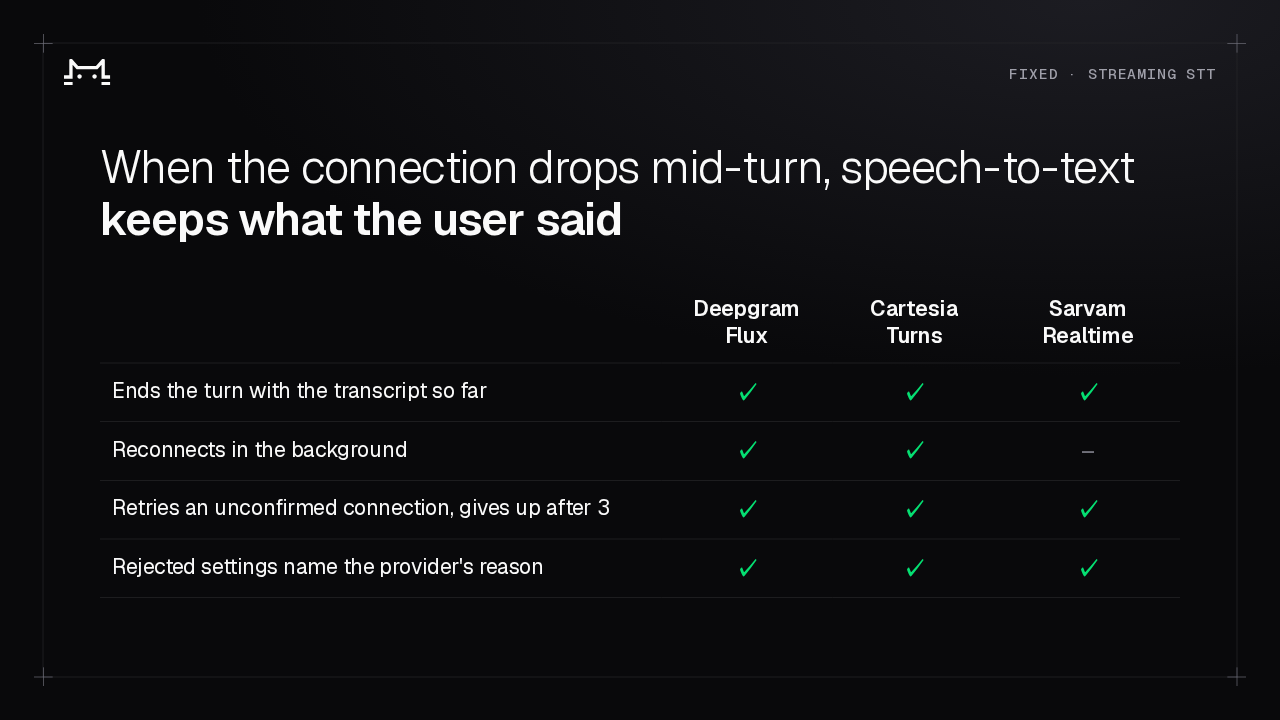
When the connection drops mid-turn, speech-to-text keeps what the user said
| Deepgram Flux | Cartesia Turns | Sarvam Realtime | |
|---|---|---|---|
| Ends the turn with the transcript so far | ✓ | ✓ | ✓ |
| Reconnects in the background | ✓ | ✓ | – |
| Retries an unconfirmed connection, gives up after 3 | ✓ | ✓ | ✓ |
| Rejected settings name the provider's reason | ✓ | ✓ | ✓ |
Deepgram Flux, Cartesia Turns, and Sarvam Realtime share a set of fixes. If the connection ends partway through a turn, the turn now ends with the transcript received so far. Flux and Cartesia Turns reconnect in the background, so audio keeps moving. A connection that opens but is never confirmed is retried, and the service gives up after three in a row. A rejected setting names the provider's reason.
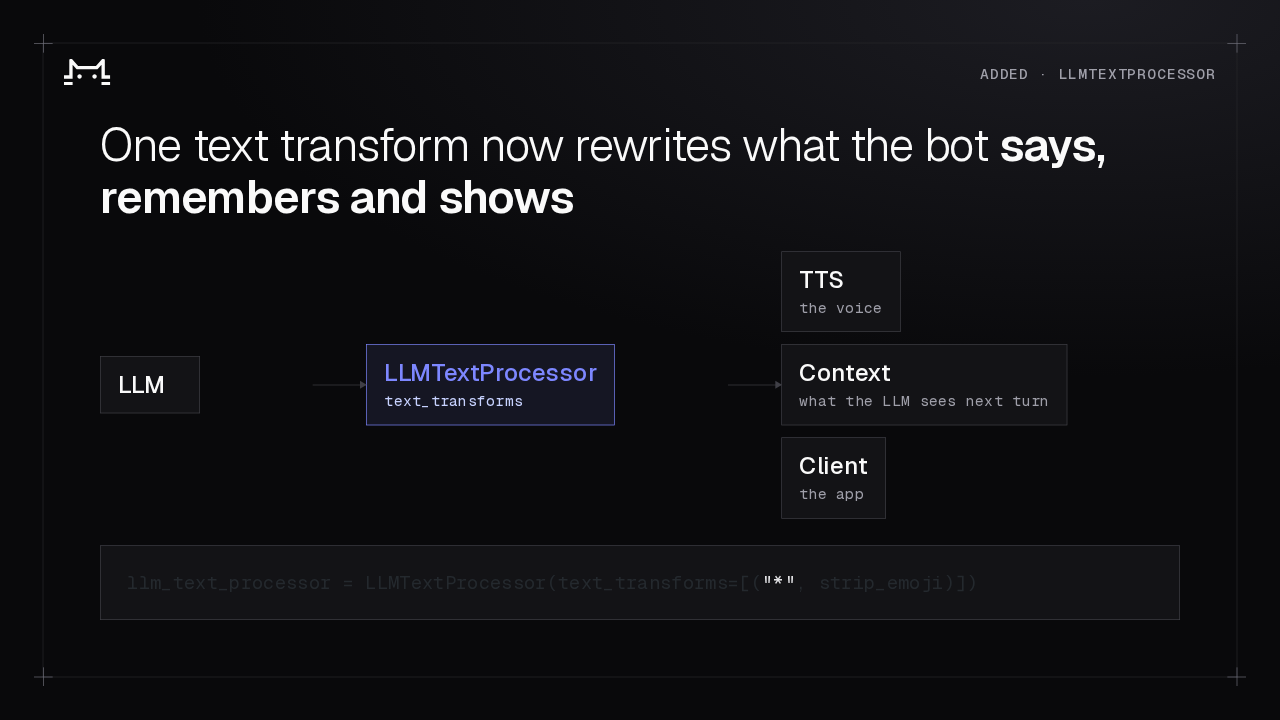
Text transforms on LLMTextProcessor
One text transform now rewrites what the bot says, remembers and shows
llm_text_processor = LLMTextProcessor(text_transforms=[("*", strip_emoji)])The LLM text processor now takes text transforms. In the updated example, one strips emoji right after the LLM. Because it runs before the text splits toward the voice, the context, and the client, the LLM never sees its own emoji, and stops adding more.
New services
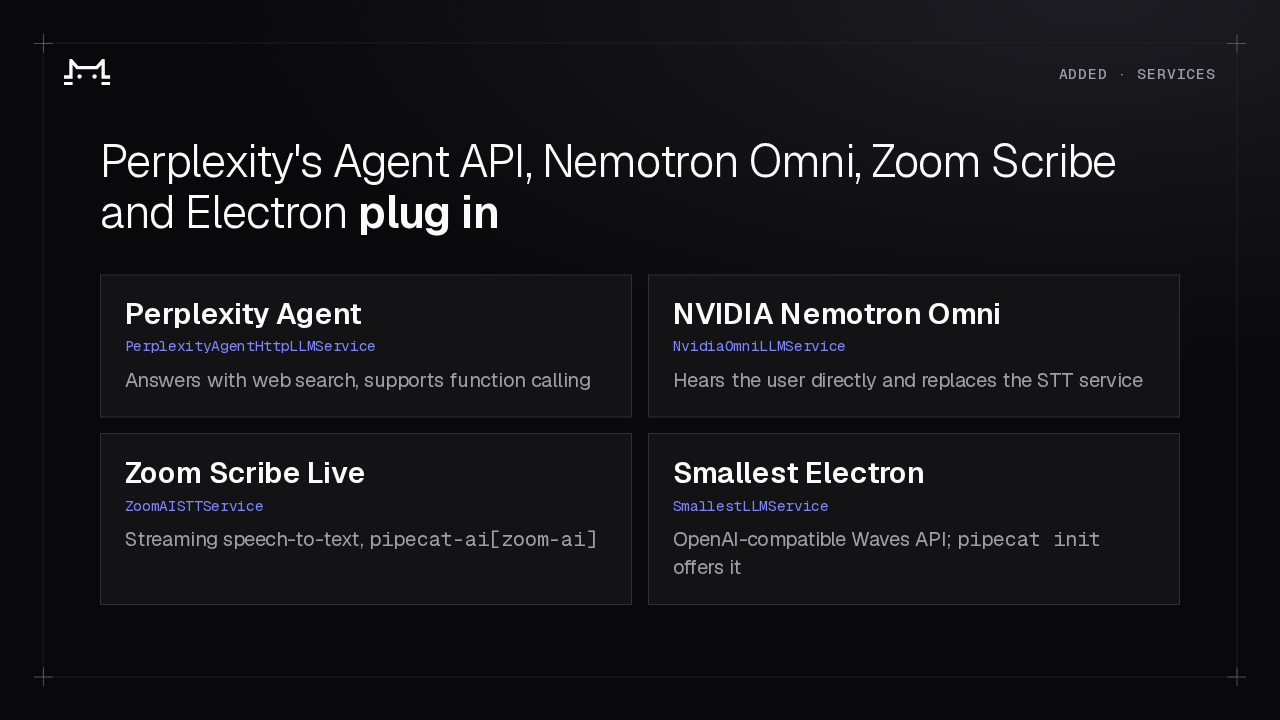
Perplexity's Agent API, Nemotron Omni, Zoom Scribe and Electron plug in
PerplexityAgentHttpLLMServiceAnswers with web search, supports function calling
NvidiaOmniLLMServiceHears the user directly and replaces the STT service
ZoomAISTTServiceStreaming speech-to-text, pipecat-ai[zoom-ai]
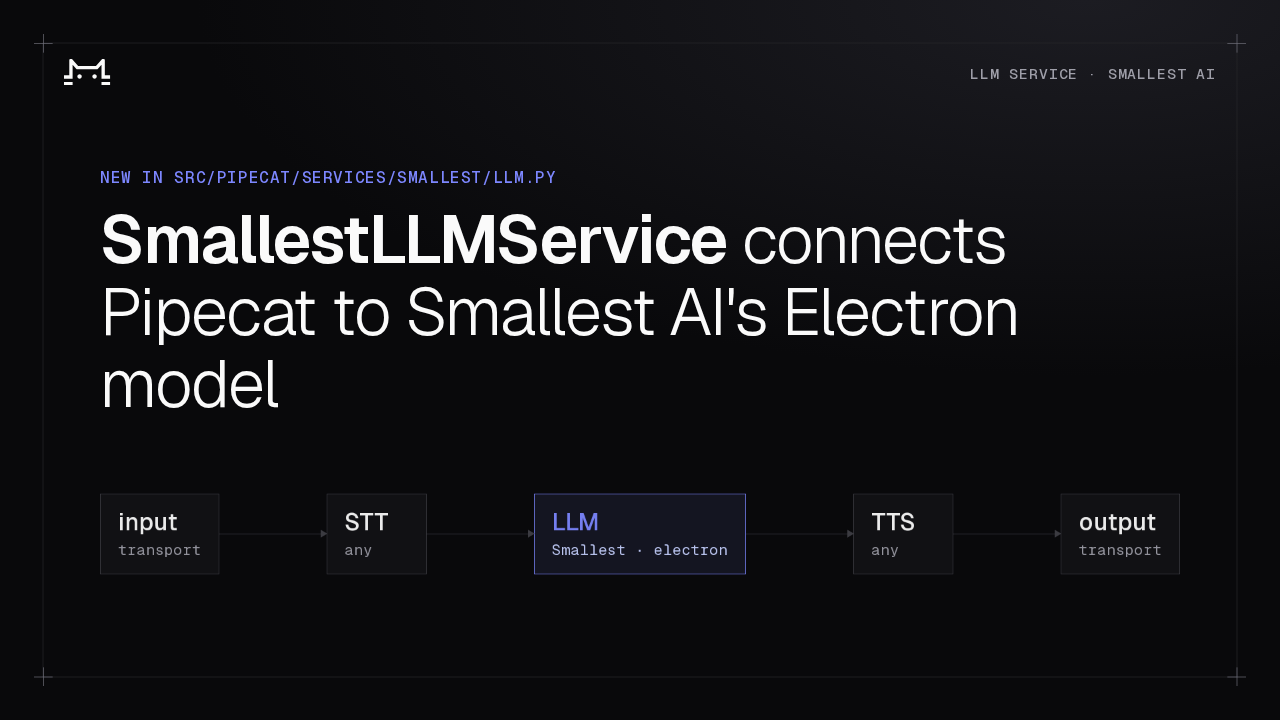
SmallestLLMServiceOpenAI-compatible Waves API; pipecat init offers it
A new Perplexity service uses its Agent API, which answers with web search and supports function calling. NVIDIA's Nemotron Omni hears the user directly, so in audio mode it replaces your speech-to-text. Zoom Scribe Live gets a streaming speech-to-text service. And Smallest AI's Electron model connects through its OpenAI-compatible Waves API.
Rime V1 needs a model
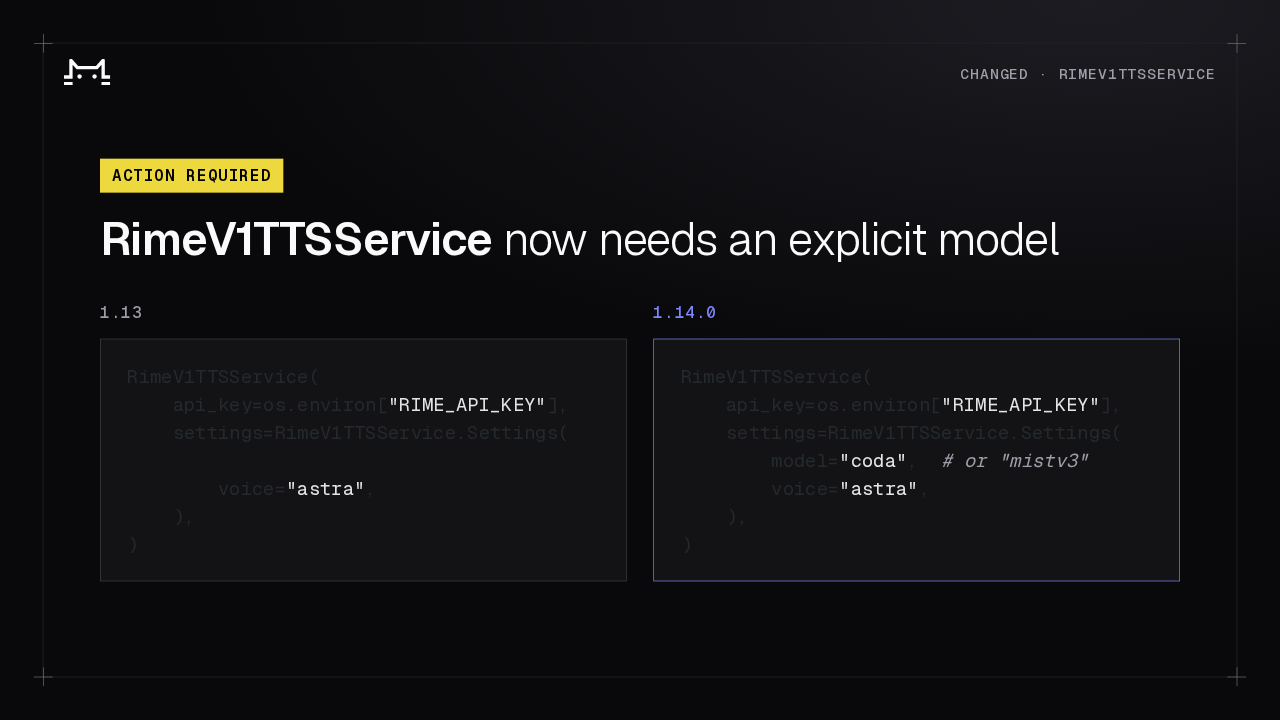
Action required
RimeV1TTSService now needs an explicit model
1.13
RimeV1TTSService(
    api_key=os.environ["RIME_API_KEY"],
    settings=RimeV1TTSService.Settings(

        voice="astra",
    ),
)
1.14.0
RimeV1TTSService(
    api_key=os.environ["RIME_API_KEY"],
    settings=RimeV1TTSService.Settings(
        model="coda",  # or "mistv3"
        voice="astra",
    ),
)
This is the change you have to make. RimeV1TTSService now requires a model in its settings. Set coda or mistv3, and the service connects to that model's public endpoint. A custom deployment also passes a websocket URL; the path in that URL doesn't select the model.
Defaults that moved
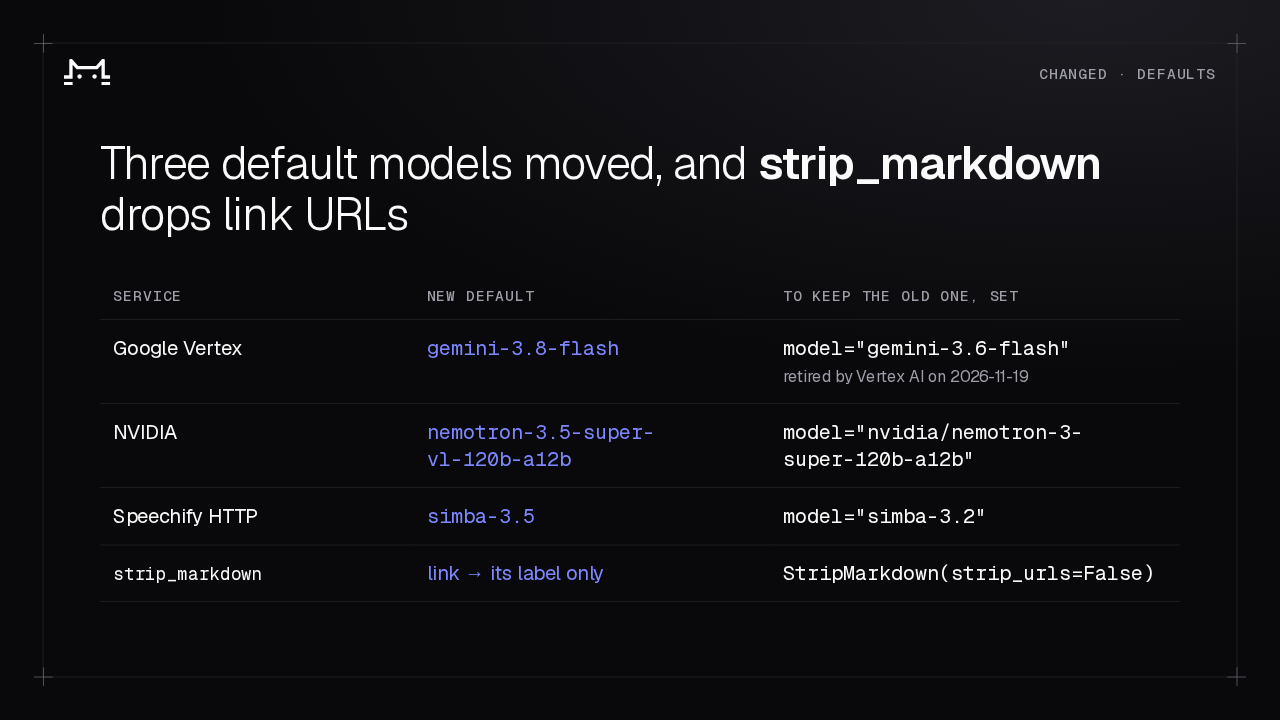
Three default models moved, and strip_markdown drops link URLs
| Service | New default | To keep the old one, set |
|---|---|---|
| Google Vertex | gemini-3.8-flash | model="gemini-3.6-flash" retired by Vertex AI on 2026-11-19 |
| NVIDIA | nemotron-3.5-super- vl-120b-a12b | model="nvidia/nemotron-3- super-120b-a12b" |
| Speechify HTTP | simba-3.5 | model="simba-3.2" |
| strip_markdown | link → its label only | StripMarkdown(strip_urls=False) |
Some defaults change under you. Google Vertex moves to Gemini 3.8 Flash, because Vertex retires 3.6 Flash on November 19, 2026. NVIDIA moves to Nemotron 3.5 Super, and Speechify to Simba 3.5. And strip_markdown now reduces a link to its label, so the URL isn't read aloud. The right-hand column keeps the old behavior.
Deprecations
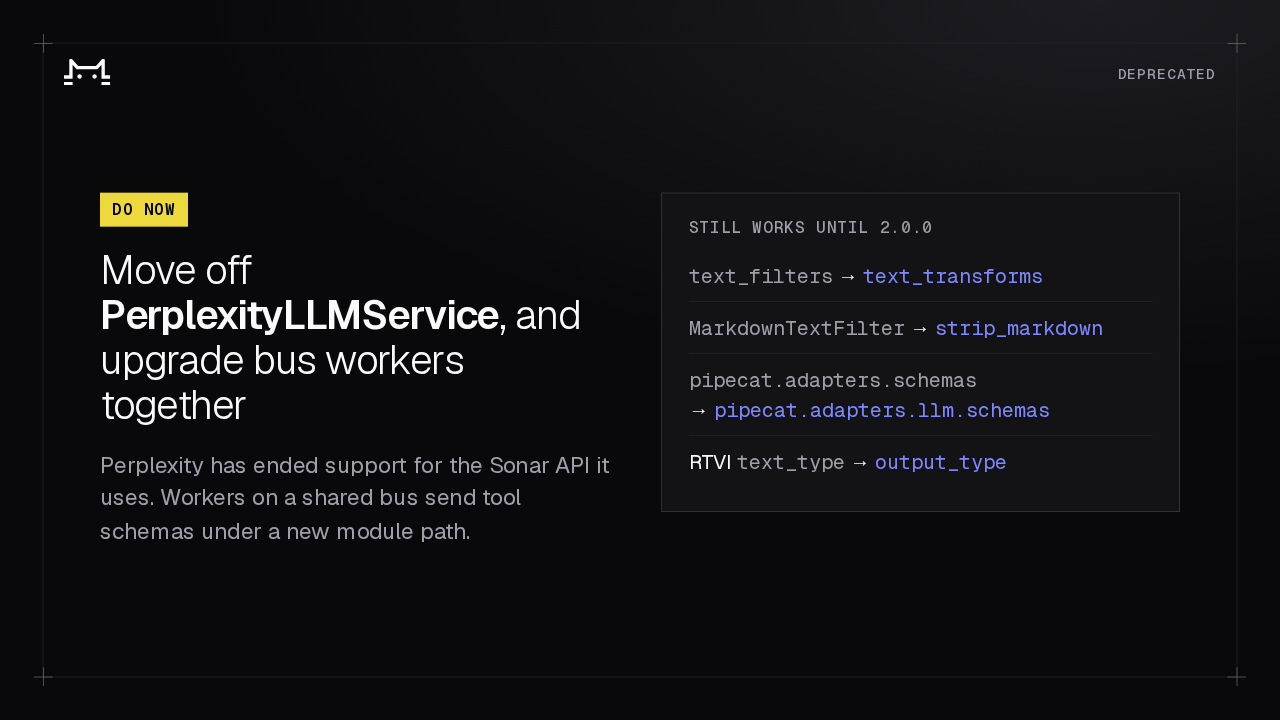
Do now
Move off PerplexityLLMService, and upgrade bus workers together
Perplexity has ended support for the Sonar API it uses. Workers on a shared bus send tool schemas under a new module path.
Still works until 2.0.0
→ pipecat.adapters.llm.schemas
Two deprecations can't wait. Perplexity has ended support for the Sonar API that PerplexityLLMService uses, so move to the Agent service. And workers on a shared bus now send tool schemas under a new module path, so upgrade them together. The rest keep working until 2.0.0.
Security
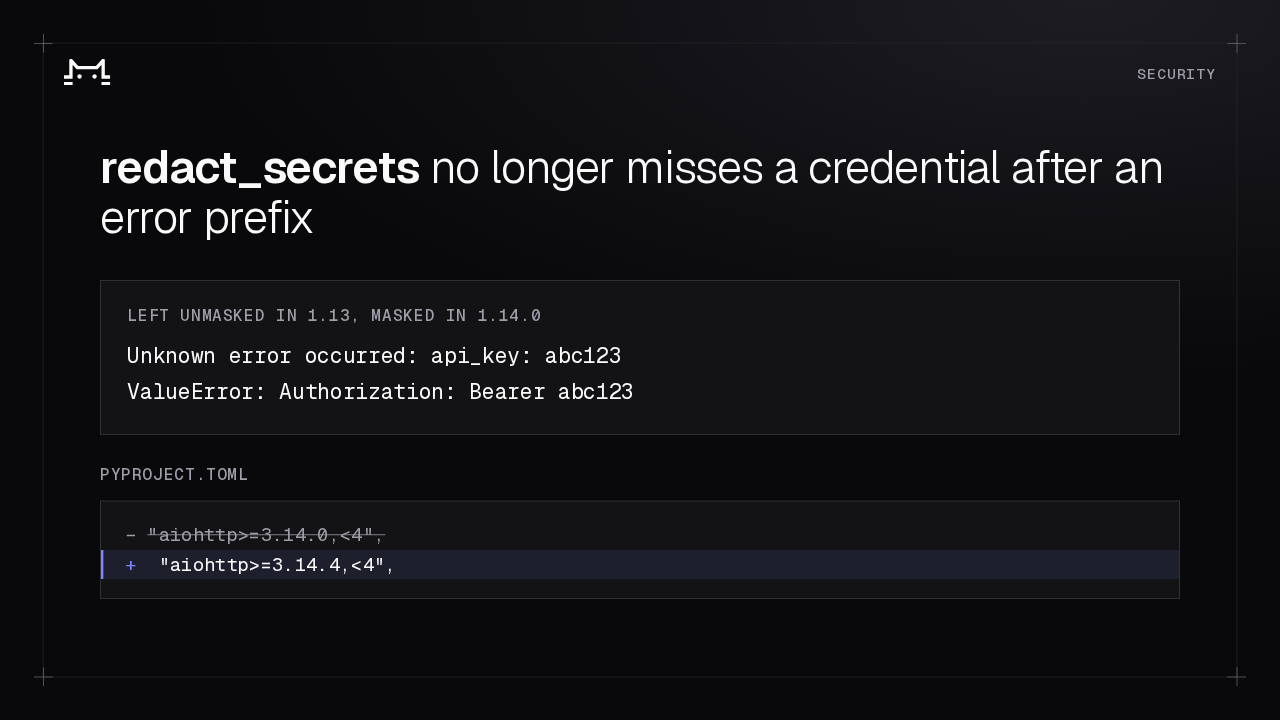
redact_secrets no longer misses a credential after an error prefix
Left unmasked in 1.13, masked in 1.14.0
ValueError: Authorization: Bearer abc123
pyproject.toml
redact_secrets, which ErrorFrame uses, left a credential unmasked when its pair followed another pair, like this API key after an error prefix. Now the prefix doesn't change what gets masked. And the minimum aiohttp is now 3.14.4, the first release with fixes for several of its security advisories.
Upgrade
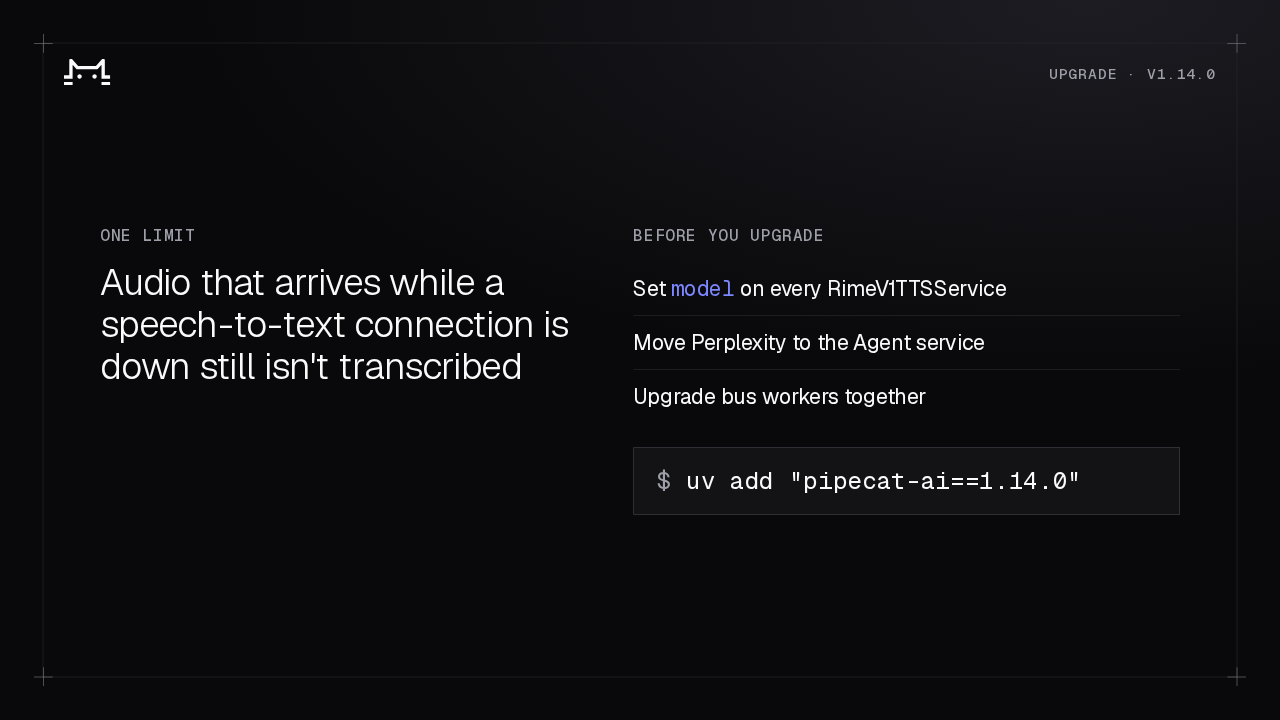
One limit
Audio that arrives while a speech-to-text connection is down still isn't transcribed
Before you upgrade
One limit: audio that arrives while a speech-to-text connection is down still isn't transcribed. Before you upgrade, set a model on any Rime V1 service, move Perplexity to the Agent service, and upgrade workers that share a bus together. Then install 1.14.0, and a stuck connection stops freezing your bot.