MLX LM v0.32.0 runs Kimi K3, DeepSeek-V4.1 and MiniMax M3 on your Mac

MLX LM now runs Kimi K3, DeepSeek-V4.1, MiniMax M3 and Meta's Muse Glimmer on your Mac. It also splits more big models across several Macs, and loading a model no longer runs its code.
01: New models
New models.
Kimi K3 runs in 2-bit across two Mac Studios
Kimi K3 from Moonshot AI loads, with its own tool-call parser. A 2-bit mixed quantization of it generates text split across two Mac Studios with M3 Ultra chips.
MiniMax M3 arrives as text only
MiniMax M3 arrives, text only
- 427B mixture of experts, about 23B active
- Vision tower and MiniMax Sparse Attention come later
MiniMax M3 loads too, a 427B mixture of experts with about 23B active per token. For now it is text only: the vision tower and MiniMax Sparse Attention are left for a later change.
Meta's Muse Glimmer 30B runs its text model in MLX LM
Meta's Muse Glimmer 30B, text model
Meta's Muse Glimmer 30B is supported as a text model; the loader strips the vision encoder. It is Apache licensed, and mlx-community already hosts full-precision, 8-bit and 4-bit builds.
Mistral 4, OLMo Hybrid and Ling-3.0 join the list
Also new: three more families
Mistral 4, OLMo Hybrid, and Ling-3.0 through the new Bailing V3 architecture all load in this release.
02: Several Macs, one model
Several Macs, one model.
Qwen3 MoE splits across Macs, and pipelining decodes faster
Qwen3 MoE now splits across Macs two ways
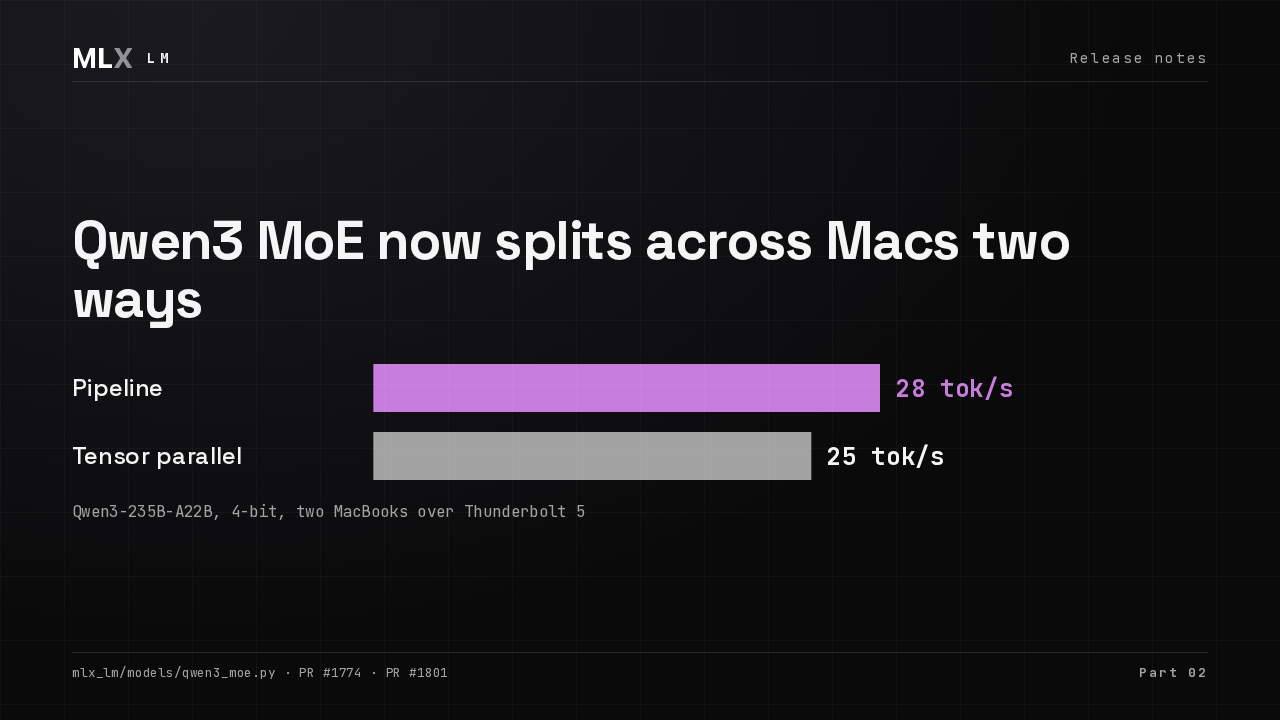
Qwen3's mixture-of-experts models can now be split across Macs by layers or by tensors. On two MacBooks running the 235B model, splitting by layers decodes about 16 percent faster.
Pipeline splitting reaches Qwen 3.5, Qwen2 and Qwen3-Next
Pipeline splitting reaches more models
- Qwen 3.5, Qwen2 and Qwen3-Next
- DeepSeek-V3.2 moves onto the shared pipeline code
- Uneven splits no longer drop layers
Qwen 3.5, Qwen2 and Qwen3-Next gain the same layer splitting, and DeepSeek-V3.2 moves onto the shared pipeline code. A split that didn't divide evenly used to drop layers; that is fixed.
03: Chat and the server
Chat and the server.
The MLX LM server can quantize its KV cache
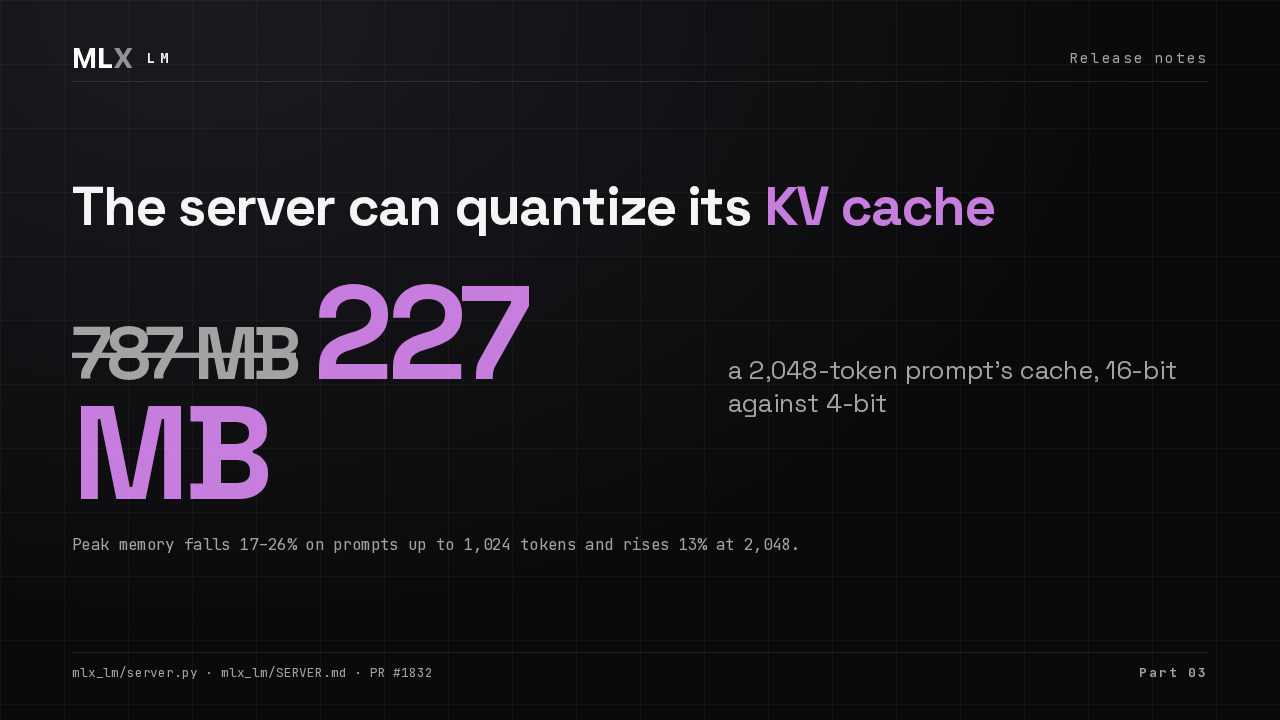
The server can quantize its KV cache
The MLX LM server can now quantize its KV cache. At 4-bit, a 2,048 token prompt's cache shrinks from about 790 megabytes to 230, though peak memory rose at that length.
mlx_lm.chat and LoRA training get a new terminal interface
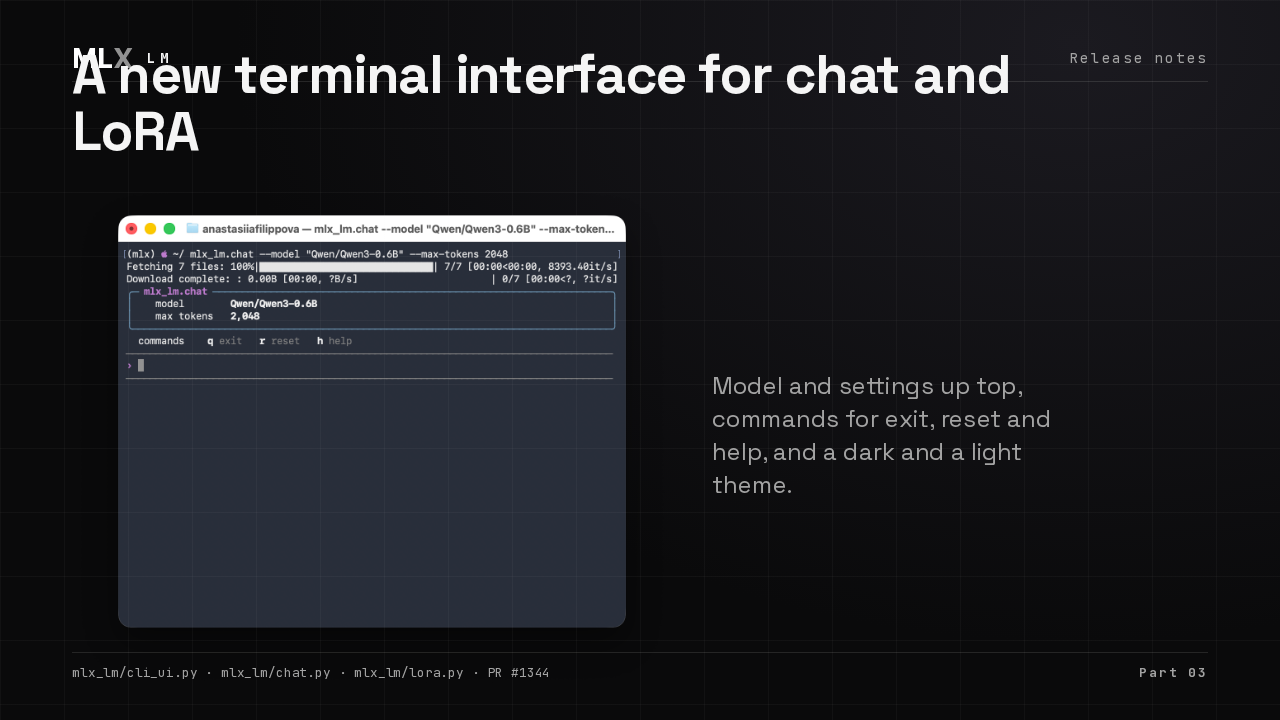
A new terminal interface for chat and LoRA

The chat command and LoRA fine-tuning get a new terminal interface. Chat shows the model and settings in a panel, with one-key commands to exit, reset and get help, in dark and light themes.
Prefill step size cuts peak memory at 128K context
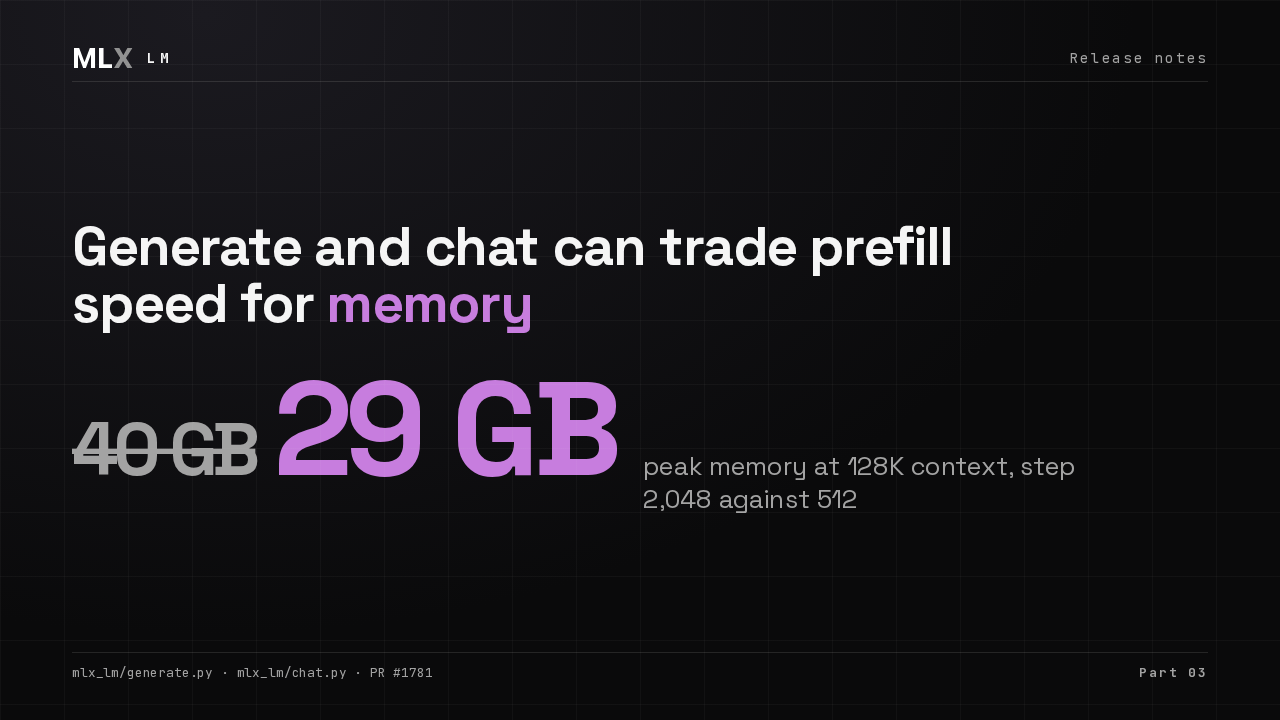
Generate and chat can trade prefill speed for memory
Generate and chat now take a prefill step size, which the server already had. At a 128K token context, smaller steps cut peak memory by about 11 gigabytes, with generation speed unchanged.
04: Fixes you may have hit
Fixes you may have hit.
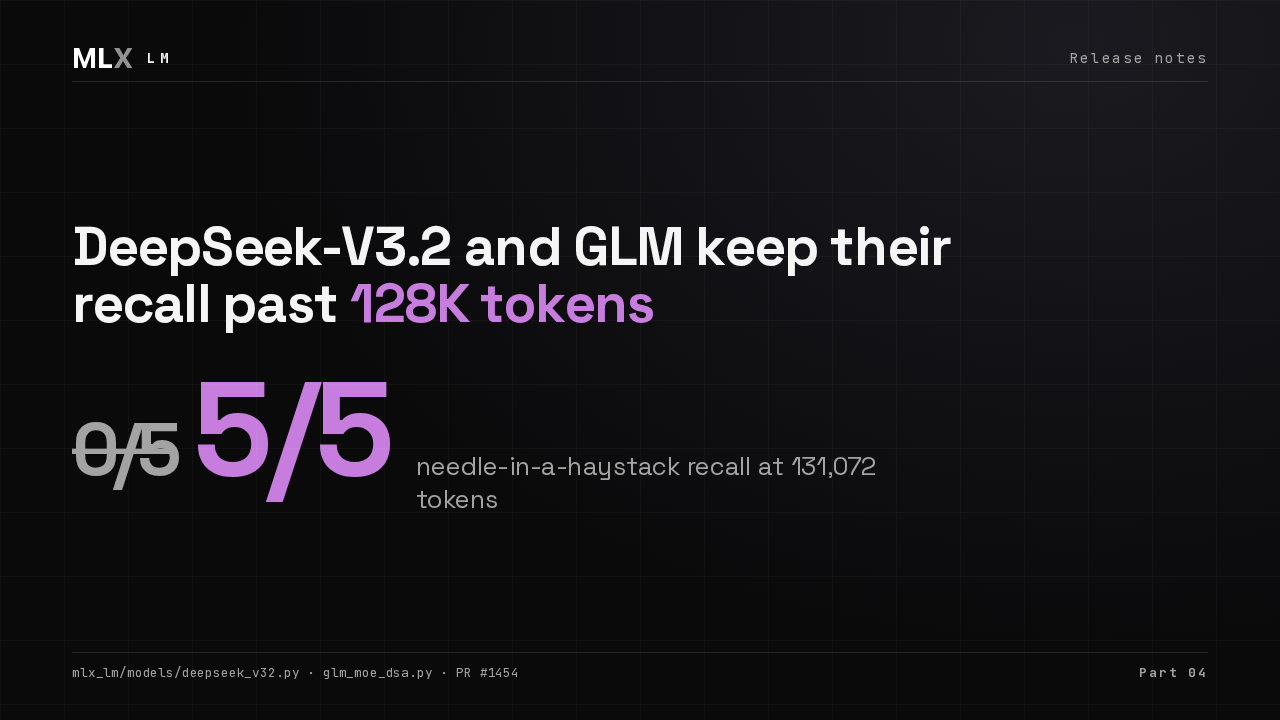
DeepSeek-V3.2 and GLM keep their recall past 128K tokens
Past about 128K tokens, DeepSeek-V3.2 and GLM quietly attended to only the last 2,048 tokens, with no warning. Long-context recall went from zero of five to five of five.
Tool calls parse on text, and Mistral keeps parallel calls
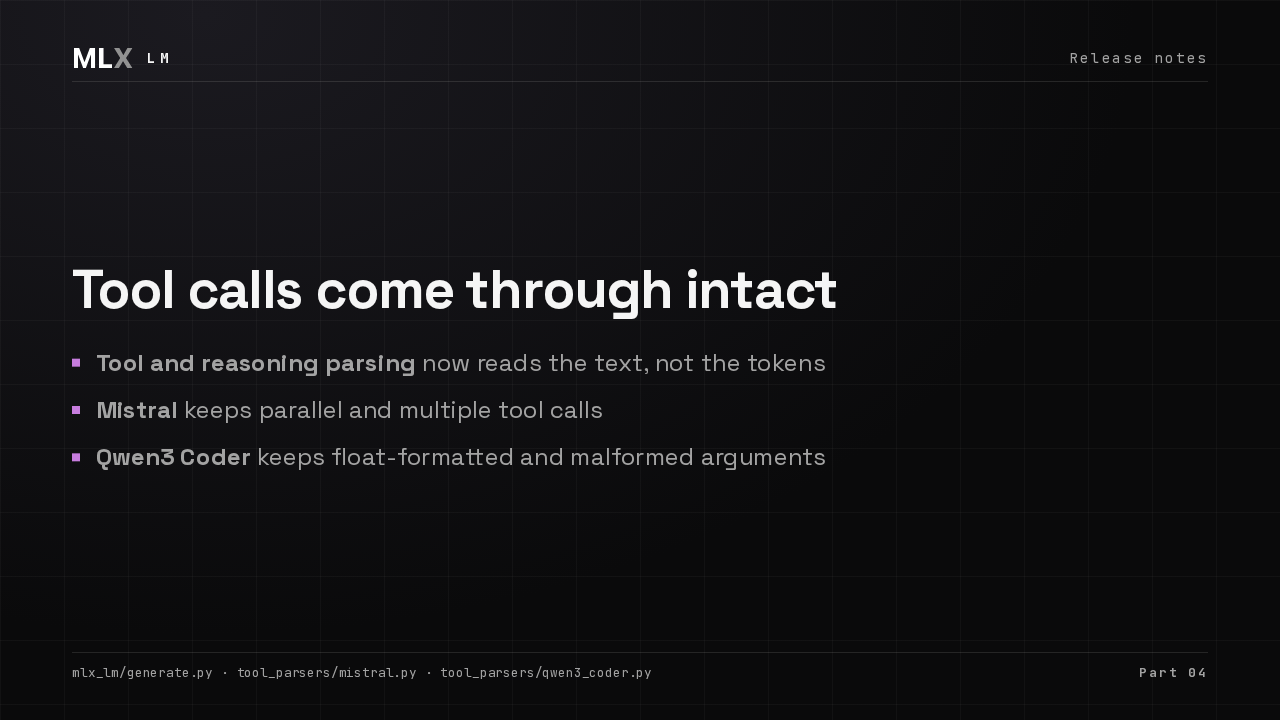
Tool calls come through intact
- Tool and reasoning parsing now reads the text, not the tokens
- Mistral keeps parallel and multiple tool calls
- Qwen3 Coder keeps float-formatted and malformed arguments
Tool and reasoning parsing now switches state on the generated text, because the same string can arrive as different tokens. Mistral keeps parallel tool calls, and Qwen3 Coder stops dropping calls with odd arguments.
FP8 checkpoints and XTC sampling stop producing garbage
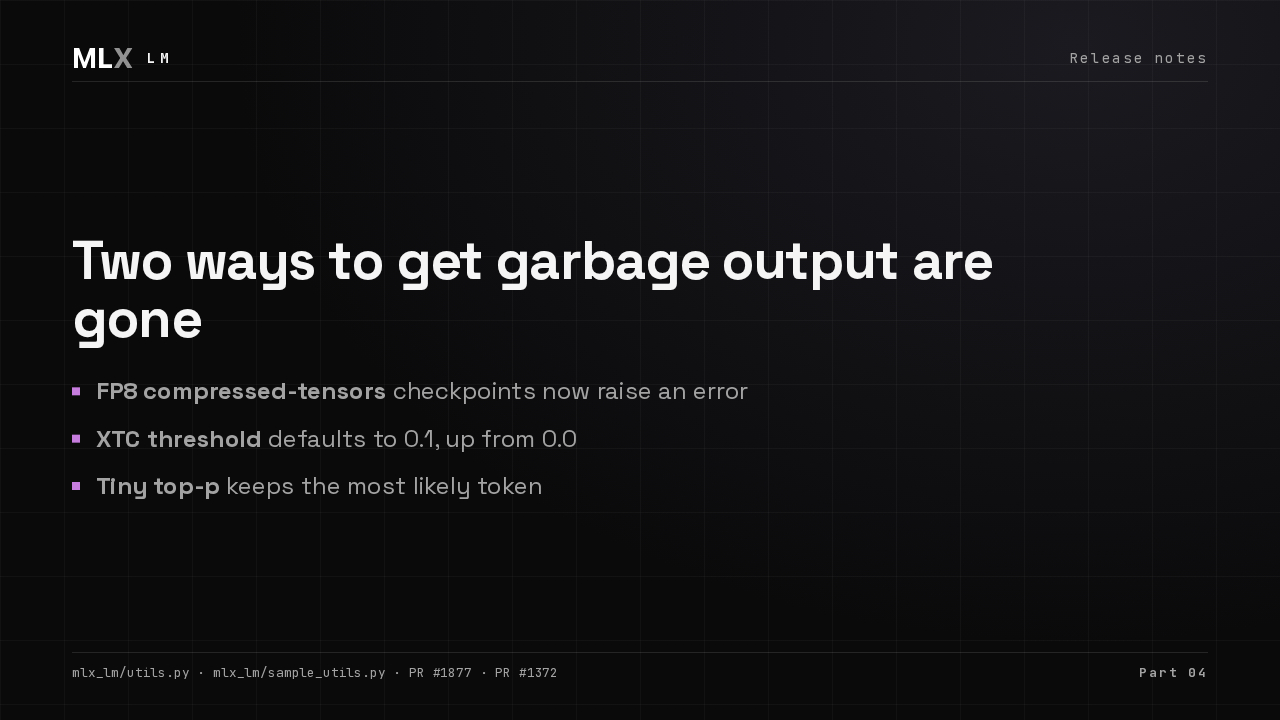
Two ways to get garbage output are gone
- FP8 compressed-tensors checkpoints now raise an error
- XTC threshold defaults to 0.1, up from 0.0
- Tiny top-p keeps the most likely token
FP8 checkpoints used to load as 4-bit and generate garbage; now they fail with a message to dequantize first. The XTC sampler's default threshold moves to 0.1, so turning XTC on without a threshold no longer wrecks the output.
05: Before you upgrade
Before you upgrade.
Loading a model no longer runs its Python file without trust_remote_code
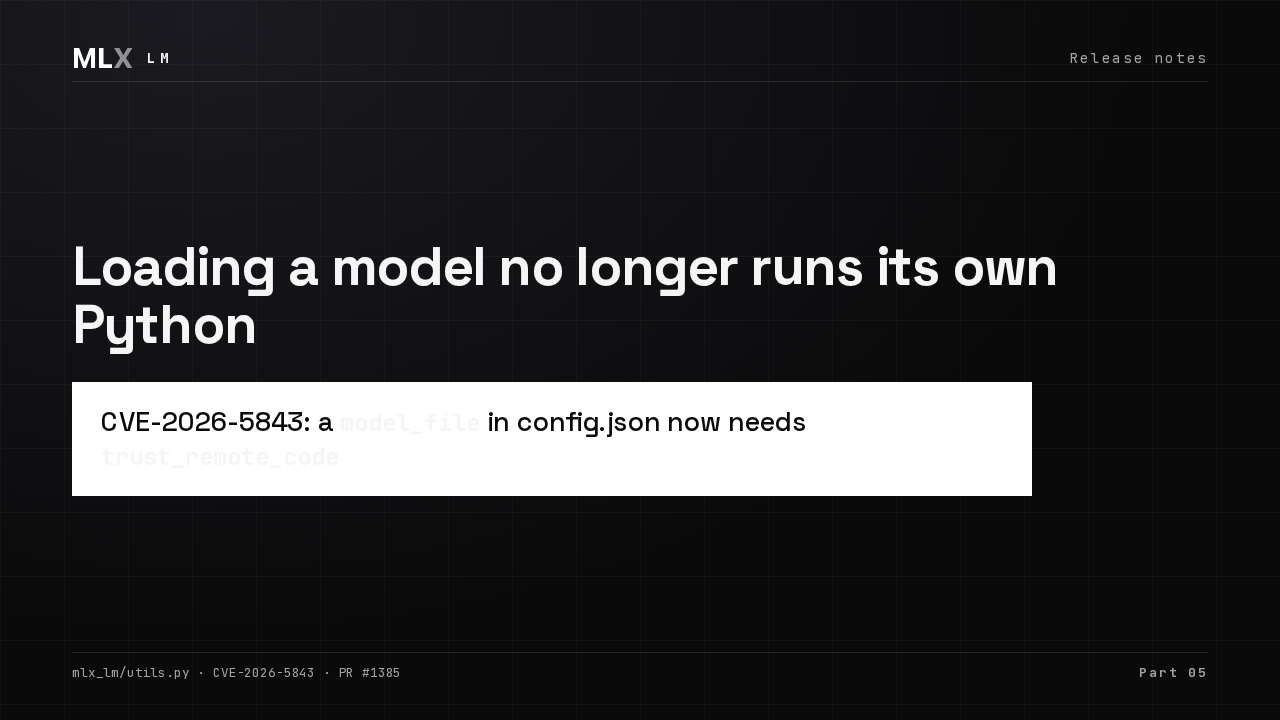
Loading a model no longer runs its own Python
model_file in config.json now needs trust_remote_codeA model whose config named its own Python file got that file run on a plain load. That is CVE-2026-5843. Those models now load only when you turn on trust remote code; other models load as before.
MLX LM v0.32.0 needs Python 3.11, MLX 0.32.2 and transformers 5.7
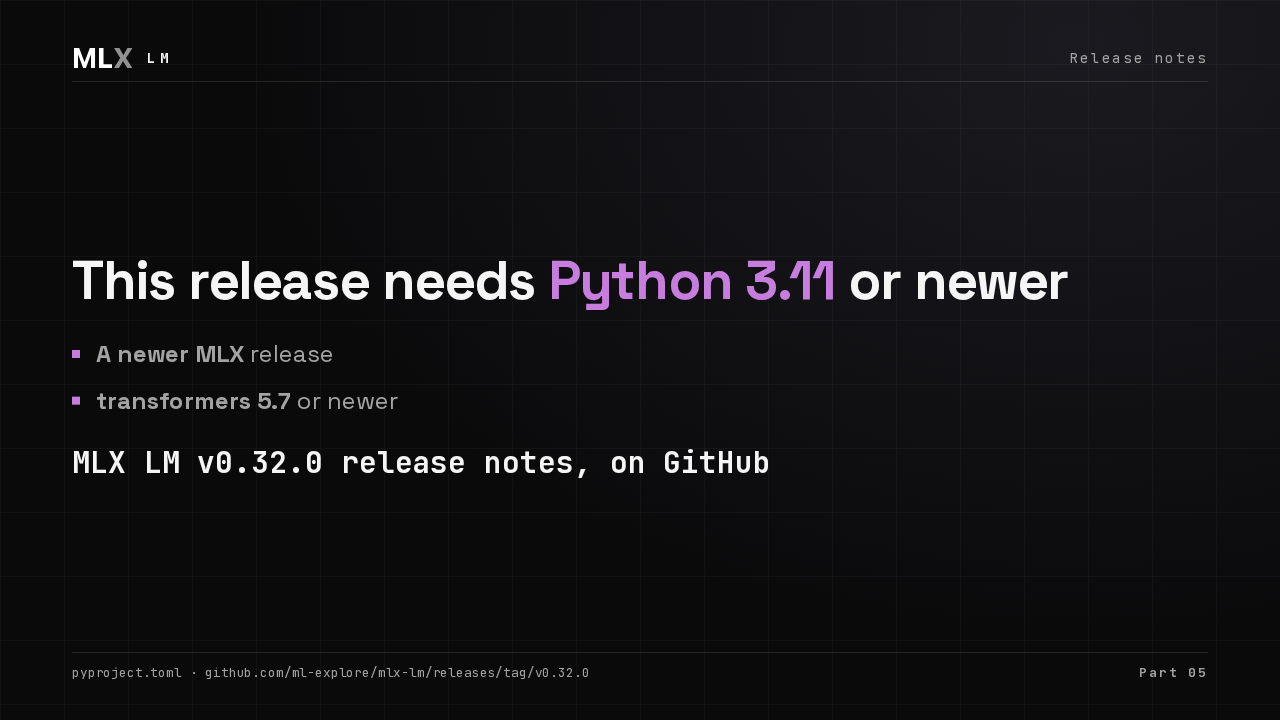
This release needs Python 3.11 or newer
- A newer MLX release
- transformers 5.7 or newer
The minimum Python moves to 3.11, so anyone on an older Python stays on the previous release. It also needs a recent MLX and transformers 5.7. The MLX LM release notes on GitHub list everything else.