MLX LM v0.32.2 loads Meta's Muse Spark from Hugging Face and fixes MiMo-V2-Flash

1 hour ago

MLX LM v0.32.2 loads Meta's Muse Spark from its public Hugging Face checkpoint (with a 16-bit output layer that should decode a bit faster), makes MiMo-V2-Flash scale its attention values as its config asks, and stops padding from decaying the state of Mamba-2, Nemotron-H, Falcon-H1, Granite hybrid and PLaMo 2 models in batched generation. https://github.com/ml-explore/mlx-lm/releases/tag/v0.32.2 https://github.com/ml-explore/mlx-lm/compare/v0.32.1...v0.32.2 https://huggingface.co/meta-models/Muse-Spark-Open-816B-A42B-NVFP4

Ask

Ask about this presentation

Answers are generated from this presentation.

Chapters

  1. 0:00MLX LM v0.32.2 loads Meta's Muse Spark from Hugging Face and fixes MiMo-V2-Flash
  2. 0:15Muse Spark's output layer is half the size
  3. 0:28MiMo-V2-Flash now scales its attention values
  4. 0:43Padding stops fading the state of Mamba-2 and other state space models
Show transcript

MLX LM v0.32.2 loads Meta's Muse Spark from Hugging Face and fixes MiMo-V2-Flash

MLX
MLX LM v0.32.2
Meta’s Muse Spark loads straight from its Hugging Face checkpoint.
meta-models/Muse-Spark-Open-816B-A42B-NVFP4
mlx_lm/models/muse_spark.py · PR #1981 · v0.32.2 release notes
v0.32.2

MLX LM now loads Meta's Muse Spark from the checkpoint Meta put on Hugging Face. The earlier support expected the weight names of an internal checkpoint, and every name now matches the public release.

Muse Spark's output layer is half the size

MLX
LM
Release notes

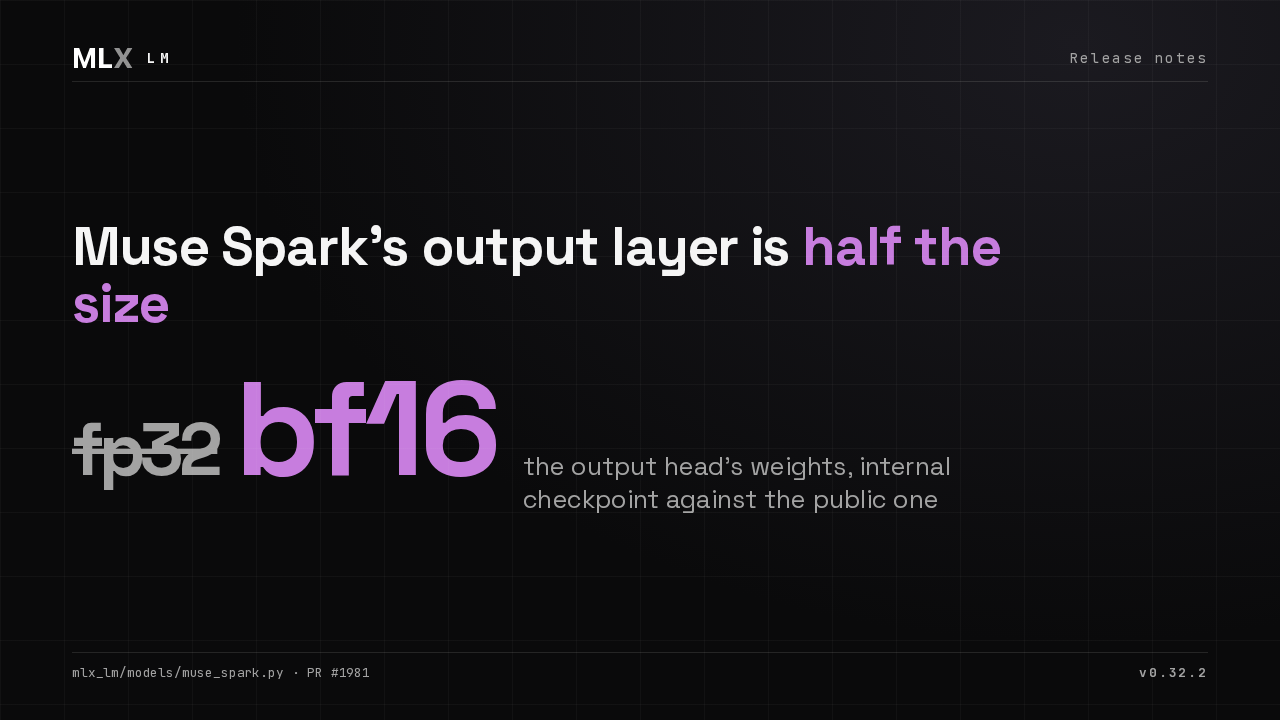
Muse Spark’s output layer is half the size

fp32bf16
the output head’s weights, internal checkpoint against the public one
mlx_lm/models/muse_spark.py · PR #1981
v0.32.2

The public Muse Spark checkpoint stores its output layer in 16-bit precision, where the internal one used 32-bit. That layer runs on every token, so decoding should get a bit faster.

MiMo-V2-Flash now scales its attention values

MLX
LM
Release notes
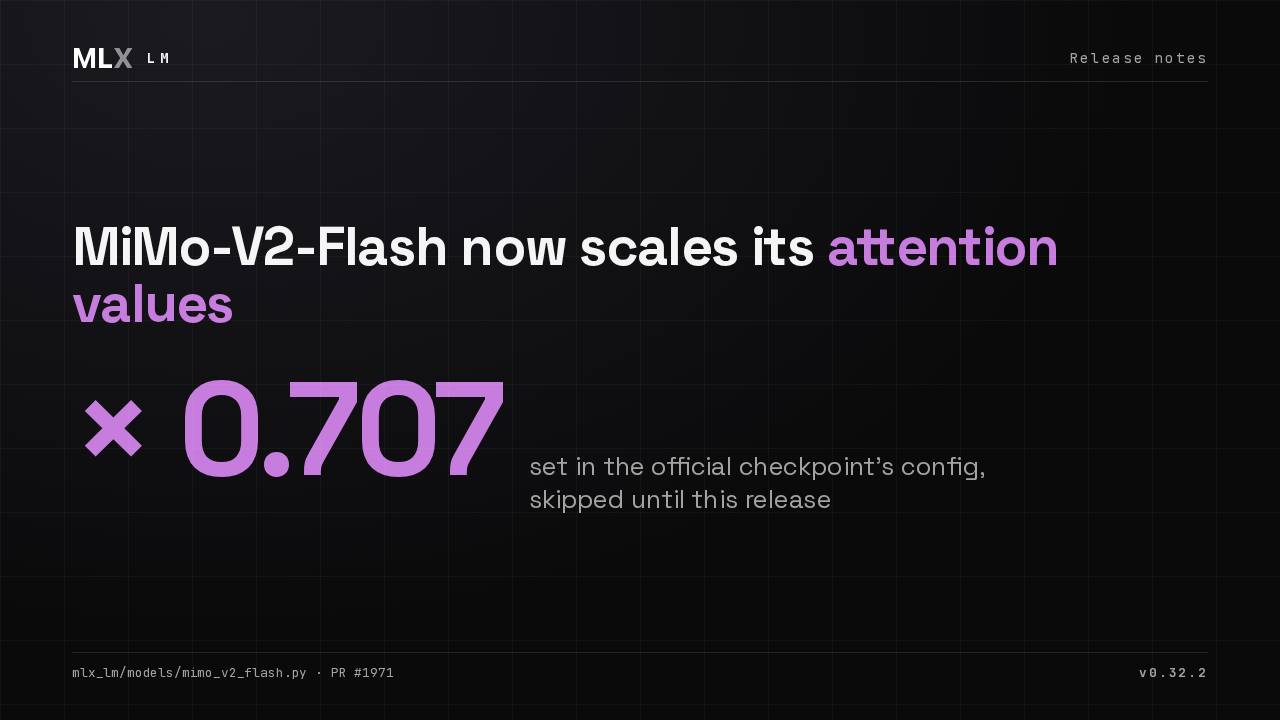
× 0.707
set in the official checkpoint’s config, skipped until this release
mlx_lm/models/mimo_v2_flash.py · PR #1971
v0.32.2

MiMo-V2-Flash's config tells it to scale its attention values by about 0.7 before they enter the cache. MLX LM skipped that step, so the model drifted from its reference code. Now it matches.

Padding stops fading the state of Mamba-2 and other state space models

MLX
LM
Release notes

Padding stops fading the state of state space models

Mamba-2
Nemotron-H
Falcon-H1
Granite hybrid
PLaMo 2
MLX LM v0.32.2 release notes, on GitHub
mlx_lm/models/ssm.py · PR #1979 · v0.32.2 release notes
v0.32.2

In a padded batch, state space models let the padding tokens decay the state carried over from the cache. Mamba-2, Nemotron-H, Falcon-H1, Granite's hybrids and PLaMo 2 now mask the padding out of that decay.