Transformers 5.20.2
 huggingface / transformersv5.20.2
Transformers 5.20.2 keeps your input types intact inside generate
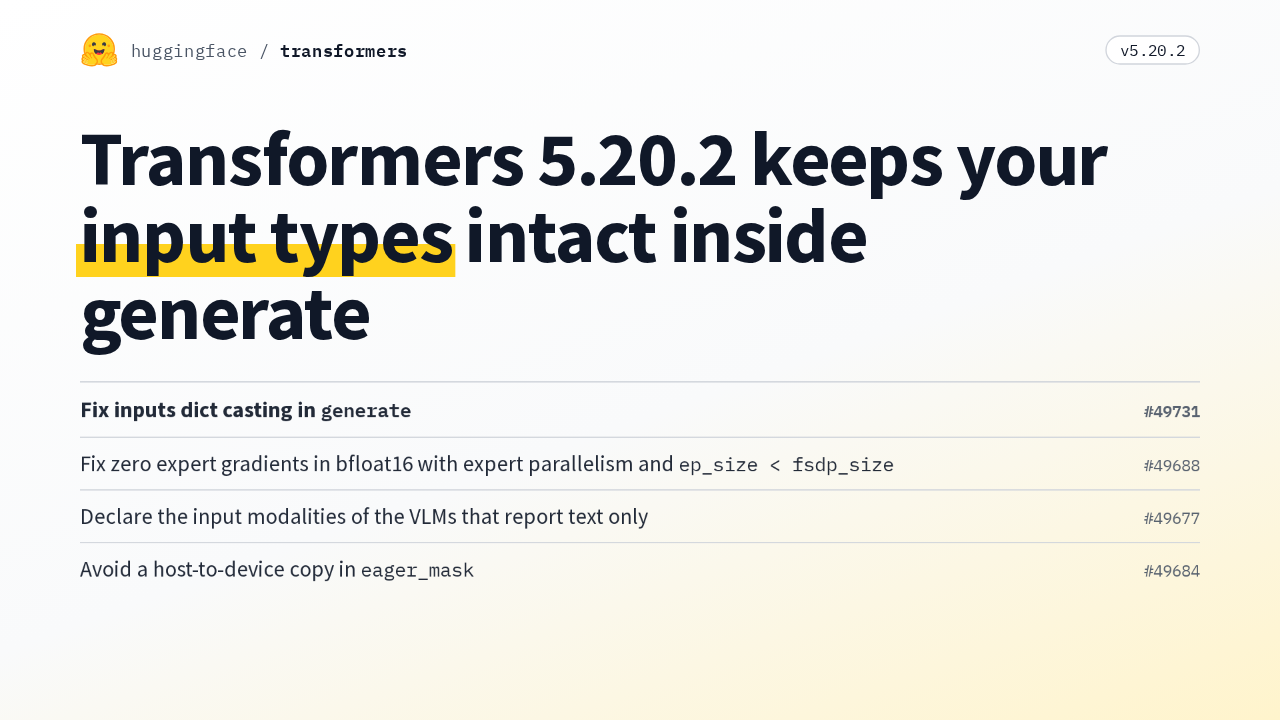
generate#49731ep_size < fsdp_size#49688eager_mask#49684Transformers 5.20.2 is a patch release. Its main fix is in generate, where some inputs could lose their original type inside prepare inputs for generation, which caused problems with multimodal models. It also fixes zero expert gradients in bfloat16 training with expert parallelism, declares image input on nine vision-language models that reported text only, and removes a host-to-device copy from the eager attention mask.
generate keeps input types
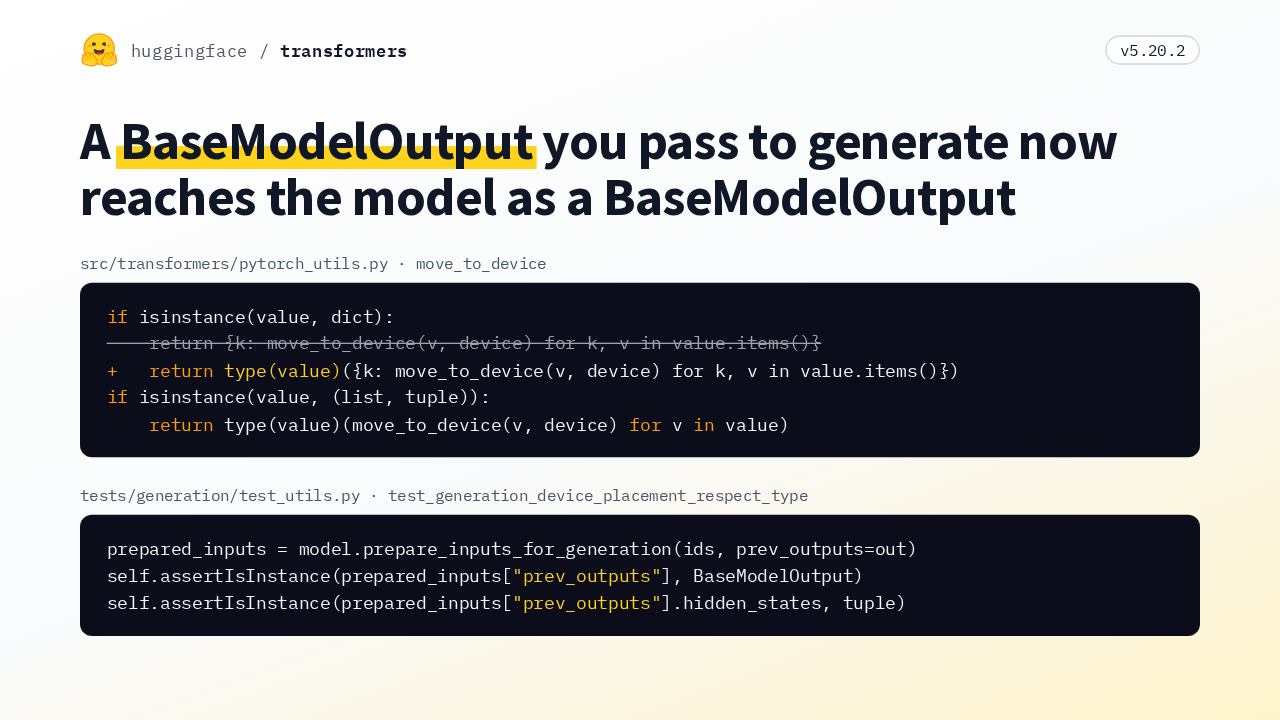
huggingface / transformersv5.20.2A BaseModelOutput you pass to generate now reaches the model as a BaseModelOutput
if isinstance(value, dict):
-   return {k: move_to_device(v, device) for k, v in value.items()}
+   return type(value)({k: move_to_device(v, device) for k, v in value.items()})
if isinstance(value, (list, tuple)):
return type(value)(move_to_device(v, device) for v in value)prepared_inputs = model.prepare_inputs_for_generation(ids, prev_outputs=out)
self.assertIsInstance(prepared_inputs["prev_outputs"], BaseModelOutput)
self.assertIsInstance(prepared_inputs["prev_outputs"].hidden_states, tuple)The cause was one line in the PyTorch utilities. When generate moves inputs onto the model's device, the move to device helper rebuilt every dictionary as a plain dict. Now it calls the input's own type, the same way it already handled lists and tuples. The new test sends a BaseModelOutput through prepare inputs for generation on a mismatched device, and checks that it comes back as a BaseModelOutput, with its hidden states still a tuple.
bfloat16 expert gradients
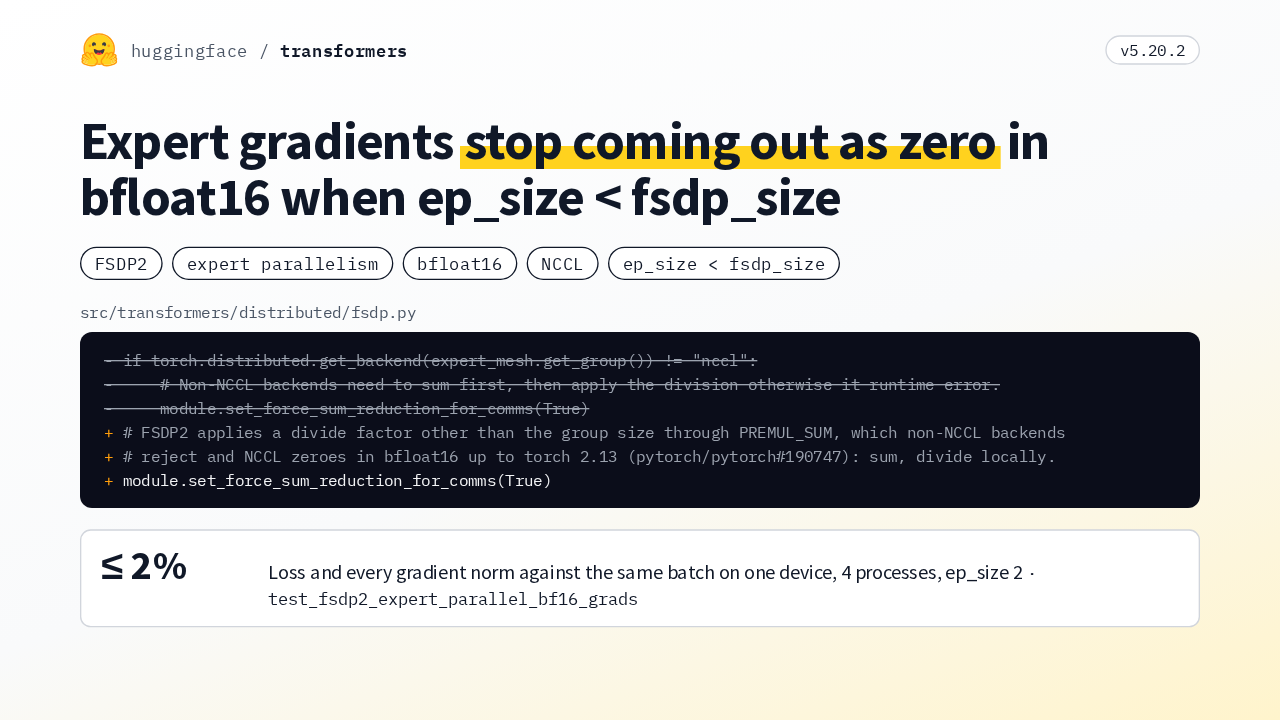
huggingface / transformersv5.20.2Expert gradients stop coming out as zero in bfloat16 when ep_size < fsdp_size
- if torch.distributed.get_backend(expert_mesh.get_group()) != "nccl":
-     # Non-NCCL backends need to sum first, then apply the division otherwise it runtime error.
-     module.set_force_sum_reduction_for_comms(True)
+ # FSDP2 applies a divide factor other than the group size through PREMUL_SUM, which non-NCCL backends
+ # reject and NCCL zeroes in bfloat16 up to torch 2.13 (pytorch/pytorch#190747): sum, divide locally.
+ module.set_force_sum_reduction_for_comms(True)The second fix is for training mixture-of-experts models with FSDP2 and expert parallelism, when the expert-parallel size is smaller than the FSDP size. Each expert's gradient is then divided by the FSDP size. FSDP2 applies that division through a premultiplied sum, and NCCL zeroes it in bfloat16 up to PyTorch 2.13. The fix forces a plain sum on every backend and divides locally. A new four-process test checks the loss and every gradient norm against the same batch on one device, within 2 percent.
VLM input modalities
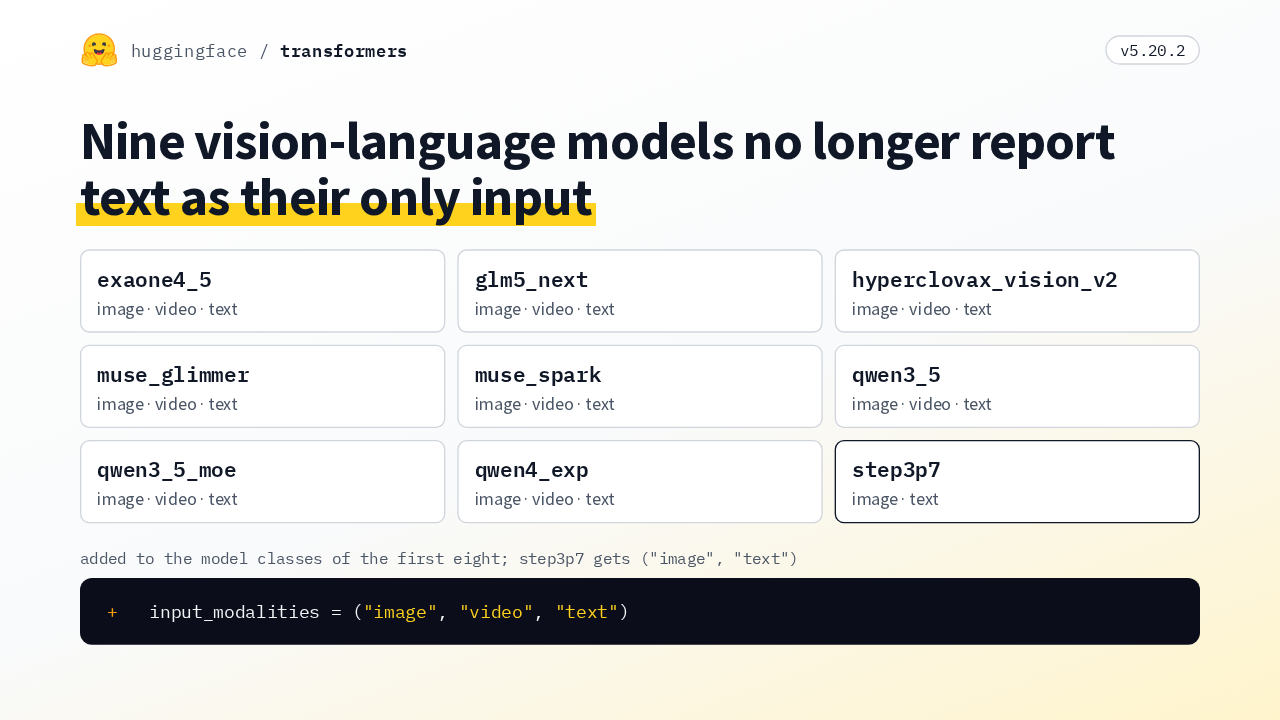
huggingface / transformersv5.20.2Nine vision-language models no longer report text as their only input
+ input_modalities = ("image", "video", "text")Nine vision-language model families reported text as their only input, even though they take images. Each now declares its modalities on the model classes: image, video and text for eight of them, and image and text for Step3p7. These are class attributes, so your calls to the models stay the same.
eager_mask copy
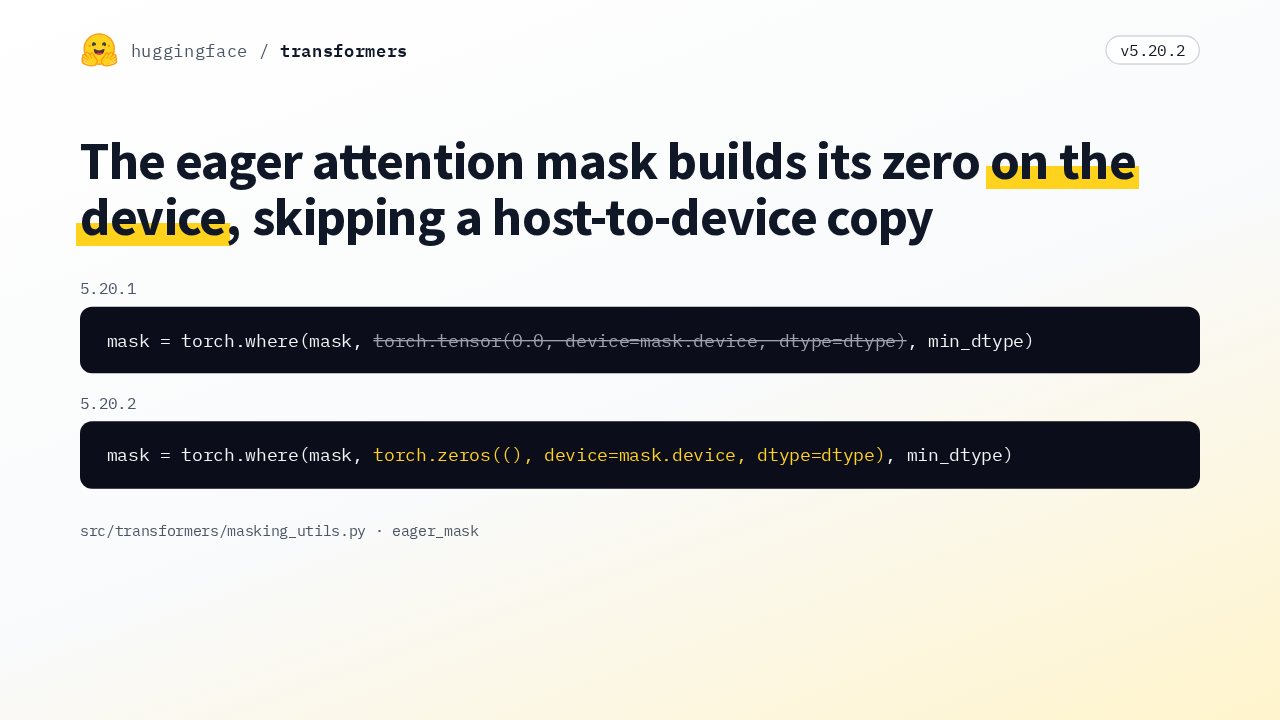
huggingface / transformersv5.20.2The eager attention mask builds its zero on the device, skipping a host-to-device copy
mask = torch.where(mask, torch.tensor(0.0, device=mask.device, dtype=dtype), min_dtype)mask = torch.where(mask, torch.zeros((), device=mask.device, dtype=dtype), min_dtype)A smaller change sits on the eager attention path. The mask builder created its zero as a new tensor from a Python number, which copies that value from the host to the device. It now allocates the zero directly on the device instead, and the mask it returns is the same.
Upgrade
huggingface / transformersv5.20.2Transformers 5.20.2 keeps your input types intact inside generate
pip install -U transformers==5.20.2Apart from the version string, the diff carries only these fixes and their tests, so this is a drop-in upgrade from 5.20.1. One behavior does change. On NCCL, expert gradients under FSDP2 are now summed and then divided locally in every precision, not only in bfloat16. To upgrade, install it with pip, pinned to 5.20.2. Transformers 5.20.2 keeps your input types intact inside generate.