Flint in Transformers
 huggingface / transformersAdd Flint model support
Recursive's Flint now runs
natively in Transformers
A mixture-of-experts language model with hybrid attention, attention sinks and sigmoid routing.
from transformers import AutoModelForCausalLM
model = AutoModelForCausalLM.from_pretrained("RecursiveSI/flint", dtype="auto", device_map="auto")
Recursive's Flint is a mixture-of-experts language model, and this change gives it native support in Transformers. The checkpoint now loads through the usual auto classes, backed by its own configuration and model classes, automatic registration, checkpoint conversion, documentation and tests. It was ported from an earlier private integration.
What Flint changes
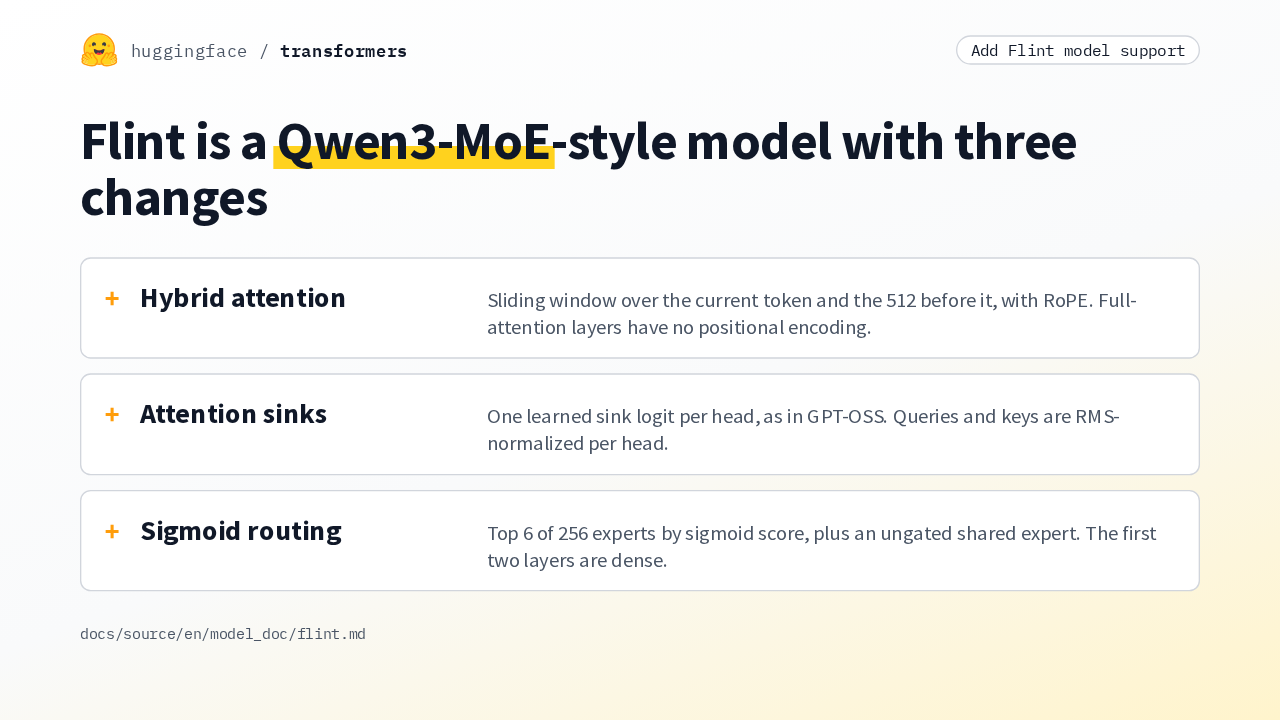
huggingface / transformersAdd Flint model supportFlint is a Qwen3-MoE-style model with three changes
The new model page describes Flint against a standard mixture-of-experts transformer like Qwen3-MoE. Most layers use sliding-window attention over the current token and the 512 before it, and the rest use full attention with no positional encoding. Every attention head has a learned sink, as in GPT-OSS. And each sparse layer sends a token to 6 of 256 experts by sigmoid score, then adds a shared expert with no gate.
Built from modular code
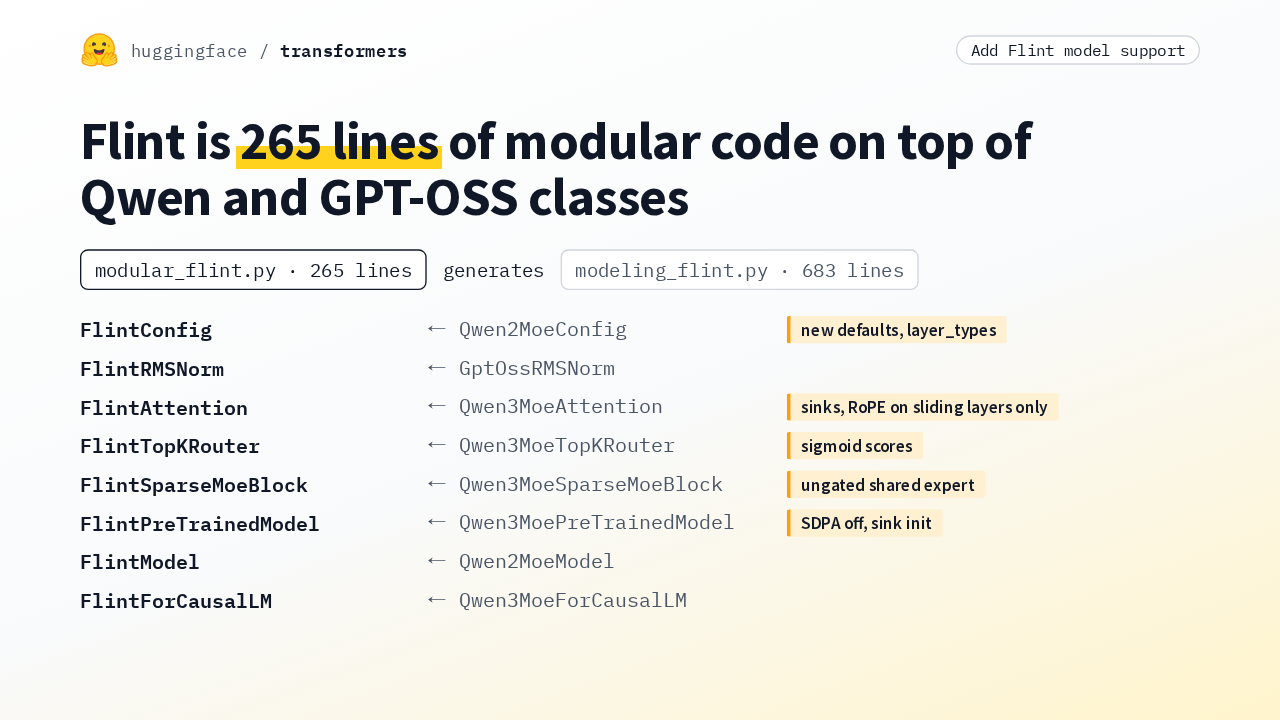
huggingface / transformersAdd Flint model supportFlint is 265 lines of modular code on top of Qwen and GPT-OSS classes
Flint is written as a modular file of about 270 lines, and the generator expands it into a modeling file of nearly 700 lines. Most of its classes inherit straight from Qwen2-MoE, Qwen3-MoE and GPT-OSS. Besides the config, four classes carry new code: the attention, the router, the sparse block, and the base class, which turns SDPA off and initializes the sinks. To change Flint, you edit the modular file and regenerate.
Which layers attend fully
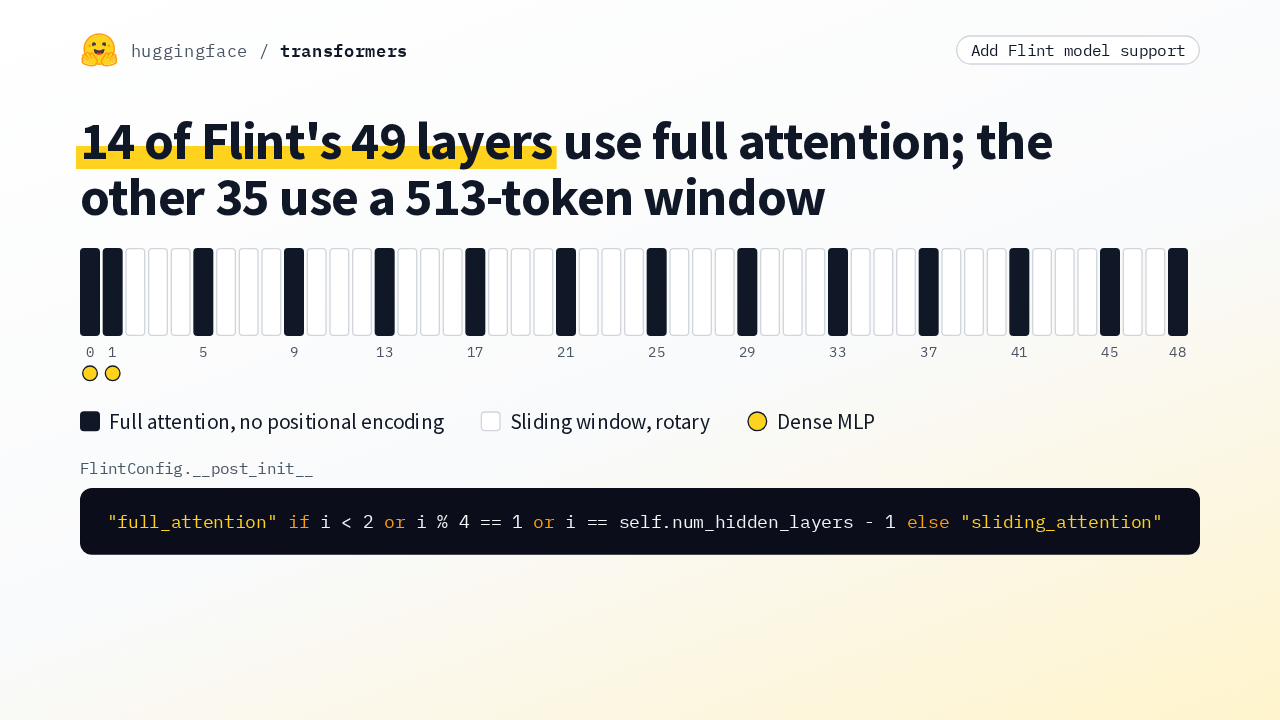
huggingface / transformersAdd Flint model support14 of Flint's 49 layers use full attention; the other 35 use a 513-token window
"full_attention" if i < 2 or i % 4 == 1 or i == self.num_hidden_layers - 1 else "sliding_attention"Here are Flint's 49 default layers. The config sets full attention on the first two layers, on every fourth layer after that, and on the last one. That makes 14 full-attention layers. The other 35 use a sliding window of 513 tokens: the current token and the 512 before it. Only the sliding layers apply rotary embeddings. And the first two layers use a dense MLP instead of experts.
Attention sinks
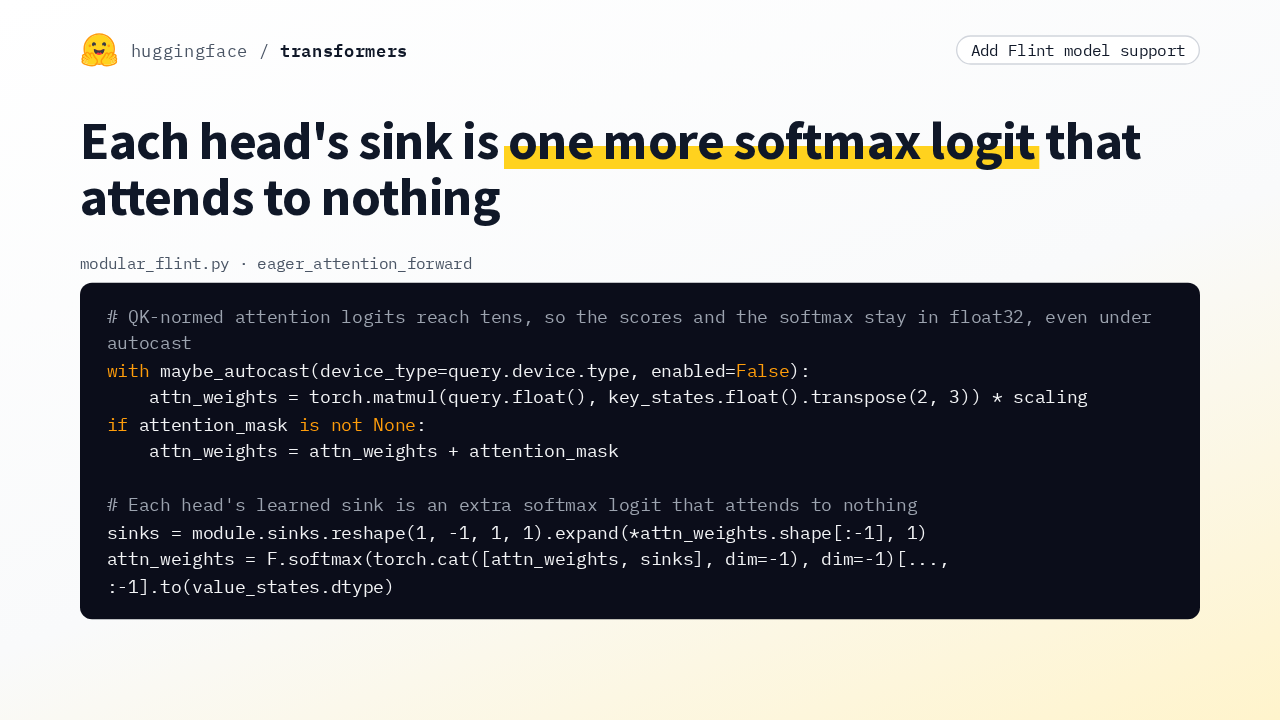
huggingface / transformersAdd Flint model supportEach head's sink is one more softmax logit that attends to nothing
# QK-normed attention logits reach tens, so the scores and the softmax stay in float32, even under autocast
with maybe_autocast(device_type=query.device.type, enabled=False):
    attn_weights = torch.matmul(query.float(), key_states.float().transpose(2, 3)) * scaling
if attention_mask is not None:
    attn_weights = attn_weights + attention_mask

# Each head's learned sink is an extra softmax logit that attends to nothing
sinks = module.sinks.reshape(1, -1, 1, 1).expand(*attn_weights.shape[:-1], 1)
attn_weights = F.softmax(torch.cat([attn_weights, sinks], dim=-1), dim=-1)[..., :-1].to(value_states.dtype)
The sink lives in the eager attention function. First, the scores are computed in float32, even under autocast, because with query and key normalization the logits reach the tens. Then each head's learned sink is appended as one more logit, the softmax runs over it, and that column is dropped. So the sink takes a share of the probability without attending to any value.
Sigmoid routing and the shared expert
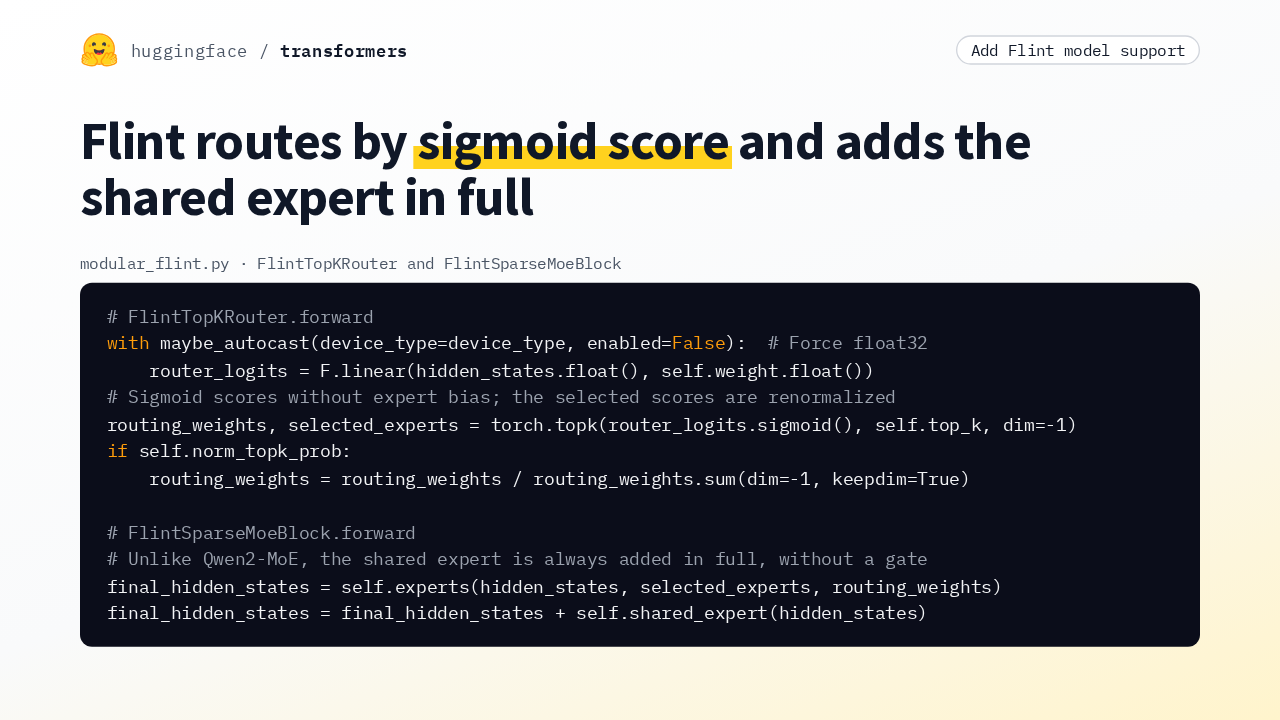
huggingface / transformersAdd Flint model supportFlint routes by sigmoid score and adds the shared expert in full
# FlintTopKRouter.forward
with maybe_autocast(device_type=device_type, enabled=False):  # Force float32
    router_logits = F.linear(hidden_states.float(), self.weight.float())
# Sigmoid scores without expert bias; the selected scores are renormalized
routing_weights, selected_experts = torch.topk(router_logits.sigmoid(), self.top_k, dim=-1)
if self.norm_topk_prob:
    routing_weights = routing_weights / routing_weights.sum(dim=-1, keepdim=True)

# FlintSparseMoeBlock.forward
# Unlike Qwen2-MoE, the shared expert is always added in full, without a gate
final_hidden_states = self.experts(hidden_states, selected_experts, routing_weights)
final_hidden_states = final_hidden_states + self.shared_expert(hidden_states)
The router computes its logits in float32, with autocast turned off. It takes a sigmoid over them, keeps the top 6 experts out of 256, and renormalizes the chosen scores so they sum to one. Then the sparse block adds the shared expert. Unlike Qwen2-MoE, Flint adds it to every token in full, with no gate.
Attention backends and limits
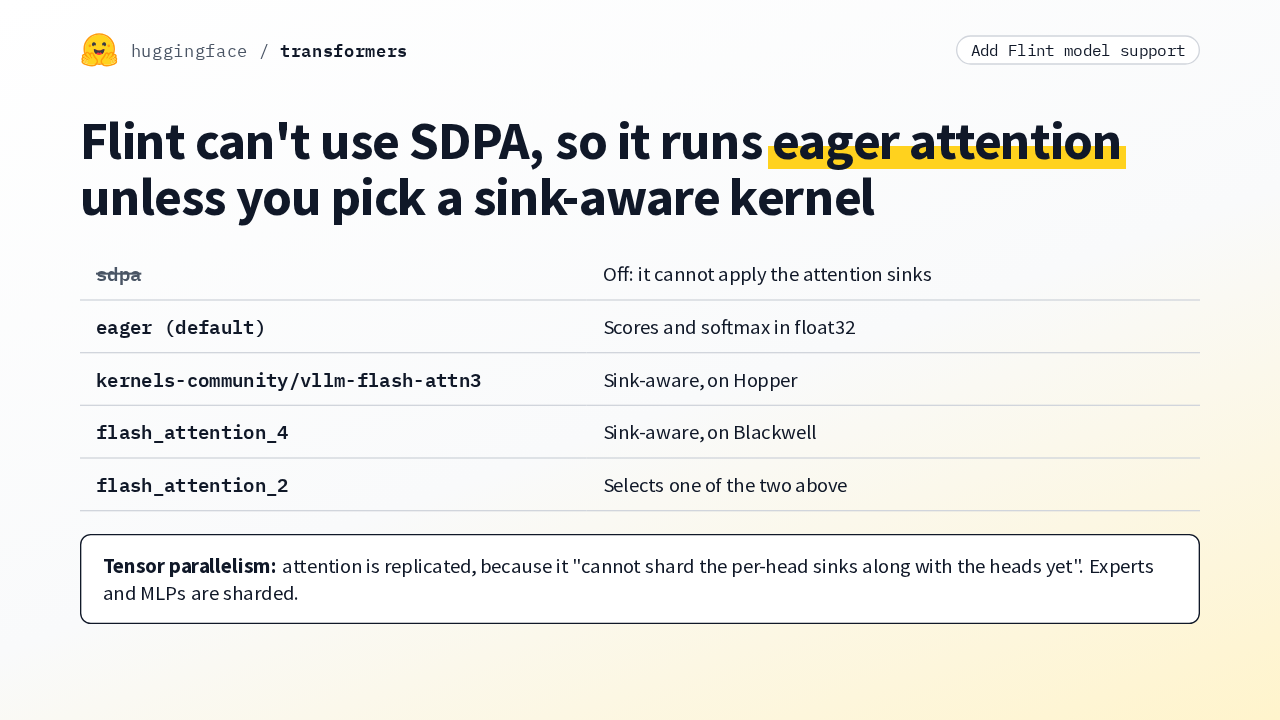
huggingface / transformersAdd Flint model supportFlint can't use SDPA, so it runs eager attention unless you pick a sink-aware kernel
| sdpa | Off: it cannot apply the attention sinks |
| eager (default) | Scores and softmax in float32 |
| kernels-community/vllm-flash-attn3 | Sink-aware, on Hopper |
| flash_attention_4 | Sink-aware, on Blackwell |
| flash_attention_2 | Selects one of the two above |
SDPA cannot apply attention sinks, so Flint switches it off and defaults to eager attention, computed in float32. For long inputs, the docs point to sink-aware FlashAttention kernels: the vLLM flash attention 3 build on Hopper, or flash attention 4 on Blackwell. Asking for flash attention 2 picks one of those instead. And under tensor parallelism, attention stays replicated, because the per-head sinks can't be sharded with the heads yet. Only the experts and the MLPs are split.
Checkpoint format
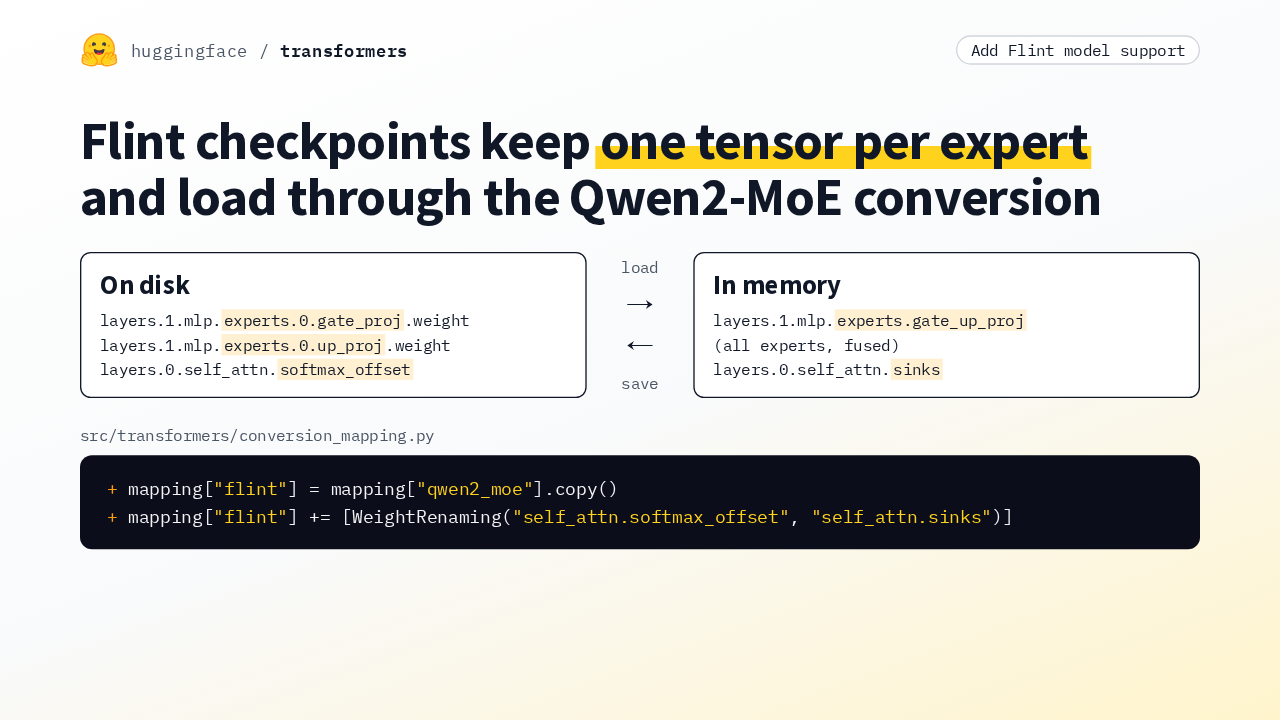
huggingface / transformersAdd Flint model supportFlint checkpoints keep one tensor per expert and load through the Qwen2-MoE conversion
layers.1.mlp.experts.0.up_proj.weight
layers.0.self_attn.softmax_offset
(all experts, fused)
layers.0.self_attn.sinks
+ mapping["flint"] = mapping["qwen2_moe"].copy()
+ mapping["flint"] += [WeightRenaming("self_attn.softmax_offset", "self_attn.sinks")]
On disk, a Flint checkpoint stores one tensor per expert, and it stores the sinks under the name softmax offset. The conversion mapping copies the Qwen2-MoE entry, which fuses the experts on load, and adds one rename from softmax offset to sinks. Saving runs both in reverse, so the model writes back the same format it read.
The tests
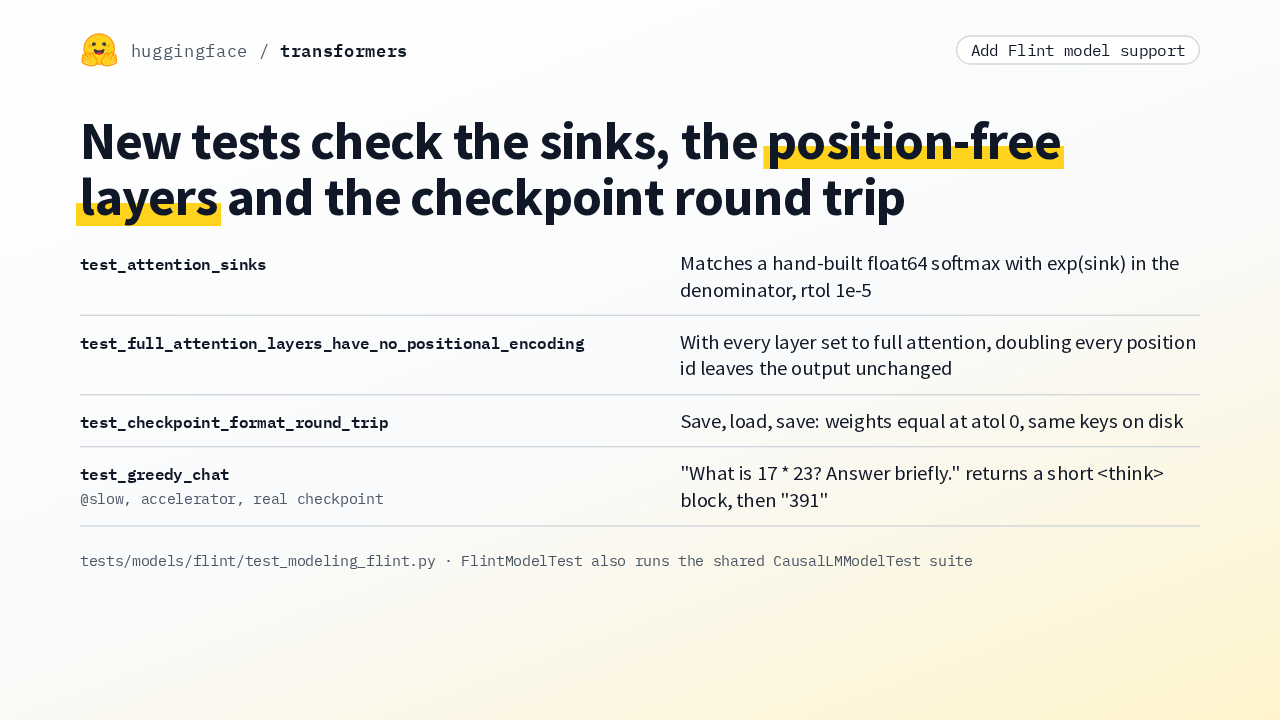
huggingface / transformersAdd Flint model supportNew tests check the sinks, the position-free layers and the checkpoint round trip
The tests check each of those claims directly. The sink test rebuilds attention by hand in float64, adding each sink's exponent to the softmax denominator, and matches it within one part in a hundred thousand. The positional test makes every layer full attention, doubles the position ids, and expects identical output. The round trip saves, reloads and saves again, with exact weights and the same keys. And a slow accelerator test runs the real checkpoint greedily. Asked for 17 times 23, it thinks briefly and answers 391.
What to do with it
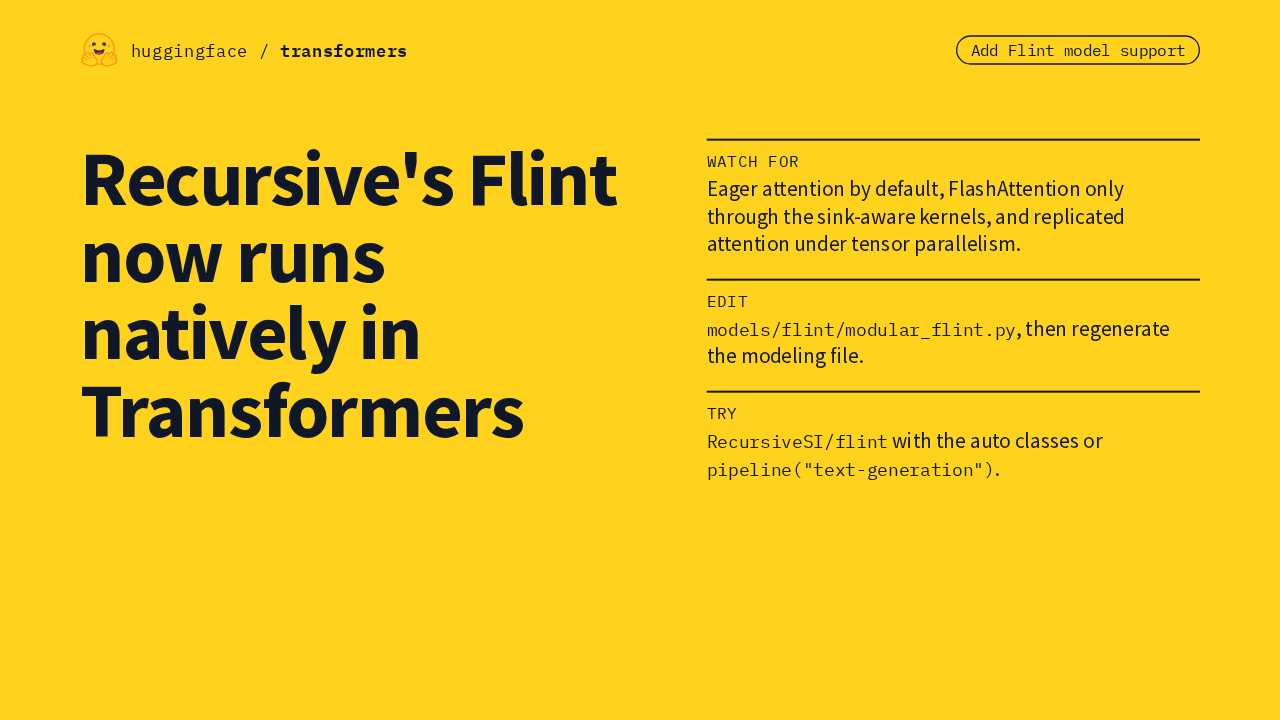
huggingface / transformersAdd Flint model supportRecursive's Flint now runs natively in Transformers
models/flint/modular_flint.py, then regenerate the modeling file.RecursiveSI/flint with the auto classes or pipeline("text-generation").The limit to keep in mind is attention: eager by default, FlashAttention only through the sink-aware kernels, and replicated under tensor parallelism. The rest of the model inherits from the Qwen classes, so to change Flint, edit the modular file and regenerate. To try it, load Recursive's checkpoint with the auto classes or the text generation pipeline. Recursive's Flint now runs natively in Transformers.