WebGPU now runs Q2_0 matrix multiplication.

2 days ago

This change teaches the WebGPU backend to run Q2_0 weights. It adds Q2_0 to the get rows shader and to matrix multiplication with F32 activations. The models it is for are Ternary Bonsai 1.7B and Bonsai 2 2B. Until now their matrix multiplications fell back to the CPU, and with this change they stay on the GPU.

Ask about this presentation

Chapters
  1. 0:00Q2_0 on WebGPU
  2. 0:24Where the work ran
  3. 0:47The Q2_0 block
  4. 1:11Host side: four lines
  5. 1:33Three shaders
  6. 1:55The vector kernel
  7. 2:17Benchmark
  8. 2:43Checked against the CPU
  9. 2:56What stays unsupported
  10. 3:17Q2_0 on WebGPU, merged
Show transcript
  1. This change teaches the WebGPU backend to run Q2_0 weights. It adds Q2_0 to the get rows shader and to matrix multiplication with F32 activations. The models it is for are Ternary Bonsai 1.7B and Bonsai 2 2B. Until now their matrix multiplications fell back to the CPU, and with this change they stay on the GPU.

    Slide text
    llama.cpp
    ggml · WebGPU

    WebGPU now runs Q2_0 matrix multiplication.

    Ternary Bonsai 1.7B and Bonsai 2 2B stop falling back to the CPU for matrix multiplication.

    GET_ROWS
    MUL_MAT with F32 activations
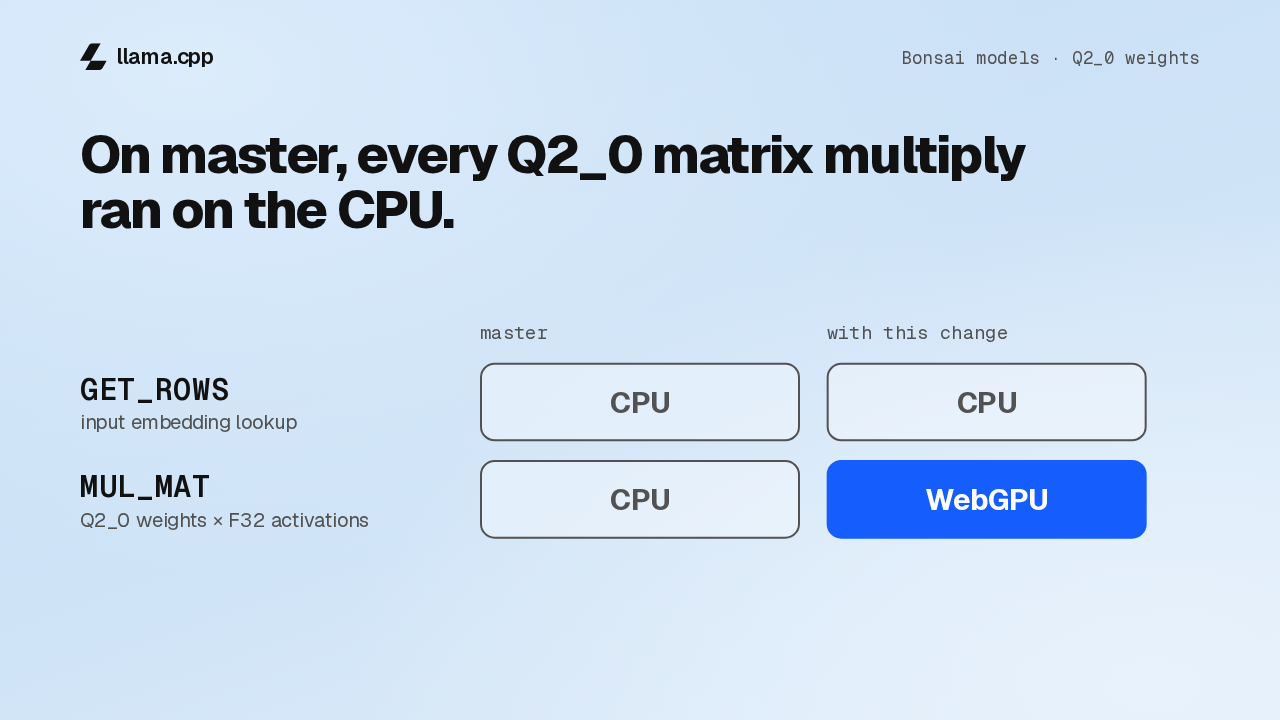
  2. Here is what that meant on master. The scheduler asks each backend whether it supports an operation, and WebGPU said no to Q2_0. So the embedding lookup and every matrix multiply over those weights ran on the CPU. With this change the matrix multiplies move to WebGPU. The input embedding lookup still runs on the CPU for both models.

    Slide text
    llama.cpp
    Bonsai models · Q2_0 weights

    On master, every Q2_0 matrix multiply ran on the CPU.

    master
    with this change
    GET_ROWS input embedding lookup
    CPU
    CPU
    MUL_MAT Q2_0 weights × F32 activations
    CPU
    WebGPU
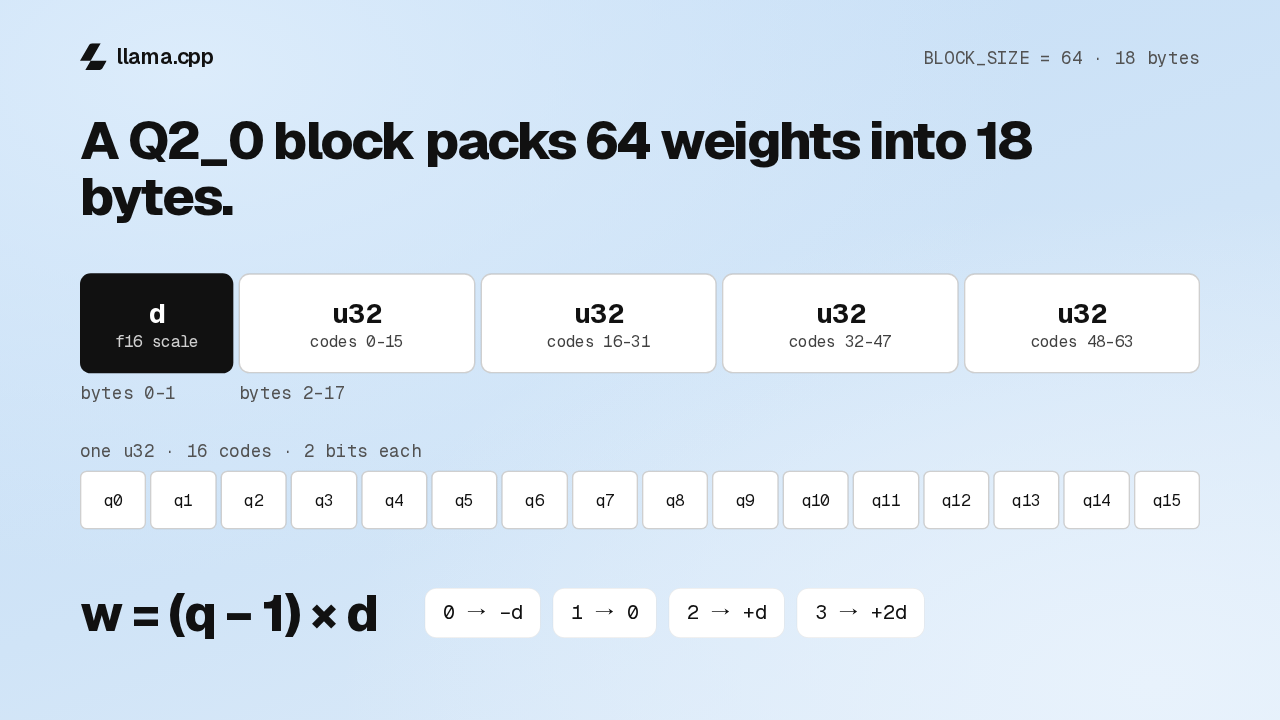
  3. The format is compact. Each block holds 64 weights in 18 bytes, and the first two bytes are a half precision scale, d. The other 16 bytes are read as four 32-bit words, and each word carries 16 two-bit codes. A code q decodes to q minus one, times d. So zero, one and two give minus d, zero and plus d, the three values a ternary model needs.

    Slide text
    llama.cpp
    BLOCK_SIZE = 64 · 18 bytes

    A Q2_0 block packs 64 weights into 18 bytes.

    d f16 scale
    u32 codes 0–15
    u32 codes 16–31
    u32 codes 32–47
    u32 codes 48–63
    bytes 0–1
    bytes 2–17
    one u32 · 16 codes · 2 bits each
    q0
    q1
    q2
    q3
    q4
    q5
    q6
    q7
    q8
    q9
    q10
    q11
    q12
    q13
    q14
    q15
    w = (q − 1) × d
    0 → −d
    1 → 0
    2 → +d
    3 → +2d
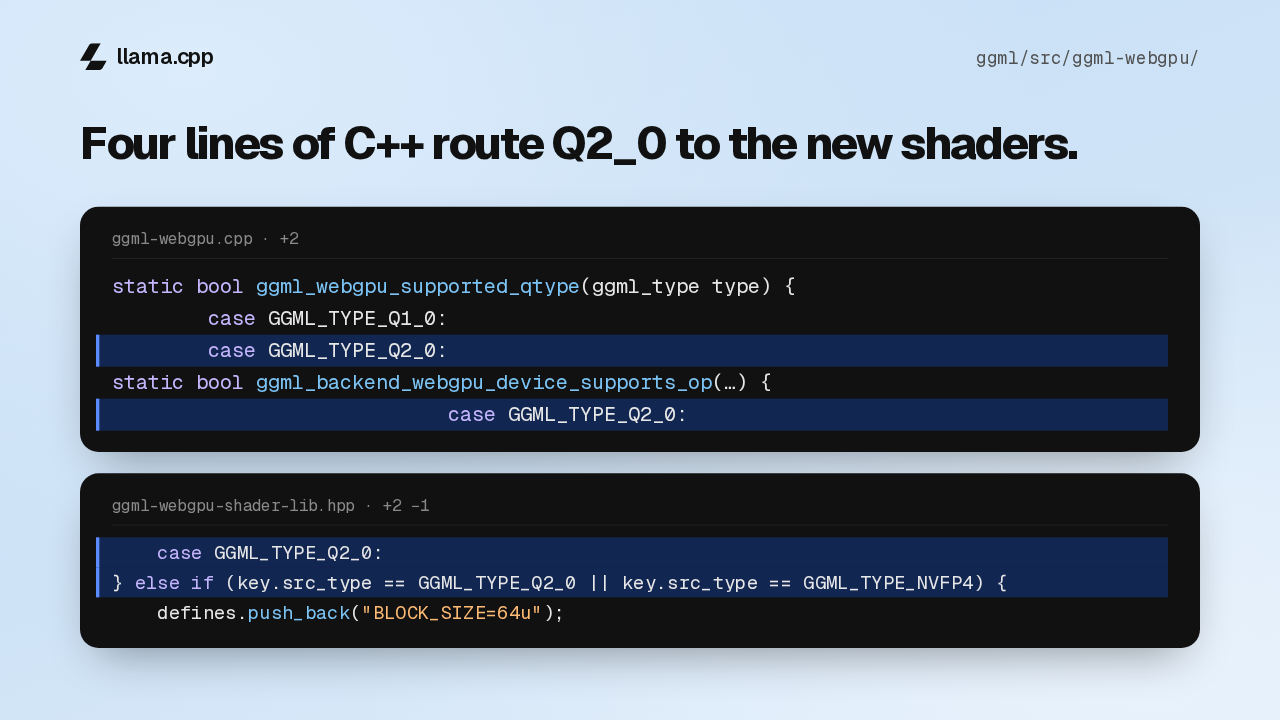
  4. On the host side the change is small. In ggml-webgpu.cpp, Q2_0 joins the supported quant types, and supports op now says yes to it. In the shader library, Q2_0 joins the same switch as Q1_0 and Q4_0, and gets a block size of 64, the define NVFP4 already uses.

    Slide text
    llama.cpp
    ggml/src/ggml-webgpu/

    Four lines of C++ route Q2_0 to the new shaders.

    ggml-webgpu.cpp · +2
    static bool ggml_webgpu_supported_qtype(ggml_type type) {
            case GGML_TYPE_Q1_0:
            case GGML_TYPE_Q2_0:static bool ggml_backend_webgpu_device_supports_op(…) {
                                case GGML_TYPE_Q2_0:
    ggml-webgpu-shader-lib.hpp · +2 −1
        case GGML_TYPE_Q2_0:} else if (key.src_type == GGML_TYPE_Q2_0 || key.src_type == GGML_TYPE_NVFP4) {    defines.push_back("BLOCK_SIZE=64u");
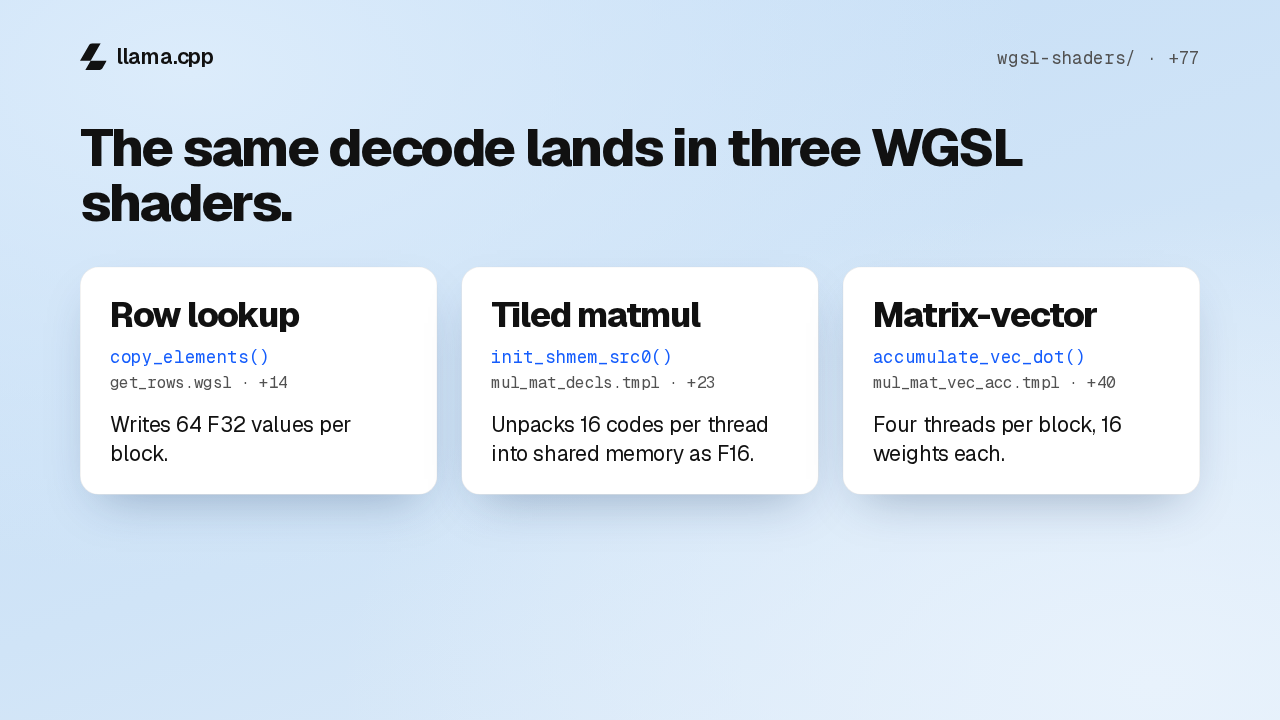
  5. The decode itself appears in three shaders. The get rows shader copies rows out of a Q2_0 tensor and writes 64 floats per block. The tiled matrix multiply unpacks 16 codes per thread into shared memory, as half precision. And the matrix-vector kernel splits each block across four threads, 16 weights apiece.

    Slide text
    llama.cpp
    wgsl-shaders/ · +77

    The same decode lands in three WGSL shaders.

    Row lookup
    copy_elements()
    get_rows.wgsl · +14

    Writes 64 F32 values per block.

    Tiled matmul
    init_shmem_src0()
    mul_mat_decls.tmpl · +23

    Unpacks 16 codes per thread into shared memory as F16.

    Matrix-vector
    accumulate_vec_dot()
    mul_mat_vec_acc.tmpl · +40

    Four threads per block, 16 weights each.

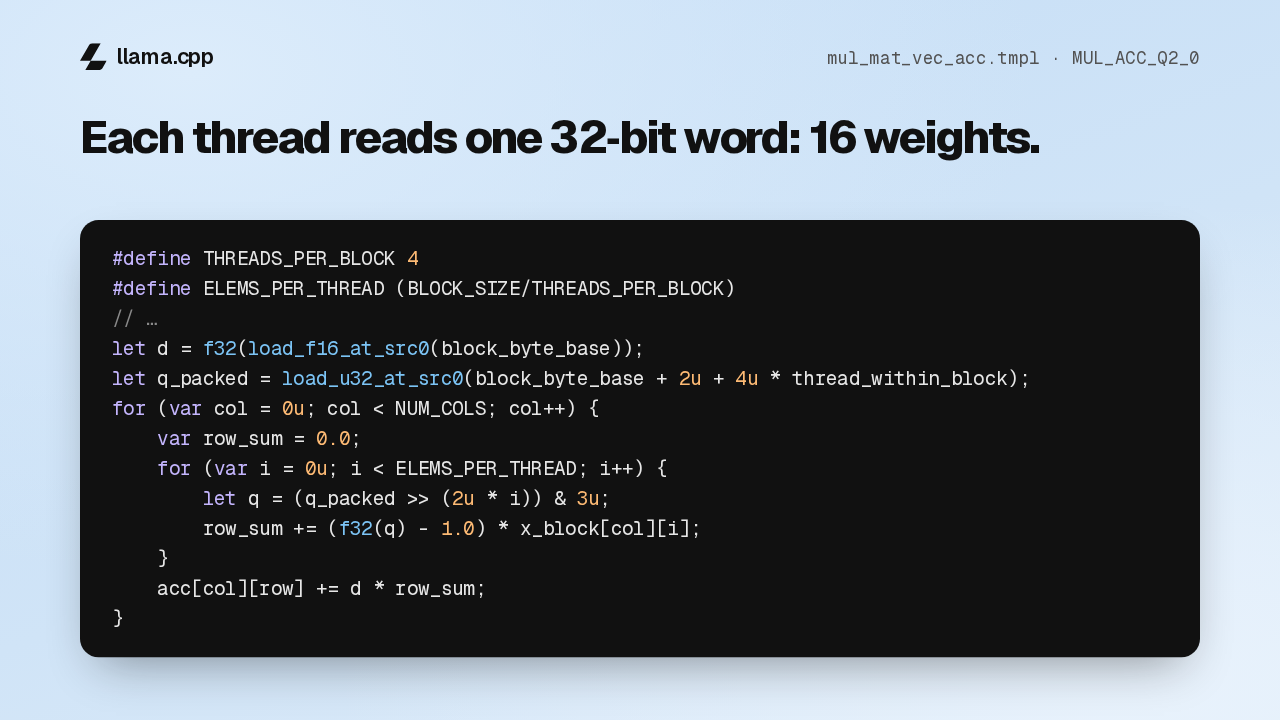
  6. Here is that kernel. Four threads share each 64 weight block, so each thread owns 16 weights. A thread loads the block's scale, then exactly one 32-bit word, which holds its 16 codes. Each code is shifted out two bits at a time, decoded as q minus one, and multiplied by the activation. The scale is applied once, after the sum.

    Slide text
    llama.cpp
    mul_mat_vec_acc.tmpl · MUL_ACC_Q2_0

    Each thread reads one 32‑bit word: 16 weights.

    #define THREADS_PER_BLOCK 4
    #define ELEMS_PER_THREAD (BLOCK_SIZE/THREADS_PER_BLOCK)
    // …
    let d = f32(load_f16_at_src0(block_byte_base));
    let q_packed = load_u32_at_src0(block_byte_base + 2u + 4u * thread_within_block);
    for (var col = 0u; col < NUM_COLS; col++) {
        var row_sum = 0.0;
        for (var i = 0u; i < ELEMS_PER_THREAD; i++) {
            let q = (q_packed >> (2u * i)) & 3u;
            row_sum += (f32(q) - 1.0) * x_block[col][i];
        }
        acc[col][row] += d * row_sum;
    }
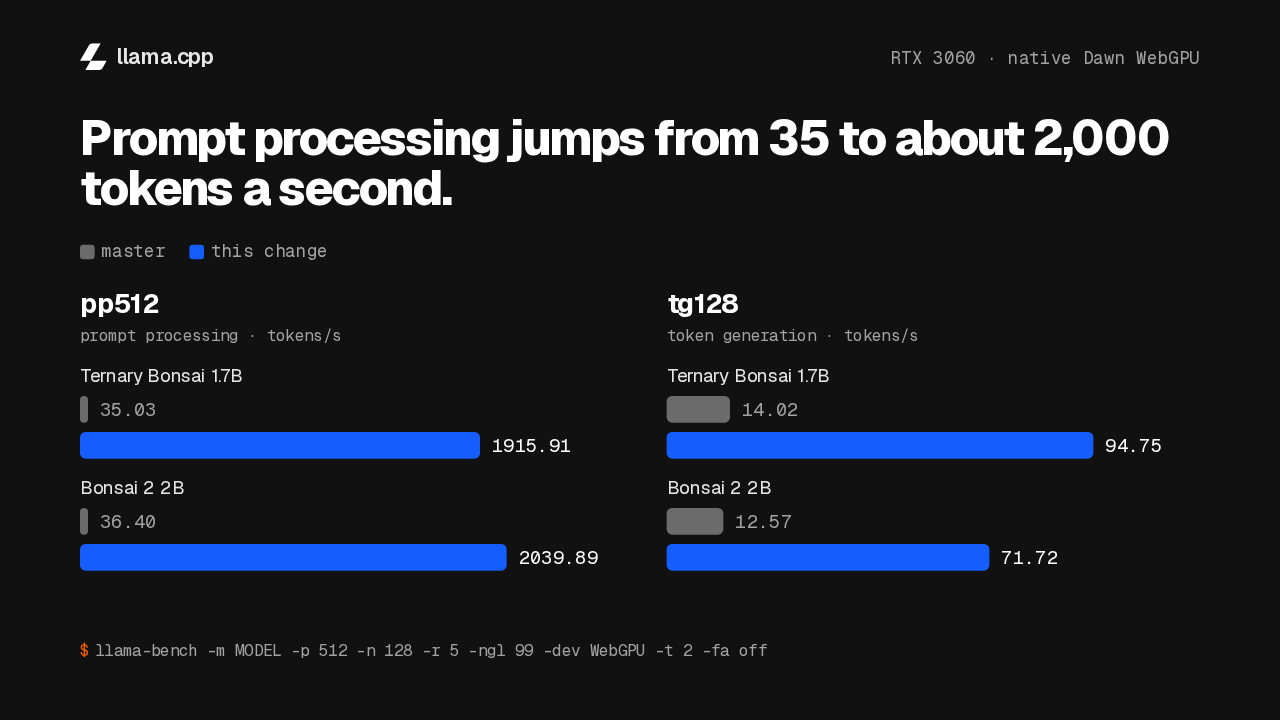
  7. On an RTX 3060 with native Dawn WebGPU, prompt processing for Ternary Bonsai 1.7B goes from 35 tokens a second to about 1,900. Bonsai 2 2B lands just over 2,000. Token generation goes from 14 to about 95 tokens a second on the smaller model, and from about 13 to about 72 on Bonsai 2.

    Slide text
    llama.cpp
    RTX 3060 · native Dawn WebGPU

    Prompt processing jumps from 35 to about 2,000 tokens a second.

    master this change

    pp512

    prompt processing · tokens/s
    Ternary Bonsai 1.7B
    35.03
    1915.91
    Bonsai 2 2B
    36.40
    2039.89

    tg128

    token generation · tokens/s
    Ternary Bonsai 1.7B
    14.02
    94.75
    Bonsai 2 2B
    12.57
    71.72
    $llama-bench -m MODEL -p 512 -n 128 -r 5 -ngl 99 -dev WebGPU -t 2 -fa off
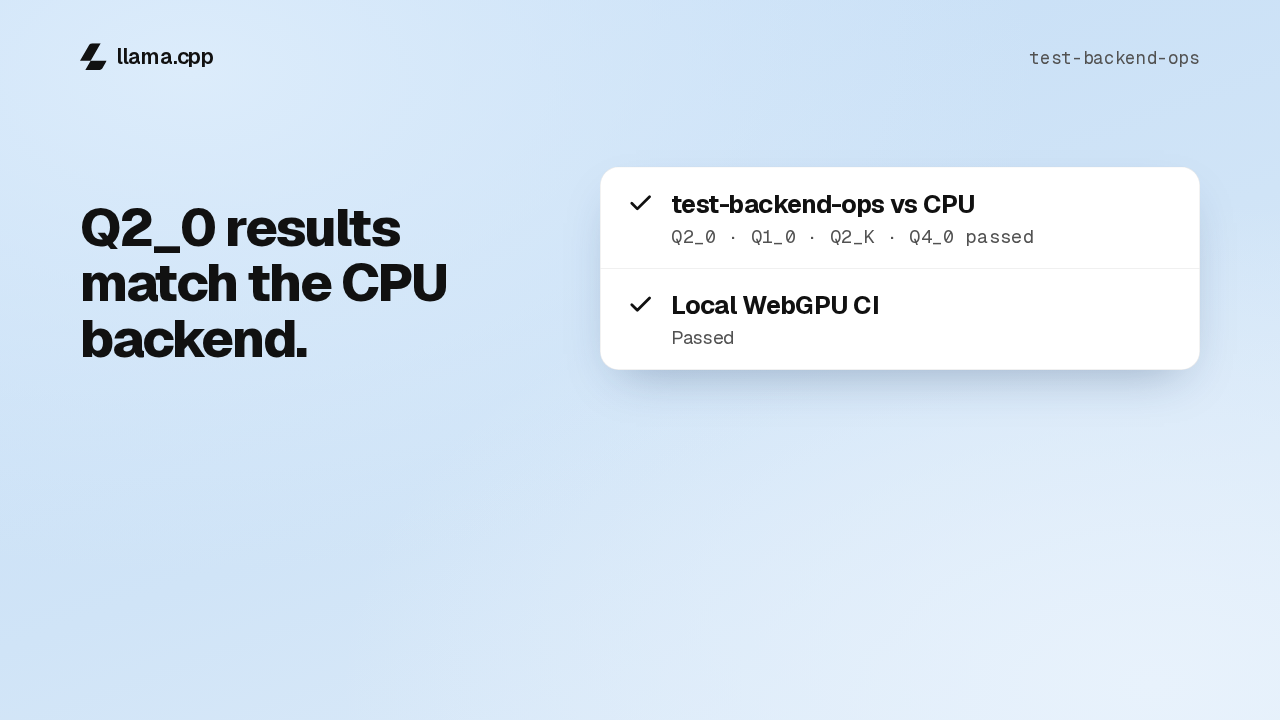
  8. Correctness is checked against the CPU backend. Q2_0 passes test backend ops there, and so do Q1_0, Q2_K and Q4_0. And the local WebGPU CI run passed.

    Slide text
    llama.cpp
    test-backend-ops

    Q2_0 results match the CPU backend.

    test-backend-ops vs CPU Q2_0 · Q1_0 · Q2_K · Q4_0 passed
    Local WebGPU CI Passed
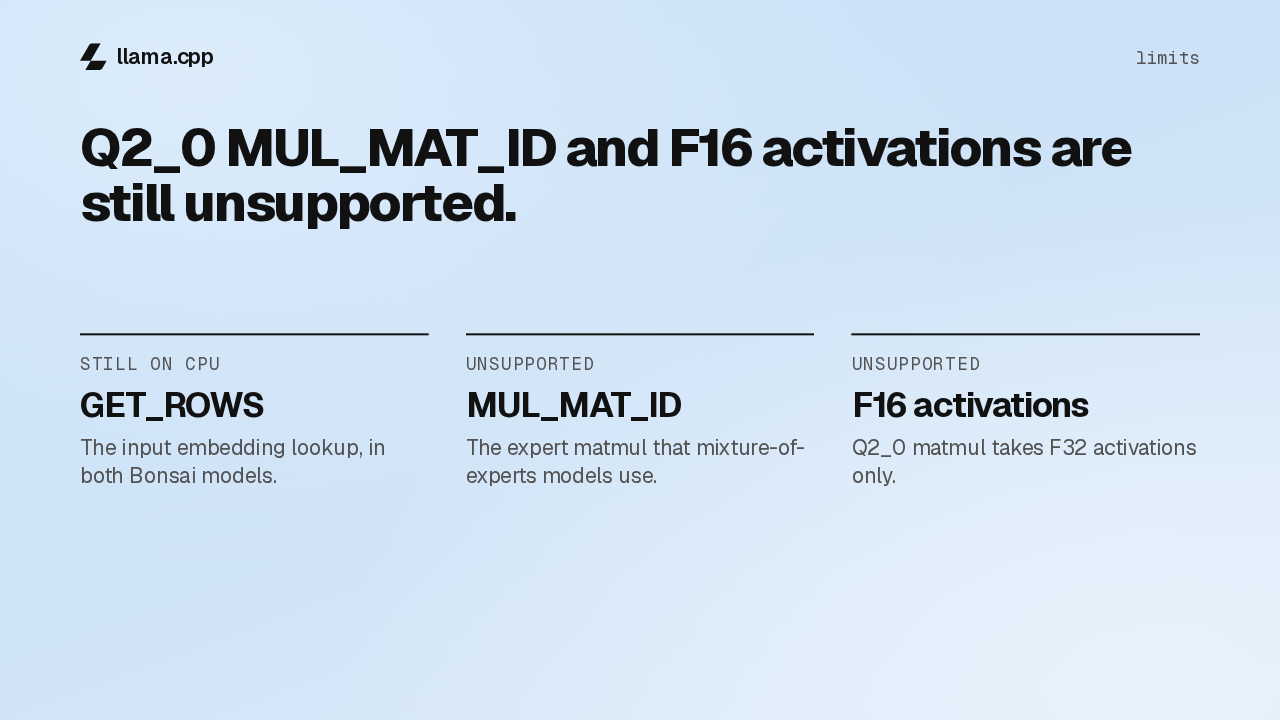
  9. The change stops short in a few places. The input embedding lookup still runs on the CPU in both Bonsai models. Q2_0 isn't supported in the expert matrix multiply that mixture of experts models use. And activations have to be F32, because F16 activations aren't supported for Q2_0.

    Slide text
    llama.cpp
    limits

    Q2_0 MUL_MAT_ID and F16 activations are still unsupported.

    still on CPU
    GET_ROWS The input embedding lookup, in both Bonsai models.
    unsupported
    MUL_MAT_ID The expert matmul that mixture-of-experts models use.
    unsupported
    F16 activations Q2_0 matmul takes F32 activations only.
  10. So the scope is dense Q2_0 models with F32 activations, and the embedding lookup stays on the CPU. Within that, Ternary Bonsai 1.7B and Bonsai 2 2B now multiply on the GPU, and prompt processing went from 35 to about 2,000 tokens a second. It's merged, so if you run Q2_0 models on WebGPU, pull master and run llama bench on your own card.
    Slide text
    llama.cpp
    merged into master

    Q2_0 matrix multiplies run on WebGPU now.

    Dense Q2_0 models with F32 activations. The embedding lookup stays on the CPU.

    github.com/ggml-org/llama.cpp/pull/30914

What happened in AI today, in your inbox

One short email each evening. Read it and you’re caught up.

Built in New York with ❤️