whisper.cpp v1.9.5

whisper.cpp v1.9.5 runs the encoder on Apple’s Neural Engine
ANEForge, an optional backend that bypasses Core ML
On an Apple Silicon Mac, whisper.cpp can now run the Whisper encoder directly on the Apple Neural Engine through ANEForge. It is opt-in, and with it switched off, whisper.cpp behaves exactly as before.
Twice as fast as Core ML
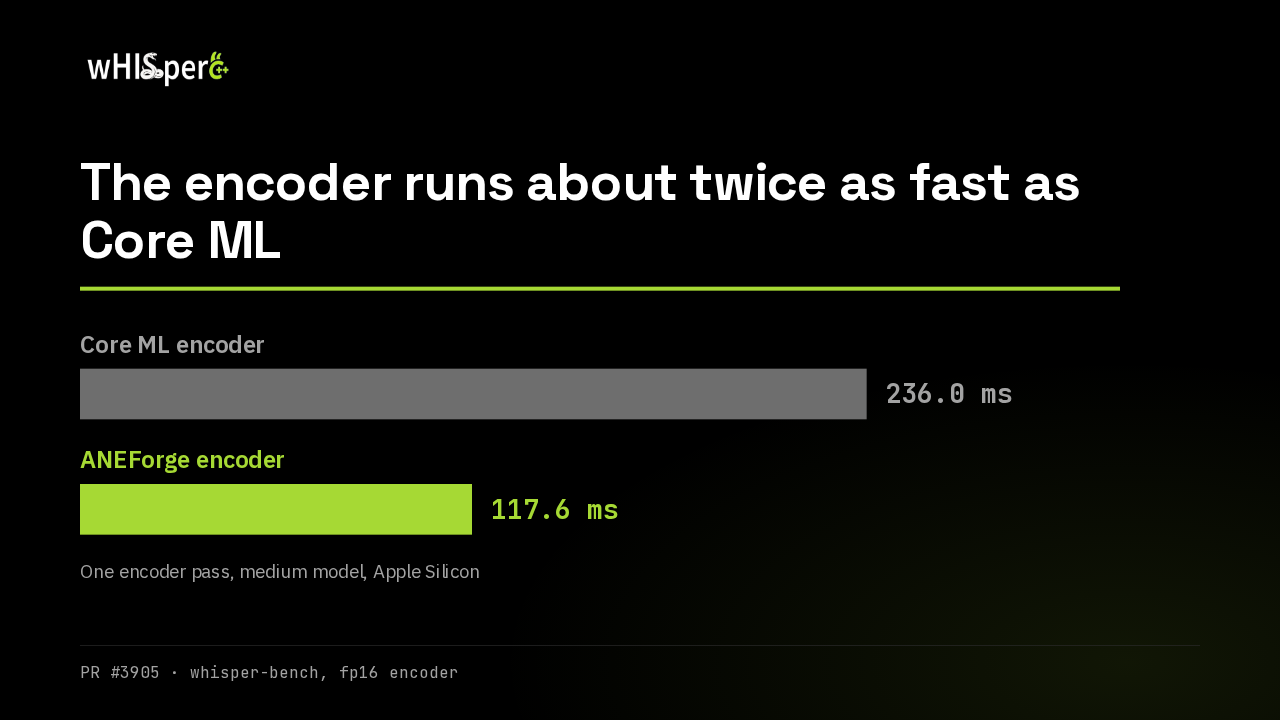
The encoder runs about twice as fast as Core ML
One encoder pass, medium model, Apple Silicon
On the medium model, one encoder pass drops from about 240 milliseconds with Core ML to under 120. The gap holds from the tiny model up to medium, and the transcripts come out the same.
whisper-cli exit codes
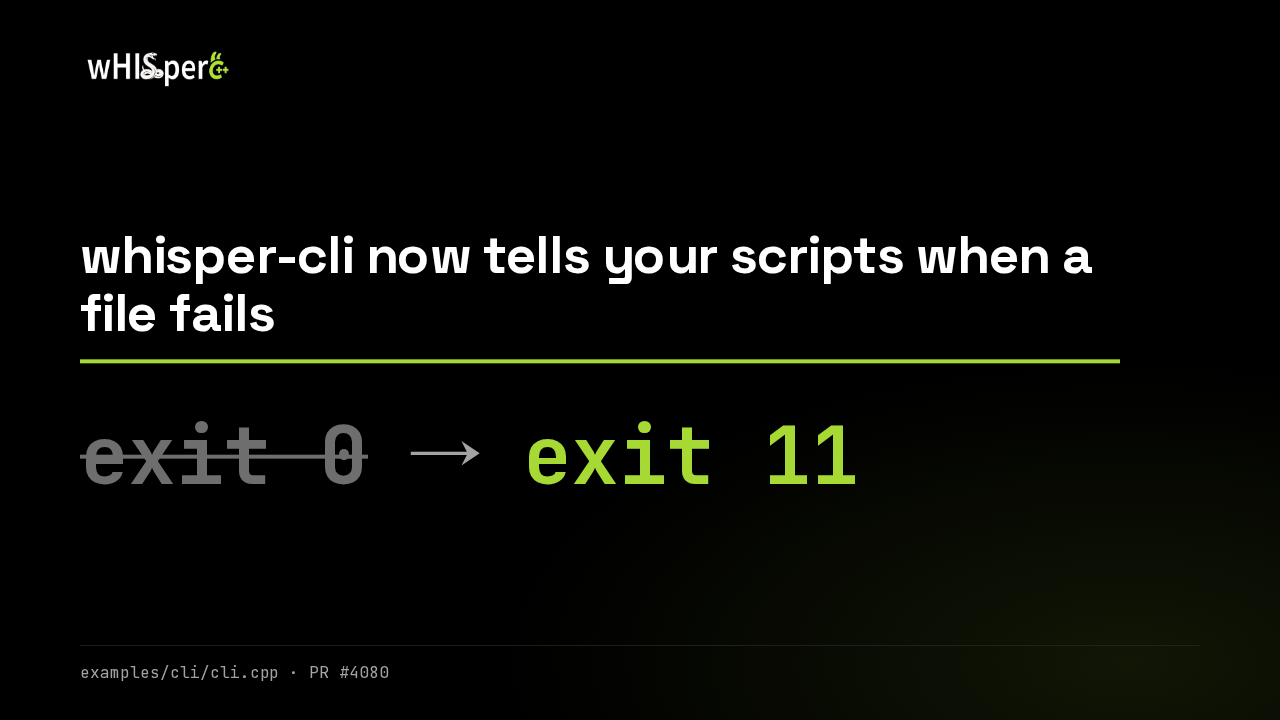
whisper-cli now tells your scripts when a file fails
whisper-cli used to exit with success even when an input file was missing, its audio couldn't be decoded, or the output couldn't be written. Now it finishes the batch and exits with code 11.
Long-file timestamps
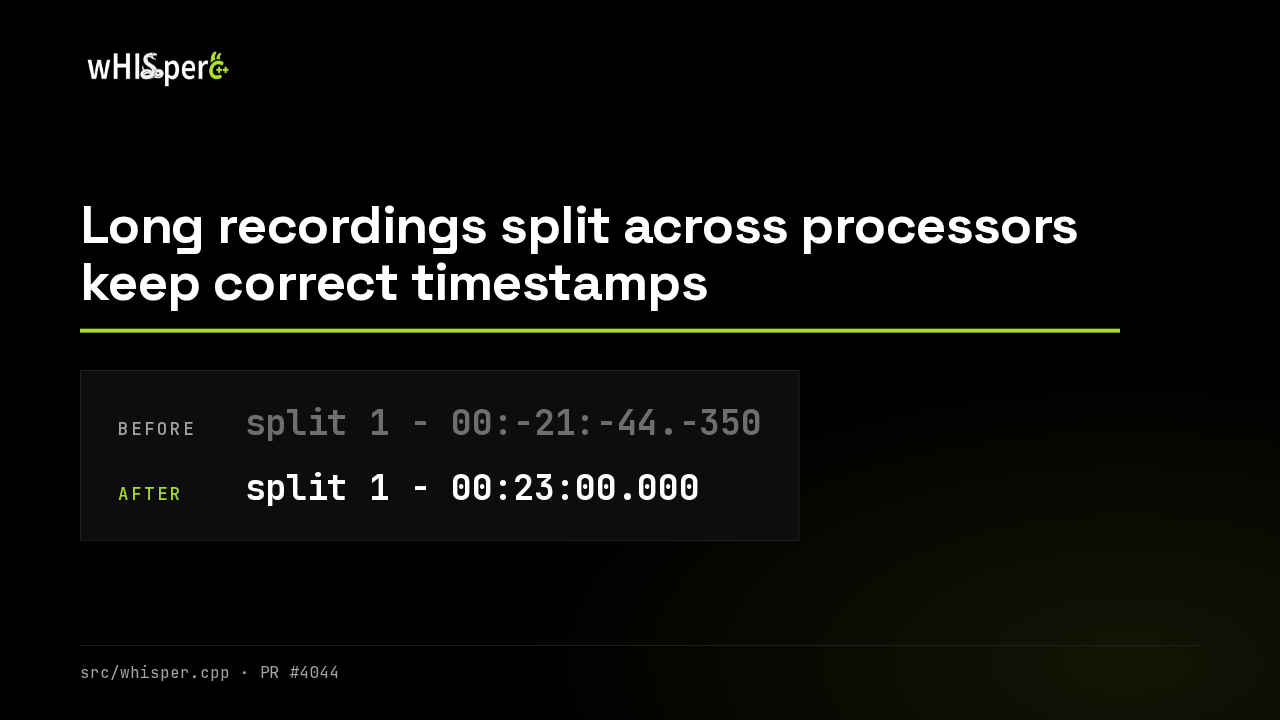
Long recordings split across processors keep correct timestamps
With the processors option on a long file, every timestamp past about 22 minutes could come out negative, mostly on Windows builds. An integer overflow caused it, and those timestamps are now correct.
Three more fixes
Cancelling, Docker and bad model files
- +The abort callback now stops language auto-detection
- +Vulkan Docker image: 1.75 GB down to 692 MB
- +Malformed model files are rejected instead of crashing
Apps can now cancel a transcription while it is still detecting the language. The Vulkan Docker image drops from almost two gigabytes to under 700 megabytes, and a malformed model file now fails to load instead of crashing.
ANEForge limits
ANEForge speeds up the encoder only, on Apple Silicon
The decoder is unchanged. You compile the encoder bundle on your own Mac, tied to its macOS build, and it relies on undocumented Apple interfaces that an update can change. The README's ANEForge section has the setup.