Vertex AI settings in config.toml
 >_ OpenAI Codex
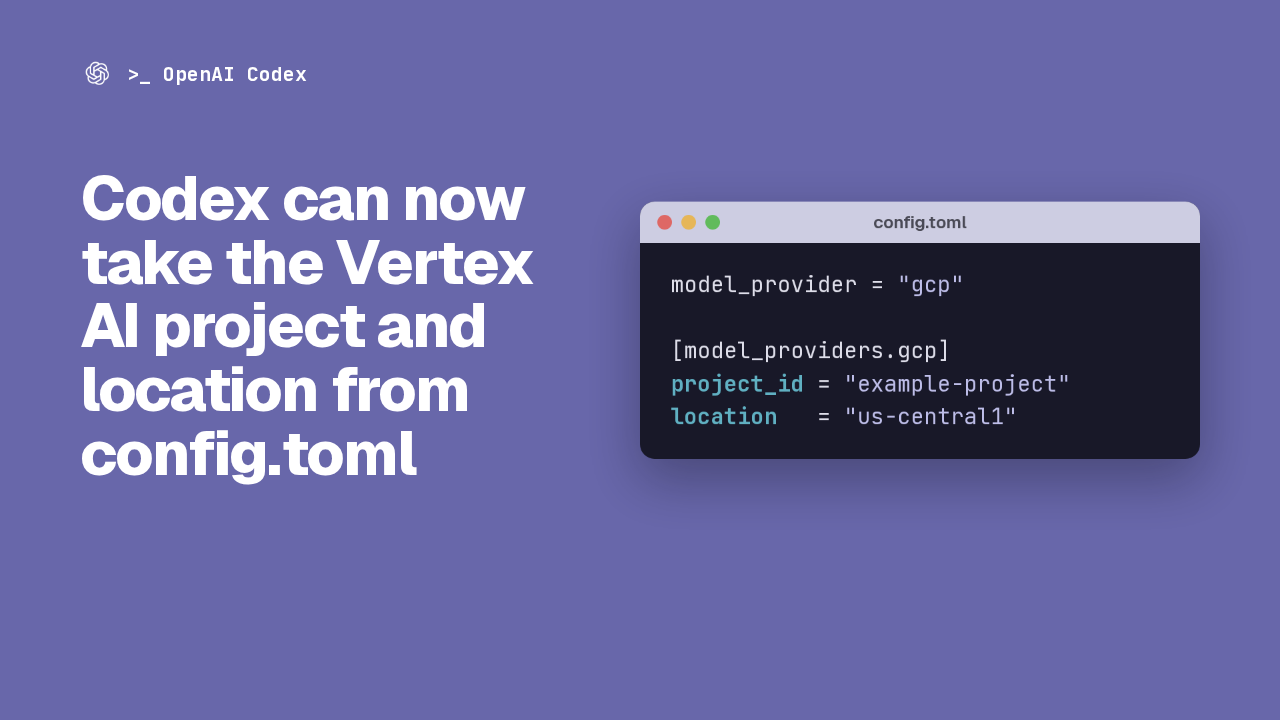
Codex can now take the Vertex AI project and location from config.toml
model_provider = "gcp"

[model_providers.gcp]
project_id = "example-project"
location   = "us-central1"
This change lets Codex reach Vertex AI with two new settings on the built-in GCP provider. Under model_providers.gcp, you can now set a project ID and a location, right beside the provider choice. Codex builds the Vertex endpoint from them, so a Google Cloud setup can live in config.toml instead of the shell environment.
Why: environment variables only
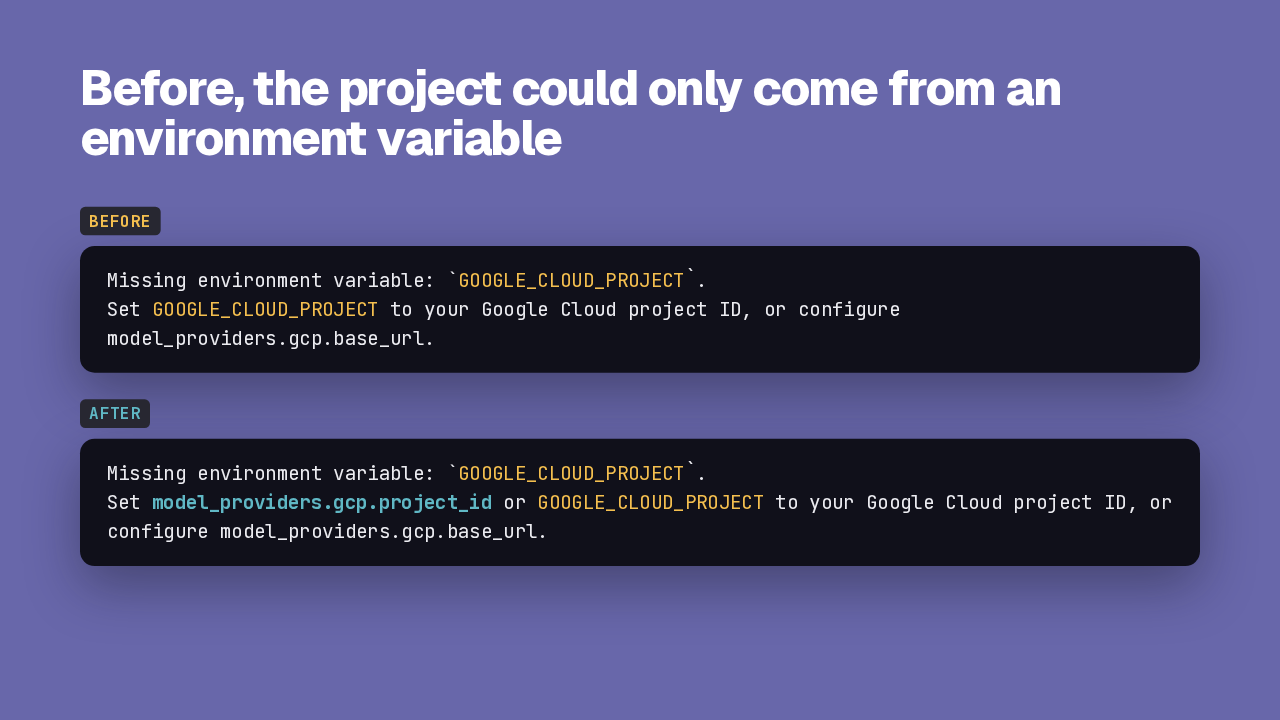
Before, the project could only come from an environment variable
Missing environment variable: `GOOGLE_CLOUD_PROJECT`.
Set GOOGLE_CLOUD_PROJECT to your Google Cloud project ID, or configure model_providers.gcp.base_url.
Missing environment variable: `GOOGLE_CLOUD_PROJECT`.
Set model_providers.gcp.project_id or GOOGLE_CLOUD_PROJECT to your Google Cloud project ID, or configure model_providers.gcp.base_url.
Deriving a Vertex AI endpoint used to require environment variables. Leave GOOGLE_CLOUD_PROJECT unset, and this was the whole instruction you got. The same error now names the new config key first, then the variable, then the base URL override.
Part 1: Resolving the endpoint
Resolving the endpoint
First, how Codex picks the endpoint now.
Config, then environment, then default
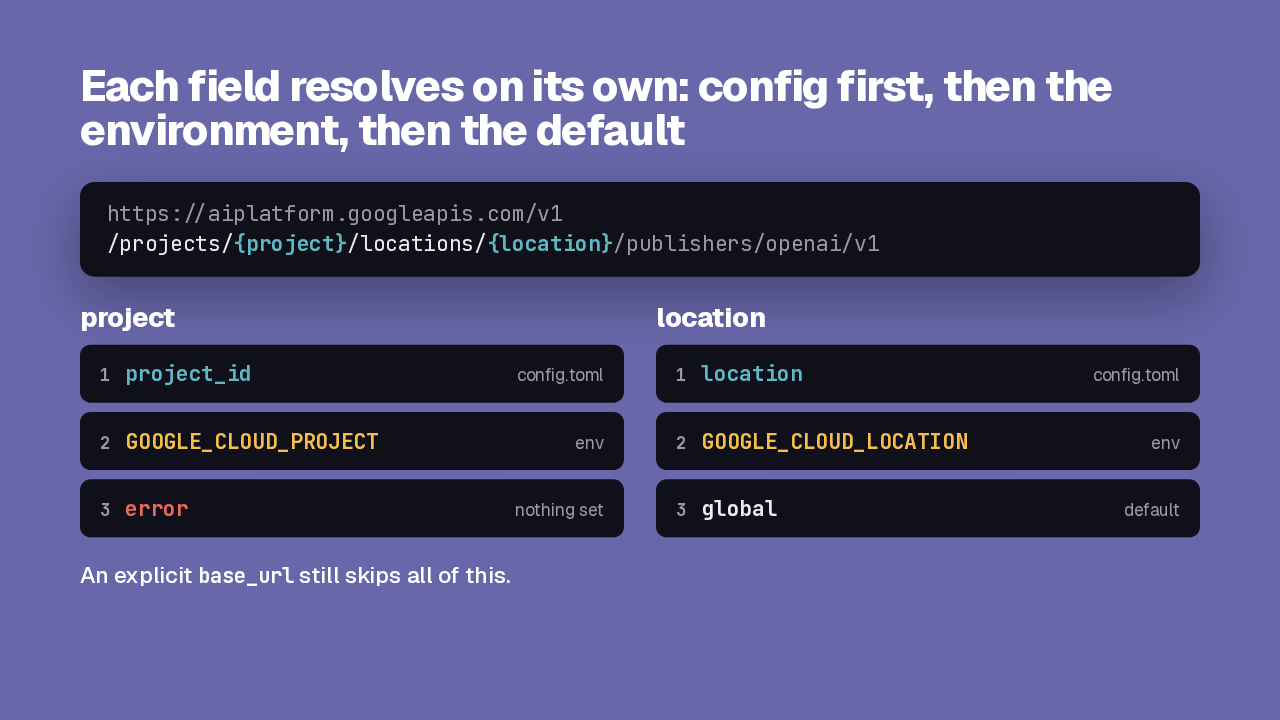
Each field resolves on its own: config first, then the environment, then the default
https://aiplatform.googleapis.com/v1
/projects/{project}/locations/{location}/publishers/openai/v1
An explicit base_url still skips all of this.
The endpoint has two slots. A project and a location, inside the Vertex AI publishers path for OpenAI. The project comes from the configured project ID first, then GOOGLE_CLOUD_PROJECT, and with neither set you get the error from before. Location follows the same order and still lands on global by default. And an explicit base URL bypasses all of it, as it did before.
The new vertex_base_url
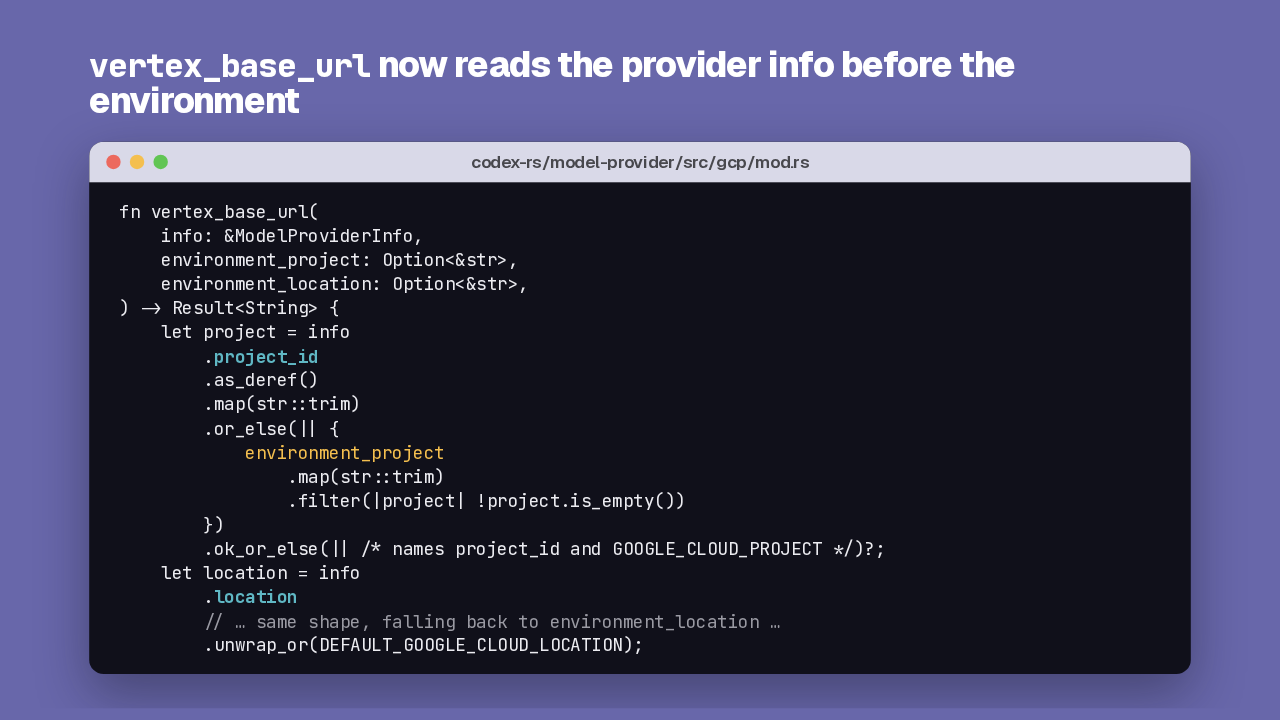
vertex_base_url now reads the provider info before the environment
fn vertex_base_url(
    info: &ModelProviderInfo,
    environment_project: Option<&str>,
    environment_location: Option<&str>,
) -> Result<String> {
    let project = info
        .project_id
        .as_deref()
        .map(str::trim)
        .or_else(|| {
            environment_project
                .map(str::trim)
                .filter(|project| !project.is_empty())
        })
        .ok_or_else(|| /* names project_id and GOOGLE_CLOUD_PROJECT */)?;
    let location = info
        .location
        // … same shape, falling back to environment_location …
        .unwrap_or(DEFAULT_GOOGLE_CLOUD_LOCATION);
Here is the function that does it, in the GCP model provider. It now takes the provider info beside the two environment values. The project starts from the configured project ID, trimmed. Only when that field is absent does it read the environment, and only the environment value is filtered for empty strings. Location has the same shape. So an empty configured project is kept, and fails validation.
An empty project_id fails
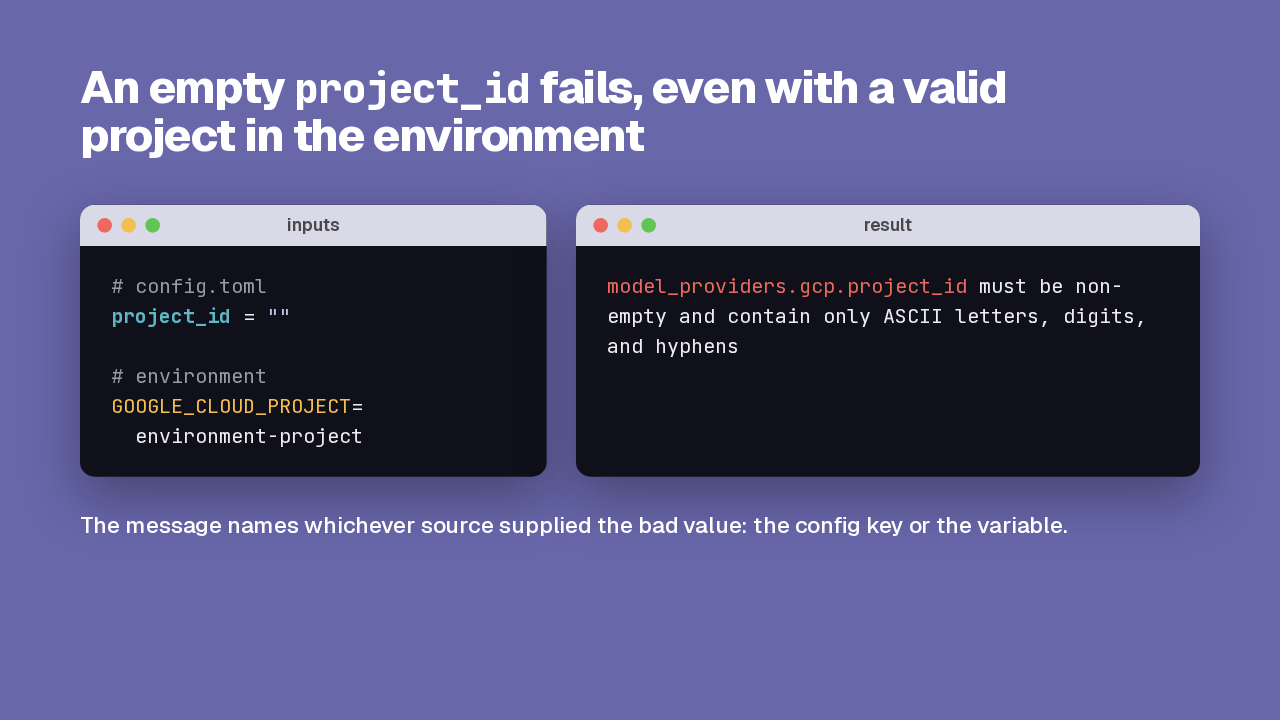
An empty project_id fails, even with a valid project in the environment
# config.toml
project_id = ""

# environment
GOOGLE_CLOUD_PROJECT=
  environment-project
model_providers.gcp.project_id must be non-empty and contain only ASCII letters, digits, and hyphens
The message names whichever source supplied the bad value: the config key or the variable.
An invalid value you set yourself now stops Codex. Set the project ID to an empty string while the environment holds a good project, and you get this error. The message names whichever source supplied the bad value, the config key or the environment variable.
Part 2: Carrying the fields through Codex
Carrying the fields through Codex
Next, everywhere the two fields have to travel.
Where project_id and location travel
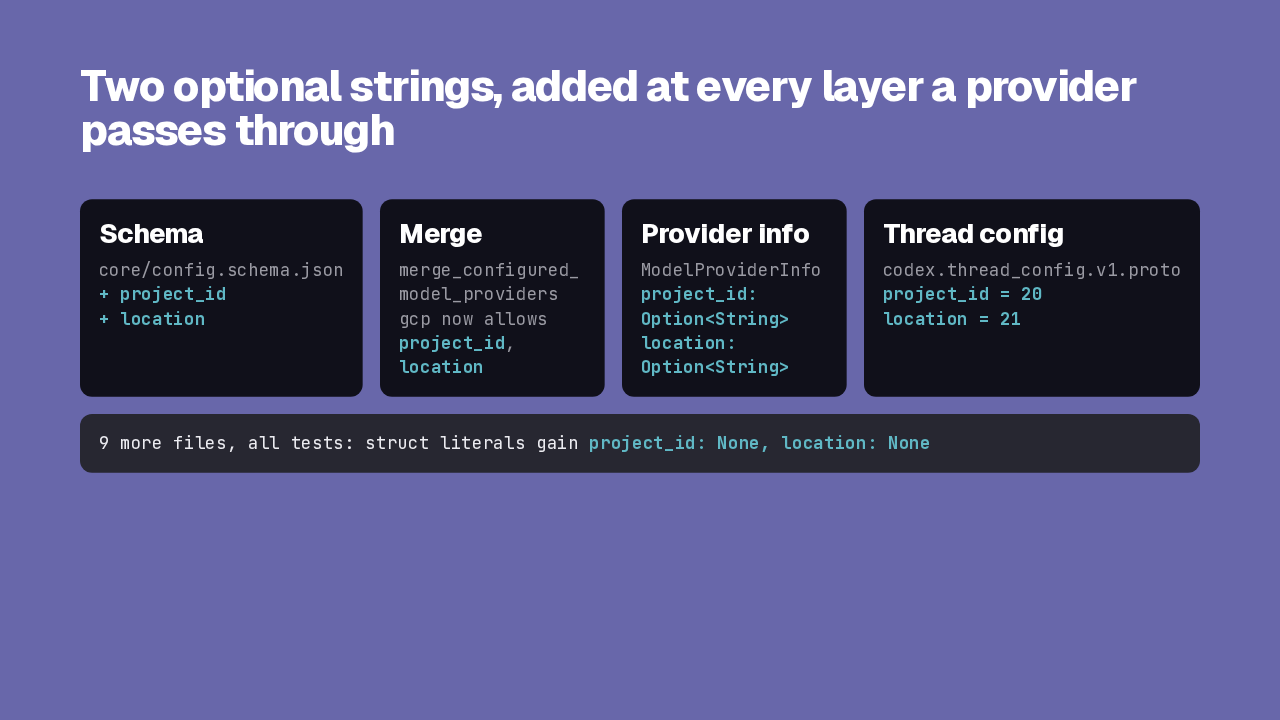
Two optional strings, added at every layer a provider passes through
Schema
core/config.schema.json
+ project_id
+ location
Merge
merge_configured_model_providers
gcp now allows project_id, location
Provider info
ModelProviderInfo
project_id: Option<String>
location: Option<String>
Thread config
codex.thread_config.v1.proto
project_id = 20
location = 21
9 more files, all tests: struct literals gain project_id: None, location: None
The fields have to survive every layer a provider passes through. The config schema gains both properties, and the merge step widens the list of GCP overrides it accepts, which used to stop at base URL, auth and HTTP headers. Model provider info carries them as two optional strings. The thread config proto adds fields 20 and 21, so remote thread configuration round-trips them. The other nine files are all tests, and the change there is mechanical: each struct literal gains two None fields.
Managed GCP requirements
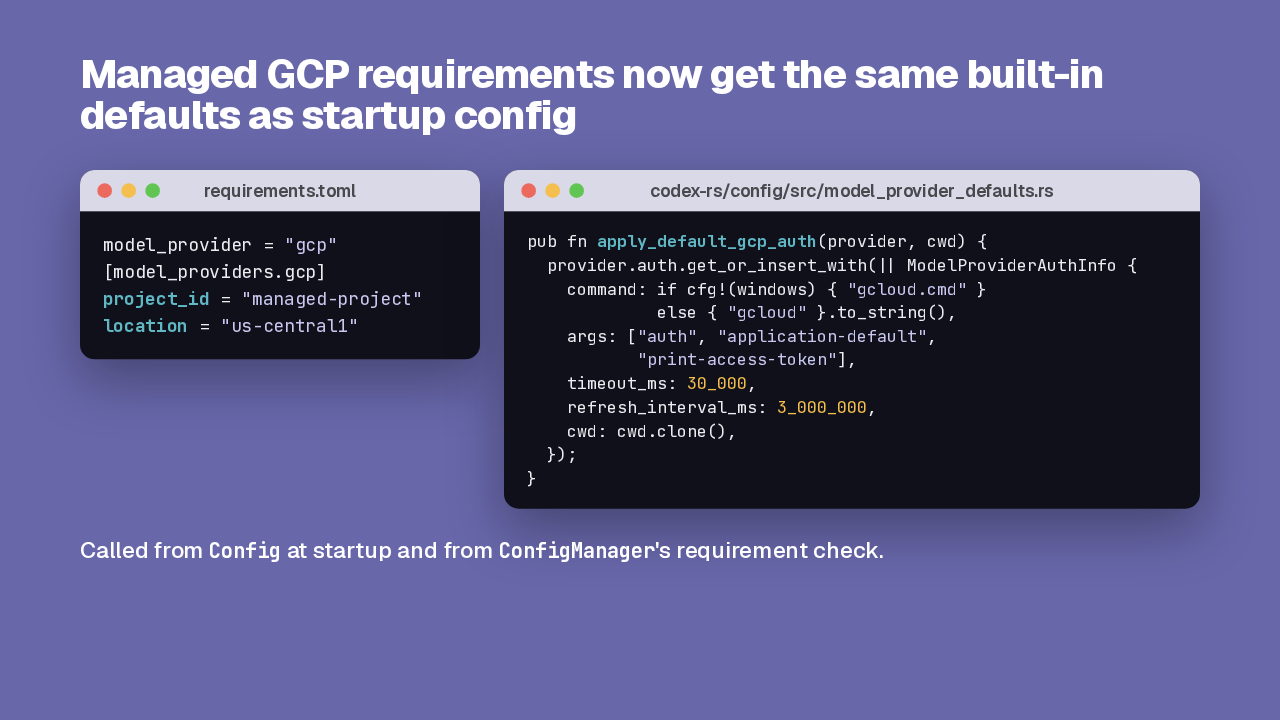
Managed GCP requirements now get the same built-in defaults as startup config
model_provider = "gcp"
[model_providers.gcp]
project_id = "managed-project"
location = "us-central1"
pub fn apply_default_gcp_auth(provider, cwd) {
  provider.auth.get_or_insert_with(|| ModelProviderAuthInfo {
    command: if cfg!(windows) { "gcloud.cmd" }
             else { "gcloud" }.to_string(),
    args: ["auth", "application-default",
           "print-access-token"],
    timeout_ms: 30_000,
    refresh_interval_ms: 3_000_000,
    cwd: cwd.clone(),
  });
}
Called from Config at startup and from ConfigManager's requirement check.
The app server also checks managed requirements against the running provider. That check used to merge built-in defaults only for Bedrock. Now GCP gets the same treatment. It also applies the default gcloud auth command, with a thirty second timeout and a refresh every fifty minutes. That block moved out of the core config loader into one shared function, so startup and the requirement check build the same provider, and unchanged requirements are accepted.
Part 3: Evidence
Evidence
Finally, what the tests pin down.
Each field resolves independently
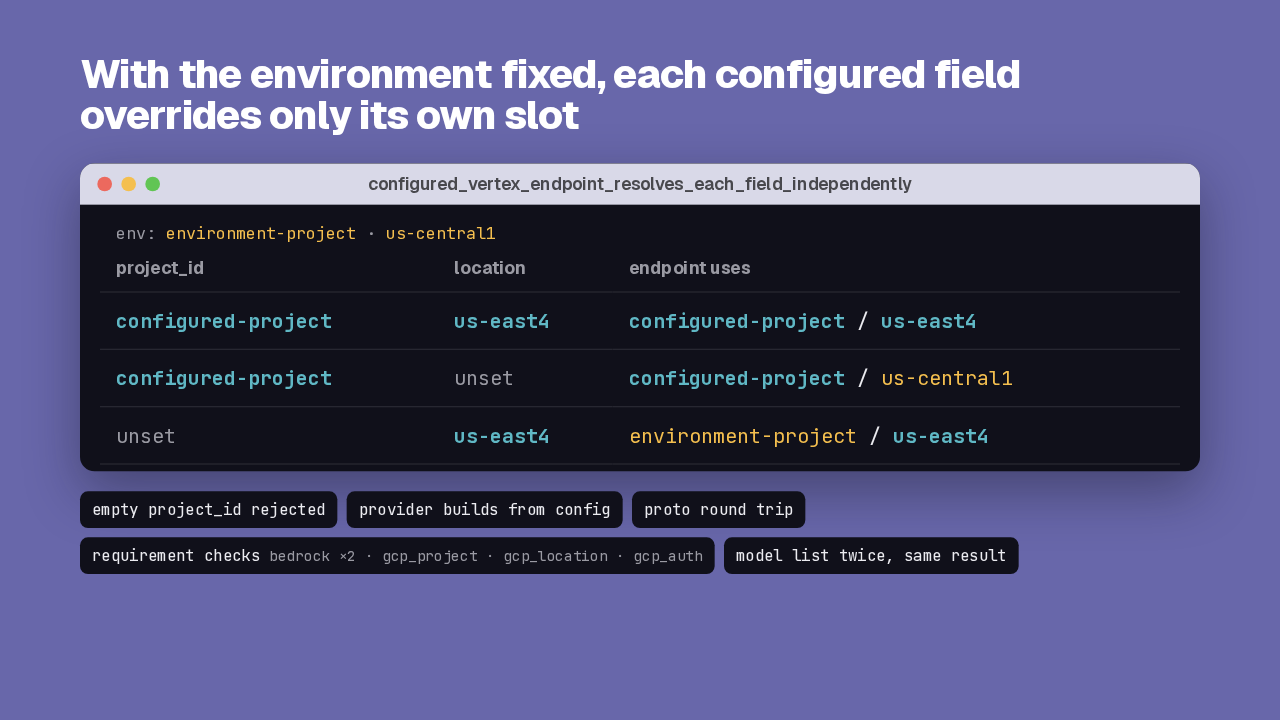
With the environment fixed, each configured field overrides only its own slot
| project_id | location | endpoint uses |
|---|---|---|
| configured-project | us-east4 | configured-project / us-east4 |
| configured-project | unset | configured-project / us-central1 |
| unset | us-east4 | environment-project / us-east4 |
This test holds the environment fixed and varies the config. Set both fields and both win. Set only the project, and the location still comes from the environment. Set only the location, and the project does. Other tests cover the empty project error, the proto round trip, requirement checks for Bedrock and GCP, and an app server that lists models twice under GCP requirements and gets the same answer.
What to do with it
>_ OpenAI Codex
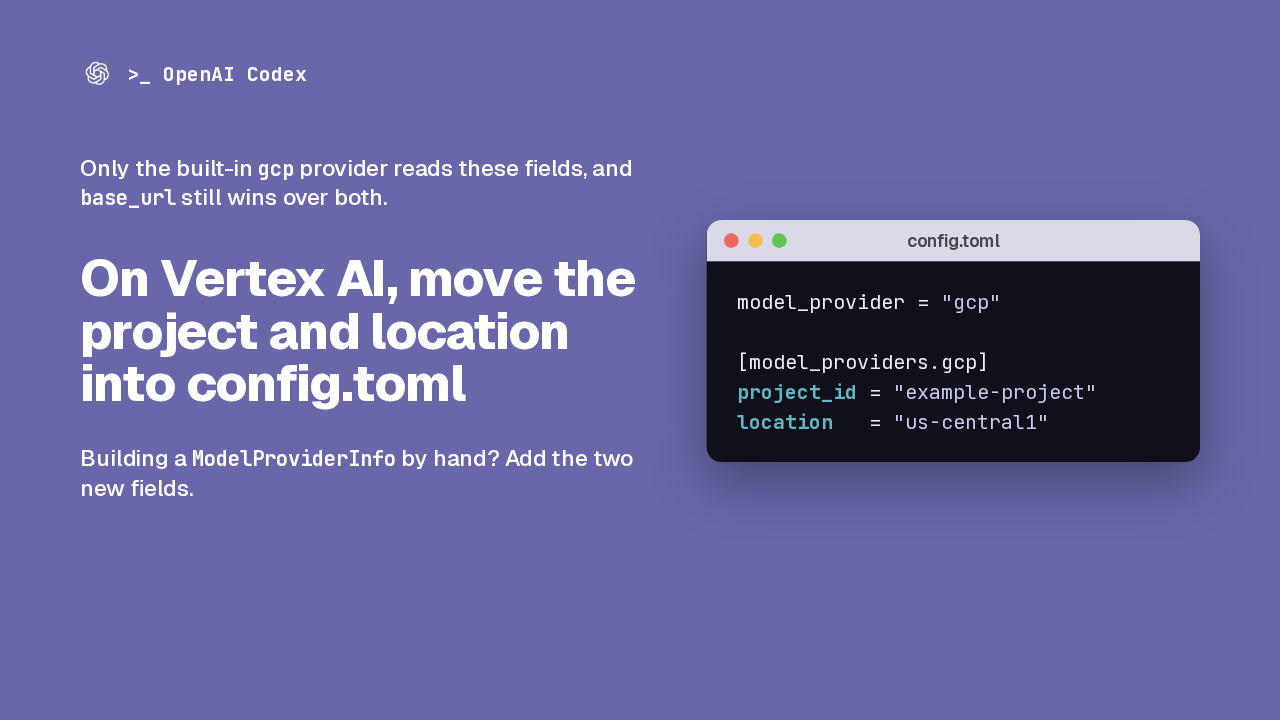
Only the built-in gcp provider reads these fields, and base_url still wins over both.
On Vertex AI, move the project and location into config.toml
Building a ModelProviderInfo by hand? Add the two new fields.
model_provider = "gcp"

[model_providers.gcp]
project_id = "example-project"
location   = "us-central1"
One limit: only the built-in GCP provider reads these fields, and an explicit base URL still overrides both. So if you run Codex on Vertex AI, the block from the start can replace the two environment variables, and they keep working as a fallback. And if you build model provider info by hand in a test, add the two new fields. Codex can now take the Vertex AI project and location from config.toml.