Nemotron 3.5 Bolt E4B

Ollama 0.40.10 runs NVIDIA's Nemotron 3.5 Bolt E4B
A smaller, Gemma 4-based vision-language model for fast local conversations, images and tool use.
Ollama 0.40.10 adds one model, NVIDIA's Nemotron 3.5 Bolt E4B. It's a smaller vision-language model built on Gemma 4, made for fast local conversations, understanding images and calling tools, and this one command runs it.
What you get
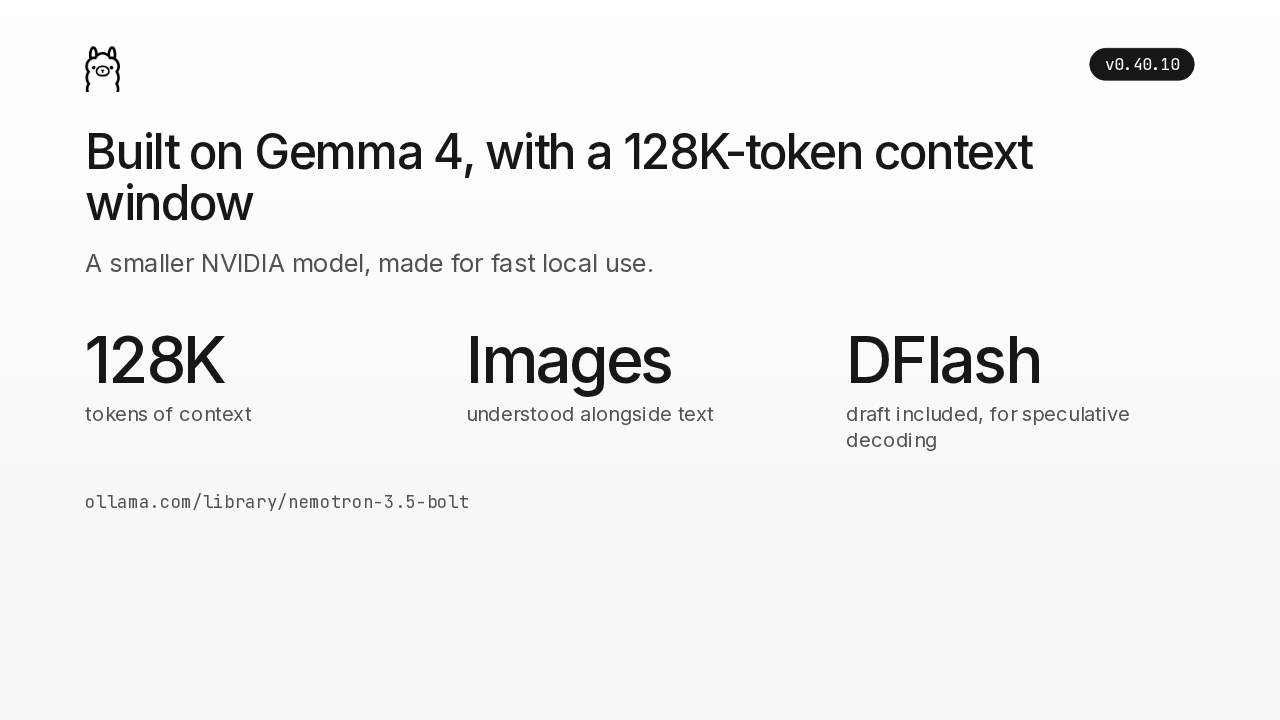
Built on Gemma 4, with a 128K-token context window
A smaller NVIDIA model, made for fast local use.
ollama.com/library/nemotron-3.5-bolt
Bolt E4B is a smaller model from NVIDIA, built on Gemma 4. It holds a context window of about 128,000 tokens, it understands images as well as text, and it ships with a DFlash draft, which is next.
A DFlash draft
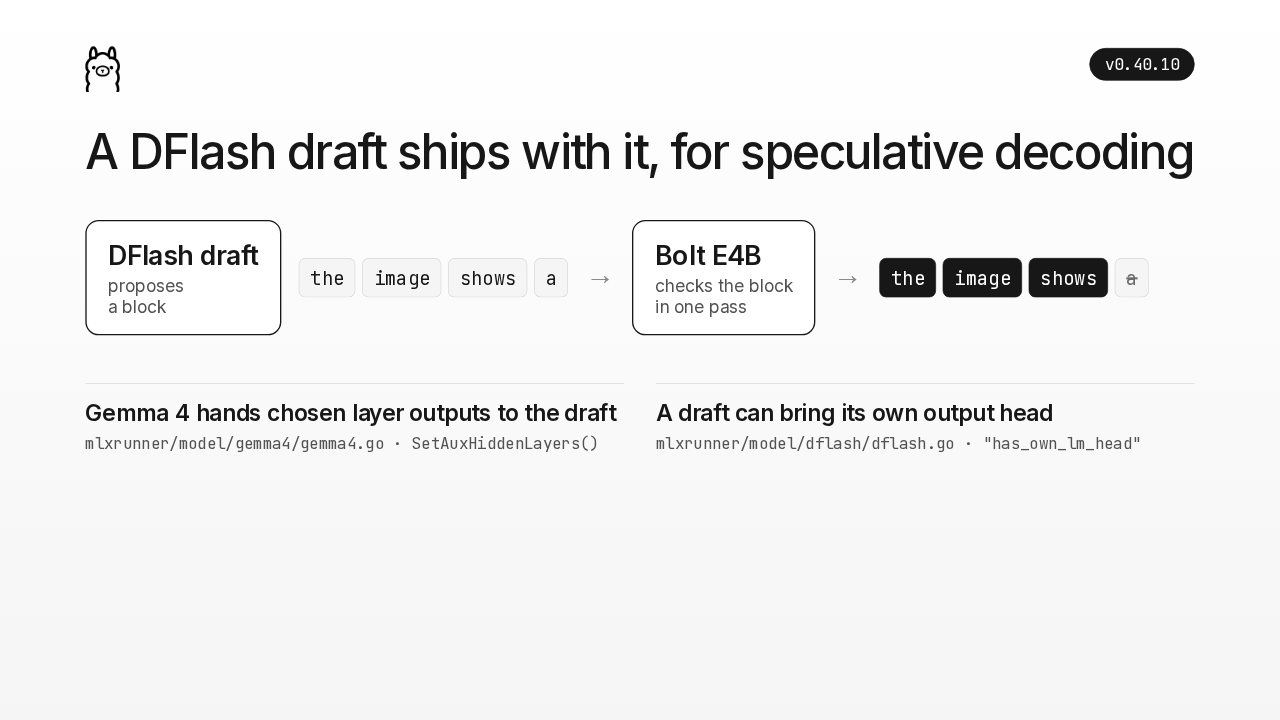
A DFlash draft ships with it, for speculative decoding
a block
in one pass
The model comes with a DFlash draft for speculative decoding. A small draft model proposes a block of tokens, and Bolt checks the whole block in one pass, keeping the tokens it agrees with. To support that, Ollama's MLX runner now lets a Gemma 4 model hand selected layer outputs to the draft, and lets a draft bring its own output head.
Tool-call prompts
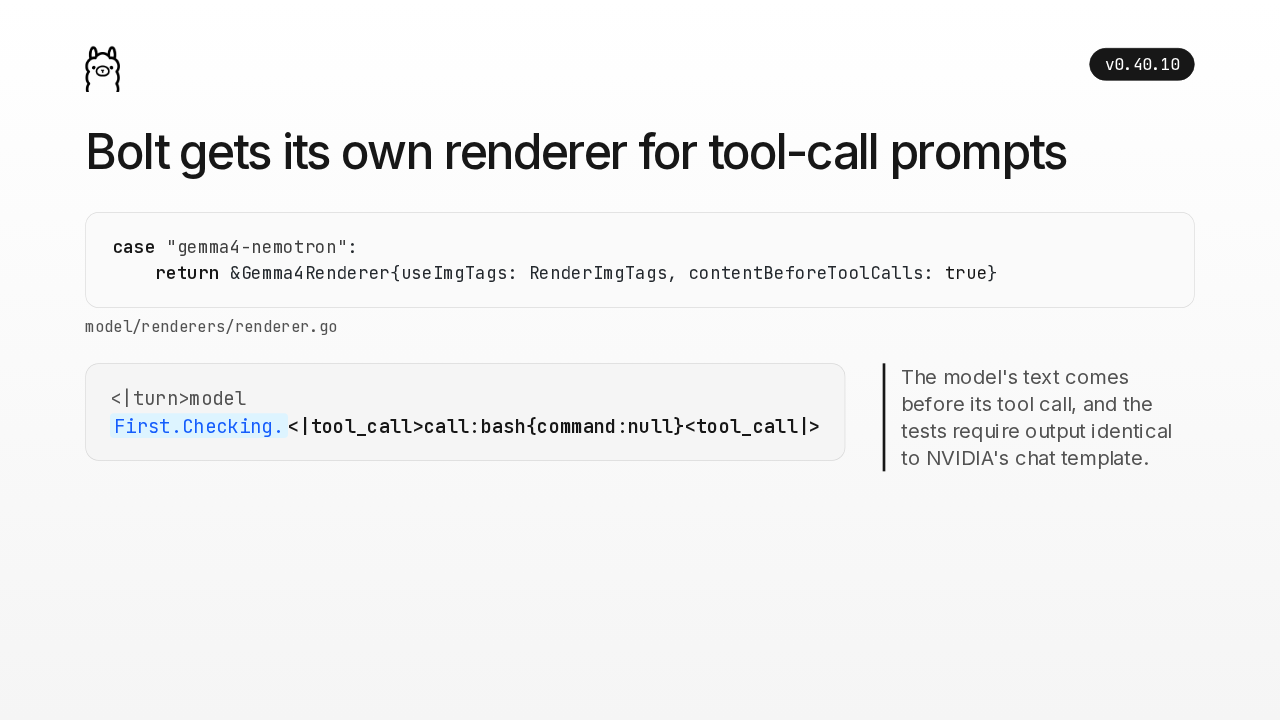
Bolt gets its own renderer for tool-call prompts
case "gemma4-nemotron":
	return &Gemma4Renderer{useImgTags: RenderImgTags, contentBeforeToolCalls: true}
model/renderers/renderer.go
The model's text comes before its tool call, and the tests require output identical to NVIDIA's chat template.
Bolt also gets its own prompt renderer, named Gemma 4 Nemotron. Compared with the other Gemma 4 renderers, it writes the model's text before its tool calls, instead of after the tool responses. The tests render each conversation through this renderer and through NVIDIA's own chat template, copied byte for byte into the repository, and require identical output. So multi-turn tool use gets the same prompt the publisher's template produces.
ollama show precision
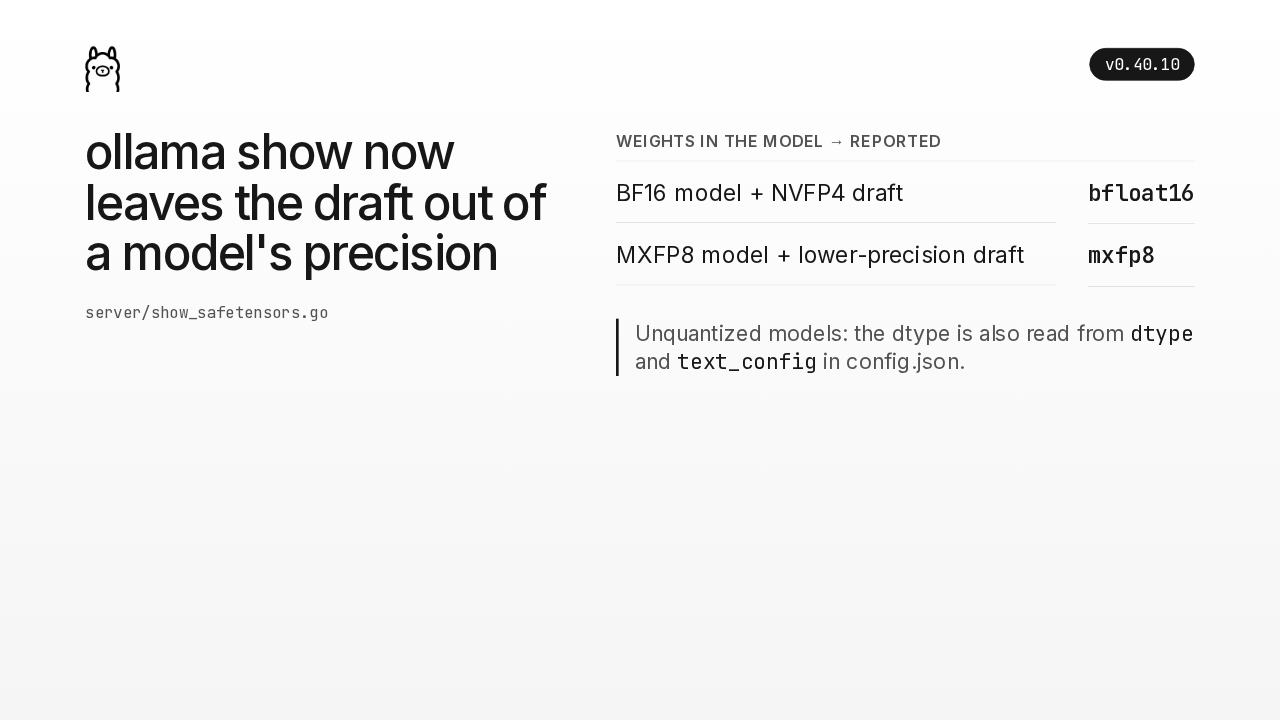
ollama show now leaves the draft out of a model's precision
server/show_safetensors.go
Weights in the model → reported
Unquantized models: the dtype is also read from dtype and text_config in config.json.
A smaller fix shows up in ollama show. A model like this one stores its draft's weights next to its own, and the draft can be quantized differently. Show now skips the draft's tensors when it reports quantization, so a bfloat16 model with an NVFP4 draft reports bfloat16. For a model that isn't quantized, show now also looks for the dtype under two more keys in its config file.
What could break
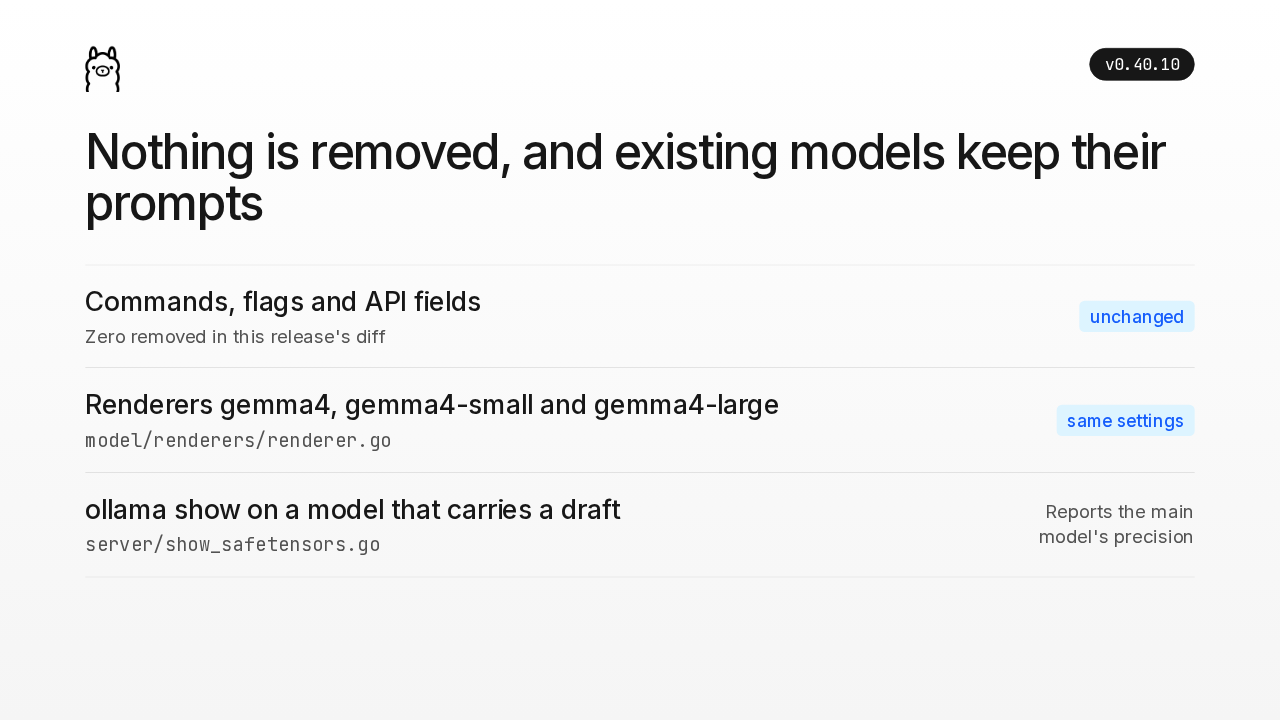
Nothing is removed, and existing models keep their prompts
model's precision
So what could break? This release removes zero commands, flags or API fields, and the existing Gemma 4 renderers keep the settings they had, so models already using them get the same prompts. The one output that can look different is ollama show, for a model that carries a draft, and that is the fix you just saw.
Upgrade
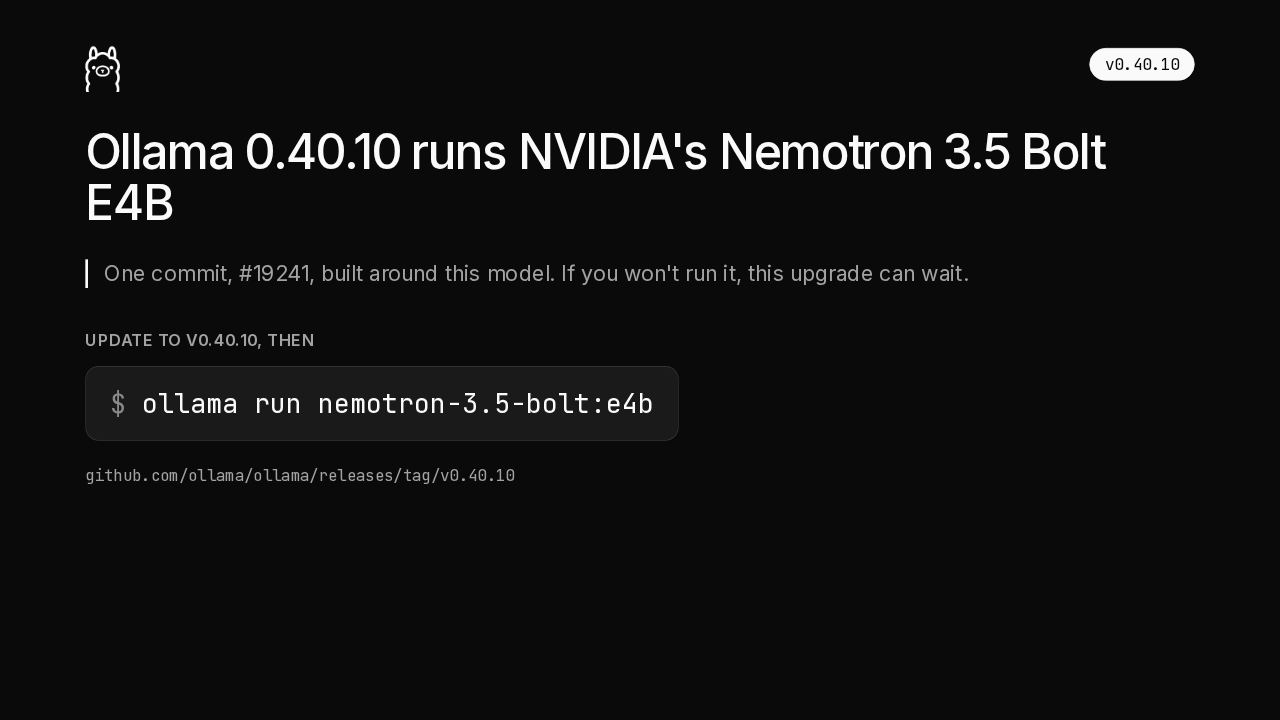
Ollama 0.40.10 runs NVIDIA's Nemotron 3.5 Bolt E4B
One commit, #19241, built around this model. If you won't run it, this upgrade can wait.
Update to v0.40.10, then
github.com/ollama/ollama/releases/tag/v0.40.10
The limit of this release is its size: one commit, built around this model. If you don't plan to run Bolt, this upgrade can wait. If you do, update Ollama to 0.40.10, then run the command with the E4B tag. Ollama 0.40.10 runs NVIDIA's Nemotron 3.5 Bolt E4B.